Advanced Search
Turn off MathJax
Article Contents
CHEN Chen, YAN Sheng, HAO Chengpeng, WU Min, HU Zhanhao, JIN Yuxi. A Two-Stage Ship-Radiated Noise Recognition Method Based on Contrastive Pre-Training and Progressive Self-Distillation with Limited Labeled Data[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260912
Citation: CHEN Chen, YAN Sheng, HAO Chengpeng, WU Min, HU Zhanhao, JIN Yuxi. A Two-Stage Ship-Radiated Noise Recognition Method Based on Contrastive Pre-Training and Progressive Self-Distillation with Limited Labeled Data[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260912

A Two-Stage Ship-Radiated Noise Recognition Method Based on Contrastive Pre-Training and Progressive Self-Distillation with Limited Labeled Data

doi: 10.11999/JEIT260912 cstr: 32379.14.JEIT260912
Funds:  National Natural Science Foundation of China (62371446)
  • Received Date: 2026-07-02
  • Accepted Date: 2026-10-16
  • Rev Recd Date: 2026-10-13
  • Available Online: 2026-10-26
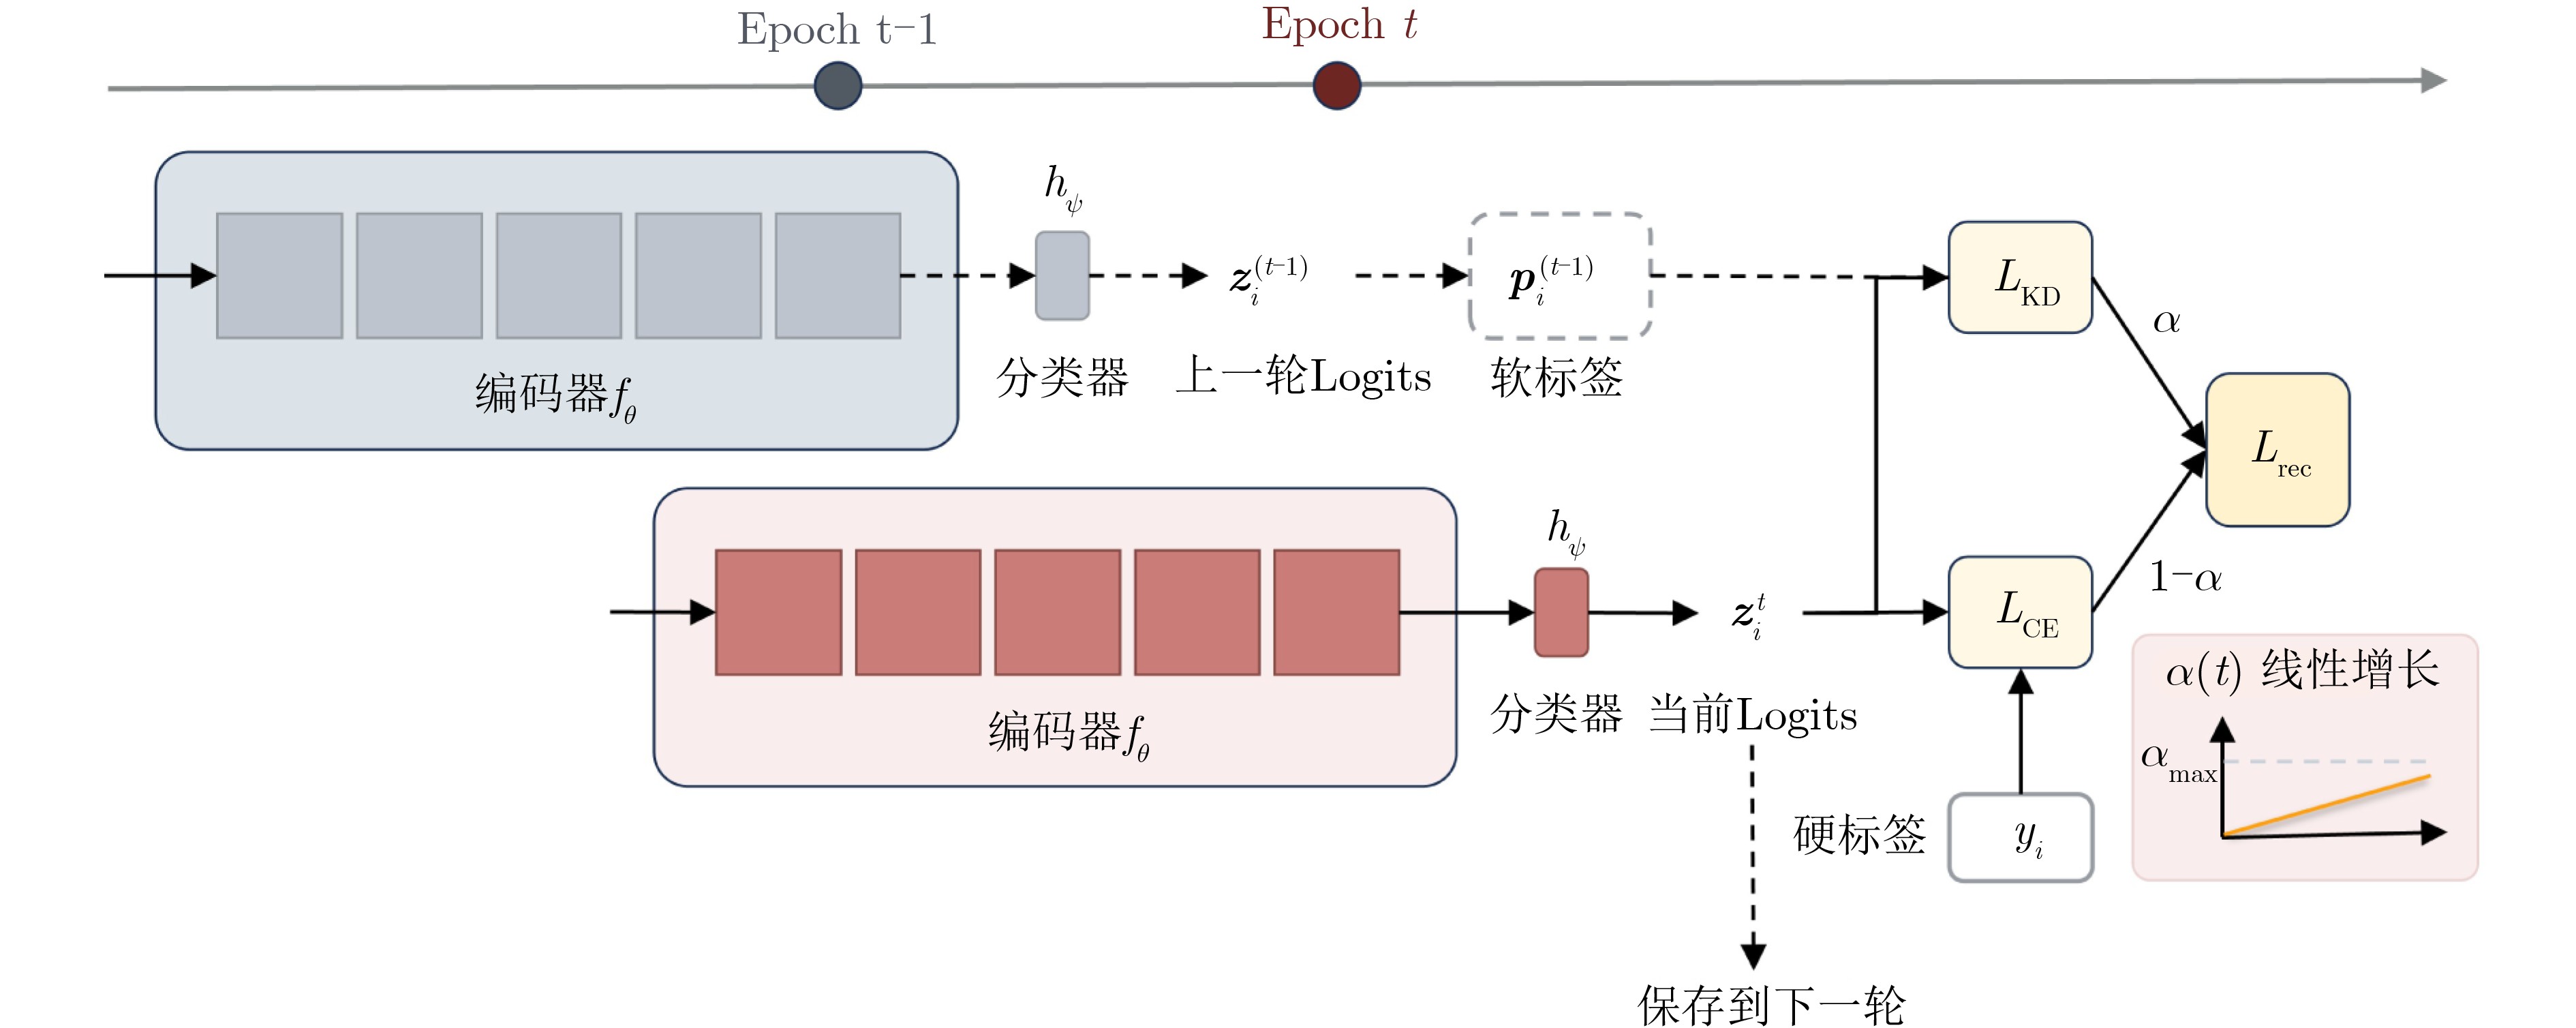
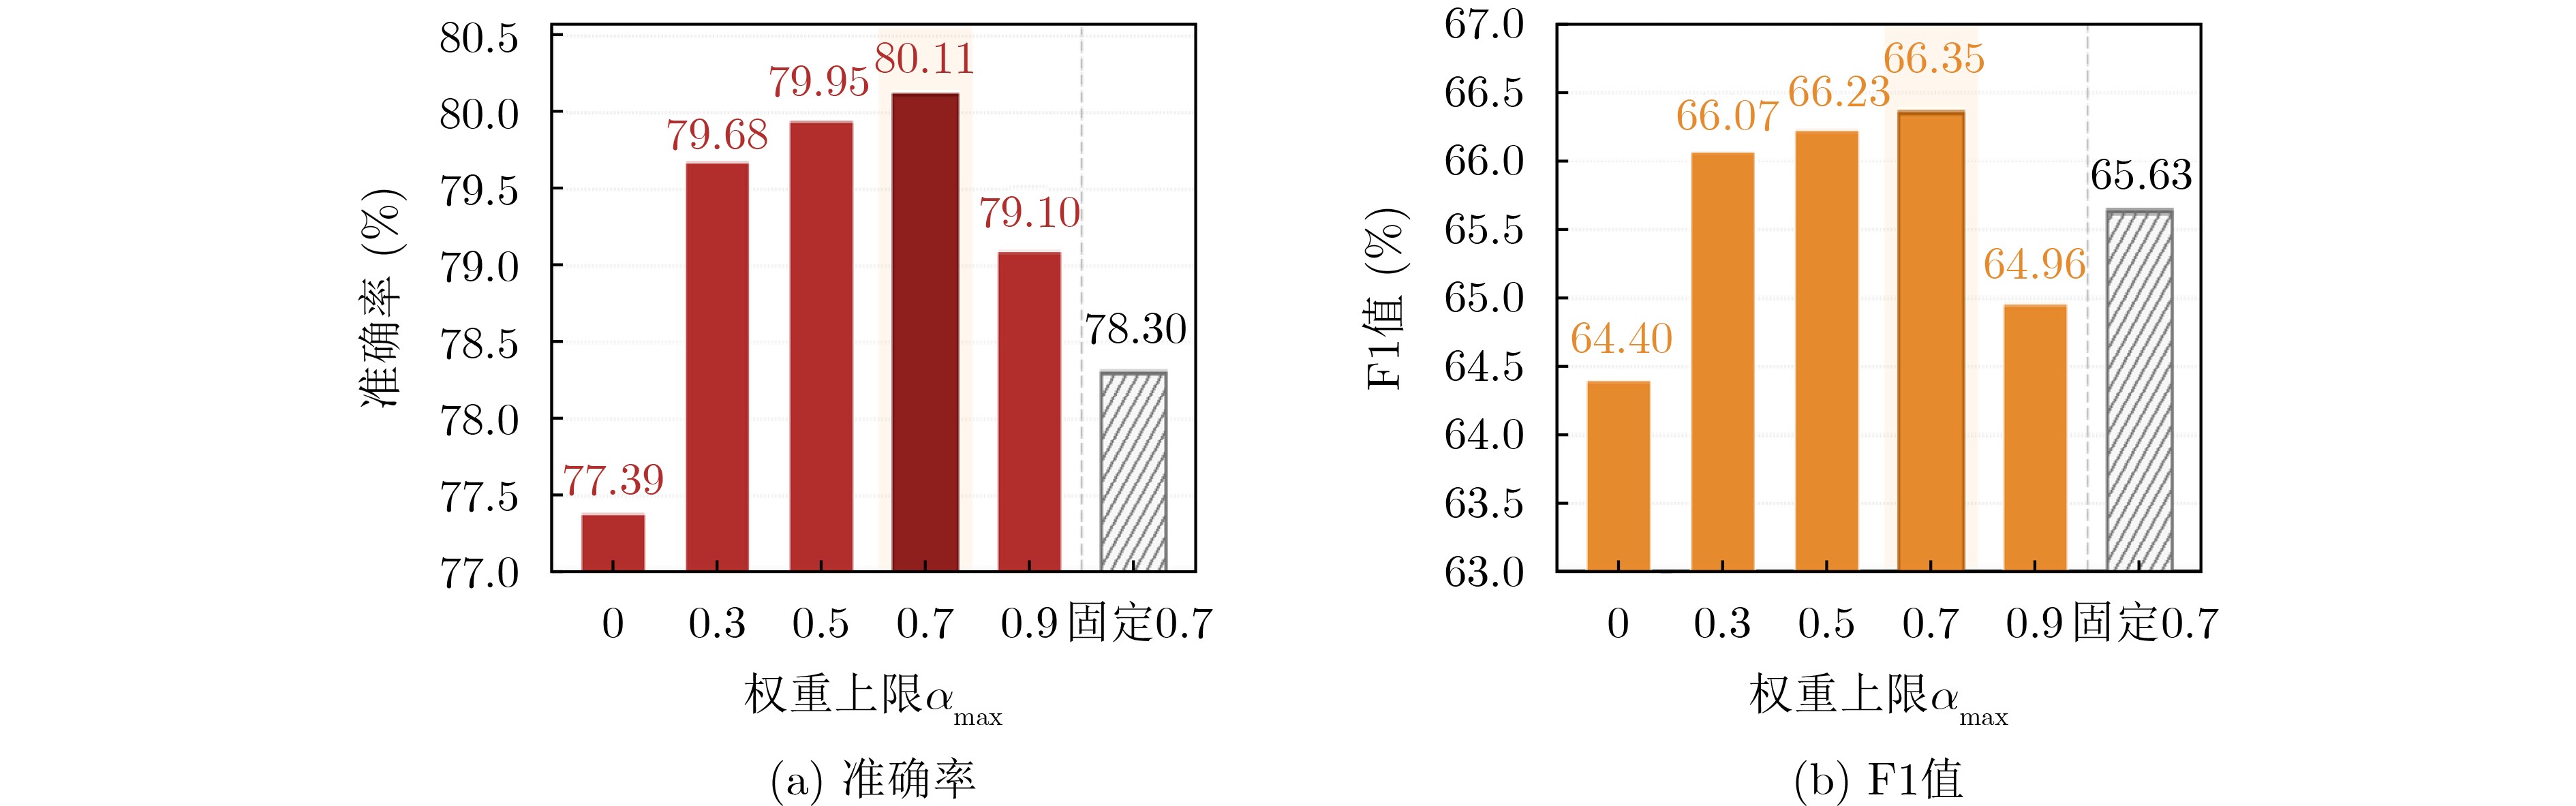
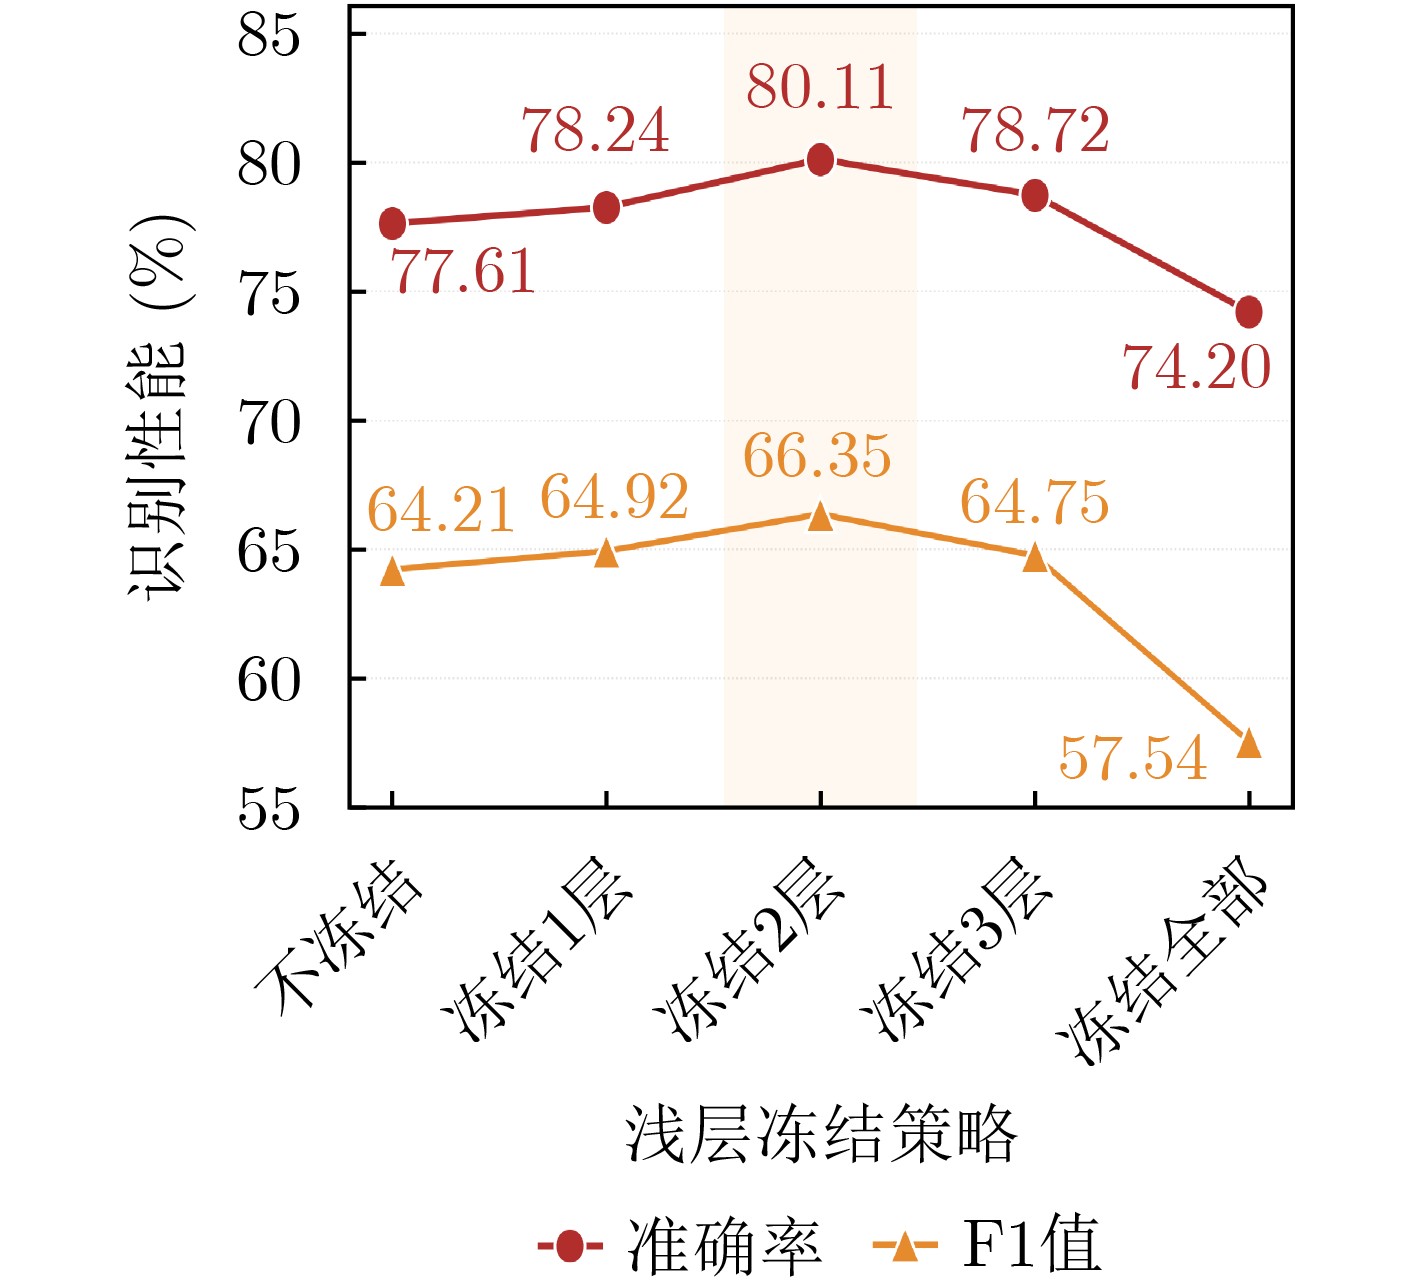
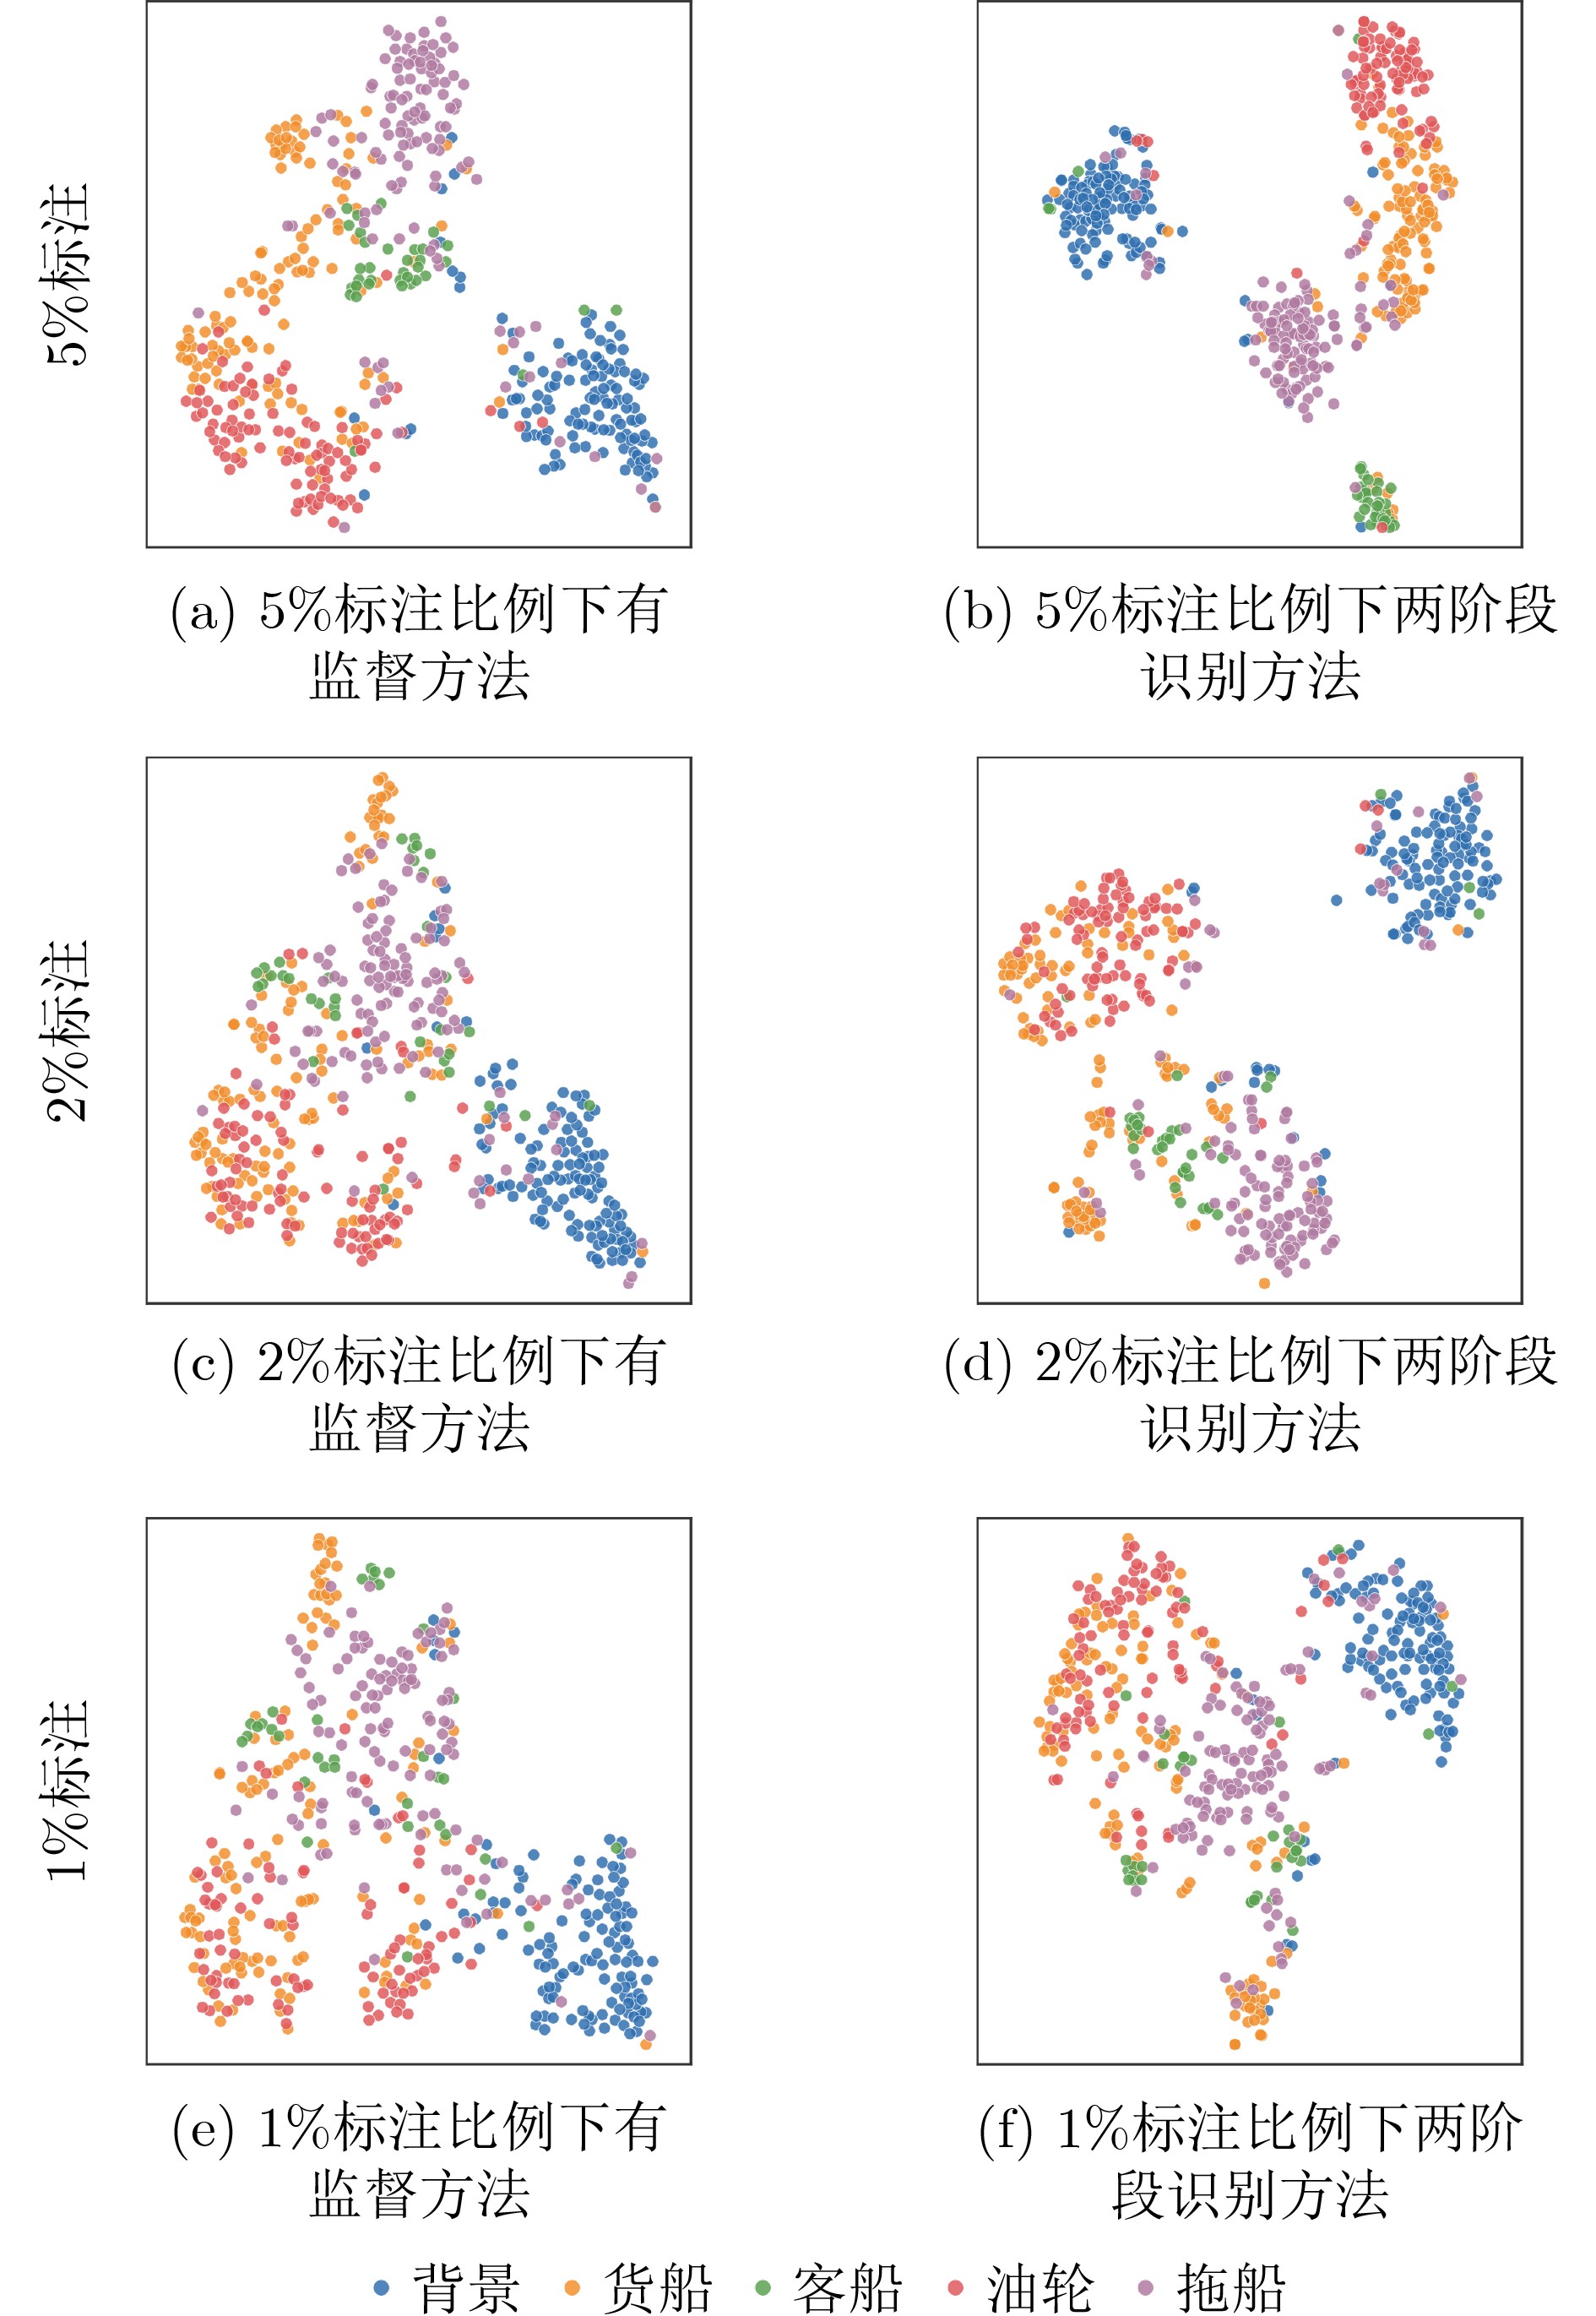
  •   Objective  With the rapid development of marine transportation, ship-radiated noise recognition has become essential for maritime safety. However, existing deep learning methods rely on large-scale labeled training data. In underwater acoustic scenarios, ship-radiated noise data are difficult to collect because hydrophone deployment and sea trials are difficult to control. Under this condition, conventional supervised recognition methods tend to suffer from performance degradation. Although contrastive learning can exploit unlabeled data, generic augmentation strategies may destroy critical spectral structures. In addition, conventional fine-tuning fails to fully use the similarity structure among ships. To address these challenges, a two-stage recognition method based on contrastive pre-training and progressive self-distillation is proposed. This research aims to improve the utilization of unlabeled data and limited labeled data and enhance the accuracy of ship-radiated noise recognition.  Methods  The ship-radiated noise signals are processed by the Constant-Q Transform (CQT) to obtain CQT spectra, which are then used as the input. The proposed method is carried out through contrastive pre-training and progressive self-distillation. In the contrastive pre-training stage, each unlabeled sample is transformed into two augmented views by a combined data augmentation strategy. This strategy includes time-axis flipping, random signal truncation and additive noise injection. These augmentations reflect variations in observation order, observation windows, and background interference. Time-axis flipping preserves the frequency positions of spectral lines, while signal truncation retains part of the waveform and restores its length through zero padding. These operations introduce view diversity while seeking to preserve structures relevant to ship recognition. The augmented views generated from the same sample are treated as a positive pair, and the views generated from other samples in the same mini-batch are treated as negative samples. An encoder and a projection head are used to map the CQT spectra into an embedding space. The contrastive loss is used to increase the similarity of positive pairs and decrease the similarity between negative ones. After contrastive pre-training, the projection head is discarded, and the encoder parameters are retained for the following recognition stage. In the progressive self-distillation stage, the pre-trained encoder is connected with a classifier to form the recognition model. The shallow layers of the encoder are frozen to preserve general acoustic features, while the deeper layers and the classifier are updated using limited labeled samples. The training objective includes the cross-entropy loss and the soft-label distillation loss. The soft labels are generated from the historical predictions of the model itself, and the weight of the distillation loss increases linearly with the training epoch. This progressive weighting strategy reduces the influence of unreliable soft labels in the early training stage and gradually introduces similarity information contained in historical predictions.  Results and Discussions  The proposed two-stage method is evaluated on the VTUAD dataset under five labeled-data scales, including 100%, 10%, 5%, 2%, and 1% labeled samples (Table 1). The supervised baseline achieves an accuracy of 94.28% and an F1-score of 91.90% when all labeled samples are used. However, its performance decreases as the labeling scale is reduced, and the accuracy and F1-score drop to 72.60% and 58.08%, respectively, when only 1% labeled training samples are used (Table 3). After contrastive pre-training, standard fine-tuning improves the recognition performance over the supervised baseline. By introducing progressive self-distillation, the proposed method further improves the recognition performance (Table 3). Compared with CRNN, VGG, CNN-Transformer, and ECAPA-TDNN, the proposed method achieves the best recognition performance in all five settings. In the 1% labeled-data case, it improves the accuracy by 11.33% and the F1-score by 15.08% compared with the second-best method (Table 4). The comparison of different self-distillation strategies shows that progressive self-distillation performs better, indicating that the progressive weighting strategy can reduce the influence of noisy soft labels at the early training stage and make better use of category similarity information (Table 6). The shallow-layer freezing experiment shows that freezing the first two layers of the encoder achieves the best balance between preserving pre-trained features and adapting to the recognition task (Fig. 8). Noise robustness is further evaluated by adding Gaussian white noise to the test recordings under the 1% labeled training data setting. At a signal-to-noise ratio of −5 dB, the proposed method achieves 62.18% accuracy and a 43.82% F1-score, compared with 45.00% and 37.68%, respectively, for the supervised baseline (Table 7). The confusion matrices and feature visualizations show that the proposed method improves the recognition performance and produces more compact intra-class distributions and clearer inter-class separation (Fig. 9, Fig. 10). A cross-dataset transfer experiment is further conducted on the ShipsEar dataset. In this experiment, the encoder pre-trained on VTUAD is adapted using labeled ShipsEar training samples. The 1% training subset contains only 40 samples. Across the five labeled-data scales, the proposed method improves accuracy and F1-score over the supervised baseline by averages of 5.27% and 5.51%, respectively. Although VTUAD and ShipsEar differ in data distribution, and ShipsEar contains fewer labeled training samples, the proposed method outperforms the supervised baseline across different labeled-data scales, demonstrating cross-dataset transferability (Table 8).  Conclusions  This paper addresses the performance degradation of ship-radiated noise recognition with limited labeled data by proposing a two-stage method based on contrastive pre-training and progressive self-distillation. The proposed method improves the utilization of unlabeled and limited labeled data in three aspects: (1) A two-stage recognition framework is constructed, in which contrastive pre-training is used to learn general acoustic representations from unlabeled ship-radiated noise samples, and self-distillation is used to optimize the recognition model with limited labeled samples; (2) A combined data augmentation strategy is designed for contrastive pre-training to introduce different views; (3) A progressive self-distillation mechanism is introduced in the recognition stage, where the historical predictions are used as soft labels and are gradually incorporated into training to supplement hard-label supervision. The method is evaluated on the VTUAD dataset, and the experimental results show that it achieves average improvements of 6.17% in accuracy and 8.11% in F1-score over the supervised baseline across five labeled-data scales. The transfer experiment on ShipsEar further demonstrates that the proposed method remains superior to the supervised baseline when the source and target datasets differ in data distribution and the target dataset contains fewer labeled training samples.
  • loading
  • [1]
    MCKENNA M F, ROSS D, WIGGINS S M, et al. Underwater radiated noise from modern commercial ships[J]. The Journal of the Acoustical Society of America, 2012, 131(1): 92–103. doi: 10.1121/1.3664100.
    [2]
    徐源超, 蔡志明, 孔晓鹏, 等. 船舶辐射噪声分类卷积神经网络的可视化分析和卷积核剪枝[J]. 电子与信息学报, 2024, 46(1): 74–82. doi: 10.11999/JEIT230149.

    XU Yuanchao, CAI Zhiming, KONG Xiaopeng, et al. Visualization analysis and kernel pruning of convolutional neural network for ship-radiated noise classification[J]. Journal of Electronics & Information Technology, 2024, 46(1): 74–82. doi: 10.11999/JEIT230149.
    [3]
    李理, 李向欣, 殷敬伟. 基于生成对抗网络的舰船辐射噪声分类方法研究[J]. 电子与信息学报, 2022, 44(6): 1974–1983. doi: 10.11999/JEIT211077.

    LI Li, LI Xiangxin, and YIN Jingwei. Research on classification algorithm of ship radiated noise data based on generative adversarial network[J]. Journal of Electronics & Information Technology, 2022, 44(6): 1974–1983. doi: 10.11999/JEIT211077.
    [4]
    任佳威, 谢源, 徐及, 等. 用于水声目标识别的注意力机制特征增强[J]. 声学学报, 2024, 49(4): 664–670. doi: 10.12395/0371-0025.2022178.

    REN Jiawei, XIE Yuan, XU Ji, et al. A feature attention enhancement network for underwater acoustic classification[J]. Acta Acustica, 2024, 49(4): 664–670. doi: 10.12395/0371-0025.2022178.
    [5]
    FENG Sheng, MA Shuqing, ZHU Xiaoqian, et al. Artificial intelligence-based underwater acoustic target recognition: A survey[J]. Remote Sensing, 2024, 16(17): 3333. doi: 10.3390/rs16173333.
    [6]
    郑擎宇, 邱龙皓, 梁国龙, 等. 面向水下噪声源目标识别的轻量化网络构建与优化方法[J]. 声学学报, 2026, 51(1): 158–169. doi: 10.12395/0371-0025.2024246.

    ZHENG Qingyu, QIU Longhao, LIANG Guolong, et al. A lightweight network construction and optimization method for underwater radiated noise target recognition[J]. Acta Acustica, 2026, 51(1): 158–169. doi: 10.12395/0371-0025.2024246.
    [7]
    HUANG Wei, ZHANG Qirui, ZHAO Bowen, et al. A few-shot learning method for underwater acoustic target recognition based on generative data augmentation[J]. The Journal of the Acoustical Society of America, 2026, 159(5): 3773–3791. doi: 10.1121/10.0043727.
    [8]
    CHEN Ting, KORNBLITH S, NOROUZI M, et al. A simple framework for contrastive learning of visual representations[C]. Proceedings of the 37th International Conference on Machine Learning, 2020: 149. doi: 10.5555/3524938.3525087. (查阅网上资料,未找到本条文献举办地信息,请确认).
    [9]
    朱龙俊, 袁伟伟, 门雪峰, 等. 空中对抗场景下对比学习驱动的弱监督机动识别方法[J]. 电子与信息学报, 2025, 47(11): 4504–4514. doi: 10.11999/JEIT250495.

    ZHU Longjun, YUAN Weiwei, MEN Xuefeng, et al. Weakly supervised recognition of aerial adversarial maneuvers via contrastive learning[J]. Journal of Electronics & Information Technology, 2025, 47(11): 4504–4514. doi: 10.11999/JEIT250495.
    [10]
    CHOI J, JANG S, CHO H, et al. Towards proper contrastive self-supervised learning strategies for music audio representation[C]. Proceedings of the 2022 IEEE International Conference on Multimedia and Expo, Taipei, China, 2022: 1–6. doi: 10.1109/ICME52920.2022.9859799.
    [11]
    LI Zhe, DAI Weiguo, LIU Qijun, et al. An improved Cohen-class based extraction method for fine spectral feature of line spectrum from ship-radiated noise[J]. IET Radar, Sonar & Navigation, 2025, 19(1): e70083. doi: 10.1049/rsn2.70083.
    [12]
    WANG Xingmei, LIU Zijian, and GUO Zheng. Multi-scale self-distillation underwater acoustic signal recognition via saliency masking modeling[J]. The Journal of the Acoustical Society of America, 2025, 158(6): 4594–4606. doi: 10.1121/10.0041851.
    [13]
    陈雷, 杨吉斌, 曹铁勇, 等. 一种基于Transformer特征金字塔的自蒸馏目标分割方法[J]. 电子与信息学报, 2025, 47(2): 551–560. doi: 10.11999/JEIT240735.

    CHEN Lei, YANG Jibin, CAO Tieyong, et al. A self-distillation object segmentation method based on Transformer feature pyramid[J]. Journal of Electronics & Information Technology, 2025, 47(2): 551–560. doi: 10.11999/JEIT240735.
    [14]
    HE Kaiming, ZHANG Xiangyu, REN Shaoqing, et al. Deep residual learning for image recognition[C]. Proceedings of the 2016 IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, USA, 2016: 770–778. doi: 10.1109/CVPR.2016.90.
    [15]
    WENZ G M. Acoustic ambient noise in the ocean: Spectra and sources[J]. The Journal of the Acoustical Society of America, 1962, 34(12): 1936–1956. doi: 10.1121/1.1909155.
    [16]
    HINTON G, VINYALS O, and DEAN J. Distilling the knowledge in a neural network[EB/OL]. https://arxiv.org/abs/1503.02531, 2015.
    [17]
    DOMINGOS L C F, SANTOS P E, SKELTON P S M, et al. An investigation of preprocessing filters and deep learning methods for vessel type classification with underwater acoustic data[J]. IEEE Access, 2022, 10: 117582–117596. doi: 10.1109/access.2022.3220265.
    [18]
    SANTOS-DOMÍNGUEZ D, TORRES-GUIJARRO S, CARDENAL-LÓPEZ A, et al. ShipsEar: An underwater vessel noise database[J]. Applied Acoustics, 2016, 113: 64–69. doi: 10.1016/j.apacoust.2016.06.008.
    [19]
    CHOI K, FAZEKAS G, SANDLER M, et al. Convolutional recurrent neural networks for music classification[C]. Proceedings of the 2017 IEEE International Conference on Acoustics, Speech and Signal Processing, New Orleans, USA, 2017: 2392–2396. doi: 10.1109/ICASSP.2017.7952585.
    [20]
    SIMONYAN K and ZISSERMAN A. Very deep convolutional networks for large-scale image recognition[C]. Proceedings of the 3rd International Conference on Learning Representations, San Diego, USA, 2015.
    [21]
    KONG Qiuqiang, XU Yong, WANG Wenwu, et al. Sound event detection of weakly labelled data with CNN-Transformer and automatic threshold optimization[J]. IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2020, 28: 2450–2460. doi: 10.1109/taslp.2020.3014737.
    [22]
    DESPLANQUES B, THIENPONDT J, and DEMUYNCK K. ECAPA-TDNN: Emphasized channel attention, propagation and aggregation in TDNN based speaker verification[C]. Proceedings of the Interspeech 2020, Shanghai, China, 2020: 3830–3834. doi: 10.21437/Interspeech.2020-2650. (查阅网上资料,本条文献举办地为线上,请确认).
    [23]
    YUN S, PARK J, LEE K, et al. Regularizing class-wise predictions via self-knowledge distillation[C]. Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, USA, 2020: 13873–13882. doi: 10.1109/CVPR42600.2020.01389.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(10)  / Tables(8)

    Article Metrics

    Article views (73) PDF downloads(4) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return