Advanced Search
Turn off MathJax
Article Contents
FAN Lingyan, XU Xinchen, HUANG Cankun, SHEN Zhengnuo, DENG Jiangxia, LIU Hailuan. An ECO Repair Method for Max Transition Violations in Multi-Load Nets[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260600
Citation: FAN Lingyan, XU Xinchen, HUANG Cankun, SHEN Zhengnuo, DENG Jiangxia, LIU Hailuan. An ECO Repair Method for Max Transition Violations in Multi-Load Nets[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260600

An ECO Repair Method for Max Transition Violations in Multi-Load Nets

doi: 10.11999/JEIT260600 cstr: 32379.14.JEIT260600
Funds:  The National Natural Science Foundation of China(U22A2071)
  • Received Date: 2026-05-14
  • Accepted Date: 2026-08-13
  • Rev Recd Date: 2026-08-13
  • Available Online: 2026-08-25
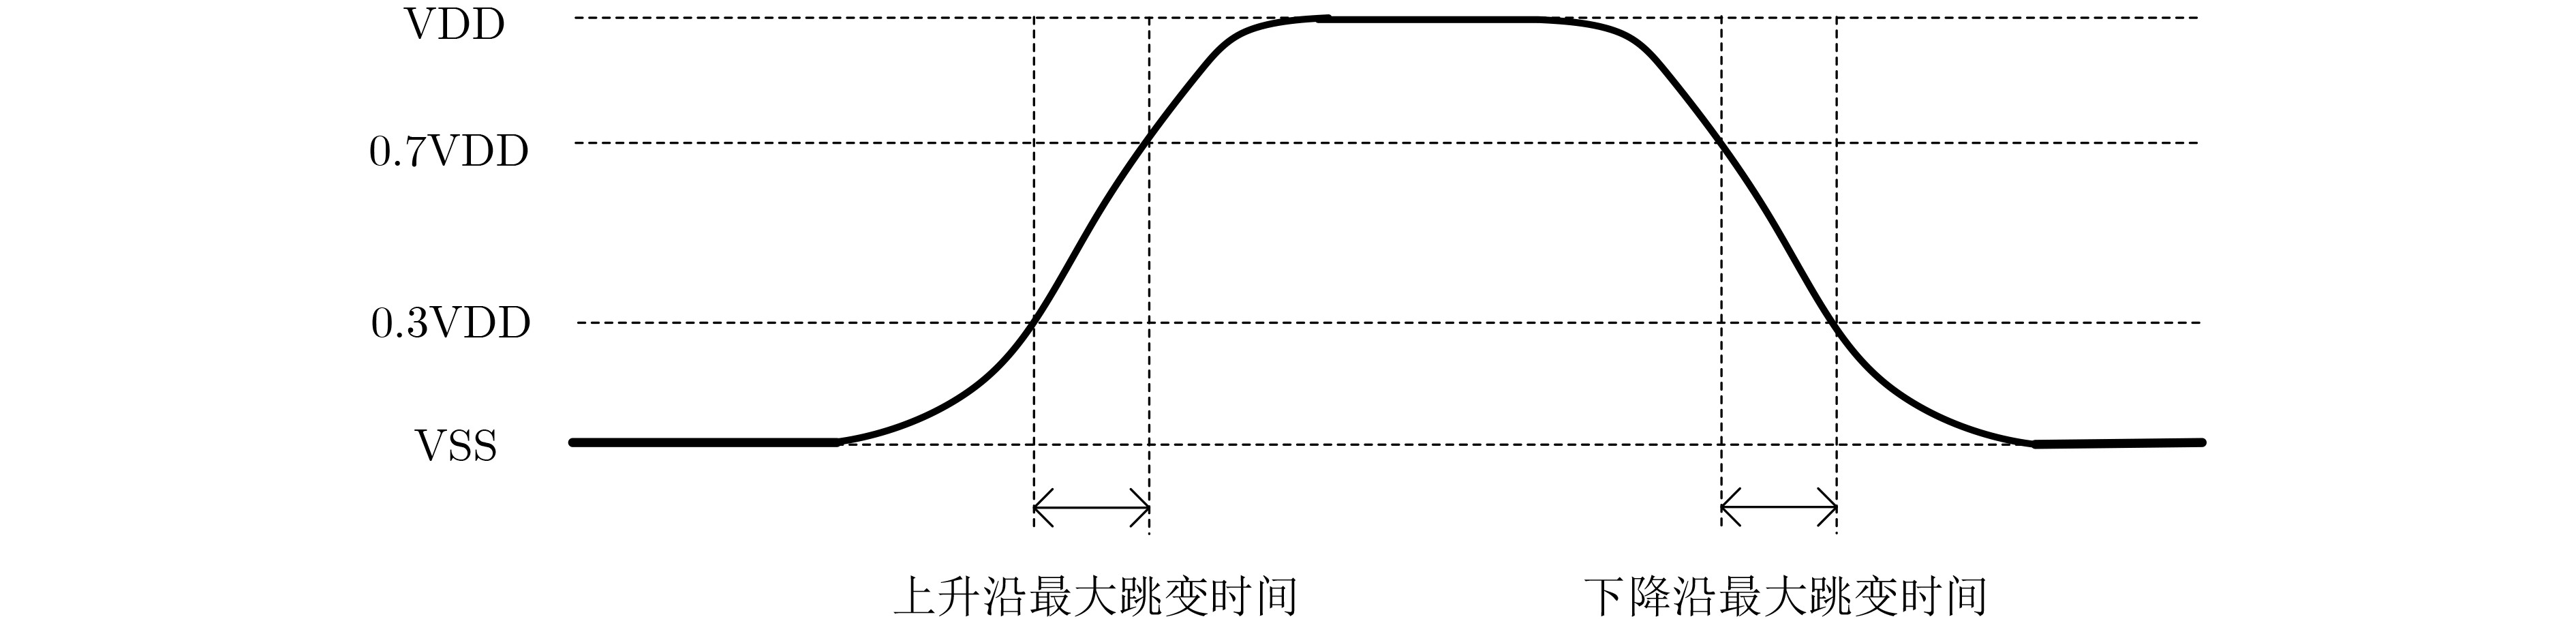
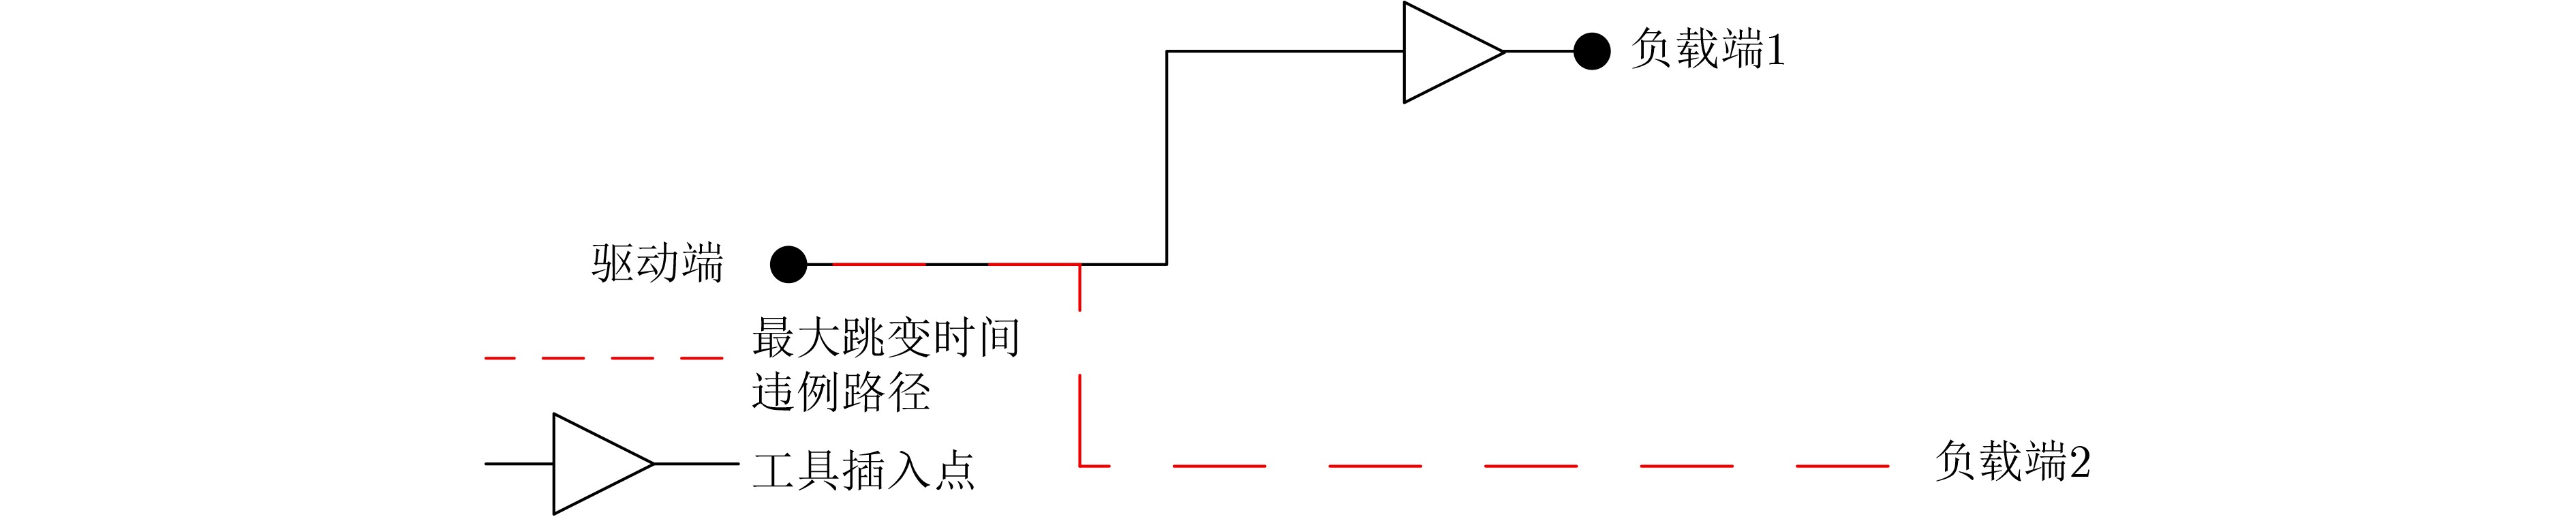
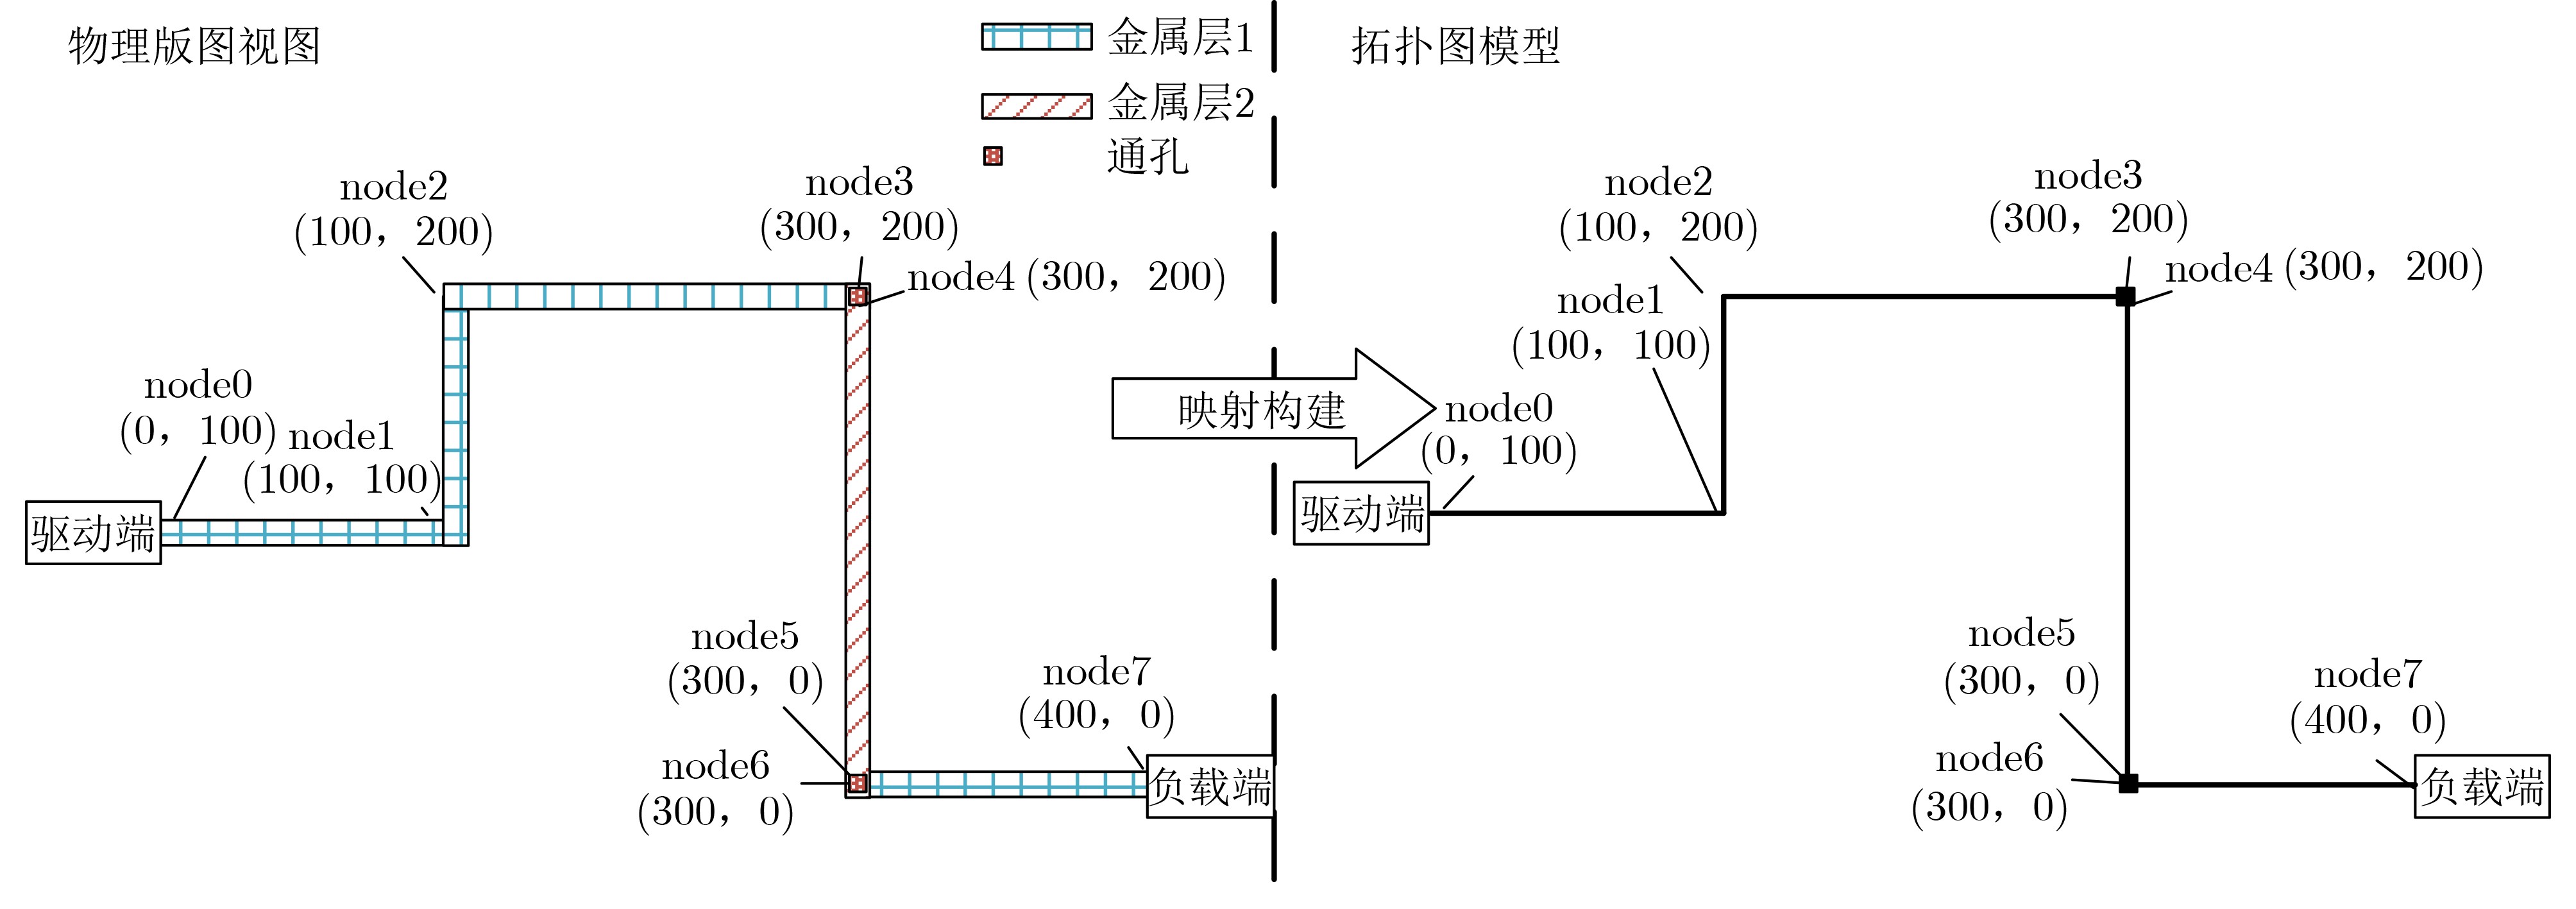
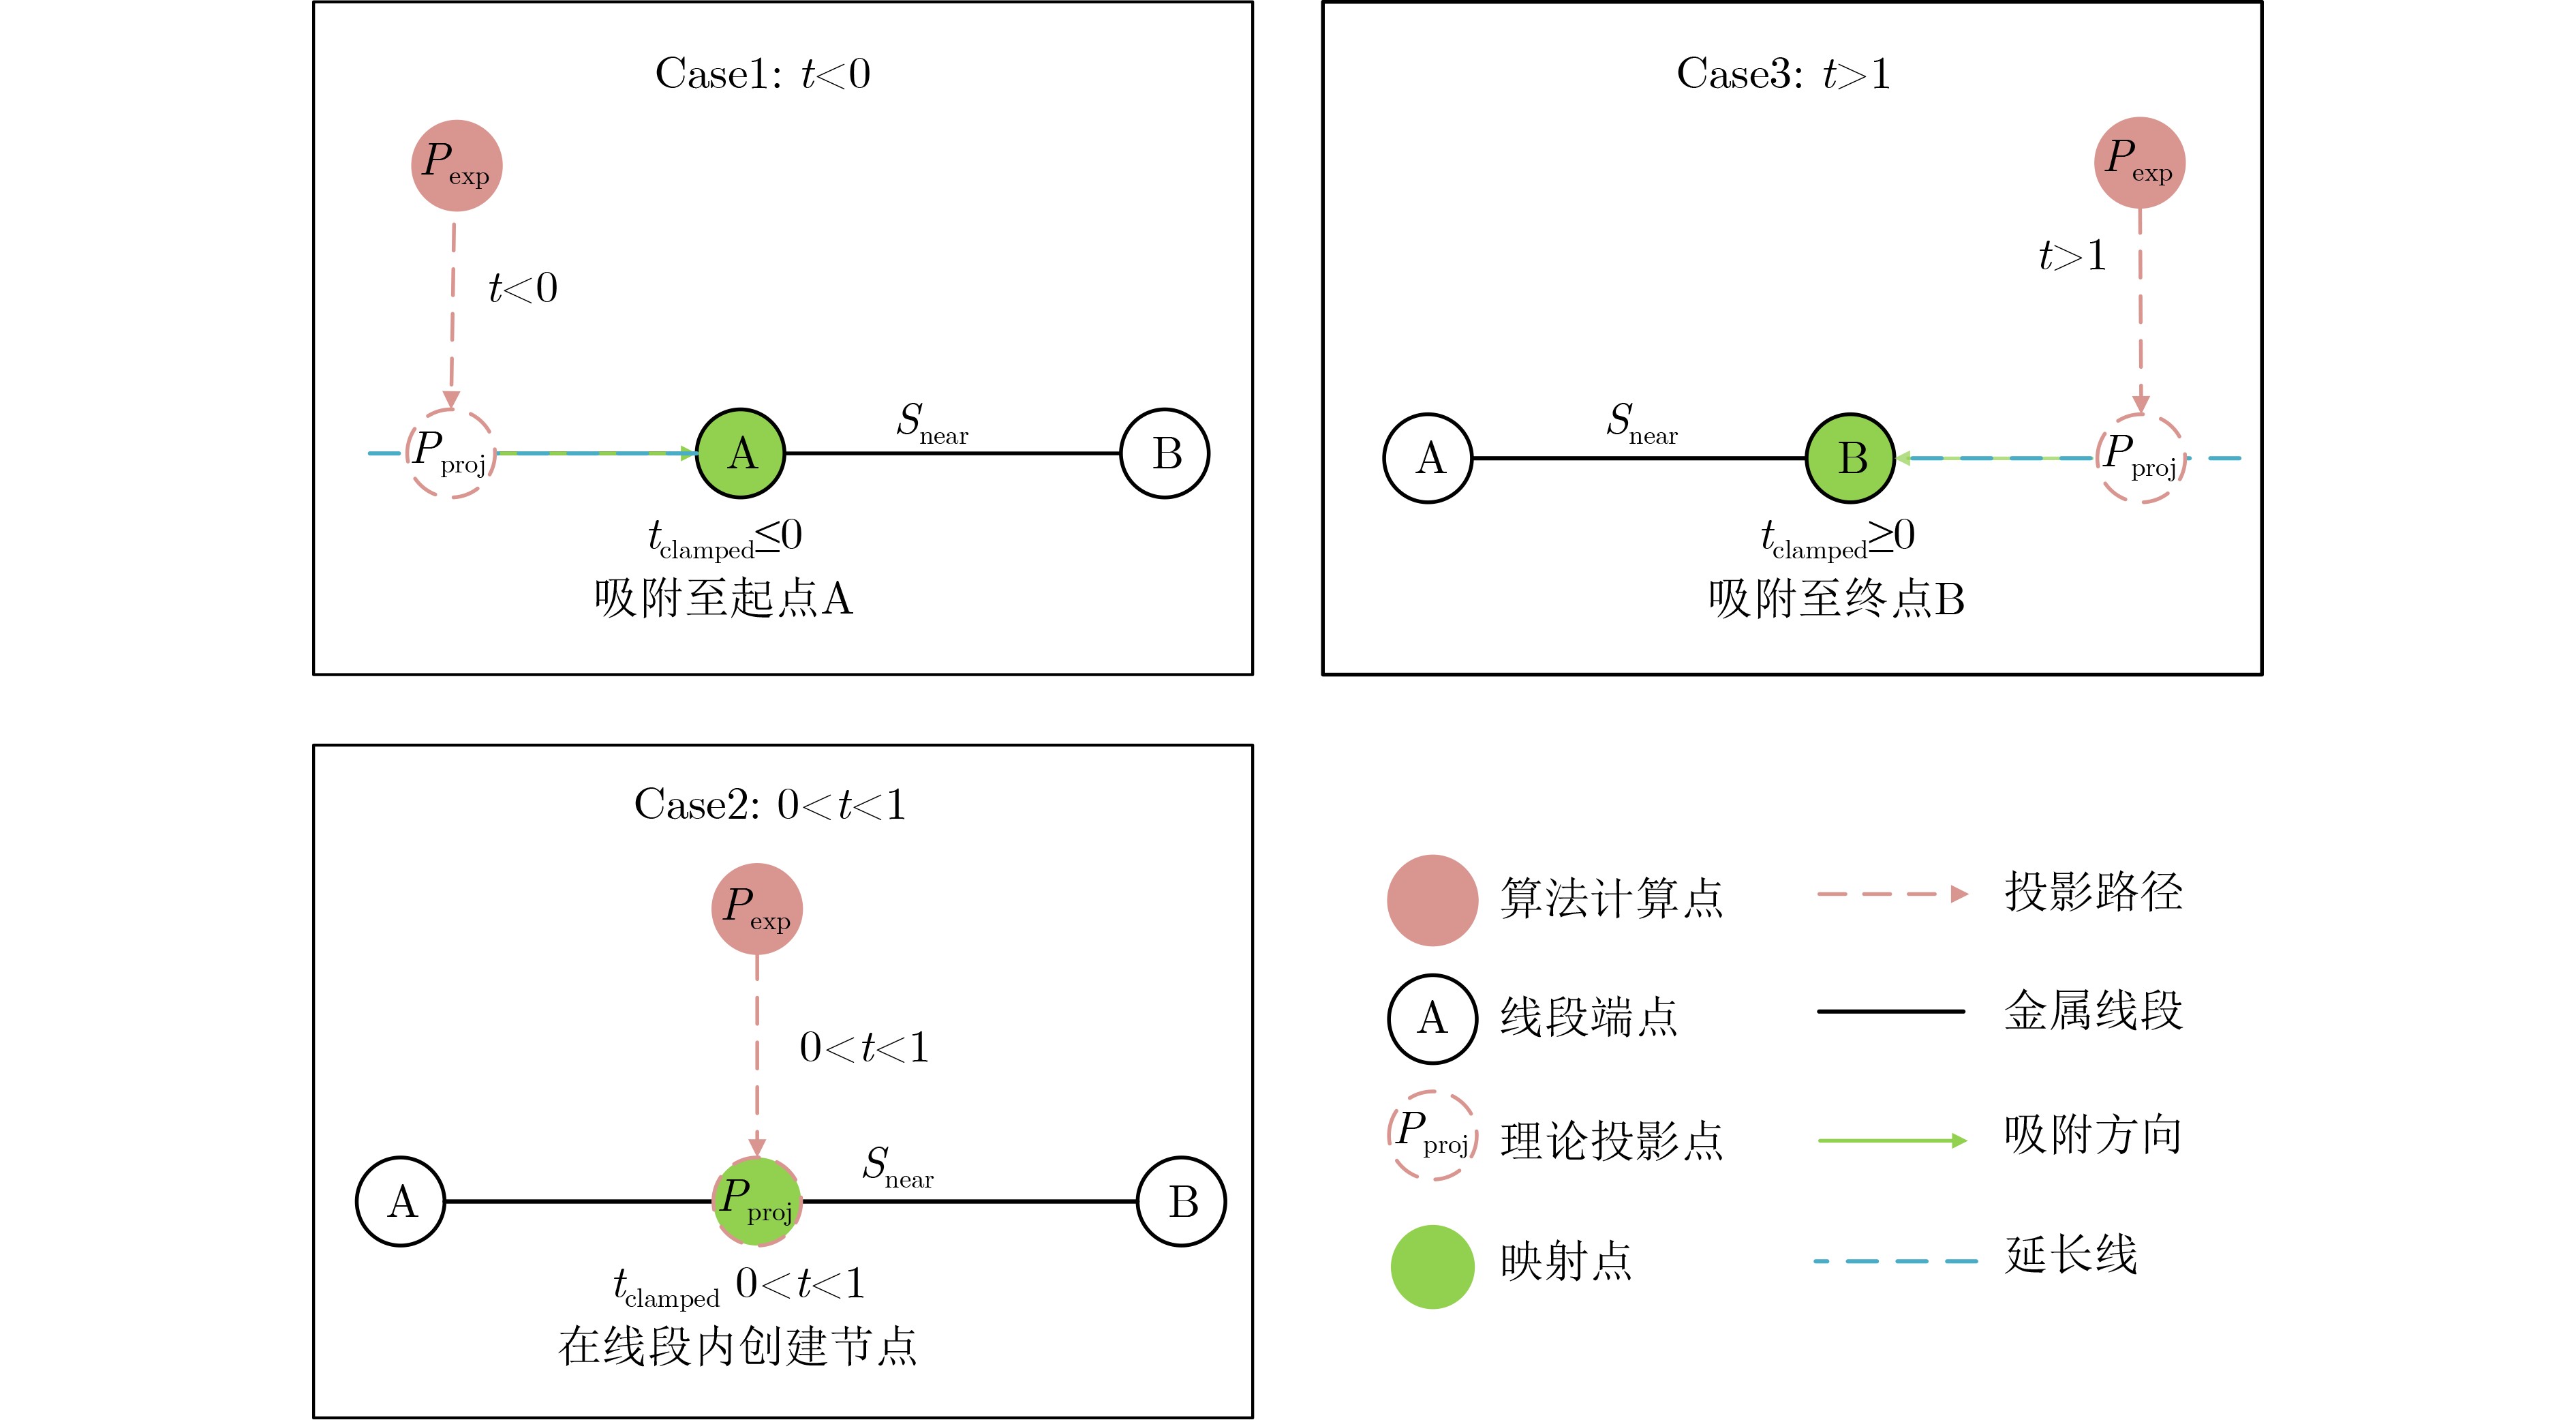
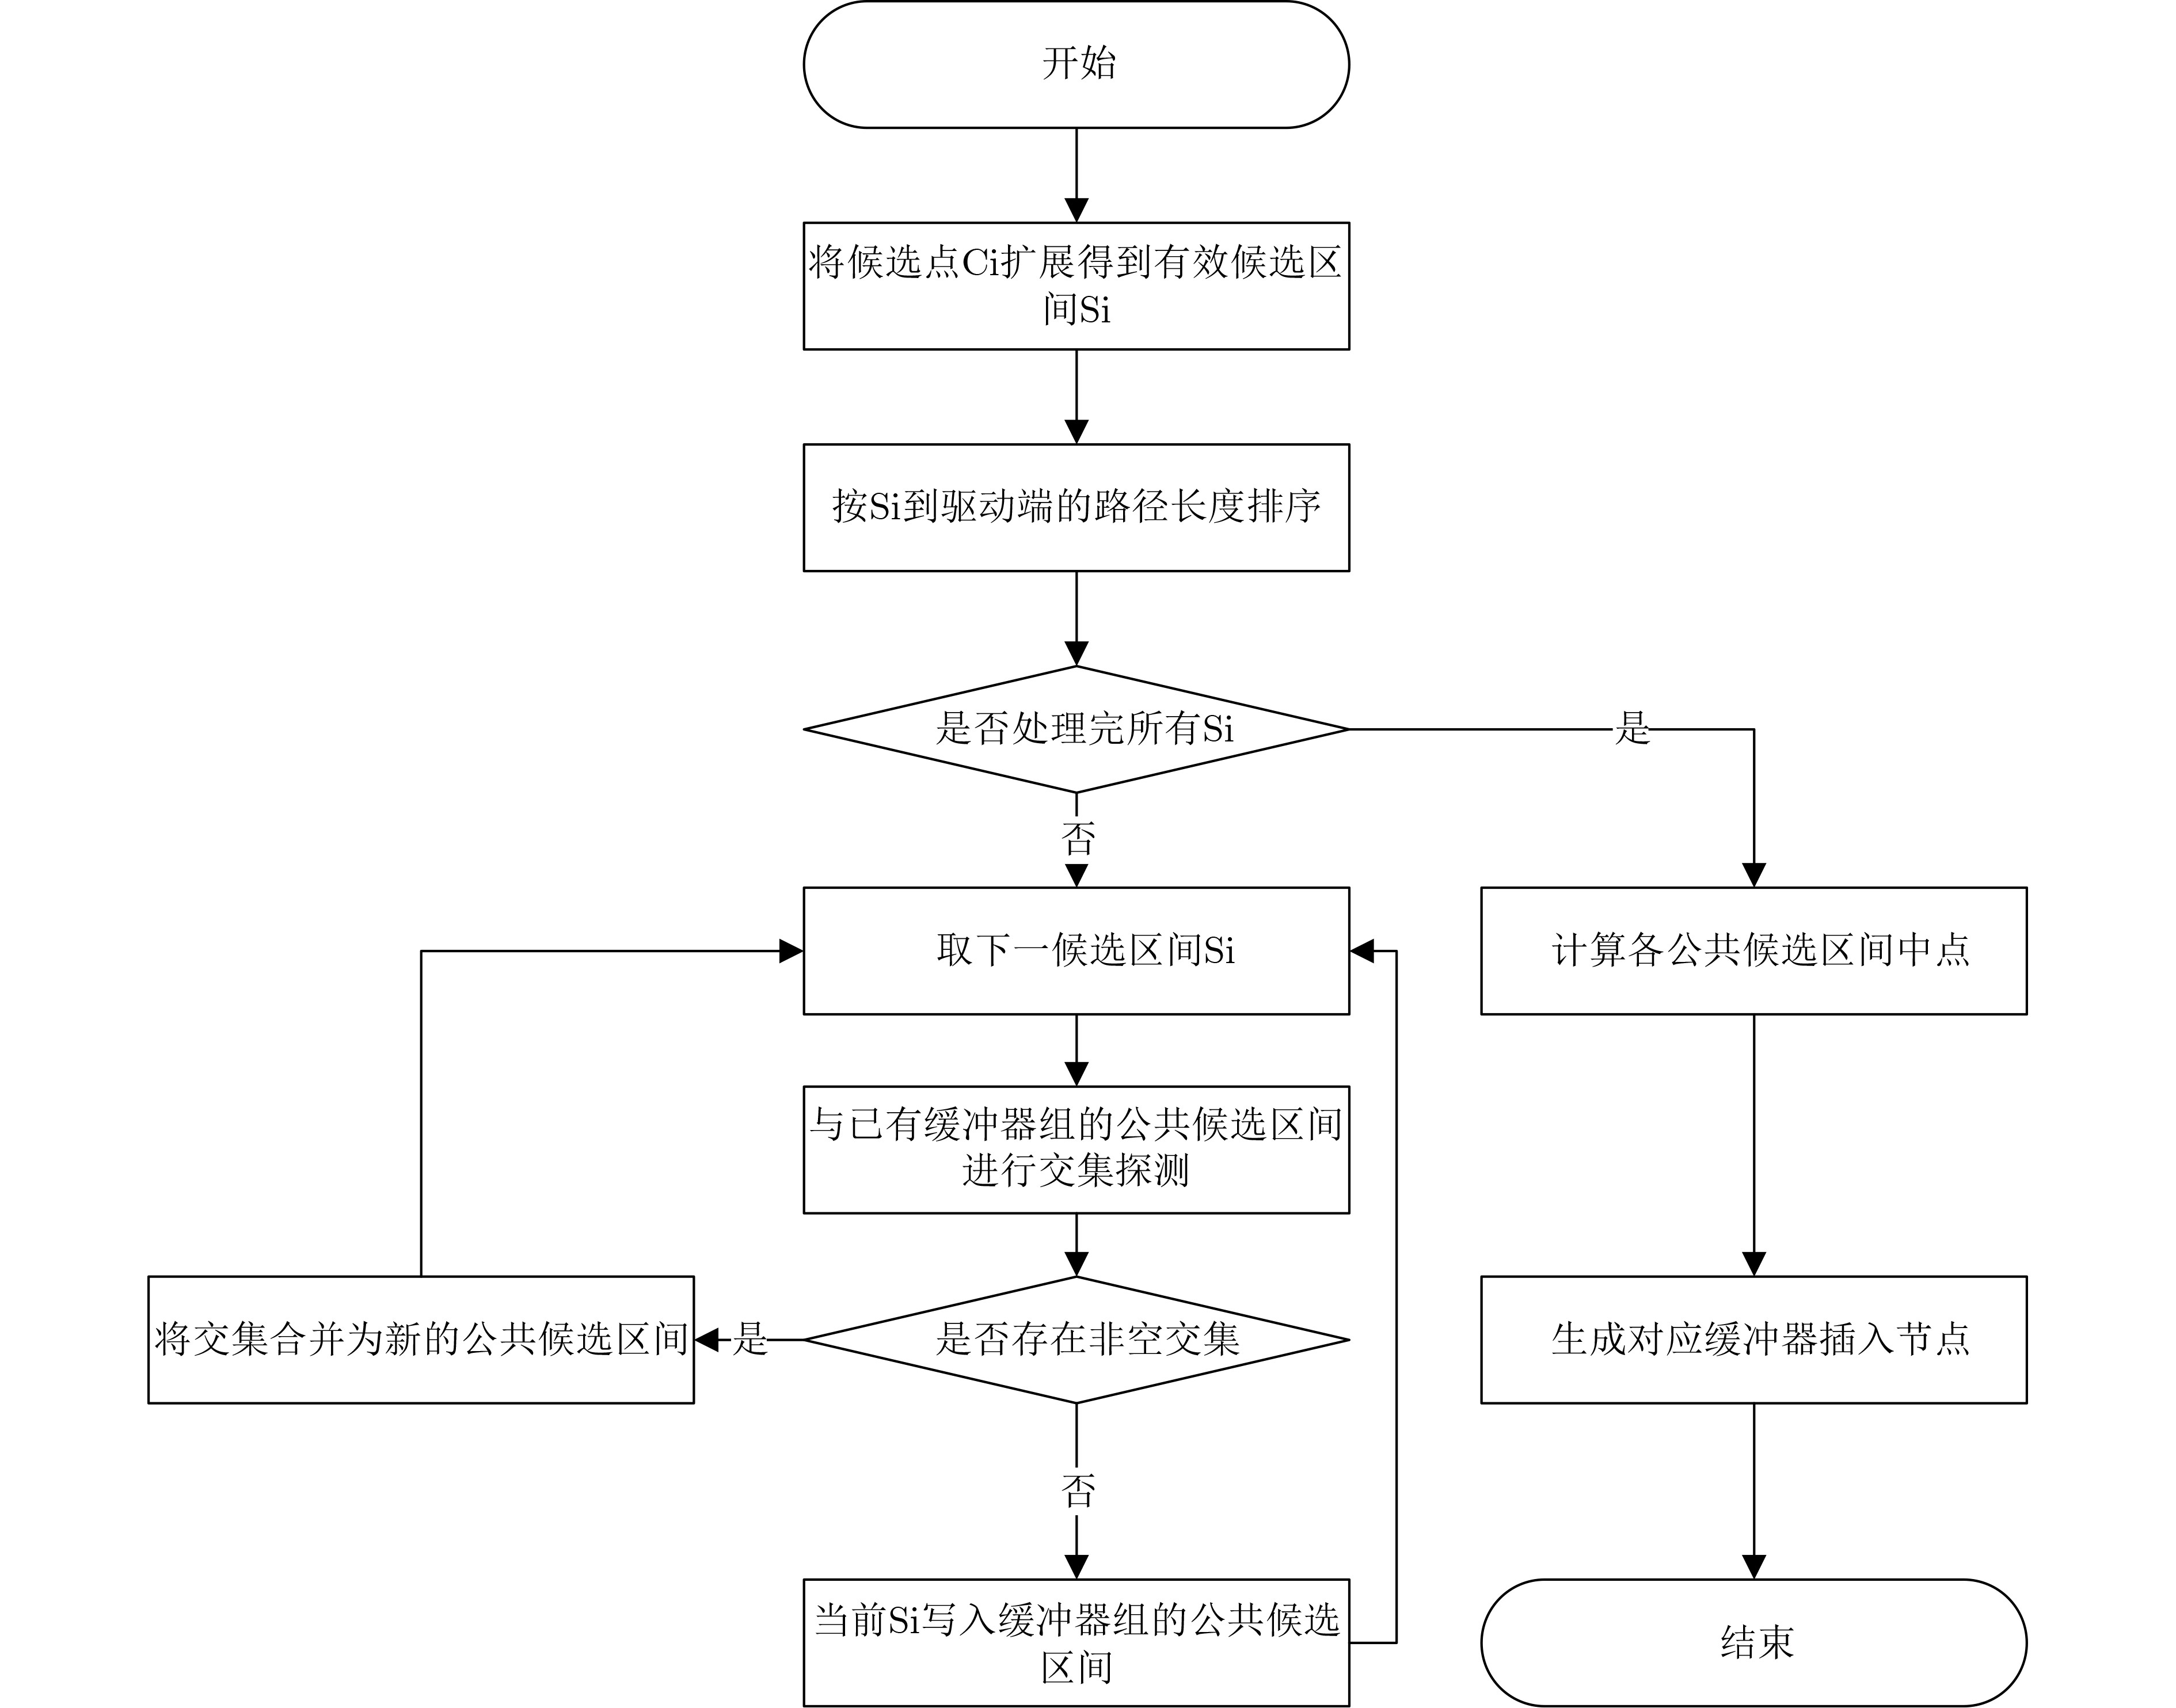
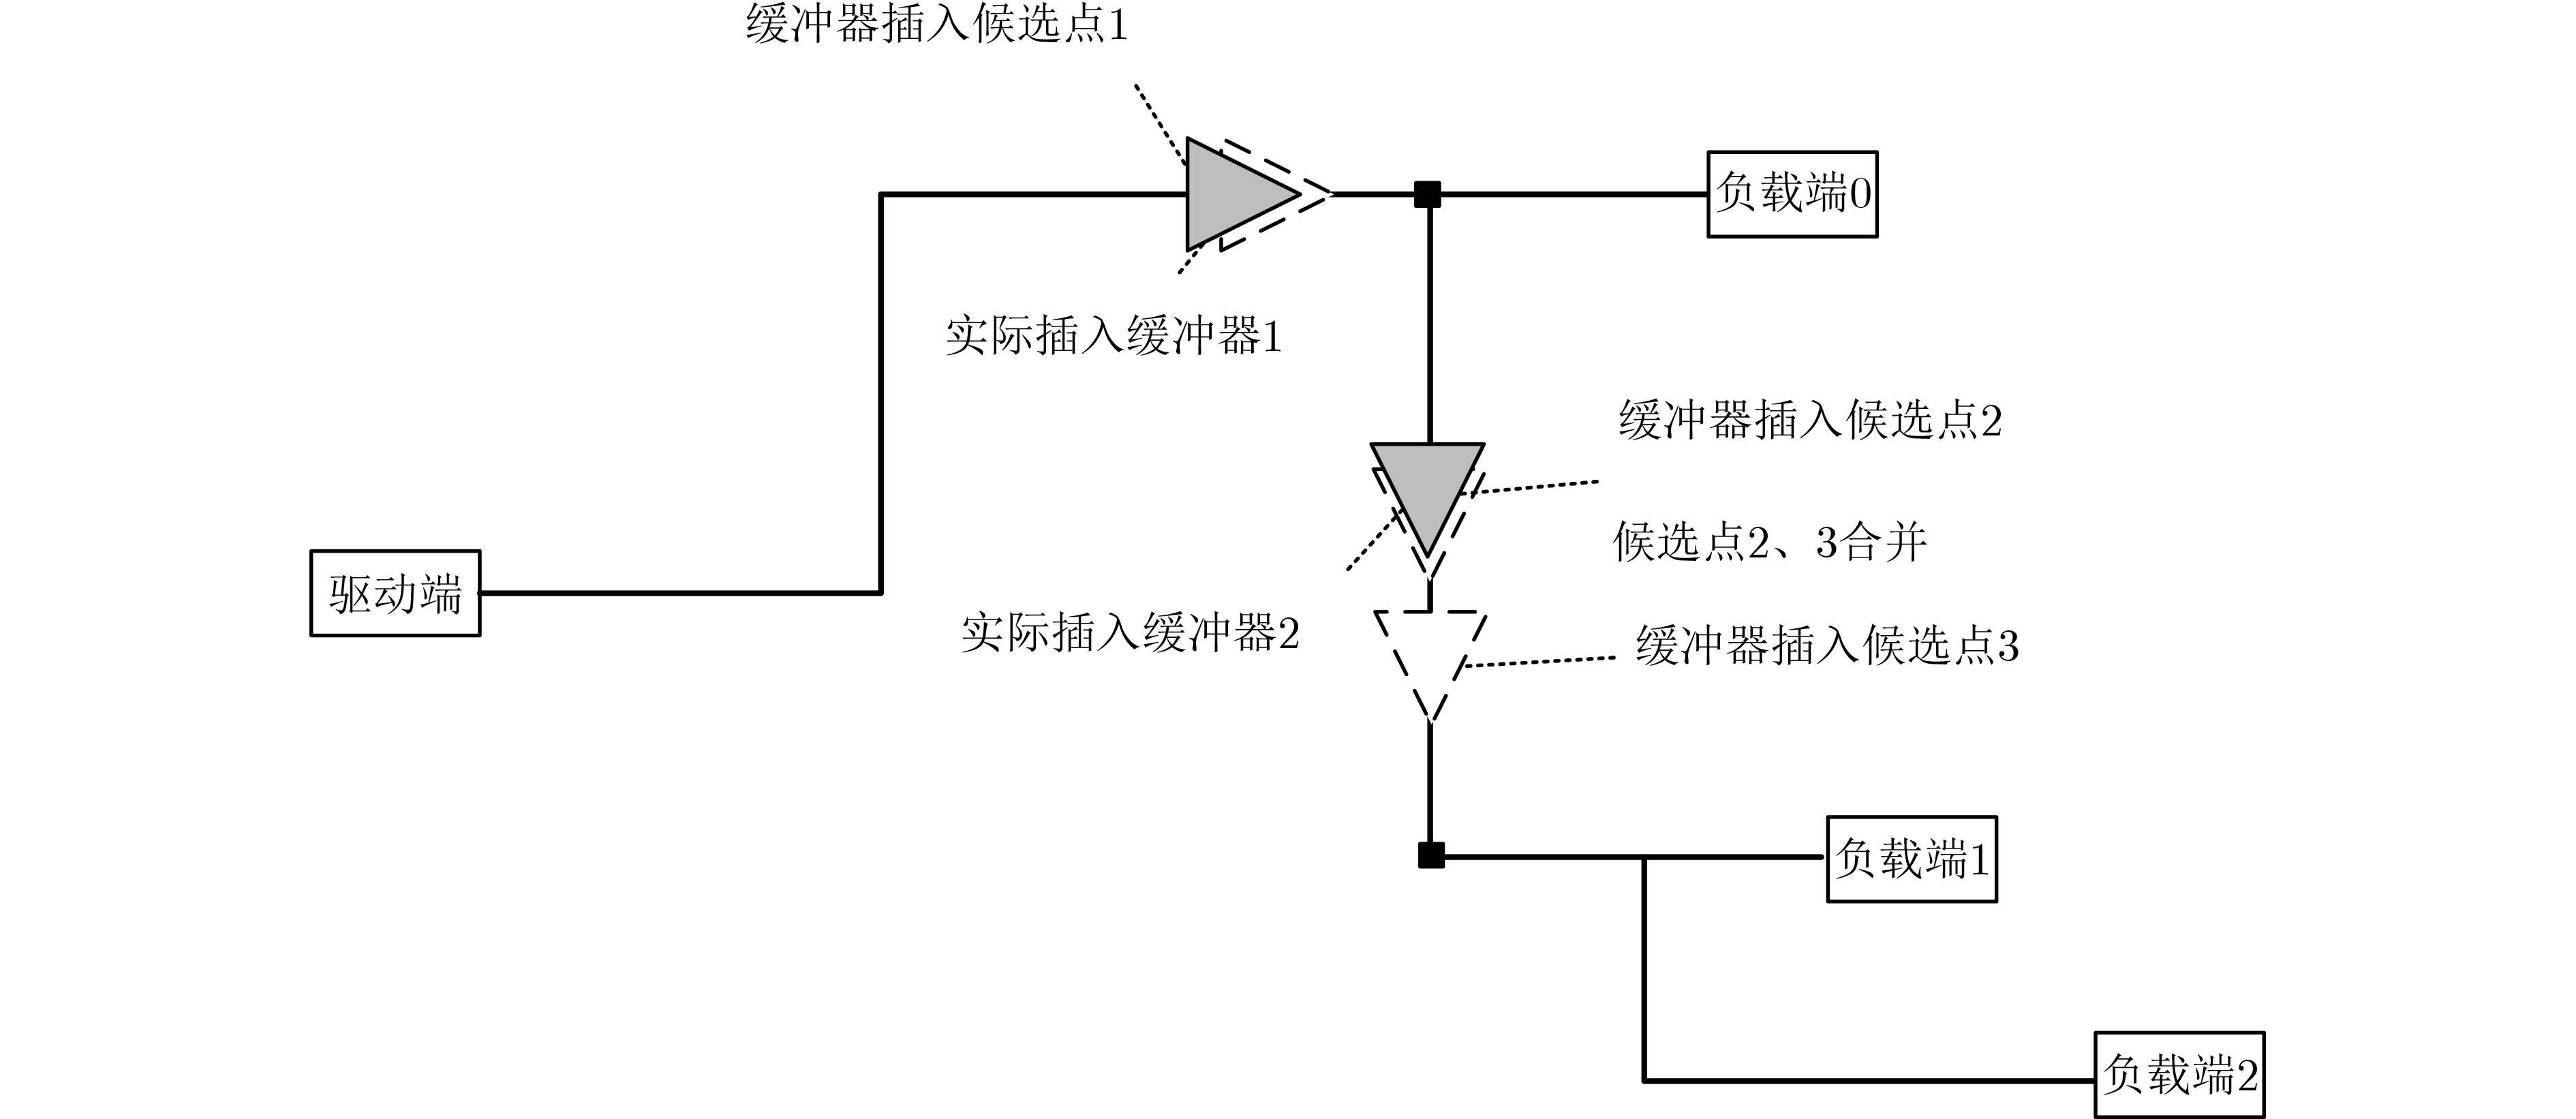
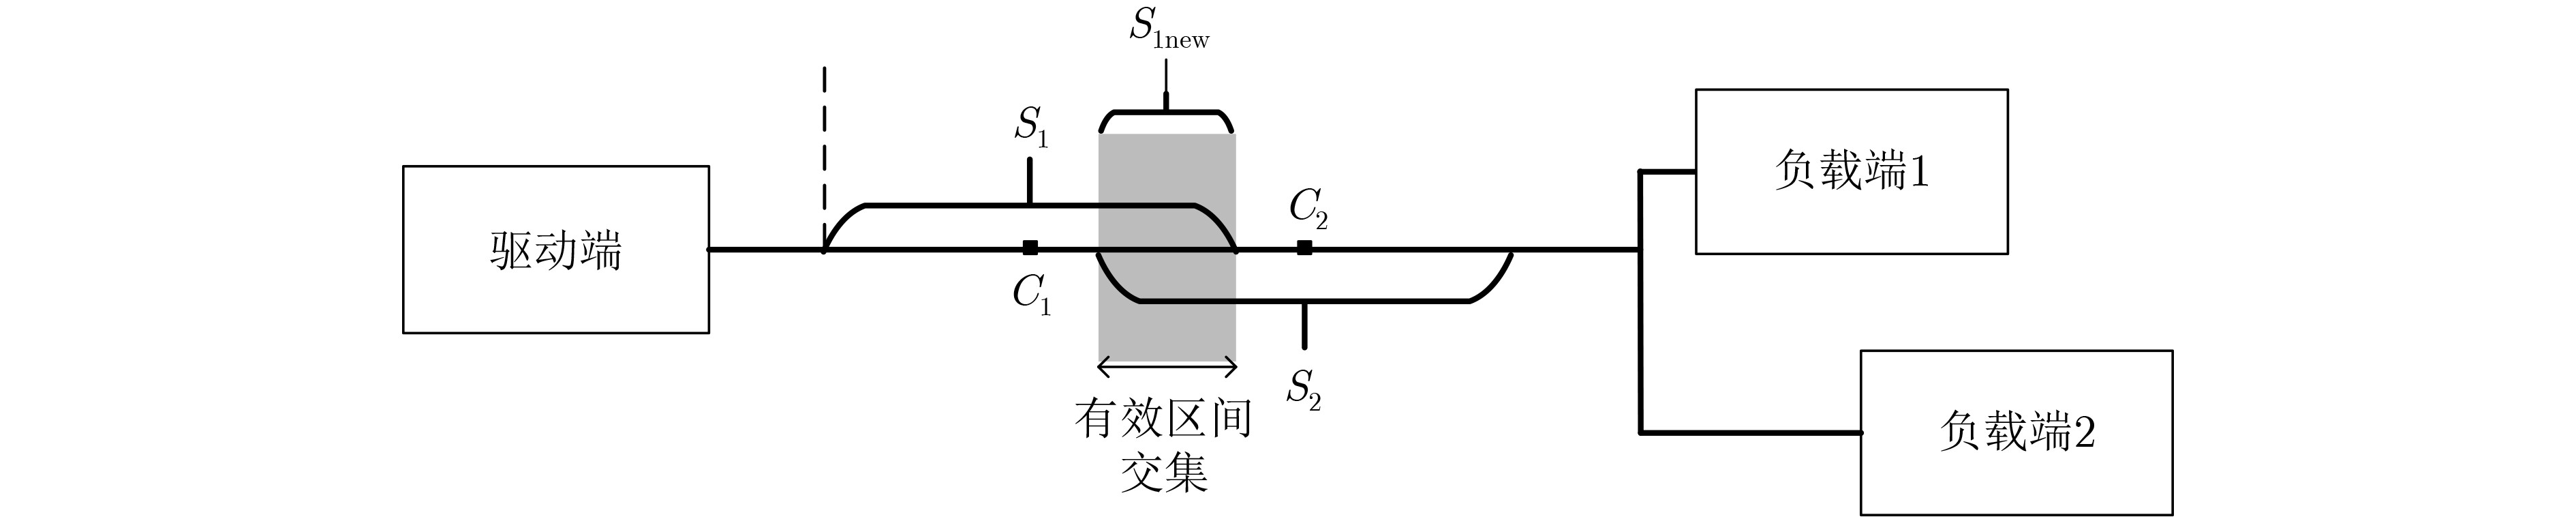
  •   Objective   Max transition violations in digital integrated circuit physical design may increase gate delay, reduce timing margin, and introduce additional power-consumption and signal-integrity risks. With technology scaling and the increasing complexity of high-performance SoC and CPU designs, long interconnects and heavy effective loads make such violations more prominent in post-routing optimization and ECO stages. Conventional repair methods usually rely on manual analysis or global heuristics, such as total-wire-length-ratio-based buffer insertion, which may lead to low repair efficiency, inaccurate repair targeting, and redundant buffer insertion in multi-load nets. Although these approaches can alleviate some violations in simple cases, they often fail to accurately identify the real violating branches in multi-load nets. As a result, repair targeting becomes insufficient and redundant buffer insertion is likely to occur. To address these limitations, a path-level buffer insertion method is proposed for max transition violation repair in multi-load nets.  Methods   The proposed method first reconstructs the physical topology of the target net from routing information extracted from the Design Exchange Format (DEF) file. Routing endpoints, turning points, and via connection points are abstracted as physical nodes with coordinate and metal-layer attributes, and a weighted undirected graph is established to preserve branch structures and cross-layer connectivity (Fig. 3). To reduce the influence of small coordinate deviations, a spatial-tolerance-based node merging strategy is introduced during graph construction. Since the violation coordinates reported by timing analysis tools may not lie exactly on valid routed segments, a vector-projection-based coordinate snapping strategy is then adopted to align logical violation coordinates with the actual physical topology (Fig. 4). After endpoint binding, the actual physical propagation path from the driver to each violating load is recovered by Dijkstra shortest-path search. Based on the Elmore-model intuition that inserting a buffer near the midpoint of a long interconnect can effectively segment the distributed RC load, the midpoint of each recovered path is selected as the initial candidate insertion point. The exact insertion coordinate is obtained by accumulating segment lengths along the path and interpolating on the segment where half of the total path length is reached. To improve robustness, the initial candidate point is further expanded into an effective candidate interval with a spatial tolerance factor. For multi-load nets, different violating branches may share long common physical segments. Therefore, an interval-intersection-based shared-buffer optimization strategy is introduced to merge overlapping candidate intervals into shared insertion regions, thereby reducing redundant buffer insertion (Fig. 5-Fig. 7).  Results and Discussions   Experiments are conducted on five designs, including CPU, SAS, RAID, PCIe, and HBA, implemented in the UMC 28 nm process. Synopsys IC Compiler II is used for physical implementation, and PrimeTime is used for timing analysis. A violation-margin threshold of -8 ps is adopted, and only paths below this threshold are included in the repair and evaluation. The complete ECO flow retains the existing repair method for single-load nets and applies the proposed path-level method to multi-load nets. To illustrate the repair mechanism, a representative multi-load violating net is selected for detailed analysis. The net contains one driver and fourteen loads, among which thirteen violating load paths share a long common routed trunk and exhibit max transition violation margins ranging from -75.2 ps to -38.3 ps. If these paths are repaired independently, thirteen nearby buffer insertion demands are generated on the shared trunk. After interval-intersection-based merging, one shared buffer is sufficient to repair all thirteen violating paths jointly (Fig. 8). This case study indicates that path recovery improves repair targeting, while shared-buffer optimization improves resource efficiency. Across the five designs, the complete ECO flow reduces the total number of max transition violations from 10,616 to 108, corresponding to an overall repair rate of 98.98% (Table 1). The CPU, SAS, and RAID designs are completely repaired, while only 17 and 91 violations remain in PCIe and HBA, respectively. Among the 8,216 multi-load violating paths, 8,166 are successfully repaired, corresponding to a multi-load violation repair rate of 99.39%. If these successfully repaired paths were handled independently, 8,166 buffer insertions would be required. After shared-buffer optimization, only 1,548 buffers are inserted, giving an overall compression ratio of 81.04%. The setup worst negative slack, total negative slack, and number of violating paths remain generally stable before and after repair, with only minor fluctuations observed in individual designs (Table 2). These results show that the repair flow does not cause obvious degradation in setup timing quality. Further analysis indicates that the residual violations in PCIe and HBA mainly occur when candidate buffer locations fall inside standard-cell placement blockages around hard macros or IP cores. Metal routing is allowed through these regions, but buffers cannot be legally placed, revealing a current limitation in the physical-feasibility handling of candidate insertion locations.  Conclusions   A path-level buffer insertion method is proposed for max transition violation repair in multi-load nets. By combining physical topology reconstruction, violation-coordinate snapping, shortest-path-based path recovery, midpoint-guided candidate generation, and interval-intersection-based shared-buffer optimization, the proposed method improves repair targeting and reduces redundant buffer insertion. Experimental results on five designs show that the complete ECO flow reduces the number of max transition violations from 10,616 to 108, achieving an overall repair rate of 98.98%. Among the 8,216 multi-load violating paths, 8,166 are successfully repaired, corresponding to a repair rate of 99.39%. For these successfully repaired paths, shared-buffer optimization reduces the number of buffer insertion demands from 8,166 to 1,548, corresponding to a compression ratio of 81.04%, without causing obvious degradation in setup timing quality. The remaining violations are mainly associated with standard-cell placement blockages around hard macros or IP cores, indicating that the physical-feasibility handling of candidate insertion locations should be further improved.
  • loading
  • [1]
    田春生, 陈雷, 王源, 等. 基于图神经网络的电子设计自动化技术研究进展[J]. 电子与信息学报, 2023, 45(9): 3069–3082. doi: 10.11999/JEIT230266.

    TIAN Chunsheng, CHEN Lei, WANG Yuan, et al. A survey for electronic design automation based on graph neural network[J]. Journal of Electronics & Information Technology, 2023, 45(9): 3069–3082. doi: 10.11999/JEIT230266.
    [2]
    KAHNG A B. Panel statement: EDA needs at advanced technology nodes[C]. Proceedings of the 2024 International Symposium on Physical Design, Taipei, China, 2024: 63. doi: 10.1145/3626184.3639696.
    [3]
    TARAATE V. Design constraints and SDC commands[M]. TARAATE V. ASIC Design and Synthesis: RTL Design Using Verilog. Singapore: Springer, 2021: 139–151. doi: 10.1007/978-981-33-4642-0_10.
    [4]
    刘峰. 集成电路静态时序分析与建模[M]. 北京: 机械工业出版社, 2016.

    LIU Feng. Static Timing Analysis and Modeling of Integrated Circuits[M]. Beijing: China Machine Press, 2016. (查阅网上资料, 未找到本条文献英文翻译信息, 请确认).
    [5]
    陈春章, 艾霞, 王国雄. 数字集成电路物理设计[M]. 北京: 科学出版社, 2008.

    CHEN Chunzhang, AI Xia, and WANG Guoxiong. Physical Design of Digital Integrated Circuits[M]. Beijing: Science Press, 2008. (查阅网上资料, 未找到本条文献英文翻译信息, 请确认).
    [6]
    CHANG K and KIM T. Pre-route timing prediction and optimization with graph neural network models[J]. Integration, 2024, 99: 102262. doi: 10.1016/j.vlsi.2024.102262.
    [7]
    冯善亮, 杨兵, 陈亮. 基于时间窃取的数字电路时序优化方法[J]. 微电子学与计算机, 2023, 40(8): 114–124. doi: 10.19304/J.ISSN1000-7180.2022.0619.

    FENG Shanliang, YANG Bing, and CHEN Liang. Timing optimization method for digital circuits based on timing borrow[J]. Microelectronics & Computer, 2023, 40(8): 114–124. doi: 10.19304/J.ISSN1000-7180.2022.0619.
    [8]
    WU Hongxi, HUANG Zhipeng, LI Xingquan, et al. AiTO: Simultaneous gate sizing and buffer insertion for timing optimization with GNNs and RL[J]. Integration, 2024, 98: 102211. doi: 10.1016/j.vlsi.2024.102211.
    [9]
    PU Yuan, JI Yuhao, YU Siying, et al. GPU acceleration for versatile buffer insertion[C]. Proceedings of the 2025 IEEE/ACM International Conference on Computer Aided Design (ICCAD), Munich, Germany, 2025: 1–9. doi: 10.1109/ICCAD66269.2025.11240837.
    [10]
    DU Yufan, GUO Zizheng, WANG Runsheng, et al. Differentiable physical optimization[C]. Proceedings of the 2025 IEEE/ACM International Conference on Computer Aided Design (ICCAD), Munich, Germany, 2025: 1–9. doi: 10.1109/ICCAD66269.2025.11240839.
    [11]
    陈家瑞, 吴昭怡, 游勇杰, 等. 基于概率模型的集成电路寄生参数提取算法[J]. 电子与信息学报, 2025, 47(9): 3198–3207. doi: 10.11999/JEIT250458.

    CHEN Jiarui, WU Zhaoyi, YOU Yongjie, et al. A probability-based parasitic extraction algorithm for global-routed VLSI designs[J]. Journal of Electronics & Information Technology, 2025, 47(9): 3198–3207. doi: 10.11999/JEIT250458.
    [12]
    BHASKER J and CHADHA R. Standard cell library[M]. CHADHA R and BHASKER J. Static Timing Analysis for Nanometer Designs: A Practical Approach. New York, USA: Springer, 2009: 43–100. doi: 10.1007/978-0-387-93820-2_3.
    [13]
    HU Shiyan and HU Jiang. A fast general slew constrained minimum cost buffering algorithm[J]. Microelectronics Journal, 2009, 40(10): 1482–1486. doi: 10.1016/j.mejo.2009.08.003.
    [14]
    张祥, 赵启林. 基于缓冲器的ASIC芯片时序优化设计[J]. 集成电路与嵌入式系统, 2024, 24(12): 33–37. doi: 10.20193/j.ices2097-4191.2024.0046.

    ZHANG Xiang and ZHAO Qilin. Timing optimization design of ASIC chip based on buffer[J]. Integrated Circuits and Embedded Systems, 2024, 24(12): 33–37. doi: 10.20193/j.ices2097-4191.2024.0046.
    [15]
    秋小强, 杨海钢, 周发标, 等. 长互连链延时功耗建模与基于混合粒子群算法的优化[J]. 电子与信息学报, 2011, 33(6): 1481–1486. doi: 10.3724/SP.J.1146.2010.01114.

    QIU Xiaoqiang, YANG Haigang, ZHOU Fabiao, et al. Analysis of delay-power model of long chain and optimization based on hybrid evolution particle swarm algorithm[J]. Journal of Electronics & Information Technology, 2011, 33(6): 1481–1486. doi: 10.3724/SP.J.1146.2010.01114.
    [16]
    SAINI S. Buffer insertion as a solution to interconnect issues[M]. SAINI S. Low Power Interconnect Design. New York, USA: Springer, 2015: 57–74. doi: 10.1007/978-1-4614-1323-3_3.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(8)  / Tables(3)

    Article Metrics

    Article views (69) PDF downloads(7) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return