Advanced Search
Turn off MathJax
Article Contents
YU Tianyang, WU Bi, LIU Weiqiang. Efficient Hyperdimensional Computing Accelerator Design for Chinese Text Classification[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260556
Citation: YU Tianyang, WU Bi, LIU Weiqiang. Efficient Hyperdimensional Computing Accelerator Design for Chinese Text Classification[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260556

Efficient Hyperdimensional Computing Accelerator Design for Chinese Text Classification

doi: 10.11999/JEIT260556 cstr: 32379.14.JEIT260556
Funds:  The National Natural Science Foundation of China (62425404, 92364201, 62522406), Basic Research Program of Jiangsu (BK20253023)
  • Received Date: 2026-05-06
  • Accepted Date: 2026-07-28
  • Rev Recd Date: 2026-07-16
  • Available Online: 2026-08-07
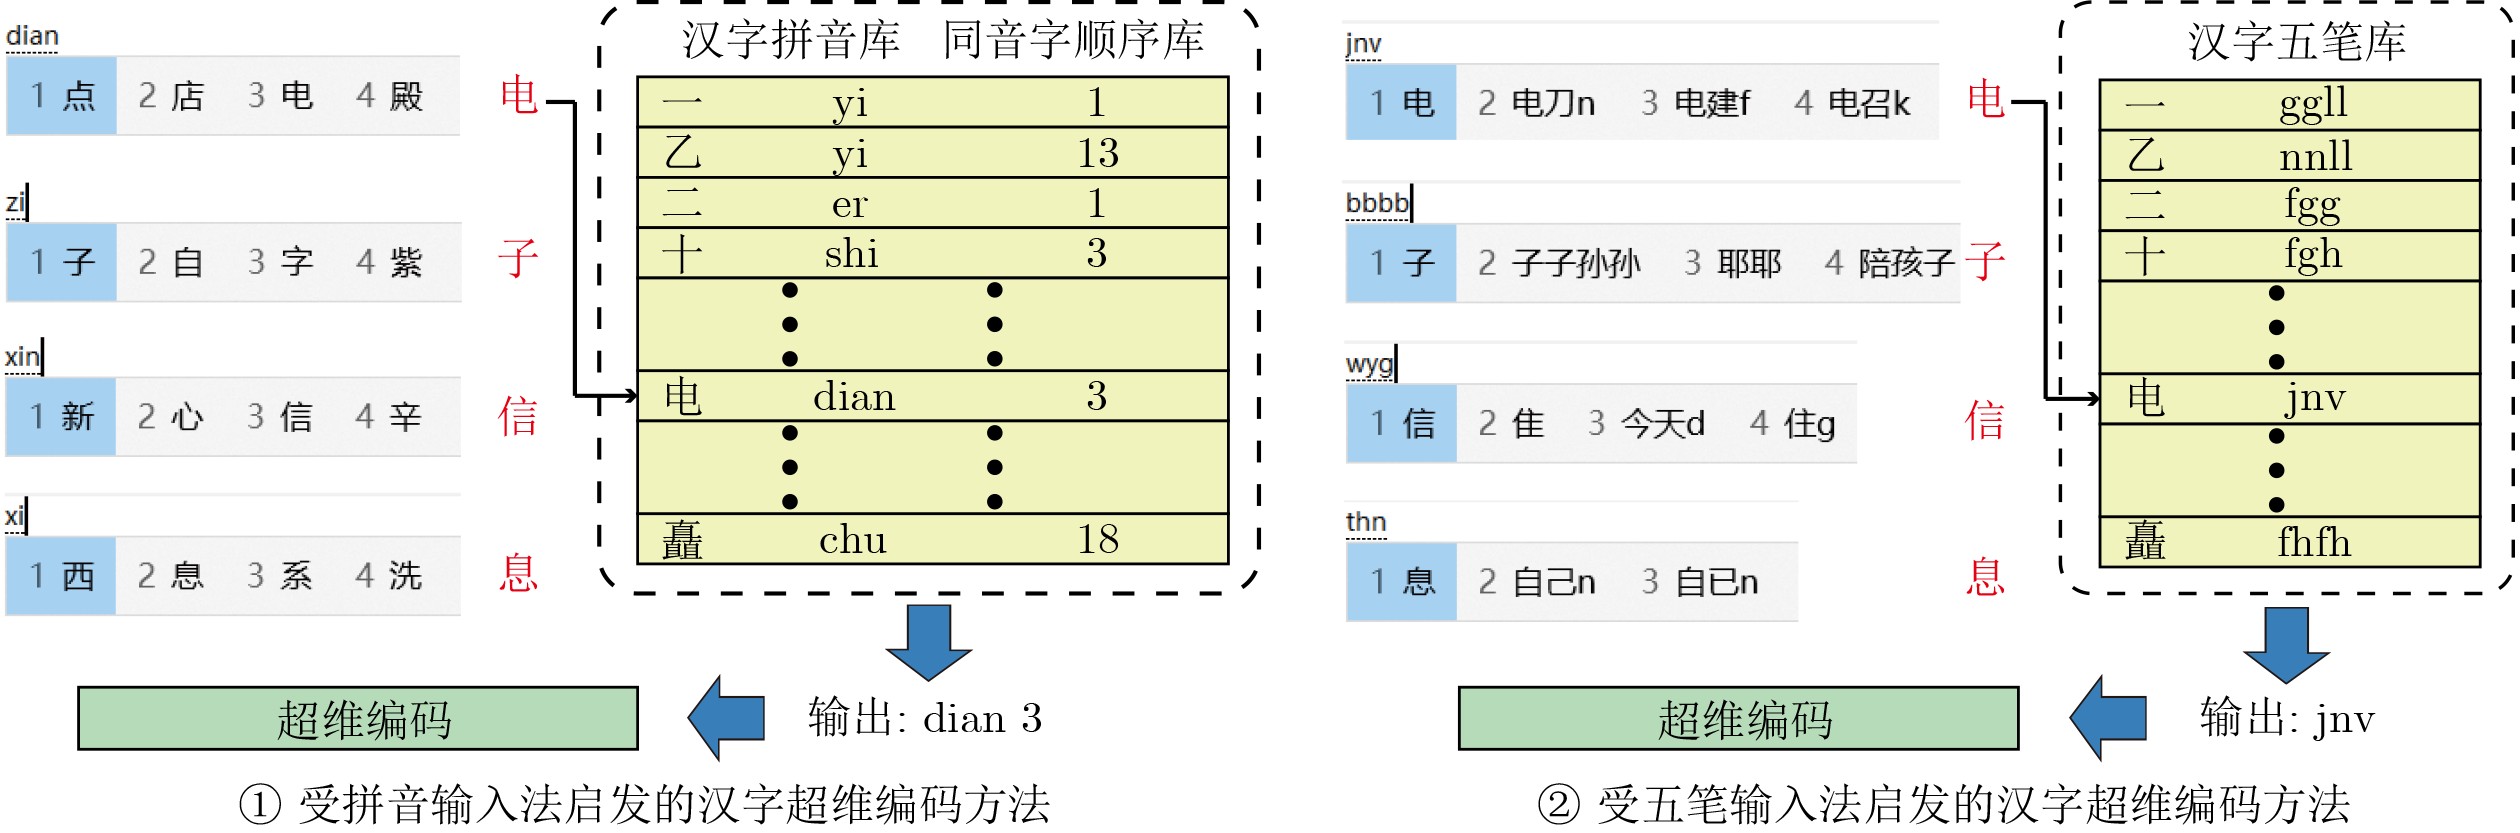
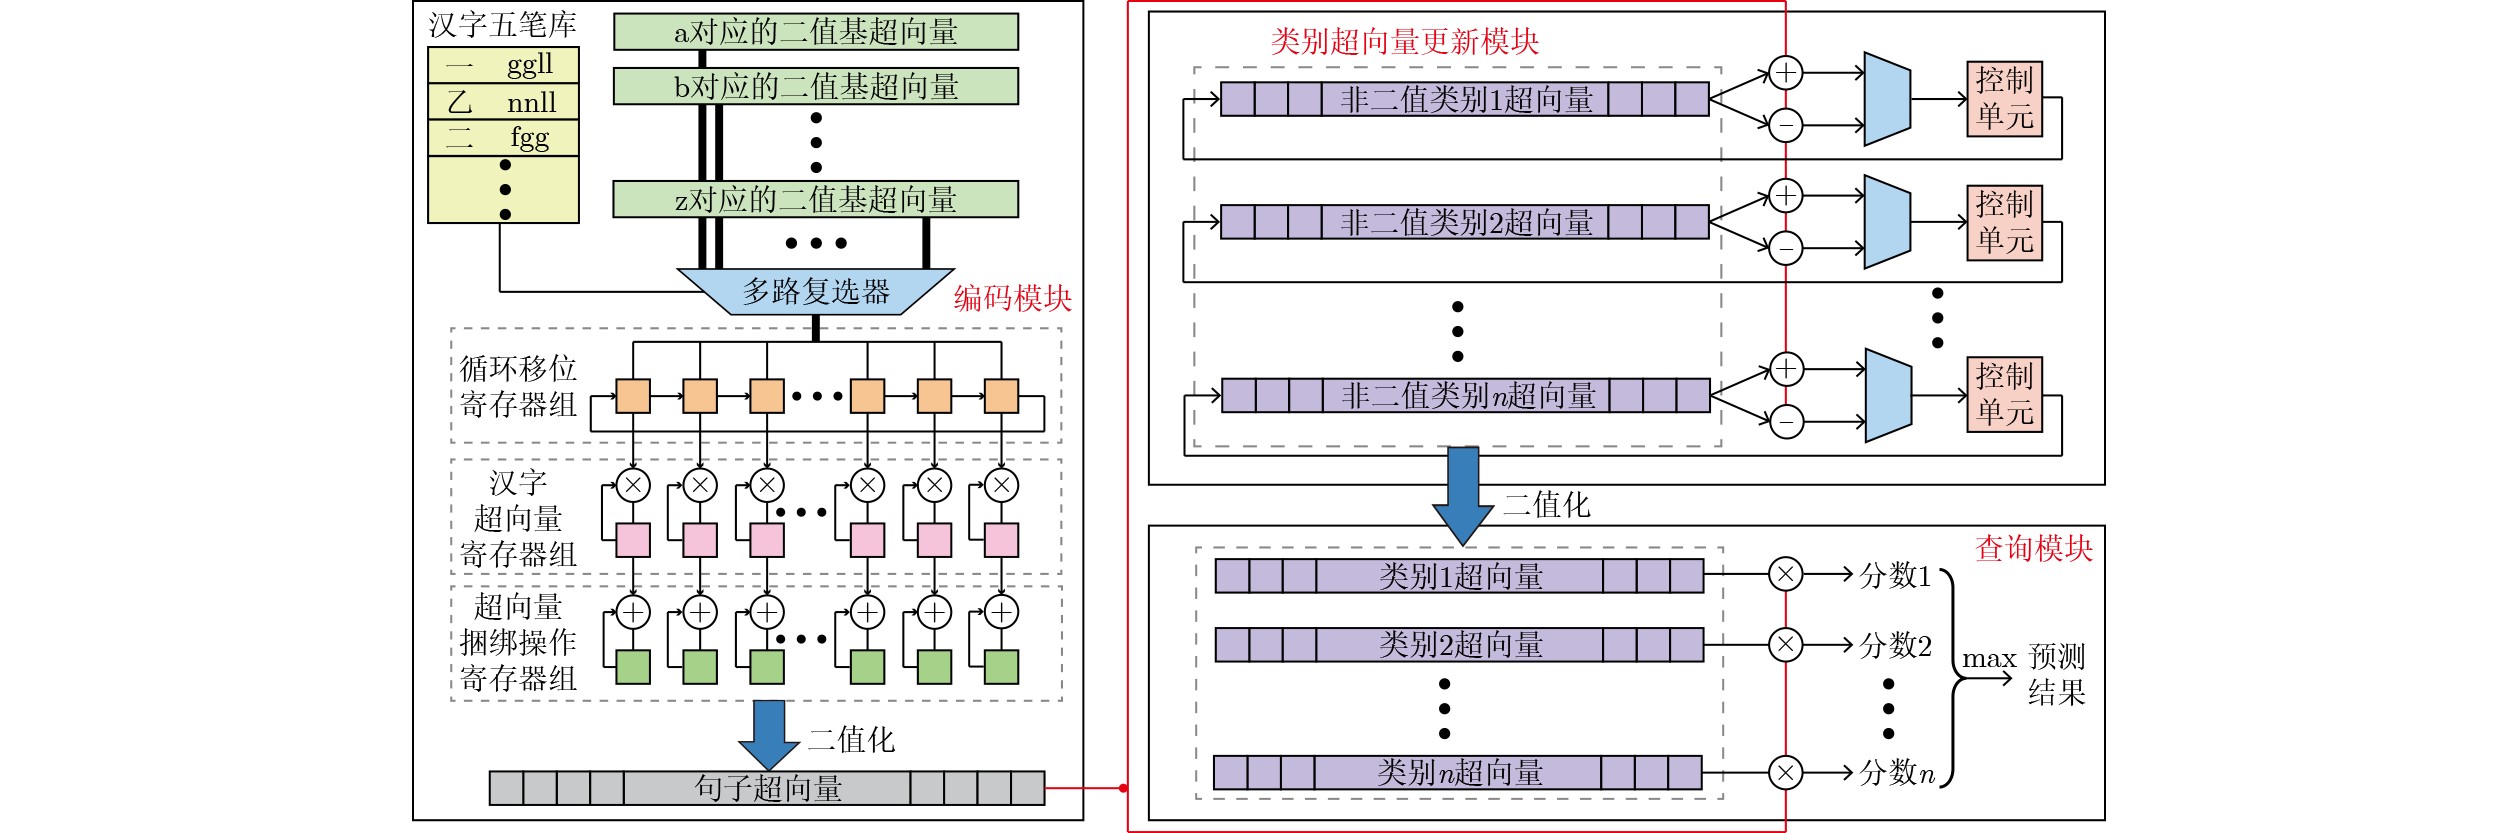
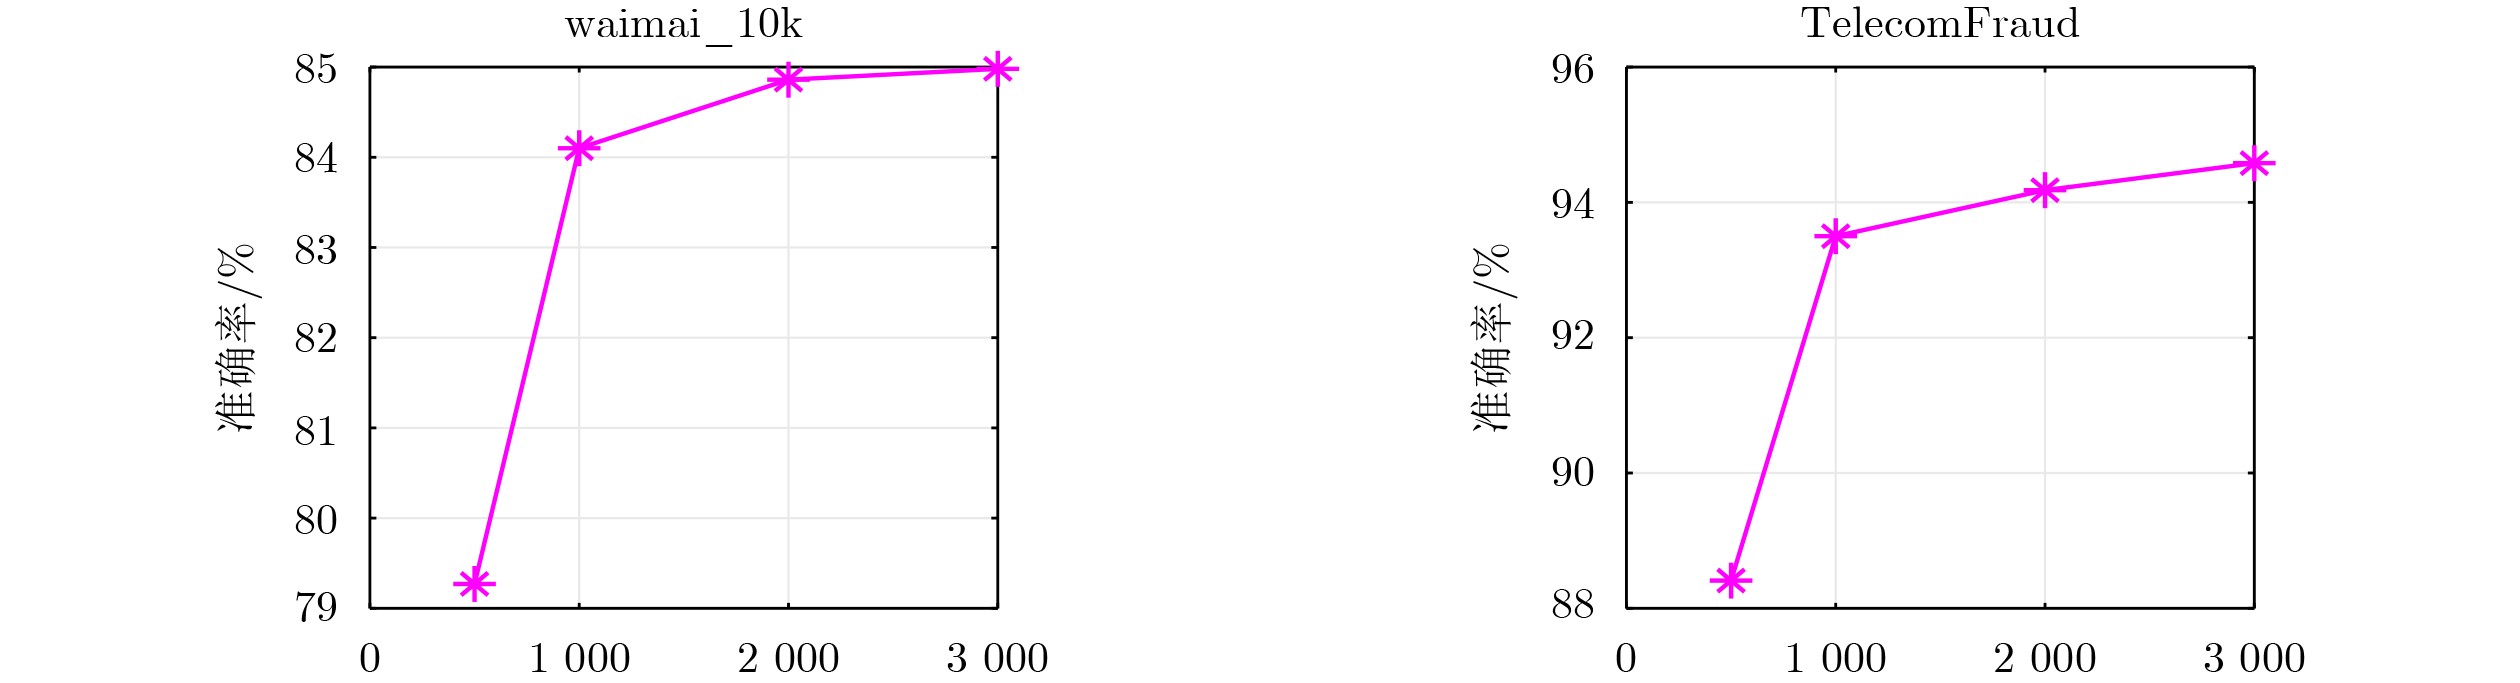
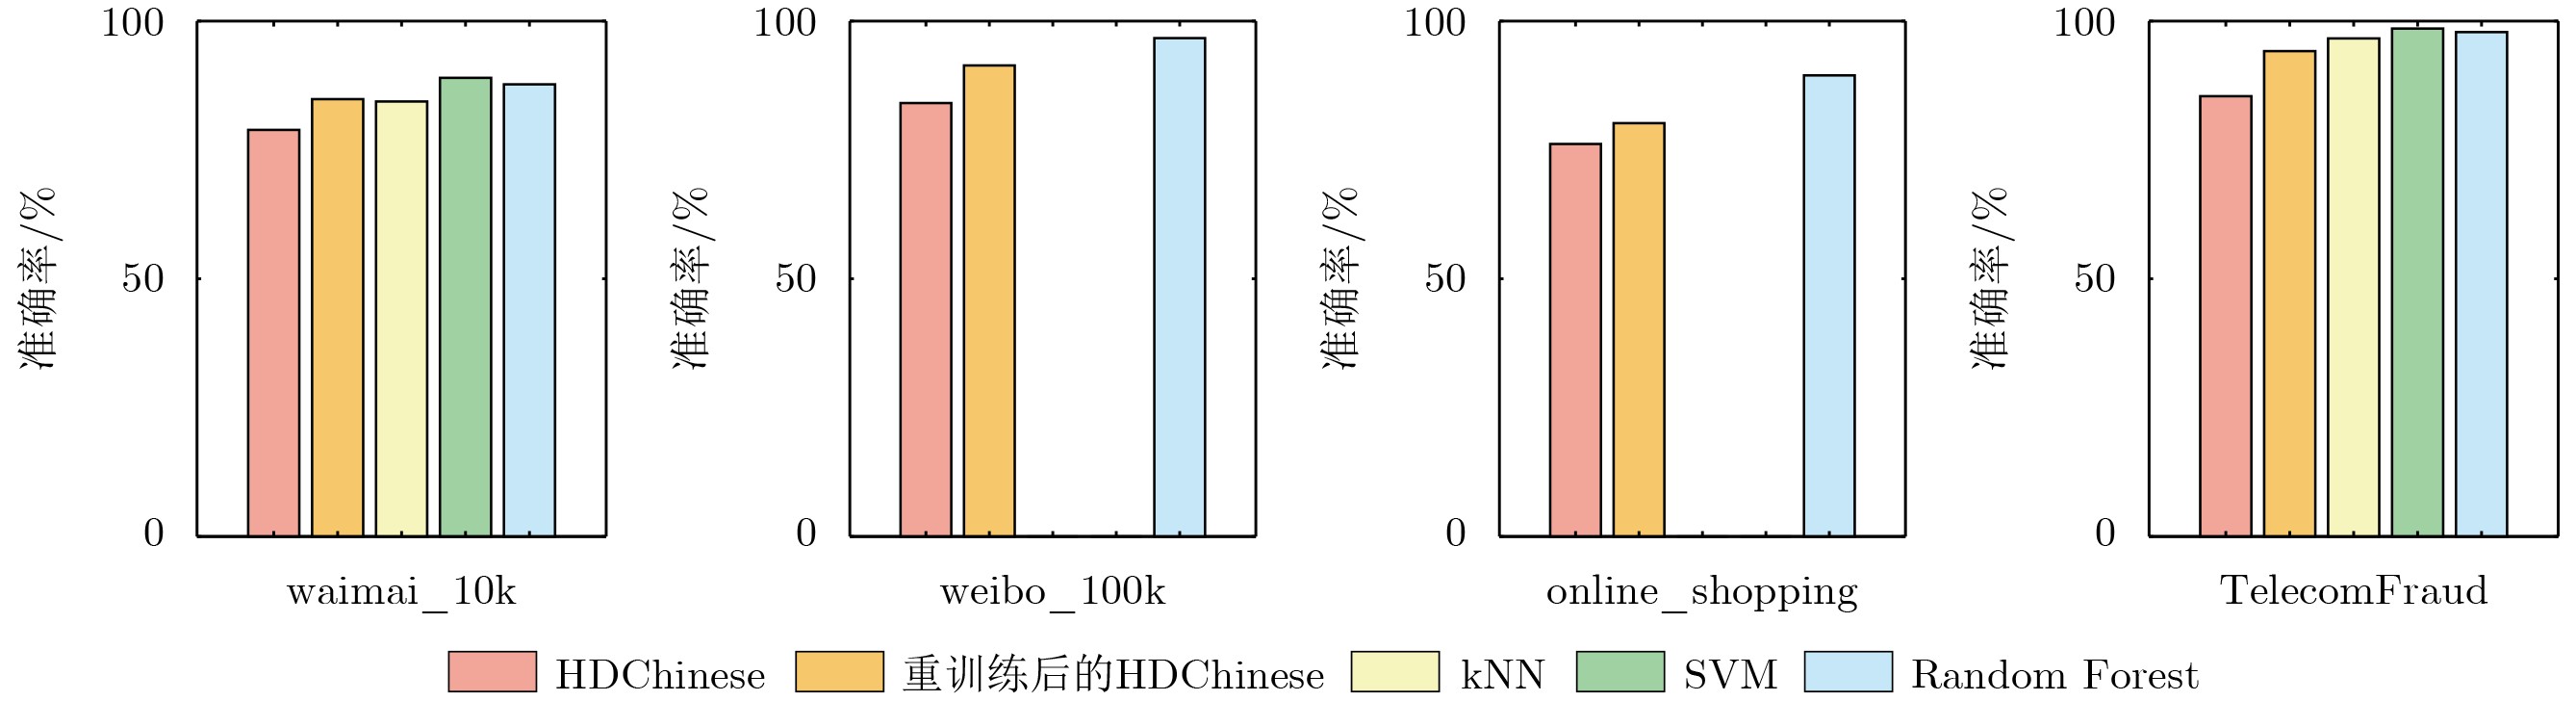
  •   Objective  With the proliferation of edge computing in the Internet of Things (IoT), smart wearables, and offline terminals, low-latency and privacy-preserving Chinese text analysis on local devices has become a core requirement. Although neural network-based and Transformer-based language models achieve high accuracy, their large parameter sizes and computational demands make them difficult to deploy on power- and storage-constrained edge devices. HyperDimensional Computing (HDC), an emerging brain-inspired computing paradigm, represents text using 2 k~10 k-dimensional hypervectors and employs lightweight encoding and querying mechanisms instead of complex multilayer networks, providing a hardware-friendly approach for edge-side text processing. However, existing HDC studies have mainly focused on alphabetic writing systems such as English, in which a limited set of letters is sufficient for N-gram encoding. For Chinese, which contains thousands of commonly used characters, directly applying these methods would require a large number of base hypervectors, resulting in substantial storage overhead and weakening the lightweight advantage of HDC. This paper aims to address this limitation by proposing an efficient character encoding method and a dedicated HDC framework with hardware acceleration for Chinese text classification.  Methods  Based on the glyph structure of Chinese characters, a hyperdimensional encoding method based on character glyph structure is proposed. Specifically, the encoding process of the Wubi input method is reverse-engineered to decompose each Chinese character into an equivalent Wubi letter sequence for efficient hyperdimensional encoding. A retrieval library covering 3 500 commonly used Chinese characters, as defined in the General Standard Chinese Characters Table issued by the Ministry of Education of the People’s Republic of China, is constructed. For each character, the Wubi library is queried to obtain a letter sequence of length 3 or 4, with each letter mapped to a base hypervector. Cyclic shift and binding operations are then applied to the base hypervectors of consecutive letters. This produces a character-level hypervector that captures both letter identity and positional order information, thereby avoiding confusion caused by different letter permutations. Compared with directly assigning an independent hypervector to each Chinese character, the proposed method reduces the storage requirement for base hypervectors by more than 95% (Table 1). Building on this character encoding method, the HDChinese framework is developed to support inference, training, and retraining. During inference, the sentence-level hypervector obtained by bundling all character hypervectors queries the class hypervectors using cosine similarity. Because the hypervectors are binary, the inner-product operation is efficiently implemented using XNOR logic. During training, class hypervectors are generated by bundling sentence hypervectors belonging to the same class and applying sign-based binarization. During retraining, the nonbinary class hypervectors are iteratively updated using misclassified samples with a learning rate of 0.25, thereby reducing the effect of outlier hypervectors on the cluster center. Furthermore, a dedicated hardware accelerator architecture is designed for HDChinese. The architecture comprises three main modules: an encoding module, a querying module, and a class hypervector update module. These modules can be selectively activated to support inference, training, and retraining modes, respectively (Fig. 2). The accelerator is prototyped on an Ultra96v2 FPGA development board equipped with a Xilinx ZYNQ System on Chip (SoC).  Results and Discussions  Four open-source Chinese text classification datasets covering binary and multiclass tasks are used for evaluation (Table 2). The Wubi-based encoding method achieves higher accuracy than the Pinyin-based method on all four datasets and reduces the storage requirement by 31.46% (Table 4). Ignoring uncommon Chinese characters, which occur at an average frequency of less than 0.5%, has a negligible effect on accuracy (Table 4). A hypervector dimension of 2 k is selected because increasing the dimension beyond 2 k provides no significant accuracy improvement (Fig. 3). FPGA measurements show that HDChinese achieves a model size of approximately 16 kB, representing a reduction of more than 99% compared with k-Nearest Neighbor (kNN), Support Vector Machine (SVM), and random forest models (Table 7). Compared with SVM and random forest, the proposed accelerator reduces inference time by 6.67%~47.25% and total training time by 4.91%~77.36%. After retraining, the classification accuracy reaches levels comparable to those of the comparison methods (Fig. 4, Table 7). The kB-scale model also enables operation without external memory chips, whereas the comparison methods require more than 400 MB of runtime memory. At 100 MHz, the FPGA implementation consumes 0.278 W, providing the most favorable trade-off between throughput and power consumption (Table 6).  Conclusions  A hyperdimensional encoding method based on Chinese character glyph structure is proposed to address the incompatibility between existing HDC methods and Chinese text. The HDChinese framework and its dedicated hardware accelerator reduce model complexity by more than 99% while maintaining competitive classification accuracy. Training time is reduced by 4.91%~77.36%, and inference time is reduced by 6.67%~47.25%. The proposed approach achieves a favorable balance between accuracy and computational and storage overhead, providing a hardware solution for Chinese text analysis on edge devices.
  • loading
  • [1]
    ZHAO Jinghua, SHU Xi, ZHAO Xiaohua, et al. Online opinion trend prediction for public health events based on time series transformer[J]. IEEE Transactions on Computational Social Systems, 2026, 13(1): 1159–1168. doi: 10.1109/TCSS.2025.3617491.
    [2]
    朱振方, 李嘉欣, 徐富永, 等. 一种融合情感和策略信息的共情对话生成方法[J]. 电子与信息学报, 2024, 46(8): 3382–3389. doi: 10.11999/JEIT231417.

    ZHU Zhenfang, LI Jiaxin, XU Fuyong, et al. Empathetic dialogue generation via sentiment and support strategy[J]. Journal of Electronics & Information Technology, 2024, 46(8): 3382–3389. doi: 10.11999/JEIT231417.
    [3]
    LIU Fengyu. Research on user dynamic preference modeling and recommendation system based on text sentiment transfer[C]. 2025 2nd International Conference on Intelligent Computing and Robotics (ICICR), Dalian, China, 2025: 1088–1092. doi: 10.1109/ICICR65456.2025.00192.
    [4]
    LIU Pengfei, QIU Xipeng, and HUANG Xuanjing. Recurrent neural network for text classification with multi-task learning[C]. The Twenty-Fifth International Joint Conference on Artificial Intelligence, New York, USA, 2016: 2873–2879.
    [5]
    ZHENG Yafeng, GAO Zhanghao, SHEN Jun, et al. Optimizing automatic text classification approach in adaptive online collaborative discussion-a perspective of attention mechanism-based bi-LSTM[J]. IEEE Transactions on Learning Technologies, 2023, 16(5): 591–602. doi: 10.1109/tlt.2022.3192116.
    [6]
    JIANG Ting, WANG Deqing, SUN Leilei, et al. LightXML: Transformer with dynamic negative sampling for high-performance extreme multi-label text classification[C]. The 35th AAAI Conference on Artificial Intelligence, 2021: 7987–7994. doi: 10.1609/aaai.v35i9.16974.
    [7]
    王泽昊, 朱振华, 谢童欣, 等. 混合专家大语言模型的系统与架构优化技术综述[J]. 电子与信息学报, 2025, 47(11): 4055–4078. doi: 10.11999/JEIT250407.

    WANG Zehao, ZHU Zhenhua, XIE Tongxin, et al. A survey on system and architecture optimization techniques for mixture-of-experts large language models[J]. Journal of Electronics & Information Technology, 2025, 47(11): 4055–4078. doi: 10.11999/JEIT250407.
    [8]
    刘文波, 姚翼荣, 张弓, 等. 超维计算概念、应用及研究进展[J]. 系统工程与电子技术, 2023, 45(7): 1938–1956. doi: 10.12305/j.issn.1001-506X.2023.07.04.

    LIU Wenbo, YAO Yirong, ZHANG Gong, et al. Concept, application, and research progress of hyperdimensional computing[J]. Systems Engineering and Electronics, 2023, 45(7): 1938–1956. doi: 10.12305/j.issn.1001-506X.2023.07.04.
    [9]
    余天洋, 吴比, 陈珂, 等. 超维计算硬件设计: 进展、趋势和展望[J]. 集成电路与嵌入式系统, 2025, 25(8): 1–9. doi: 10.20193/j.ices2097-4191.2025.0047.

    YU Tianyang, WU Bi, CHEN Ke, et al. Hyperdimensional computing hardware: Progress, trends and prospects[J]. Integrated Circuits and Embedded Systems, 2025, 25(8): 1–9. doi: 10.20193/j.ices2097-4191.2025.0047.
    [10]
    RAHIMI A, KANERVA P, and RABAEY J M. A robust and energy-efficient classifier using brain-inspired hyperdimensional computing[C]. The 2016 International Symposium on Low Power Electronics and Design, San Francisco Airport, USA, 2016: 64–69. doi: 10.1145/2934583.2934624.
    [11]
    THAPA R, LAMICHHANE B, MA Dongning, et al. SpamHD: Memory-efficient text spam detection using brain-inspired hyperdimensional computing[C]. 2021 IEEE Computer Society Annual Symposium on VLSI (ISVLSI), Tampa, USA, 2021: 84–89. doi: 10.1109/isvlsi51109.2021.00026.
    [12]
    ALONSO P, SHRIDHAR K, KLEYKO D, et al. HyperEmbed: Tradeoffs between resources and performance in NLP tasks with hyperdimensional computing enabled embedding of n-gram statistics[C]. 2021 International Joint Conference on Neural Networks (IJCNN), Shenzhen, China, 2021: 1–9. doi: 10.1109/IJCNN52387.2021.9534359.
    [13]
    PARK S, KIM K, SEO J, et al. Unsupervised extractive dialogue summarization in hyperdimensional space[C]. ICASSP 2024-2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Seoul, Korea, 2024: 12411–12415. doi: 10.1109/ICASSP48485.2024.10446698.
    [14]
    MIKOLOV T, CHEN Kai, CORRADO G, et al. Efficient estimation of word representations in vector space[C]. 1st International Conference on Learning Representations, Scottsdale, USA, 2013.
    [15]
    PENNINGTON J, SOCHER R, and MANNING C D. GloVe: Global vectors for word representation[C]. The 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), Doha, Qatar, 2014: 1532–1543. doi: 10.3115/v1/D14-1162.
    [16]
    DEVLIN J, CHANG Mingwei, LEE K, et al. BERT: Pre-training of deep bidirectional transformers for language understanding[C]. The 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (long and short papers), Minneapolis, USA, 2019: 4171–4186. doi: 10.18653/v1/N19-1423.
    [17]
    LIU Caizhi, SEHNG Yanxiu, WEI Zhiqiang, et al. Research of text classification based on improved TF-IDF algorithm[C]. IEEE International Conference of Intelligent Robotic and Control Engineering (IRCE), Lanzhou, China, 2018: 218–222. doi: 10.1109/IRCE.2018.8492945.
    [18]
    YU Tianyang, WU Bi, CHEN Ke, et al. Fully learnable hyperdimensional computing framework with ultratiny accelerator for edge-side applications[J]. IEEE Transactions on Computers, 2024, 73(2): 574–585. doi: 10.1109/tc.2023.3337316.
    [19]
    GE Lulu and PARHI K K. Classification using hyperdimensional computing: A review[J]. IEEE Circuits and Systems Magazine, 2020, 20(2): 30–47. doi: 10.1109/mcas.2020.2988388.
    [20]
    GORBAN A N and TYUKIN I Y. Blessing of dimensionality: Mathematical foundations of the statistical physics of data[J]. Philosophical Transactions of the Royal Society A: Mathematical, Physical and Engineering Sciences, 2018, 376(2118): 20170237. doi: 10.1098/rsta.2017.0237.
    [21]
    SHIN S H, YOO Y, MOON Y, et al. STAR-PIM: Self-test and repair structure for processing-in-memory with adder tree-based MAC[J]. IEEE Transactions on Circuits and Systems I: Regular Papers, 2026, 73(3): 1990–2003. doi: 10.1109/tcsi.2025.3615631.
    [22]
    LI Jun, ZHANG Cheng, and JIANG Lanlan. Innovative telecom fraud detection: A new dataset and an advanced model with RoBERTa and dual loss functions[J]. Applied Sciences, 2024, 14(24): 11628. doi: 10.3390/app142411628.
    [23]
    王杰, 王鹃. 面向RISC-V平台的安全高效固件可信平台模块设计与实现[J]. 电子与信息学报, 2025, 47(7): 2385–2395. doi: 10.11999/JEIT241112.

    WANG Jie and WANG Juan. The design and implementation of a secure and efficient firmware trusted platform module for RISC-V platforms[J]. Journal of Electronics & Information Technology, 2025, 47(7): 2385–2395. doi: 10.11999/JEIT241112.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(4)  / Tables(7)

    Article Metrics

    Article views (436) PDF downloads(33) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return