Advanced Search
Turn off MathJax
Article Contents
HU Tianwei, ZHANG Xiangrui, CHEN Jian, DUAN Haodong, JIA Jie. A Structure-preserving Semantic Transmission Method for Low-bandwidth Networks[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260525
Citation: HU Tianwei, ZHANG Xiangrui, CHEN Jian, DUAN Haodong, JIA Jie. A Structure-preserving Semantic Transmission Method for Low-bandwidth Networks[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260525

A Structure-preserving Semantic Transmission Method for Low-bandwidth Networks

doi: 10.11999/JEIT260525 cstr: 32379.14.JEIT260525
Funds:  The National Natural Science Foundation of China (62132004, 62572109)
  • Received Date: 2026-04-28
  • Accepted Date: 2026-08-17
  • Rev Recd Date: 2026-08-14
  • Available Online: 2026-08-25
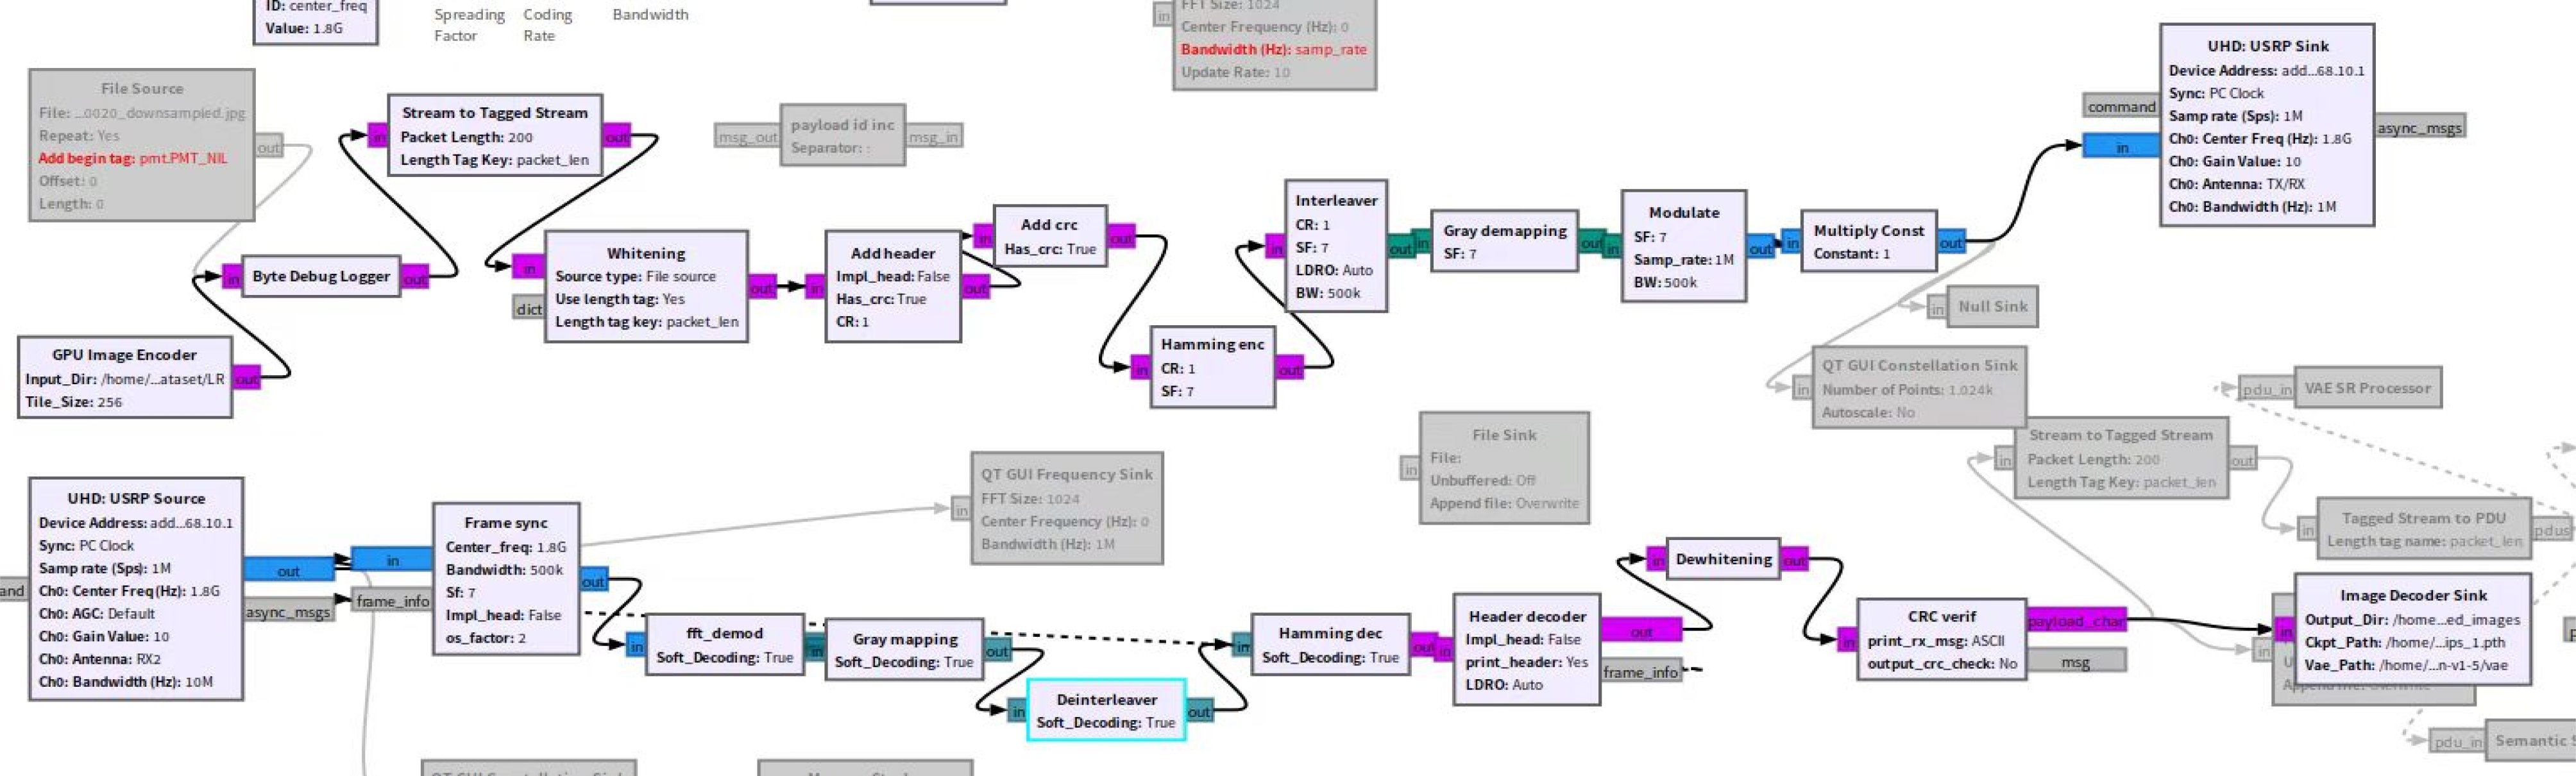
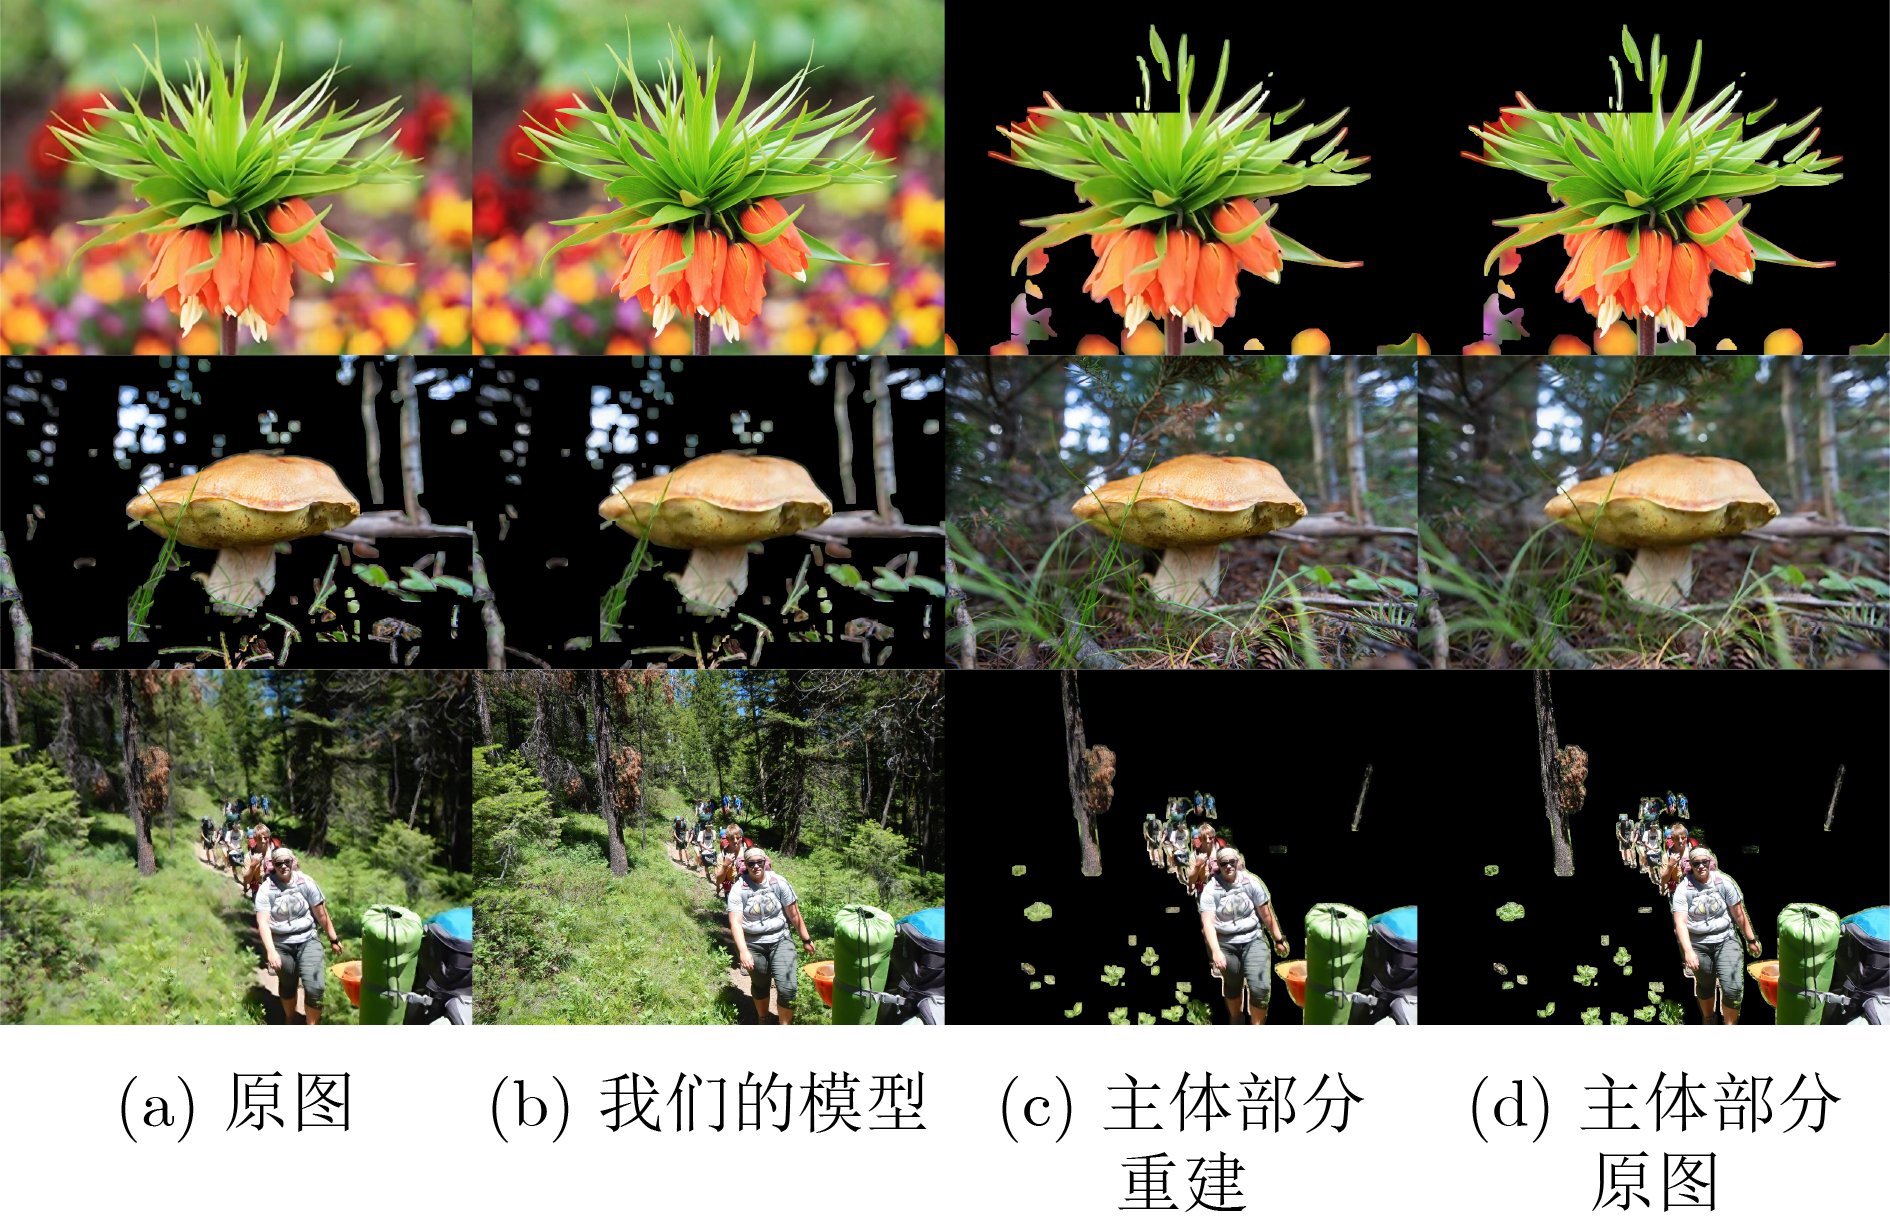
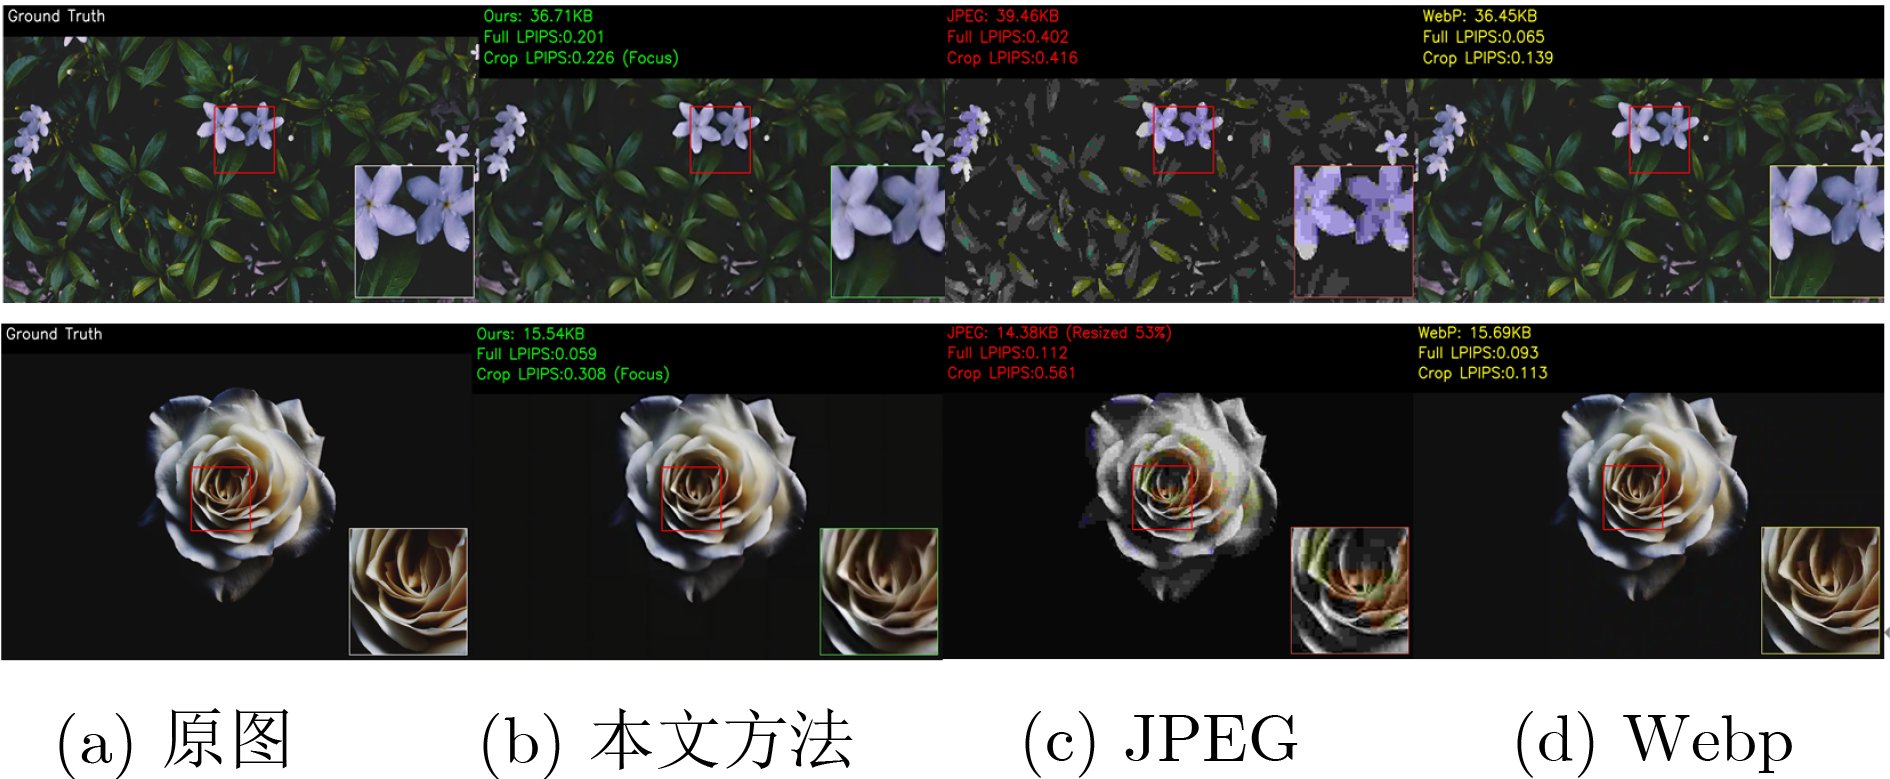
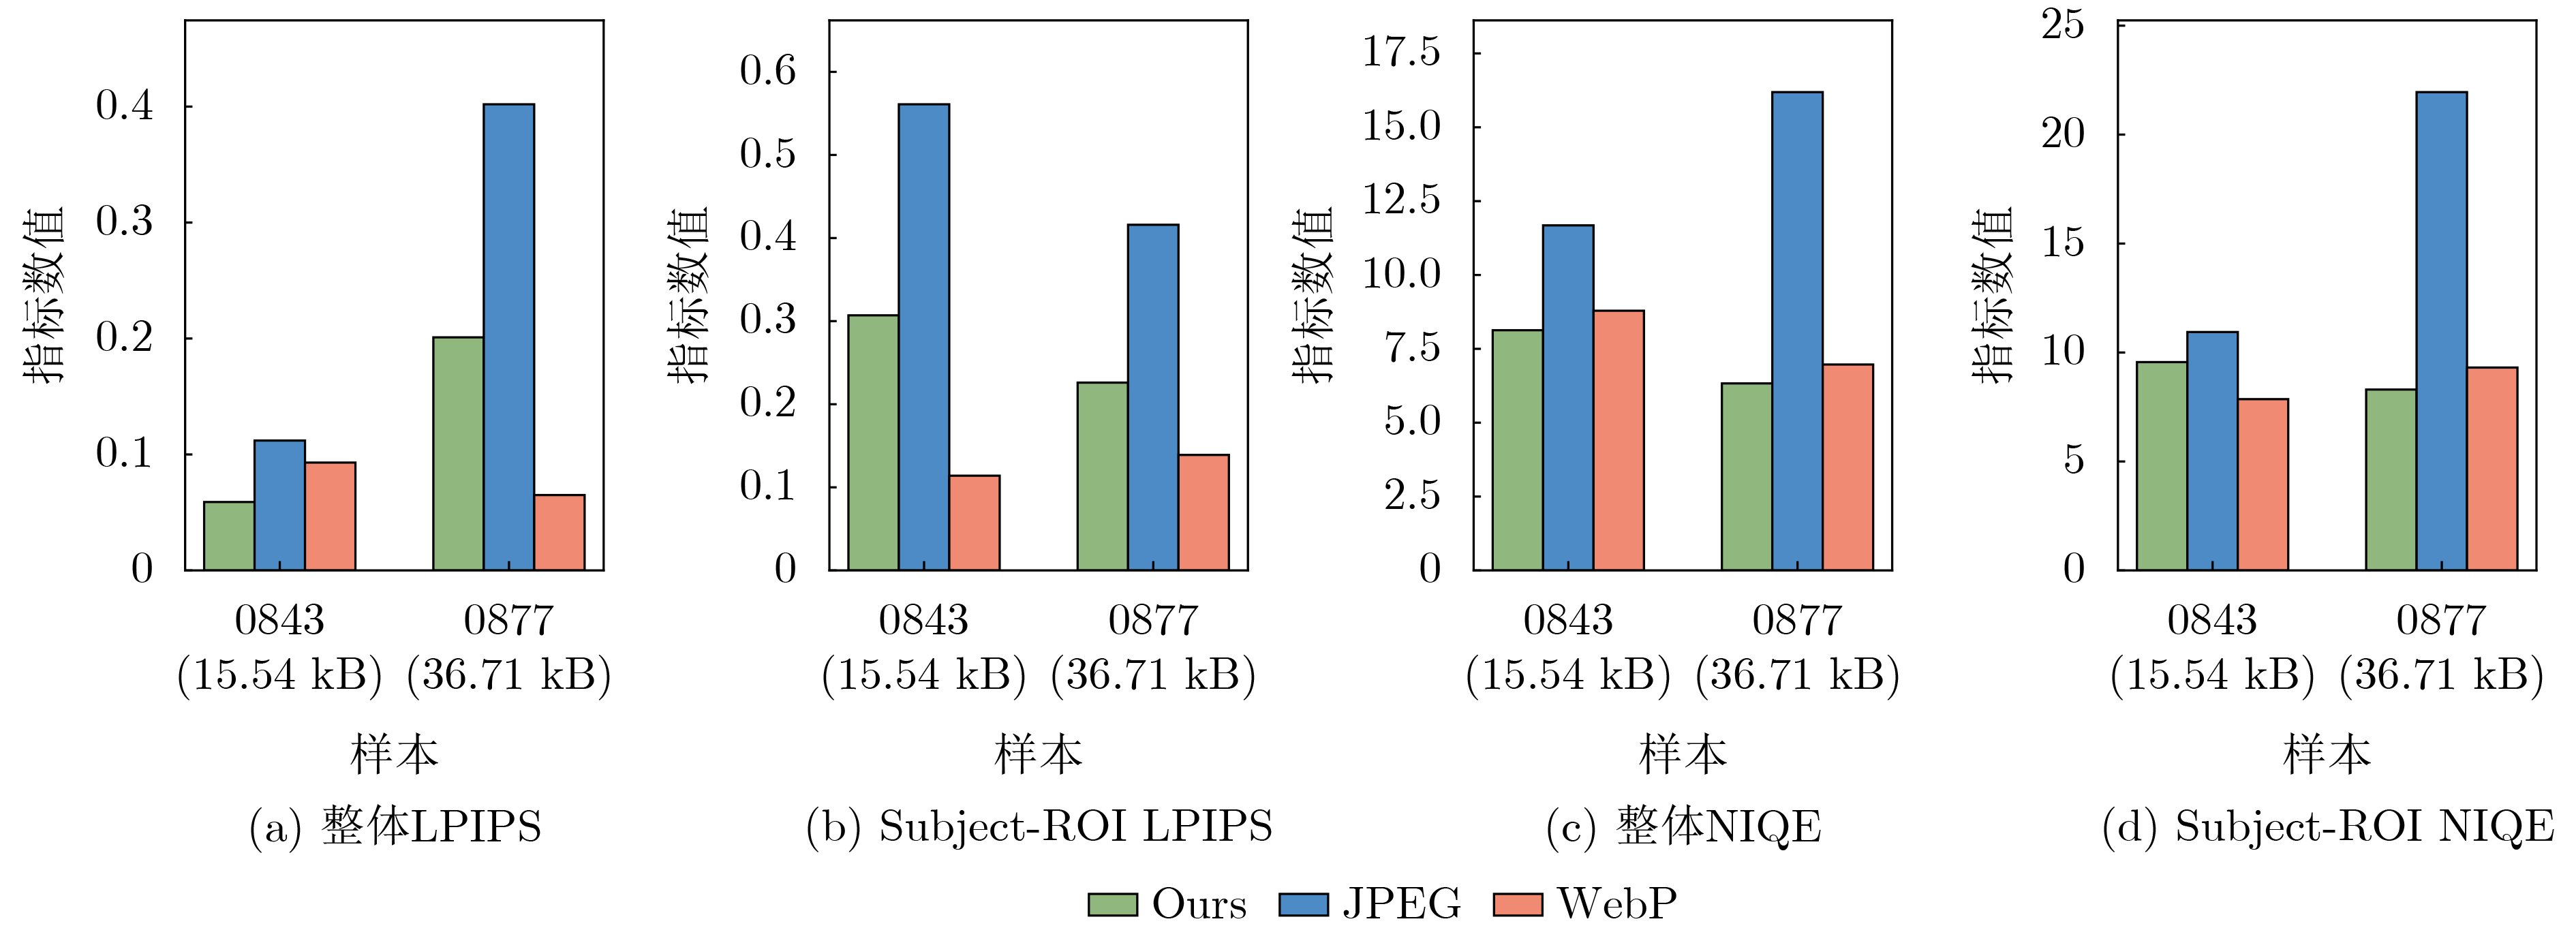
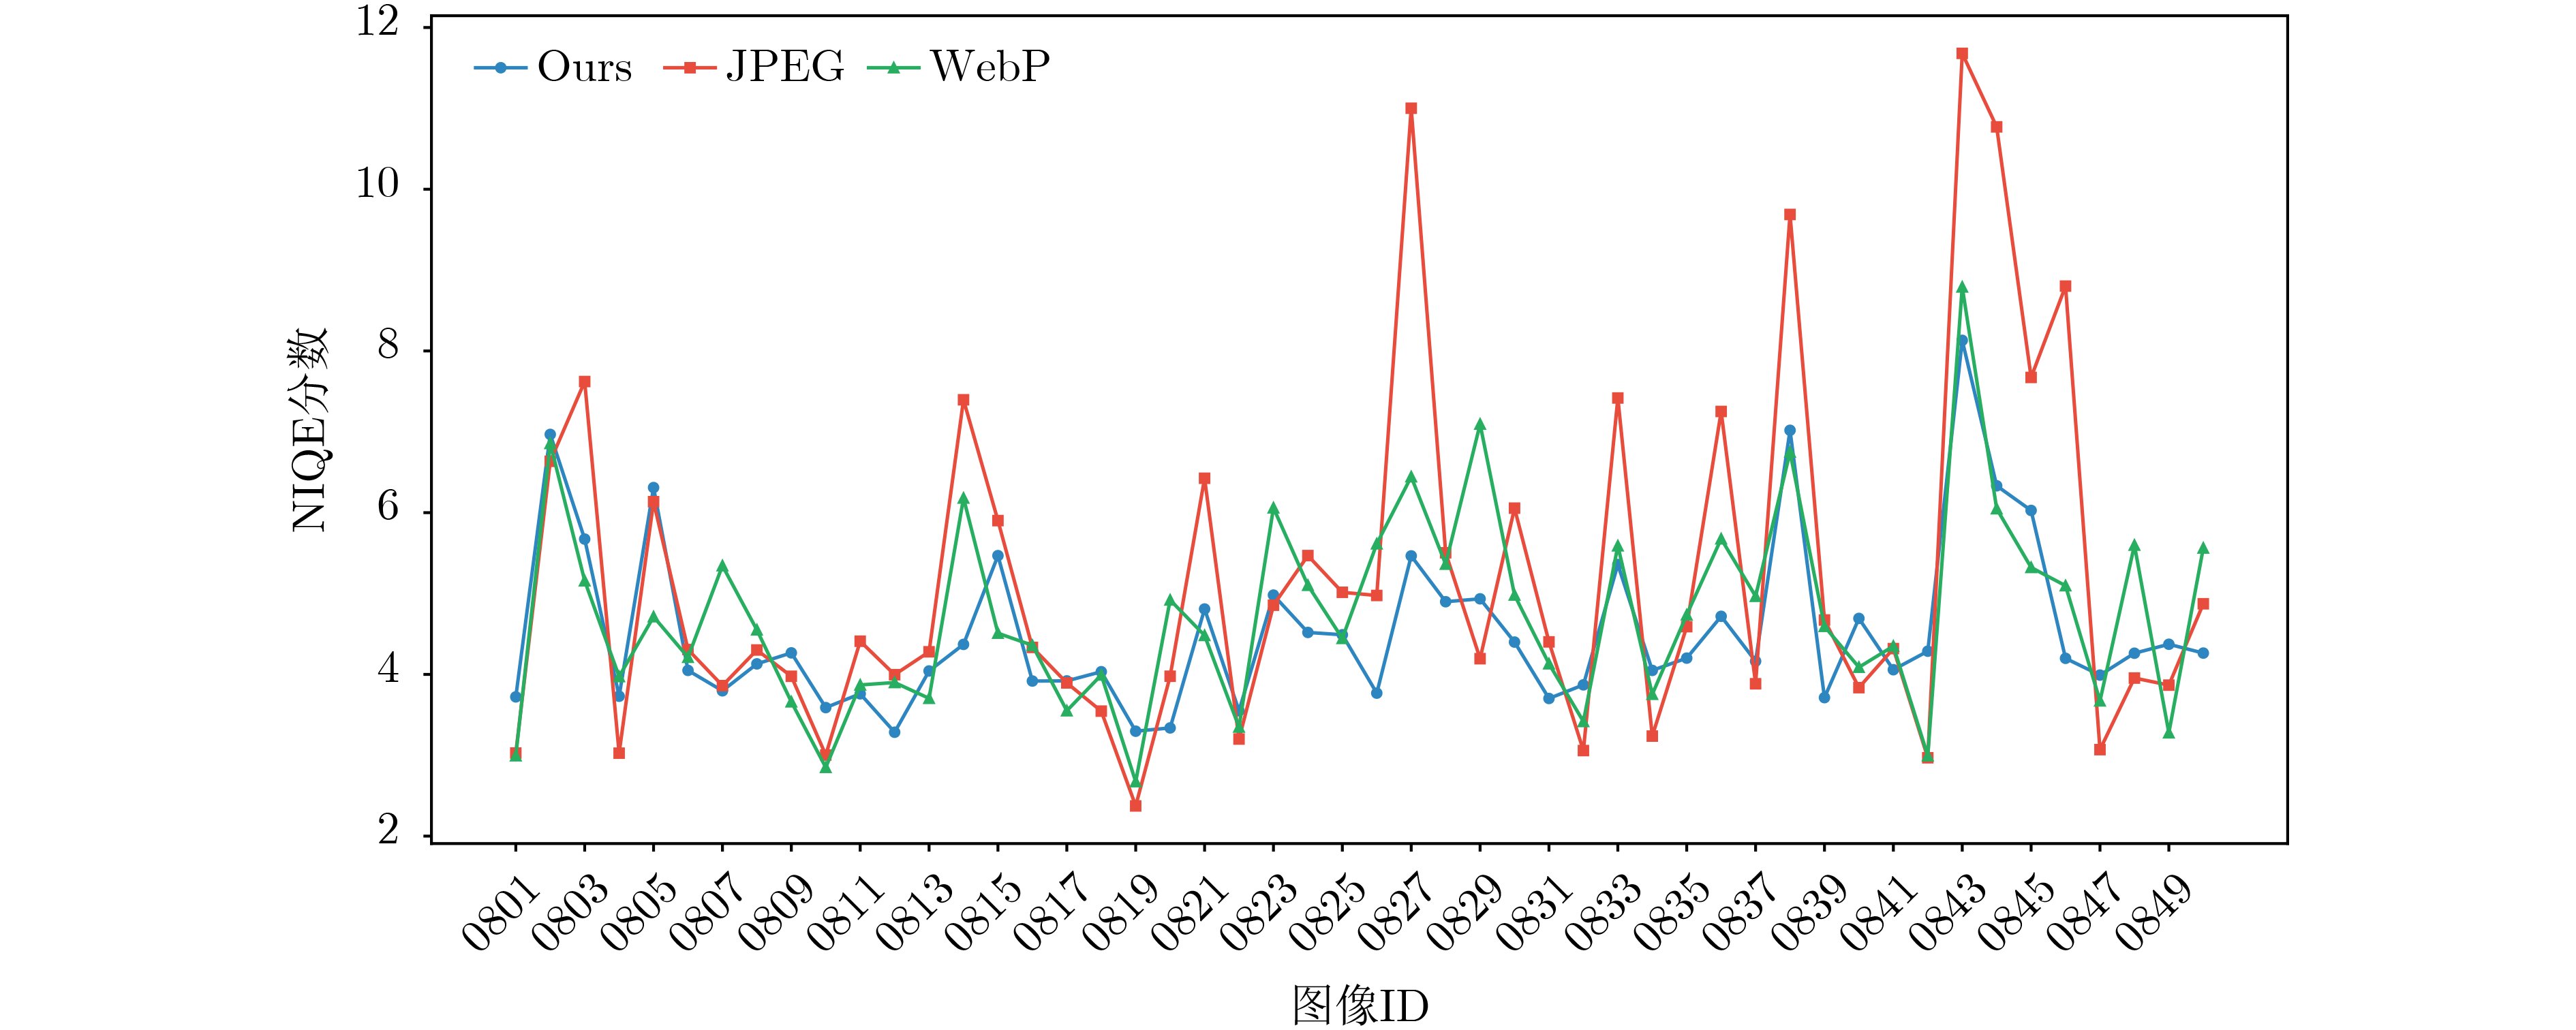
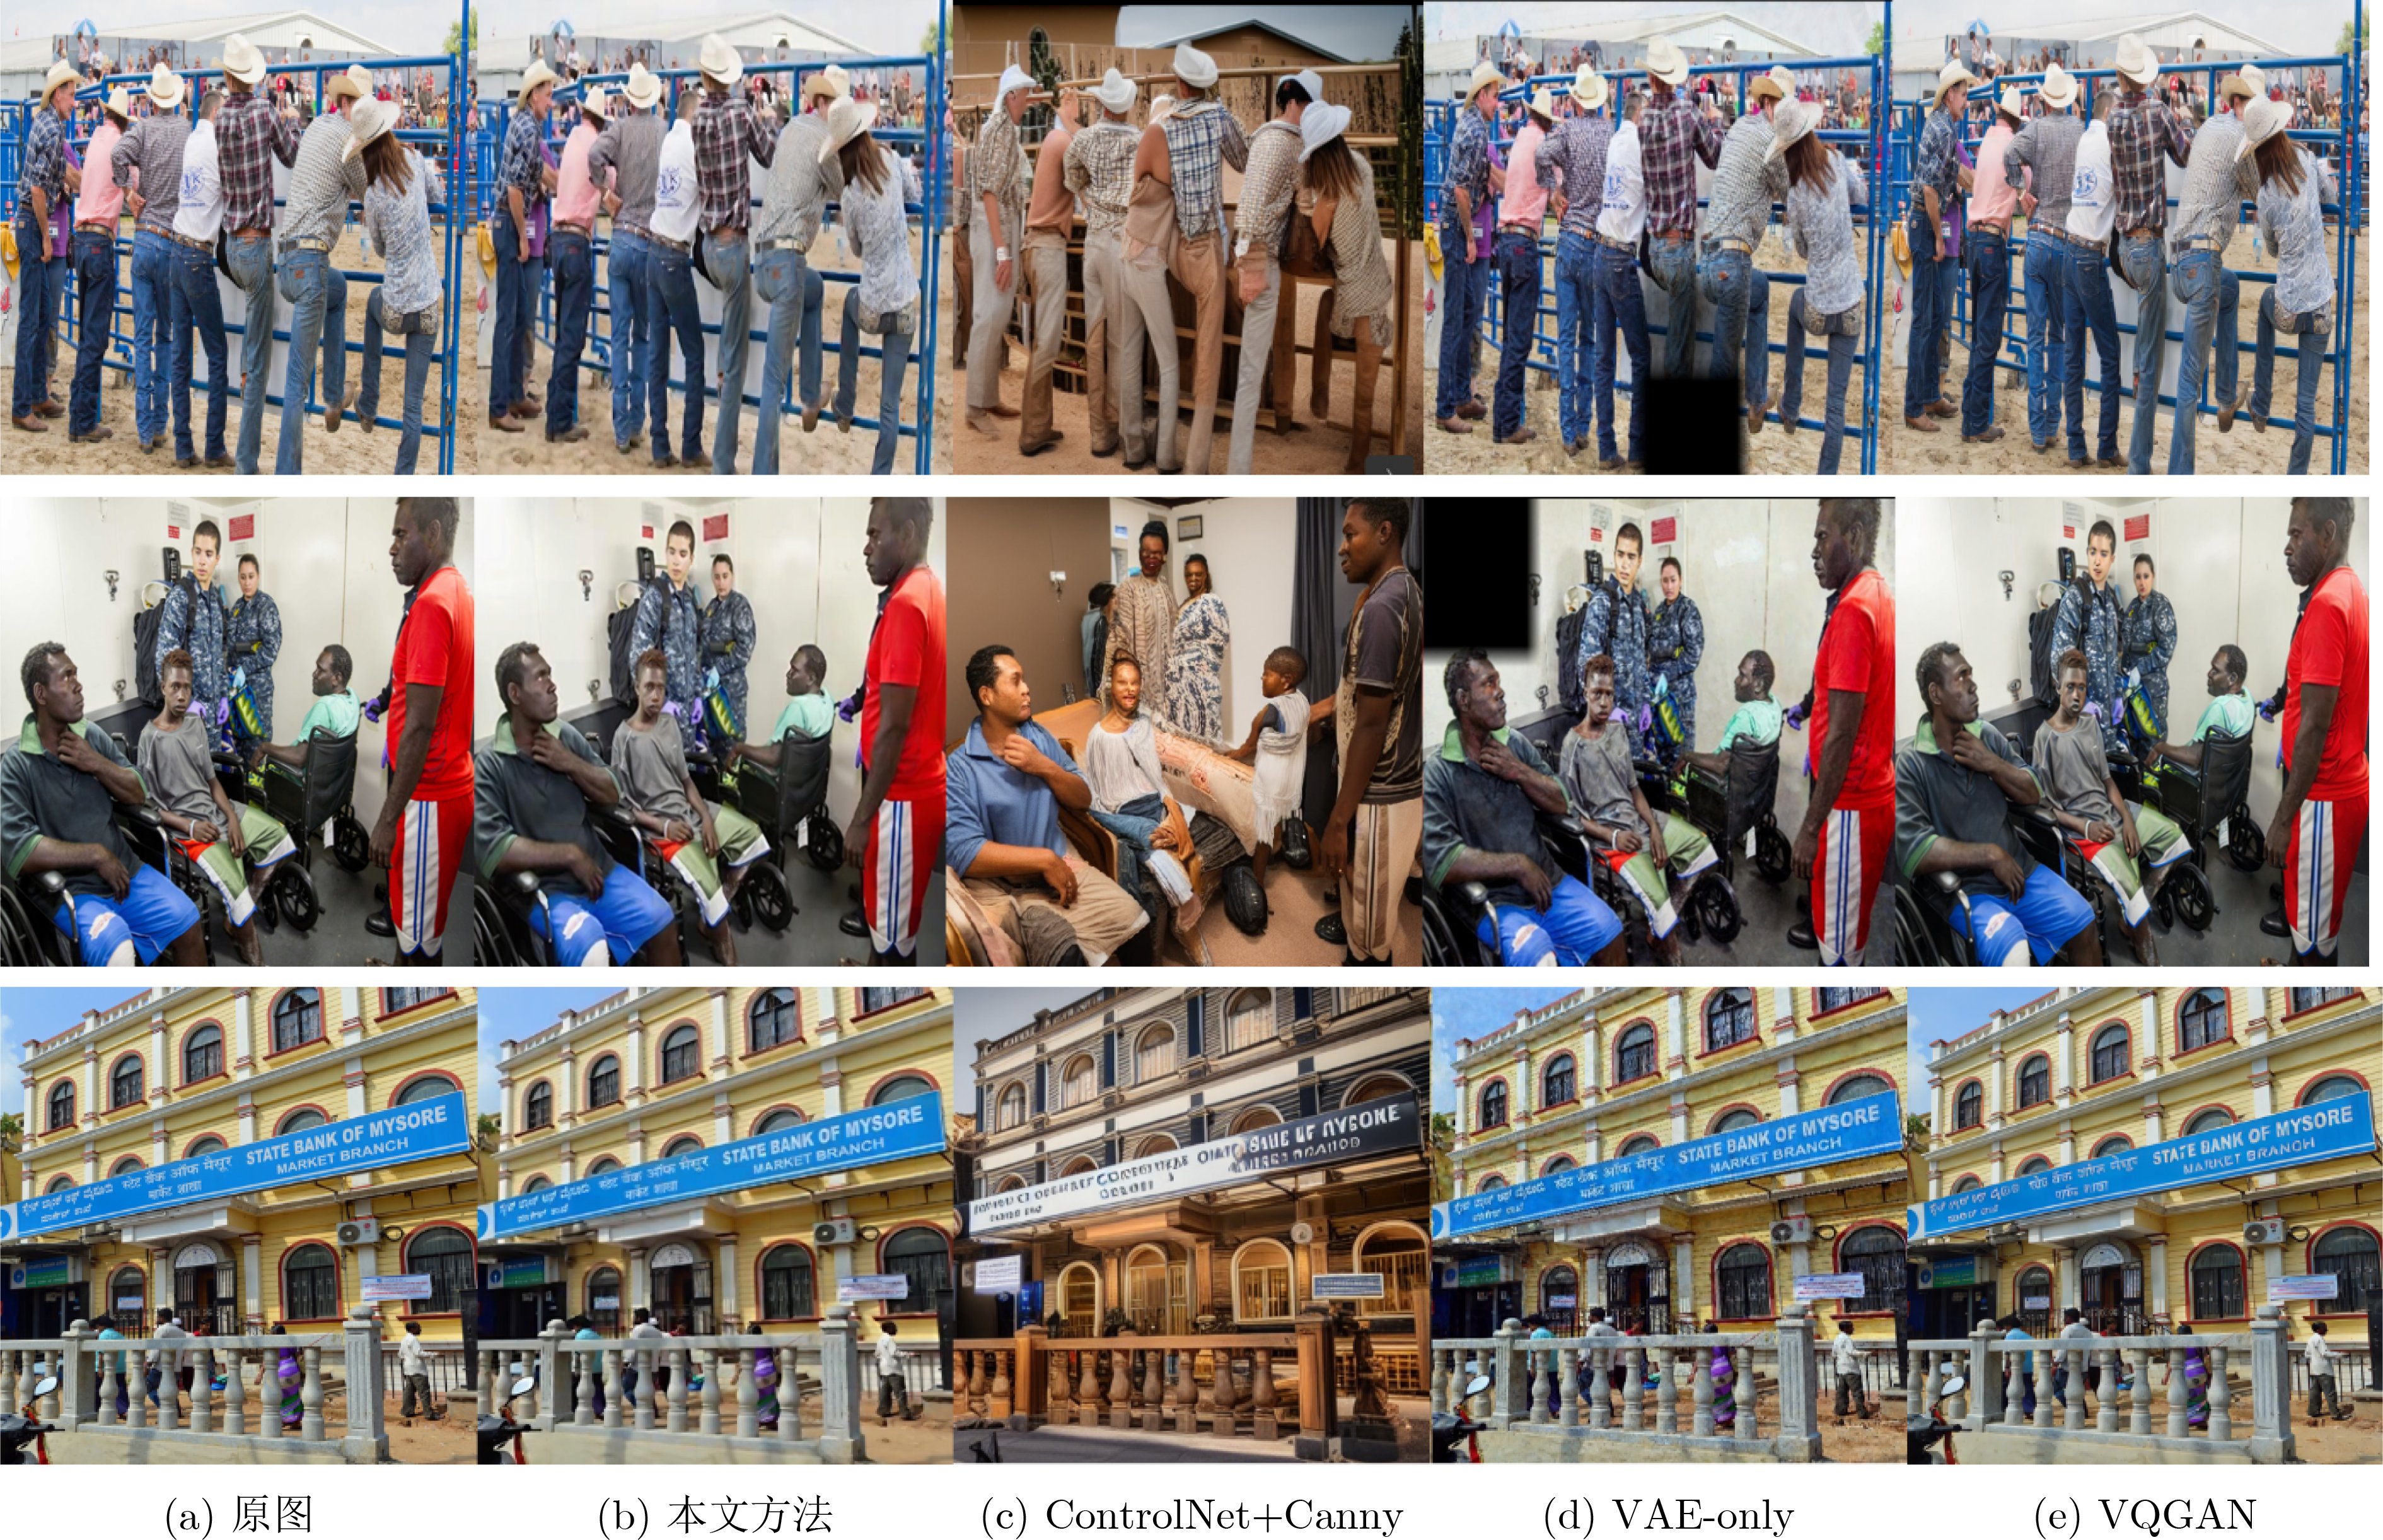
  •   Objective  Low-bandwidth visual transmission is essential for edge intelligence applications such as disaster inspection, underwater exploration, and remote assistance. These scenarios require visual communication systems to provide a low bit rate, high structural fidelity, stable color reconstruction, and low inference latency. However, conventional image coding methods suffer severe quality degradation at extremely low bit rates because of the digital cliff effect and compression artifacts. Semantic communication offers a promising solution by transmitting task-relevant representations rather than pixel-level information. However, existing methods still struggle to balance transmission efficiency, reconstruction fidelity, and decoding complexity. Therefore, a structure-preserving semantic transmission method termed Edge-Link is proposed for low-bandwidth networks.  Methods  Edge-Link adopts a multimodal decoupled representation framework that separates image information into three complementary streams: a semantic stream, a structural stream, and a low-frequency appearance stream. The semantic stream is extracted using a frozen Contrastive Language-Image Pre-training (CLIP) encoder to provide global semantic guidance. The structural stream is derived from Canny edge information to explicitly preserve object boundaries. A low-resolution color map is used as the low-frequency appearance stream to preserve the global color distribution and illumination characteristics with minimal transmission overhead. Furthermore, a Fast Segment Anything Model (FastSAM)-based semantic gateway is used to distinguish foreground objects from background regions. An object-aware bit-rate allocation strategy is then applied to prioritize semantically important regions under bandwidth constraints. At the receiver, a deterministic dual-stream generative network based on SPatially ADaptive normalization (SPADE) is used for image reconstruction. Structural information provides spatial constraints, whereas semantic features guide image generation. This design avoids the high latency associated with iterative diffusion sampling. A LoRa communication prototype based on GNU Radio and a Universal Software Radio Peripheral (USRP) is also implemented to evaluate transmission feasibility and robustness under physical wireless-channel conditions.  Results and Discussions  Experiments are conducted on Set14 and DIV2K to evaluate transmission efficiency, reconstruction quality, perceptual naturalness, and latency. For 512 × 512 images, the proposed method achieves an average payload of 10.96 kB, corresponding to approximately 0.31 bit per pixel (bpp), and the end-to-end inference latency remains below 60 ms. Over a LoRa narrowband link of approximately 8 kbps, the airtime latency per frame is approximately 11 s, confirming the feasibility of the method under bandwidth-limited conditions (Table 1). The ablation study shows that the object-aware bit-rate allocation strategy improves the trade-off between bit rate and reconstruction quality. On DIV2K, the average payload is reduced from 126.09 kB to 93.55 kB while better reconstruction quality is maintained in semantically important regions (Table 2). Compared with JPEG, the proposed method also provides better structure preservation and perceptual quality at low bit rates. For image 0843 with a payload of 15.54 kB, the overall Structural Similarity Index Measure (SSIM) increases from 0.783 to 0.963, whereas the Learned Perceptual Image Patch Similarity (LPIPS) for the subject region of interest (Subject-ROI) decreases from 0.561 to 0.307 (Table 4). Under the same bit-rate constraint, the proposed method further outperforms VQGAN and ControlNet+Canny. It achieves a Peak Signal-to-Noise Ratio (PSNR) of 23.738 dB, an SSIM of 0.622, an LPIPS of 0.223, and a Natural Image Quality Evaluator (NIQE) value of 4.570. These results indicate a better balance between reconstruction fidelity and perceptual quality in low-bandwidth semantic image reconstruction (Table 5).  Conclusions  A structure-preserving semantic transmission framework for low-bandwidth networks is presented. By combining multimodal decoupled representation, object-aware bit-rate allocation, and deterministic dual-stream generative reconstruction, the framework balances transmission efficiency, structural fidelity, perceptual quality, and inference latency. The results show that the proposed method is suitable for high-reliability edge visual communication scenarios that require accurate object contours, stable color appearance, and efficient inference. Validation using the LoRa prototype further supports its practical applicability to bandwidth-constrained edge networks.
  • loading
  • [1]
    JERNBERG C, SANDIN J, ZIEMKE T, et al. The effect of latency, speed and task on remote operation of vehicles[J]. Transportation Research Interdisciplinary Perspectives, 2024, 26: 101152. doi: 10.1016/j.trip.2024.101152.
    [2]
    BOURTSOULATZE E, KURKA D B, and GÜNDÜZ D. Deep joint source-channel coding for wireless image transmission[J]. IEEE Transactions on Cognitive Communications and Networking, 2019, 5(3): 567–579. doi: 10.1109/TCCN.2019.2919300.
    [3]
    DONG Chao, DENG Yubin, LOY C C, et al. Compression artifacts reduction by a deep convolutional network[C]. The 2015 IEEE International Conference on Computer Vision (ICCV), Santiago, Chile, 2015: 576–584. doi: 10.1109/ICCV.2015.73.
    [4]
    LIU Yating, WANG Xiaojie, NING Zhaolong, et al. A survey on semantic communications: Technologies, solutions, applications and challenges[J]. Digital Communications and Networks, 2024, 10(3): 528–545. doi: 10.1016/j.dcan.2023.05.010.
    [5]
    CHAI Jingxuan, XIAO Yong, and SHI Guangming. On the rate-distortion-complexity tradeoff for semantic communication[J]. IEEE Internet of Things Journal, 2026, 13(14): 31768–31781. doi: 10.1109/JIOT.2026.3689652.
    [6]
    陈阳, 马欢, 姬智, 等. 面向图像恢复任务的语义通信网络能耗优化[J]. 电子与信息学报, 2026, 48(1): 183–190. doi: 10.11999/JEIT250915.

    CHEN Yang, MA Huan, JI Zhi, et al. Optimization of energy consumption in semantic communication networks for image recovery tasks[J]. Journal of Electronics & Information Technology, 2026, 48(1): 183–190. doi: 10.11999/JEIT250915.
    [7]
    AITHAL S K, MAINI P, LIPTON Z, et al. Understanding hallucinations in diffusion models through mode interpolation[C]. The 38th International Conference on Neural Information Processing Systems, Vancouver, Canada, 2024: 134614–134644. doi: 10.52202/079017-4278.
    [8]
    JIA Zhaoyang, LI Jiahao, LI Bin, et al. Generative latent coding for ultra-low bitrate image compression[C]. The 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, USA, 2024: 26088–26098. doi: 10.1109/CVPR52733.2024.02465.
    [9]
    PEZONE F, MUSA O, CAIRE G, et al. Semantic-preserving image coding based on conditional diffusion models[C]. ICASSP 2024–2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Seoul, Korea, 2024: 13501–13505. doi: 10.1109/ICASSP48485.2024.10447279.
    [10]
    ZHANG Chaoning, CHO J, PUSPITASARI F D, et al. A survey on Segment Anything Model (SAM): Vision foundation model meets prompt engineering[EB/OL]. arXiv preprint arXiv: 2306.06211. https://arxiv.org/abs/2306.06211, 2023.
    [11]
    KINGMA D P and WELLING M. Auto-encoding variational Bayes[EB/OL]. arXiv preprint arXiv: 1312.6114. https://arxiv.org/abs/1312.6114, 2013.
    [12]
    BURGESS C P, HIGGINS I, PAL A, et al. Understanding disentangling in β-VAE[EB/OL]. arXiv preprint arXiv: 1804.03599. https://arxiv.org/abs/1804.03599?context=cs.LG#1, 2018.
    [13]
    罗一畅, 齐析屿, 张博锐, 等. 分割一切模型的轻量化研究综述[J]. 电子与信息学报, 2026, 48(2): 713–731. doi: 10.11999/JEIT250894.

    LUO Yichang, QI Xiyu, ZHANG Borui, et al. A survey of lightweight techniques for segment anything model[J]. Journal of Electronics & Information Technology, 2026, 48(2): 713–731. doi: 10.11999/JEIT250894.
    [14]
    TAPPAREL J, AFISIADIS O, MAYORAZ P, et al. An open-source LoRa physical layer prototype on GNU radio[C]. The 2020 IEEE 21st International Workshop on Signal Processing Advances in Wireless Communications (SPAWC), Atlanta, USA, 2020: 1–5. doi: 10.1109/SPAWC48557.2020.9154273.
    [15]
    SUN Xiaorui, LIU Jun, SHEN Hengtao, et al. On efficient variants of Segment Anything Model: A survey[J]. International Journal of Computer Vision, 2025, 133(10): 7406–7436. doi: 10.1007/s11263-025-02539-8.
    [16]
    RADFORD A, KIM J W, HALLACY C, et al. Learning transferable visual models from natural language supervision[C]. The 38th International Conference on Machine Learning, 2021: 8748–8763.
    [17]
    PARK T, LIU Mingyu, WANG Tingchun, et al. Semantic image synthesis with spatially-adaptive normalization[C]. The 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, USA, 2019: 2332–2341. doi: 10.1109/CVPR.2019.00244.
    [18]
    BLAU Y and MICHAELI T. The perception-distortion tradeoff[C]. The 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, USA, 2018: 6228–6237. doi: 10.1109/CVPR.2018.00652.
    [19]
    JIANG Wei, ZHAI Yongqi, LI Hangyu, et al. Learned image compression with ROI-weighted distortion and bit allocation[EB/OL]. CoRR. https://arxiv.org/html/2401.08154v2, 2024.
    [20]
    MAO Qi, YANG Tinghan, ZHANG Yinuo, et al. Extreme image compression using fine-tuned VQGANs[C]. The 2024 Data Compression Conference (DCC), Snowbird, USA, 2024: 203–212. doi: 10.1109/DCC58796.2024.00028.
    [21]
    CHEN Weilong, XU Wenxuan, CHEN Haoran, et al. Semantic communication based on large language model for underwater image transmission[J]. IEEE Transactions on Mobile Computing, 2026, 25(2): 2060–2075. doi: 10.1109/TMC.2025.3607717.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(10)  / Tables(7)

    Article Metrics

    Article views (344) PDF downloads(18) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return