Advanced Search
Turn off MathJax
Article Contents
WU Yanjun, LIU Zhangyuhang, YANG Wenxin, YAN Mubiao, ZHOU Hao, ZHAO Yajun, XIE Zhuochen, LIANG Xuwen. Design of a Channel-Adaptive Denoiser for Digital Semantic Communications[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260523
Citation: WU Yanjun, LIU Zhangyuhang, YANG Wenxin, YAN Mubiao, ZHOU Hao, ZHAO Yajun, XIE Zhuochen, LIANG Xuwen. Design of a Channel-Adaptive Denoiser for Digital Semantic Communications[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260523

Design of a Channel-Adaptive Denoiser for Digital Semantic Communications

doi: 10.11999/JEIT260523 cstr: 32379.14.JEIT260523
Funds:  The National Key Research and Development Program of China(2025YFF0522600)
  • Received Date: 2026-04-27
  • Accepted Date: 2026-08-10
  • Rev Recd Date: 2026-08-10
  • Available Online: 2026-08-20
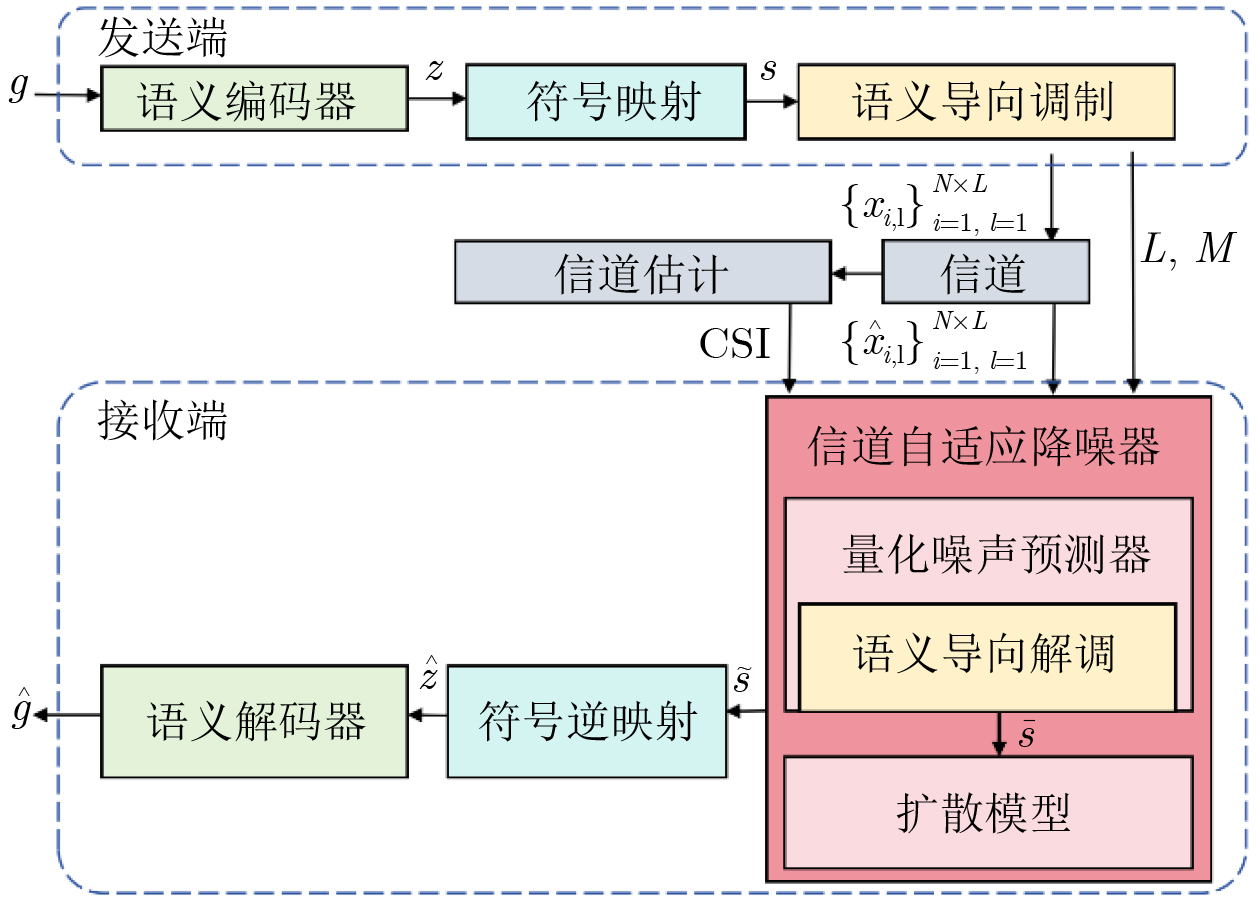
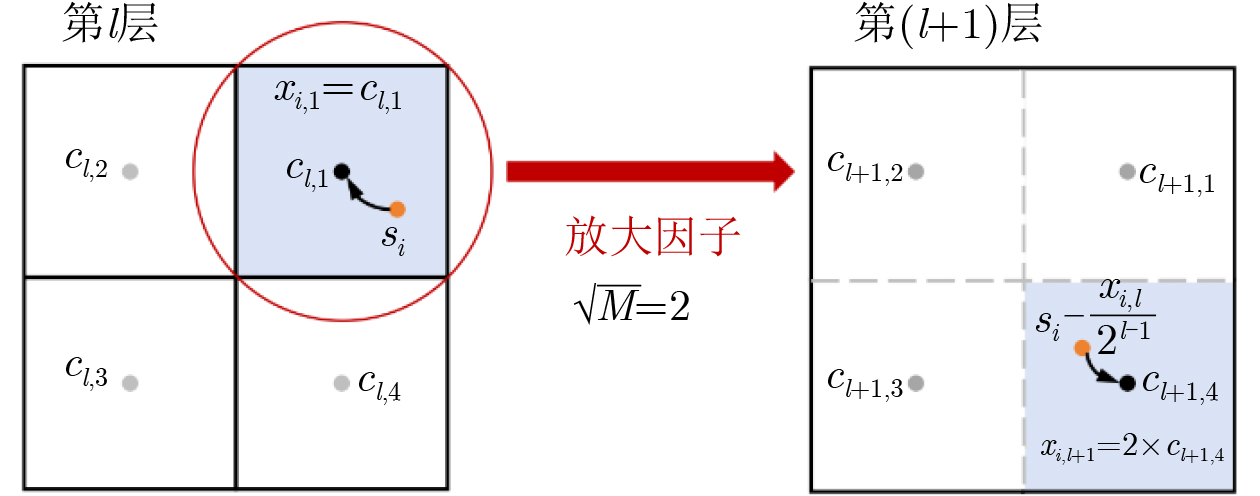
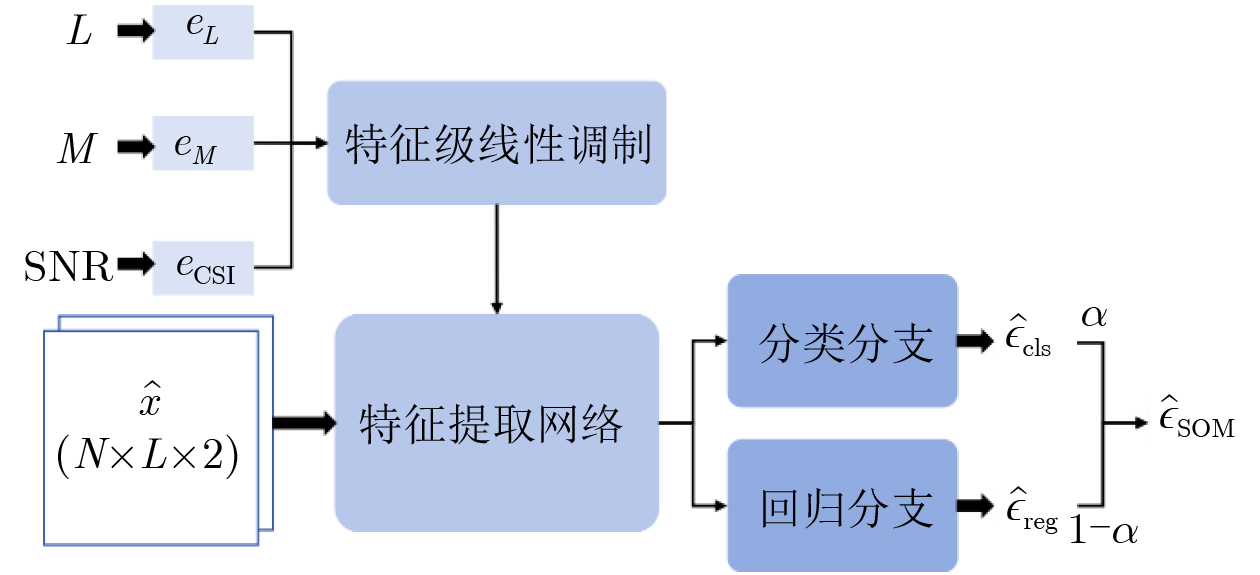
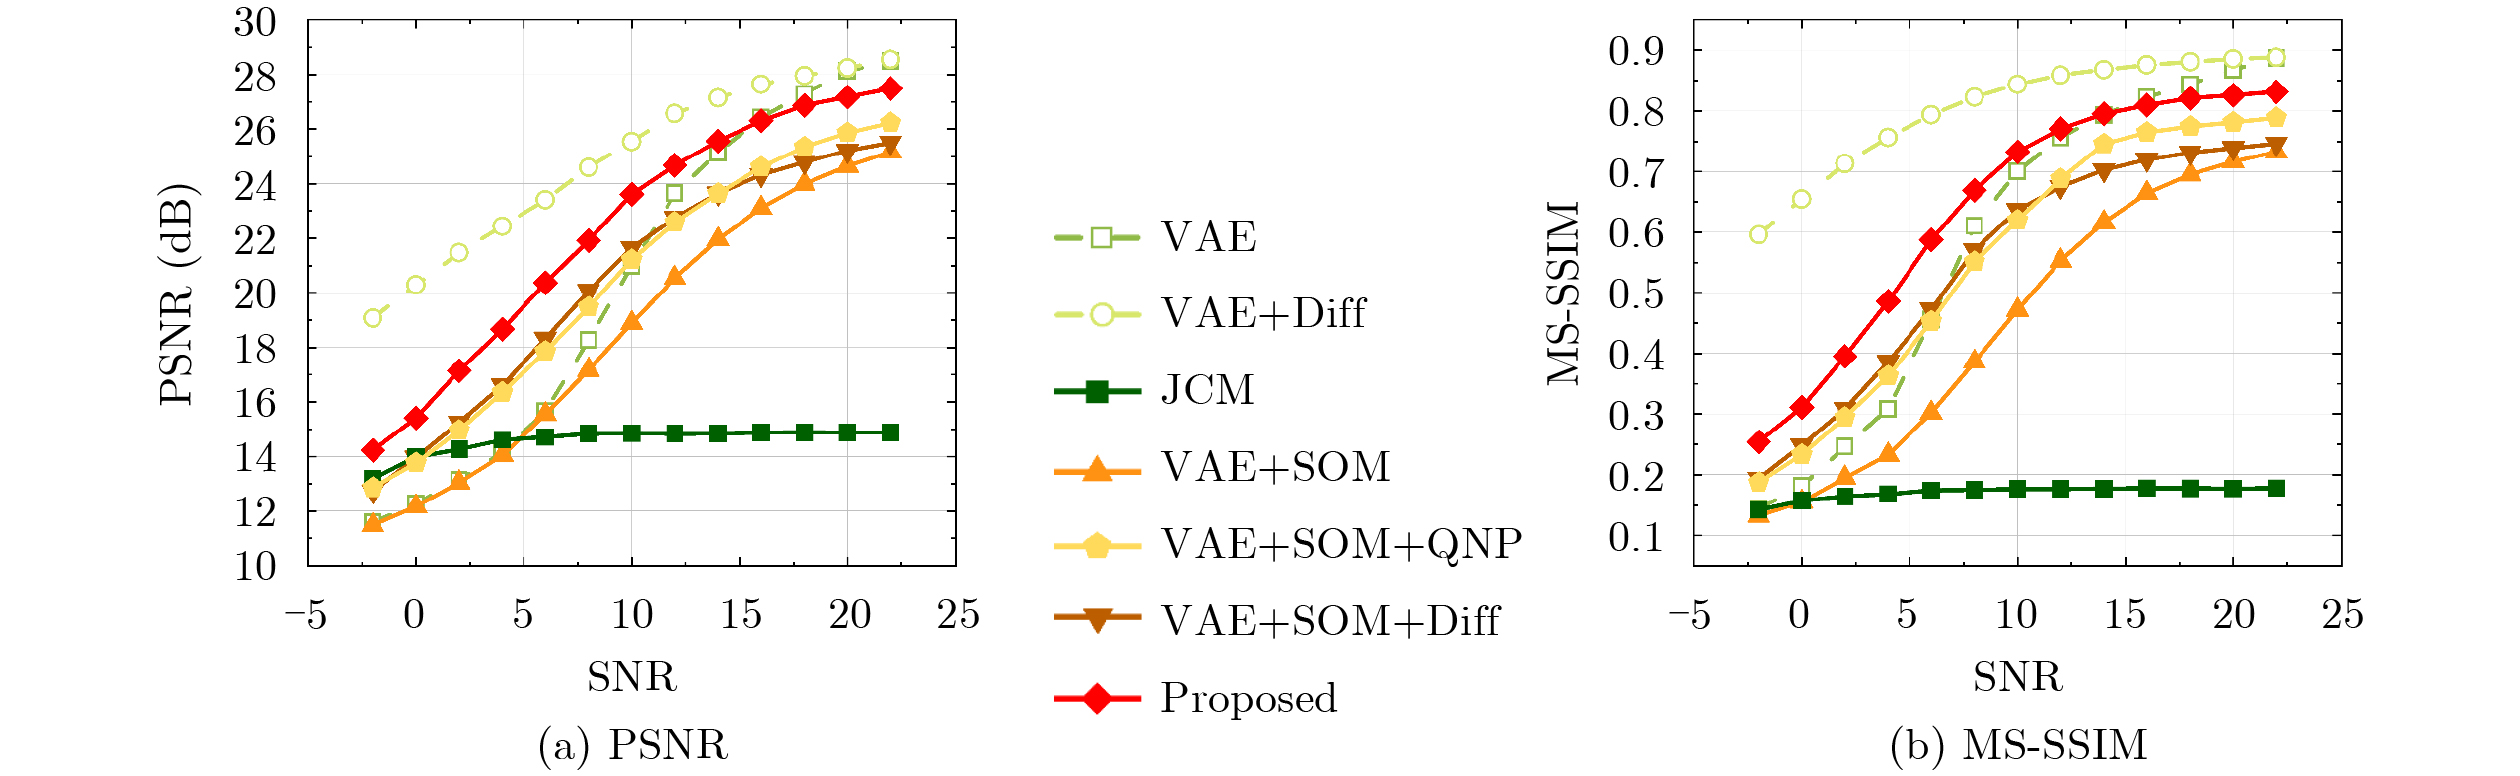
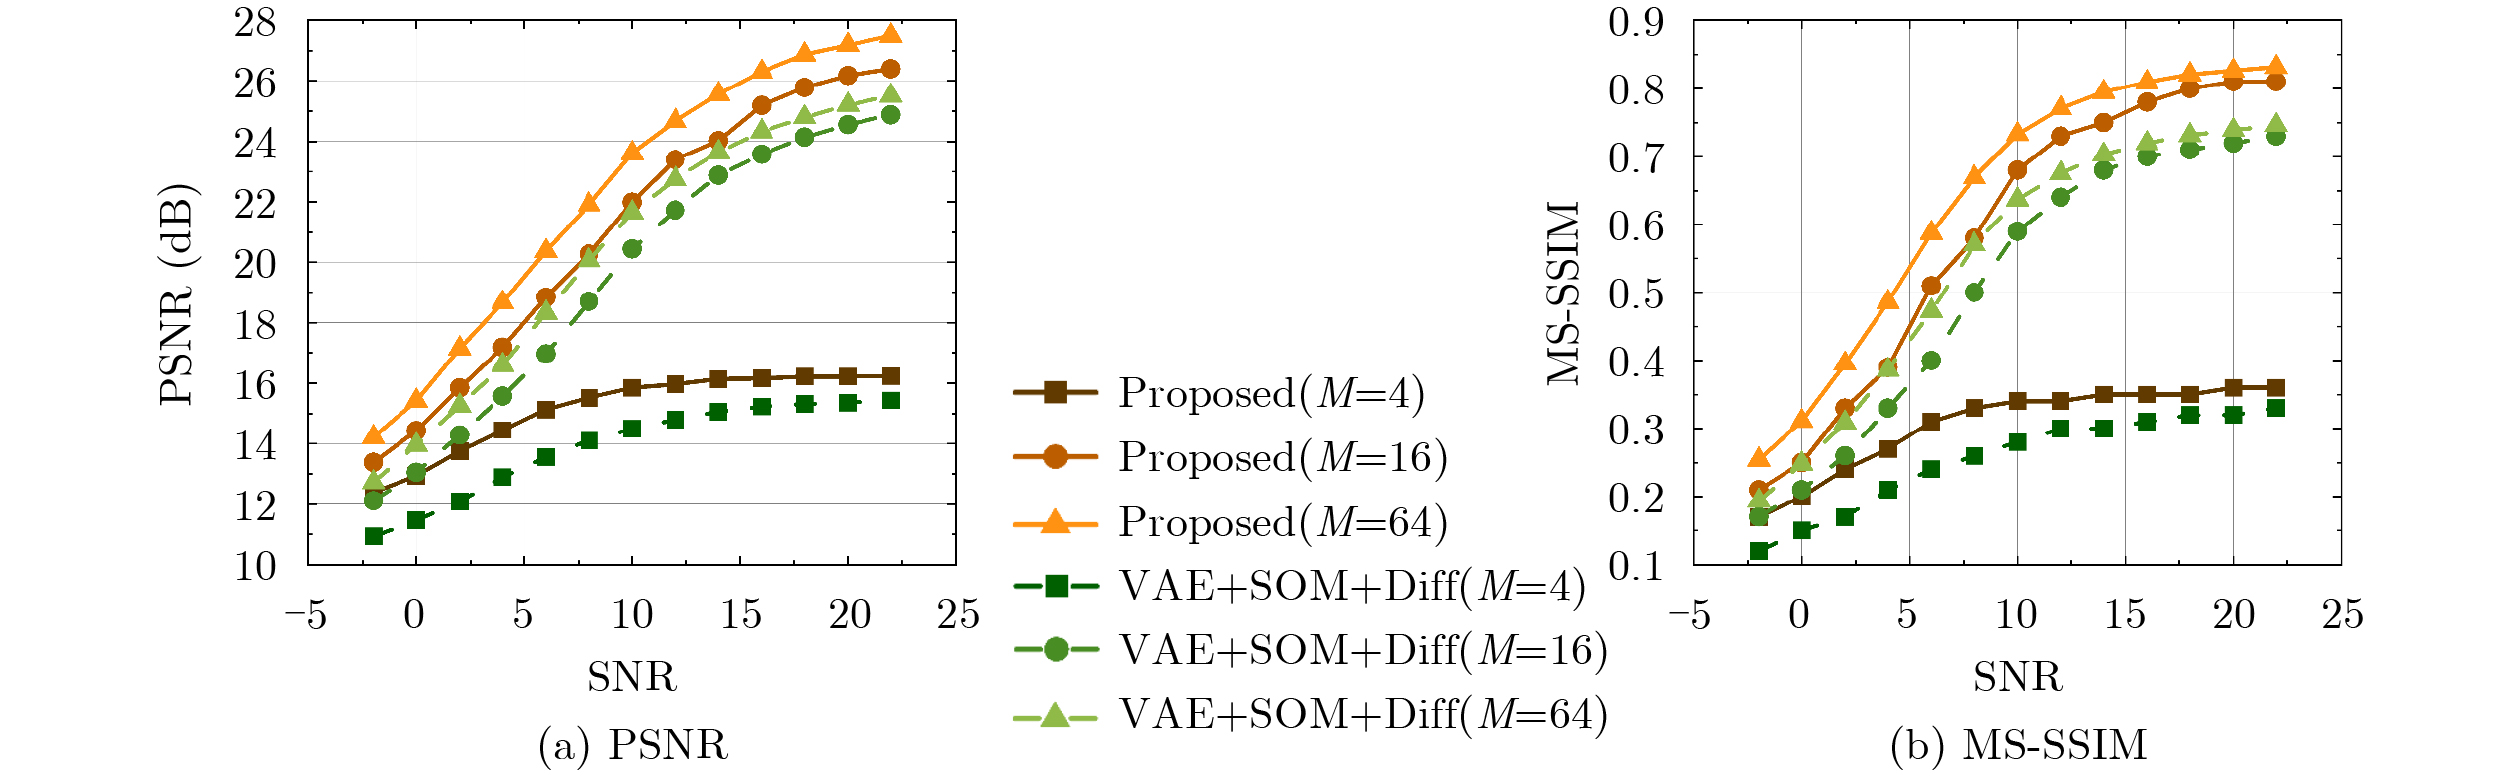
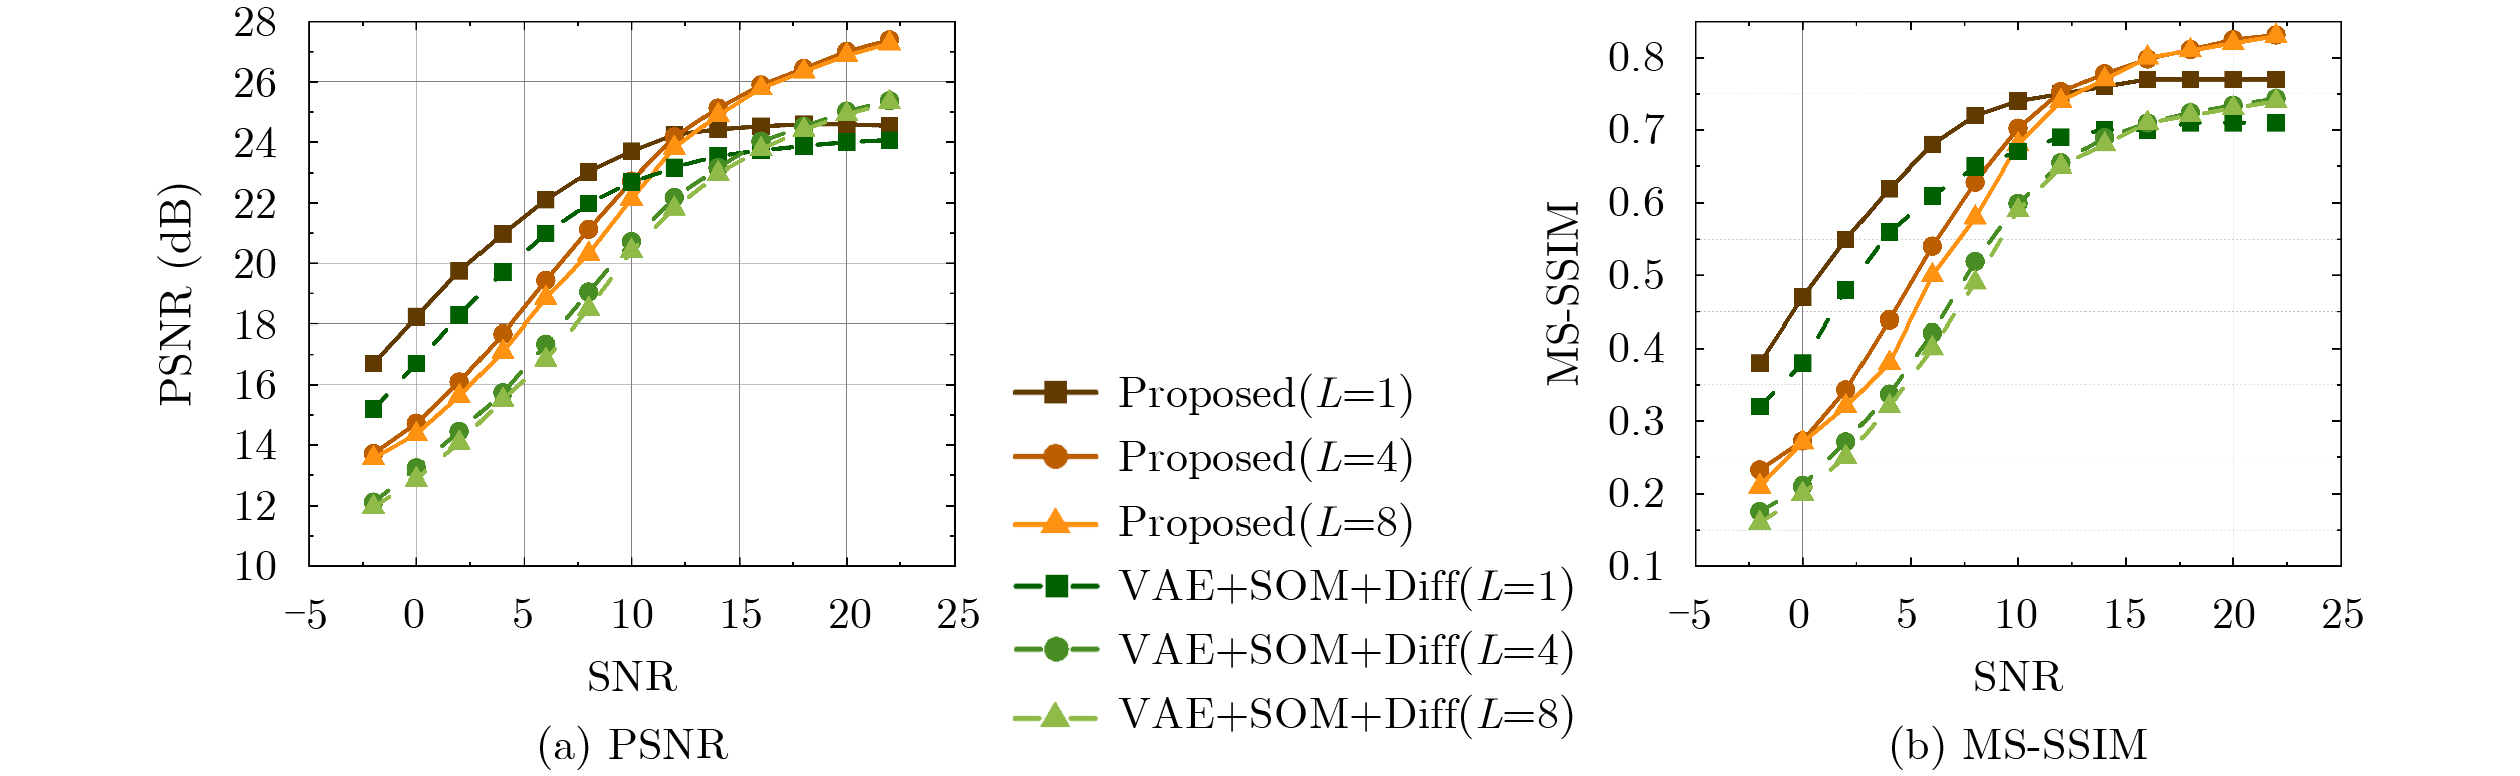
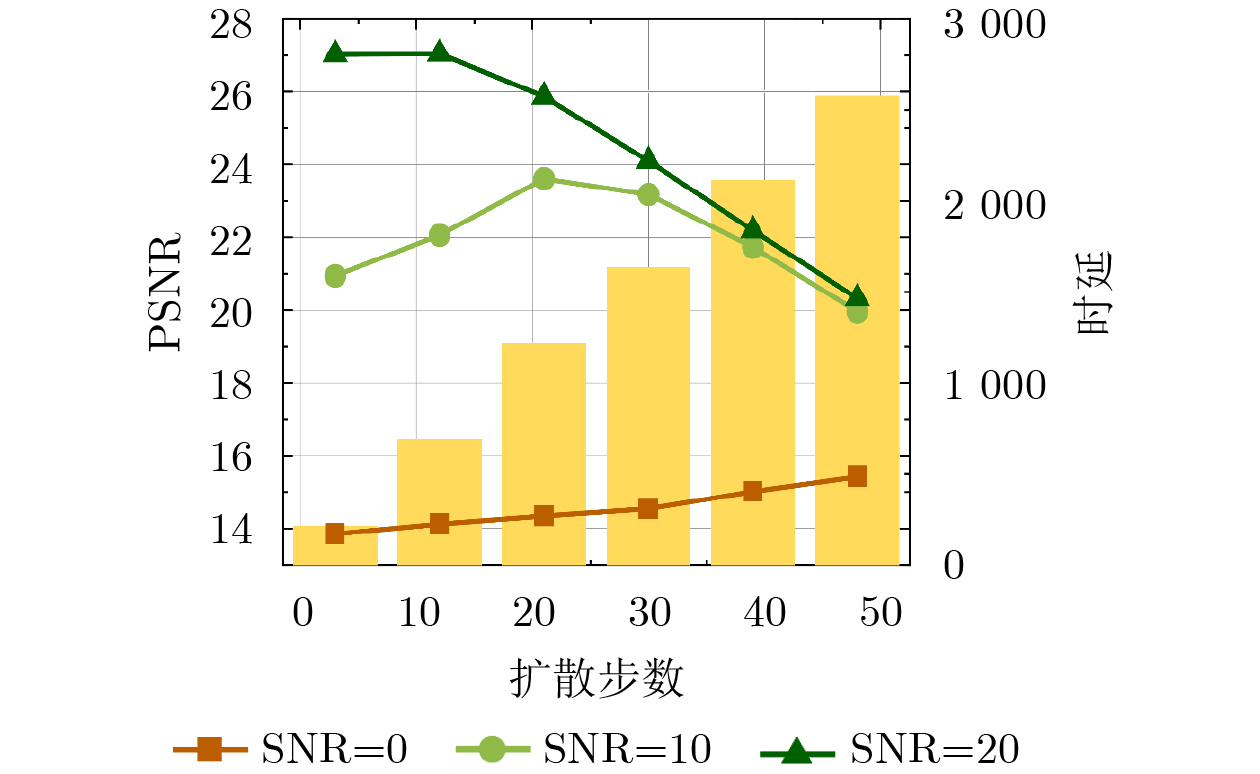
  •   Objective  Practical semantic communication should satisfy two requirements: compatibility with existing digital communication infrastructures and robustness under varying channel conditions. Semantic-Oriented Modulation (SOM) maps continuous semantic features to layered digital constellation symbols, enabling semantic transmission over conventional digital systems. However, the digitization process introduces structured quantization distortion, which increases the difficulty of receiver-side recovery. Although diffusion models provide channel-adaptive semantic recovery, their direct application to SOM-based digital semantic communication is limited by this structured distortion. Therefore, a channel-adaptive receiver is designed for digital semantic communication to compensate for SOM-induced structured distortion before subsequent recovery.  Methods  An SOM-based digital semantic communication system for image transmission over an Additive White Gaussian Noise (AWGN) channel is considered. The proposed receiver adopts a two-stage structure comprising a Quantization Noise Predictor (QNP) and a diffusion recovery module. In the first stage, QNP estimates and compensates for the structured quantization distortion introduced by SOM from layer-wise soft received symbols. In the second stage, the compensated semantic representation is further refined by a diffusion denoiser, with the number of inference steps adaptively selected according to the estimated Signal-to-Noise Ratio (SNR). The QNP consists of a shared feature-extraction front end, a classification branch that exploits discrete SOM constellation priors, and a regression branch that performs fine-grained compensation for quantization distortion in the continuous domain. A Feature-wise Linear Modulation (FiLM) mechanism is used to incorporate SOM parameters and channel state information, enabling a single QNP to adapt to different modulation configurations and channel conditions. In addition, a composite loss comprising classification, regression, and distribution regularization terms is designed to improve the statistical properties of the compensated residual noise.  Results and Discussions  Experiments are conducted on the CLIC dataset using Peak Signal-to-Noise Ratio (PSNR) and Multi-scale structural similarity (MS-SSIM) as evaluation metrics. The proposed method is compared with a Variational autoencoder (VAE), VAE+Diff, VAE+SOM, VAE+SOM+QNP, VAE+SOM+Diff, and the Joint coding-modulation (JCM) method. Direct SOM-based digitization causes noticeable performance degradation, whereas the proposed method consistently improves image reconstruction quality over digital semantic baselines. QNP alone improves PSNR by an average of 1.77 dB and MS-SSIM by 26.08% compared with the VAE+SOM baseline under different channel conditions. Moreover, compared with VAE+SOM and VAE+SOM+Diff, the complete method improves PSNR by 3.67 dB and 1.89 dB and MS-SSIM by 58.79% and 18.64%, respectively. These results demonstrate that QNP provides effective compensation independently of diffusion recovery and that its combination with diffusion recovery provides complementary gains. Two training strategies, namely independent QNP training and diffusion-assisted fine-tuning, are further compared. Diffusion-assisted fine-tuning improves PSNR and MS-SSIM by only 0.83 dB and 3.30% on average, respectively, but substantially increases training complexity and resource consumption. Therefore, independent training is adopted for the main experiments. Under different SOM configurations, the proposed method maintains stable gains across different modulation orders and numbers of SOM layers. Latency analysis shows that QNP requires only 4.127 ms for one forward pass, whereas one diffusion step requires approximately 85.746 ms. Thus, inference latency is mainly determined by diffusion iterations, and the diffusion-step schedule is selected according to the trade-off between reconstruction quality and latency. Finally, Gaussianity analysis based on Kullback-Leibler divergence and Wasserstein distance shows that QNP compensation makes the residual noise distribution more consistent with a Gaussian distribution. Without distribution regularization, the two distances decrease by 97.20% and 89.26% on average, respectively, compared with the uncompensated case. With distribution regularization, the corresponding reductions reach 99.26% and 98.47%, respectively.  Conclusions  A channel-adaptive receiver for digital semantic communication is proposed by combining QNP-based front-end compensation with diffusion-based semantic recovery. The QNP provides lightweight compensation for SOM-induced structured quantization distortion before subsequent recovery and remains effective when used independently. Experimental results show that stable digital semantic recovery gains are obtained under different SNR conditions and SOM configurations. When combined with diffusion recovery, the proposed method achieves the best overall performance. The proposed receiver therefore provides an effective approach for improving semantic recovery quality and channel adaptability while maintaining compatibility with existing digital communication infrastructures.
  • loading
  • [1]
    SHI Guangming, XIAO Yong, LI Yingyu, et al. From semantic communication to semantic-aware networking: Model, architecture, and open problems[J]. IEEE Communications Magazine, 2021, 59(8): 44–50. doi: 10.1109/MCOM.001.2001239.
    [2]
    GÜLER B, YENER A, and SWAMI A. The semantic communication game[J]. IEEE Transactions on Cognitive Communications and Networking, 2018, 4(4): 787–802. doi: 10.1109/TCCN.2018.2872596.
    [3]
    LI Yihao, ZHOU Fuhui, YUAN Lu, et al. Cognitive semantic communication: A new communication paradigm for 6G[J]. IEEE Communications Magazine, 2025, 63(6): 122–129. doi: 10.1109/MCOM.005.2400366.
    [4]
    SAGDUYU Y E, ERPEK T, YENER A, et al. Will 6G be semantic communications? Opportunities and challenges from task oriented and secure communications to integrated sensing[J]. IEEE Network, 2024, 38(6): 72–80. doi: 10.1109/MNET.2024.3425152.
    [5]
    张祖凡, 尹星然, 周建萍, 等. 面向语义重要性和鲁棒性的RIS增强语义通信系统[J]. 电子与信息学报, 2025, 47(8): 2608–2620. doi: 10.11999/JEIT250159.

    ZHANG Zufan, YIN Xingran, ZHOU Jianping, et al. RIS-enhanced semantic communication systems oriented towards se-mantic importance and robustness[J]. Journal of Electronics & Information Technology, 2025, 47(8): 2608–2620. doi: 10.11999/JEIT250159.
    [6]
    陈阳, 马欢, 姬智, 等. 面向图像恢复任务的语义通信网络能耗优化[J]. 电子与信息学报, 2026, 48(1): 183–190. doi: 10.11999/JEIT250915.

    CHEN Yang, MA Huan, JI Zhi, et al. Optimization of energy consumption in semantic communication networks for image recovery tasks[J]. Journal of Electronics & Information Technology, 2026, 48(1): 183–190. doi: 10.11999/JEIT250915.
    [7]
    申滨, 李旋, 赖雪冰, 等. 基于Swin Transformer的宽带无线图传语义联合编解码方法[J]. 电子与信息学报, 2025, 47(8): 2665–2674. doi: 10.11999/JEIT250039.

    SHEN Bin, LI Xuan, LAI Xuebing, et al. Swin Transformer-based wideband wireless image transmission semantic joint encoding and decoding method[J]. Journal of Electronics & Information Technology, 2025, 47(8): 2665–2674. doi: 10.11999/JEIT250039.
    [8]
    BOURTSOULATZE E, KURKA D B, and GÜNDÜZ D. Deep joint source-channel coding for wireless image transmission[J]. IEEE Transactions on Cognitive Communications and Networking, 2019, 5(3): 567–579. doi: 10.1109/TCCN.2019.2919300.
    [9]
    KURKA D B and GÜNDÜZ D. DeepJSCC-f: Deep joint source-channel coding of images with feedback[J]. IEEE Journal on Selected Areas in Information Theory, 2020, 1(1): 178–193. doi: 10.1109/JSAIT.2020.2987203.
    [10]
    BO Yufei, DUAN Yiheng, SHAO Shuo, et al. Joint coding-modulation for digital semantic communications via variational autoencoder[J]. IEEE Transactions on Communications, 2024, 72(9): 5626–5640. doi: 10.1109/TCOMM.2024.3386577.
    [11]
    GUO Lei, CHEN Wei, SUN Yuxuan, et al. Diffusion-driven semantic communication for generative models with bandwidth constraints[J]. IEEE Transactions on Wireless Communications, 2025, 24(8): 6490–6503. doi: 10.1109/TWC.2025.3553851.
    [12]
    SONG Mengshu, MA Nan, DONG Chen, et al. Deep joint source-channel coding for wireless image transmission with adaptive models[J]. Electronics, 2023, 12(22): 4637. doi: 10.3390/electronics12224637.
    [13]
    CHEN Weixuan, CHEN Yuhao, YANG Qianqian, et al. Deep joint source-channel coding for wireless image transmission with entropy-aware adaptive rate control[C]. GLOBECOM 2023-2023 IEEE Global Communications Conference, Kuala Lumpur, Malaysia, 2023: 2239–2244. doi: 10.1109/GLOBECOM54140.2023.10437482.
    [14]
    WANG Yangfan, ZHANG Xuefei, SUN Yao, et al. Semantic-oriented modulation for wireless communication[J]. IEEE Internet of Things Journal, 2025, 12(14): 28259–28273. doi: 10.1109/JIOT.2025.3565017.
    [15]
    宋淼, 陈志强, 王培松, 等. DetDiffRS: 面向细节优化的遥感图像超分辨率扩散模型[J]. 电子与信息学报, 2025, 47(12): 4763–4778. doi: 10.11999/JEIT250995.

    SONG Miao, CHEN Zhiqiang, WANG Peisong, et al. DetDiffRS: A detail-enhanced diffusion model for remote sensing image super-resolution[J]. Journal of Electronics & Information Technology, 2025, 47(12): 4763–4778. doi: 10.11999/JEIT250995.
    [16]
    XU Bingxuan, MENG Rui, CHEN Yue, et al. Latent semantic diffusion-based channel adaptive de-noising SemCom for future 6G systems[C]. GLOBECOM 2023-2023 IEEE Global Communications Conference, Kuala Lumpur, Malaysia, 2023: 1229–1234. doi: 10.1109/GLOBECOM54140.2023.10437849.
    [17]
    WU Tong, CHEN Zhiyong, HE Dazhi, et al. CDDM: Channel denoising diffusion models for wireless semantic communications[J]. IEEE Transactions on Wireless Communications, 2024, 23(9): 11168–11183. doi: 10.1109/TWC.2024.3379244.
    [18]
    HO J, JAIN A, and ABBEEL P. Denoising diffusion probabilistic models[C]. The 34th International Conference on Neural Information Processing Systems, Vancouver, Canada, 2020: 574.
    [19]
    ROMBACH R, BLATTMANN A, LORENZ D, et al. High-resolution image synthesis with latent diffusion models[C]. 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, USA, 2022: 10674–10685. doi: 10.1109/CVPR52688.2022.01042.
    [20]
    PEREZ E, STRUB F, DE VRIES H, et al. FiLM: Visual reasoning with a general conditioning layer[C]. The 32nd AAAI Conference on Artificial Intelligence, New Orleans, USA, 2018: 3942–3951. doi: 10.1609/aaai.v32i1.11671.
    [21]
    QIAO Li, MASHHADI M B, GAO Zhen, et al. Latency-aware generative semantic communications with pre-trained diffusion models[J]. IEEE Wireless Communications Letters, 2024, 13(10): 2652–2656. doi: 10.1109/LWC.2024.3429295.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(7)  / Tables(4)

    Article Metrics

    Article views (368) PDF downloads(21) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return