Advanced Search
Turn off MathJax
Article Contents
LU Hao, YUAN Liang, CAO Ning. Semantic-Driven Adaptive Joint Source-Channel Coding for UAV Disaster Image Transmission[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260490
Citation: LU Hao, YUAN Liang, CAO Ning. Semantic-Driven Adaptive Joint Source-Channel Coding for UAV Disaster Image Transmission[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260490

Semantic-Driven Adaptive Joint Source-Channel Coding for UAV Disaster Image Transmission

doi: 10.11999/JEIT260490 cstr: 32379.14.JEIT260490
Funds:  The National Natural Science Foundation of China (62271190)
  • Accepted Date: 2026-10-19
  • Rev Recd Date: 2026-10-19
  • Available Online: 2026-10-29
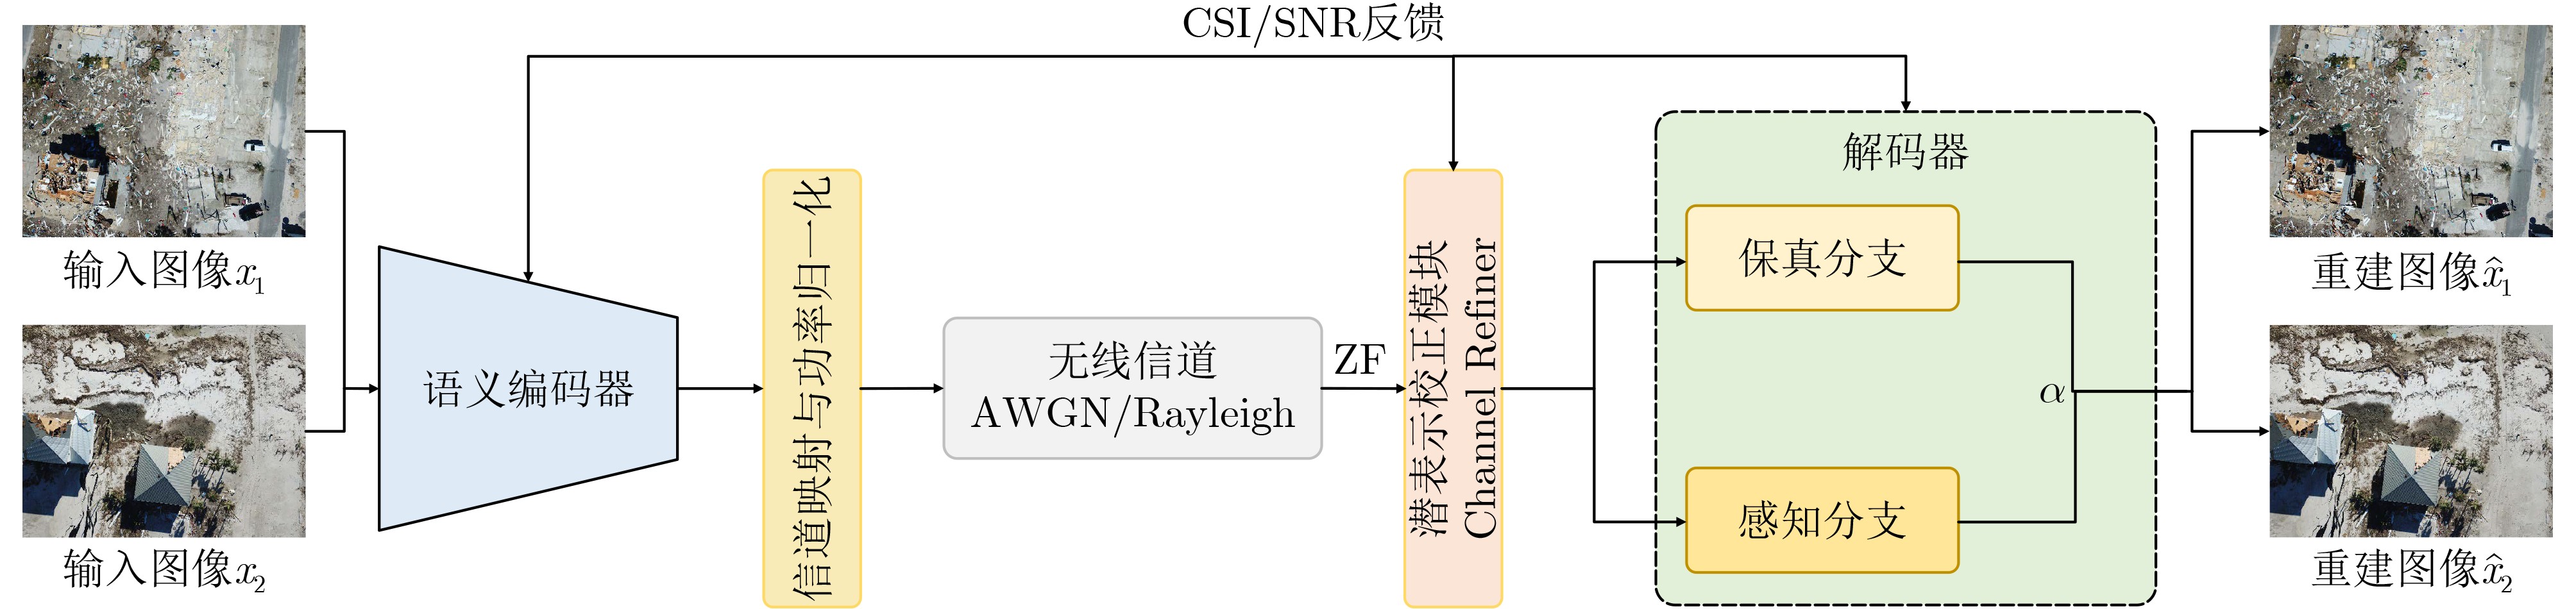
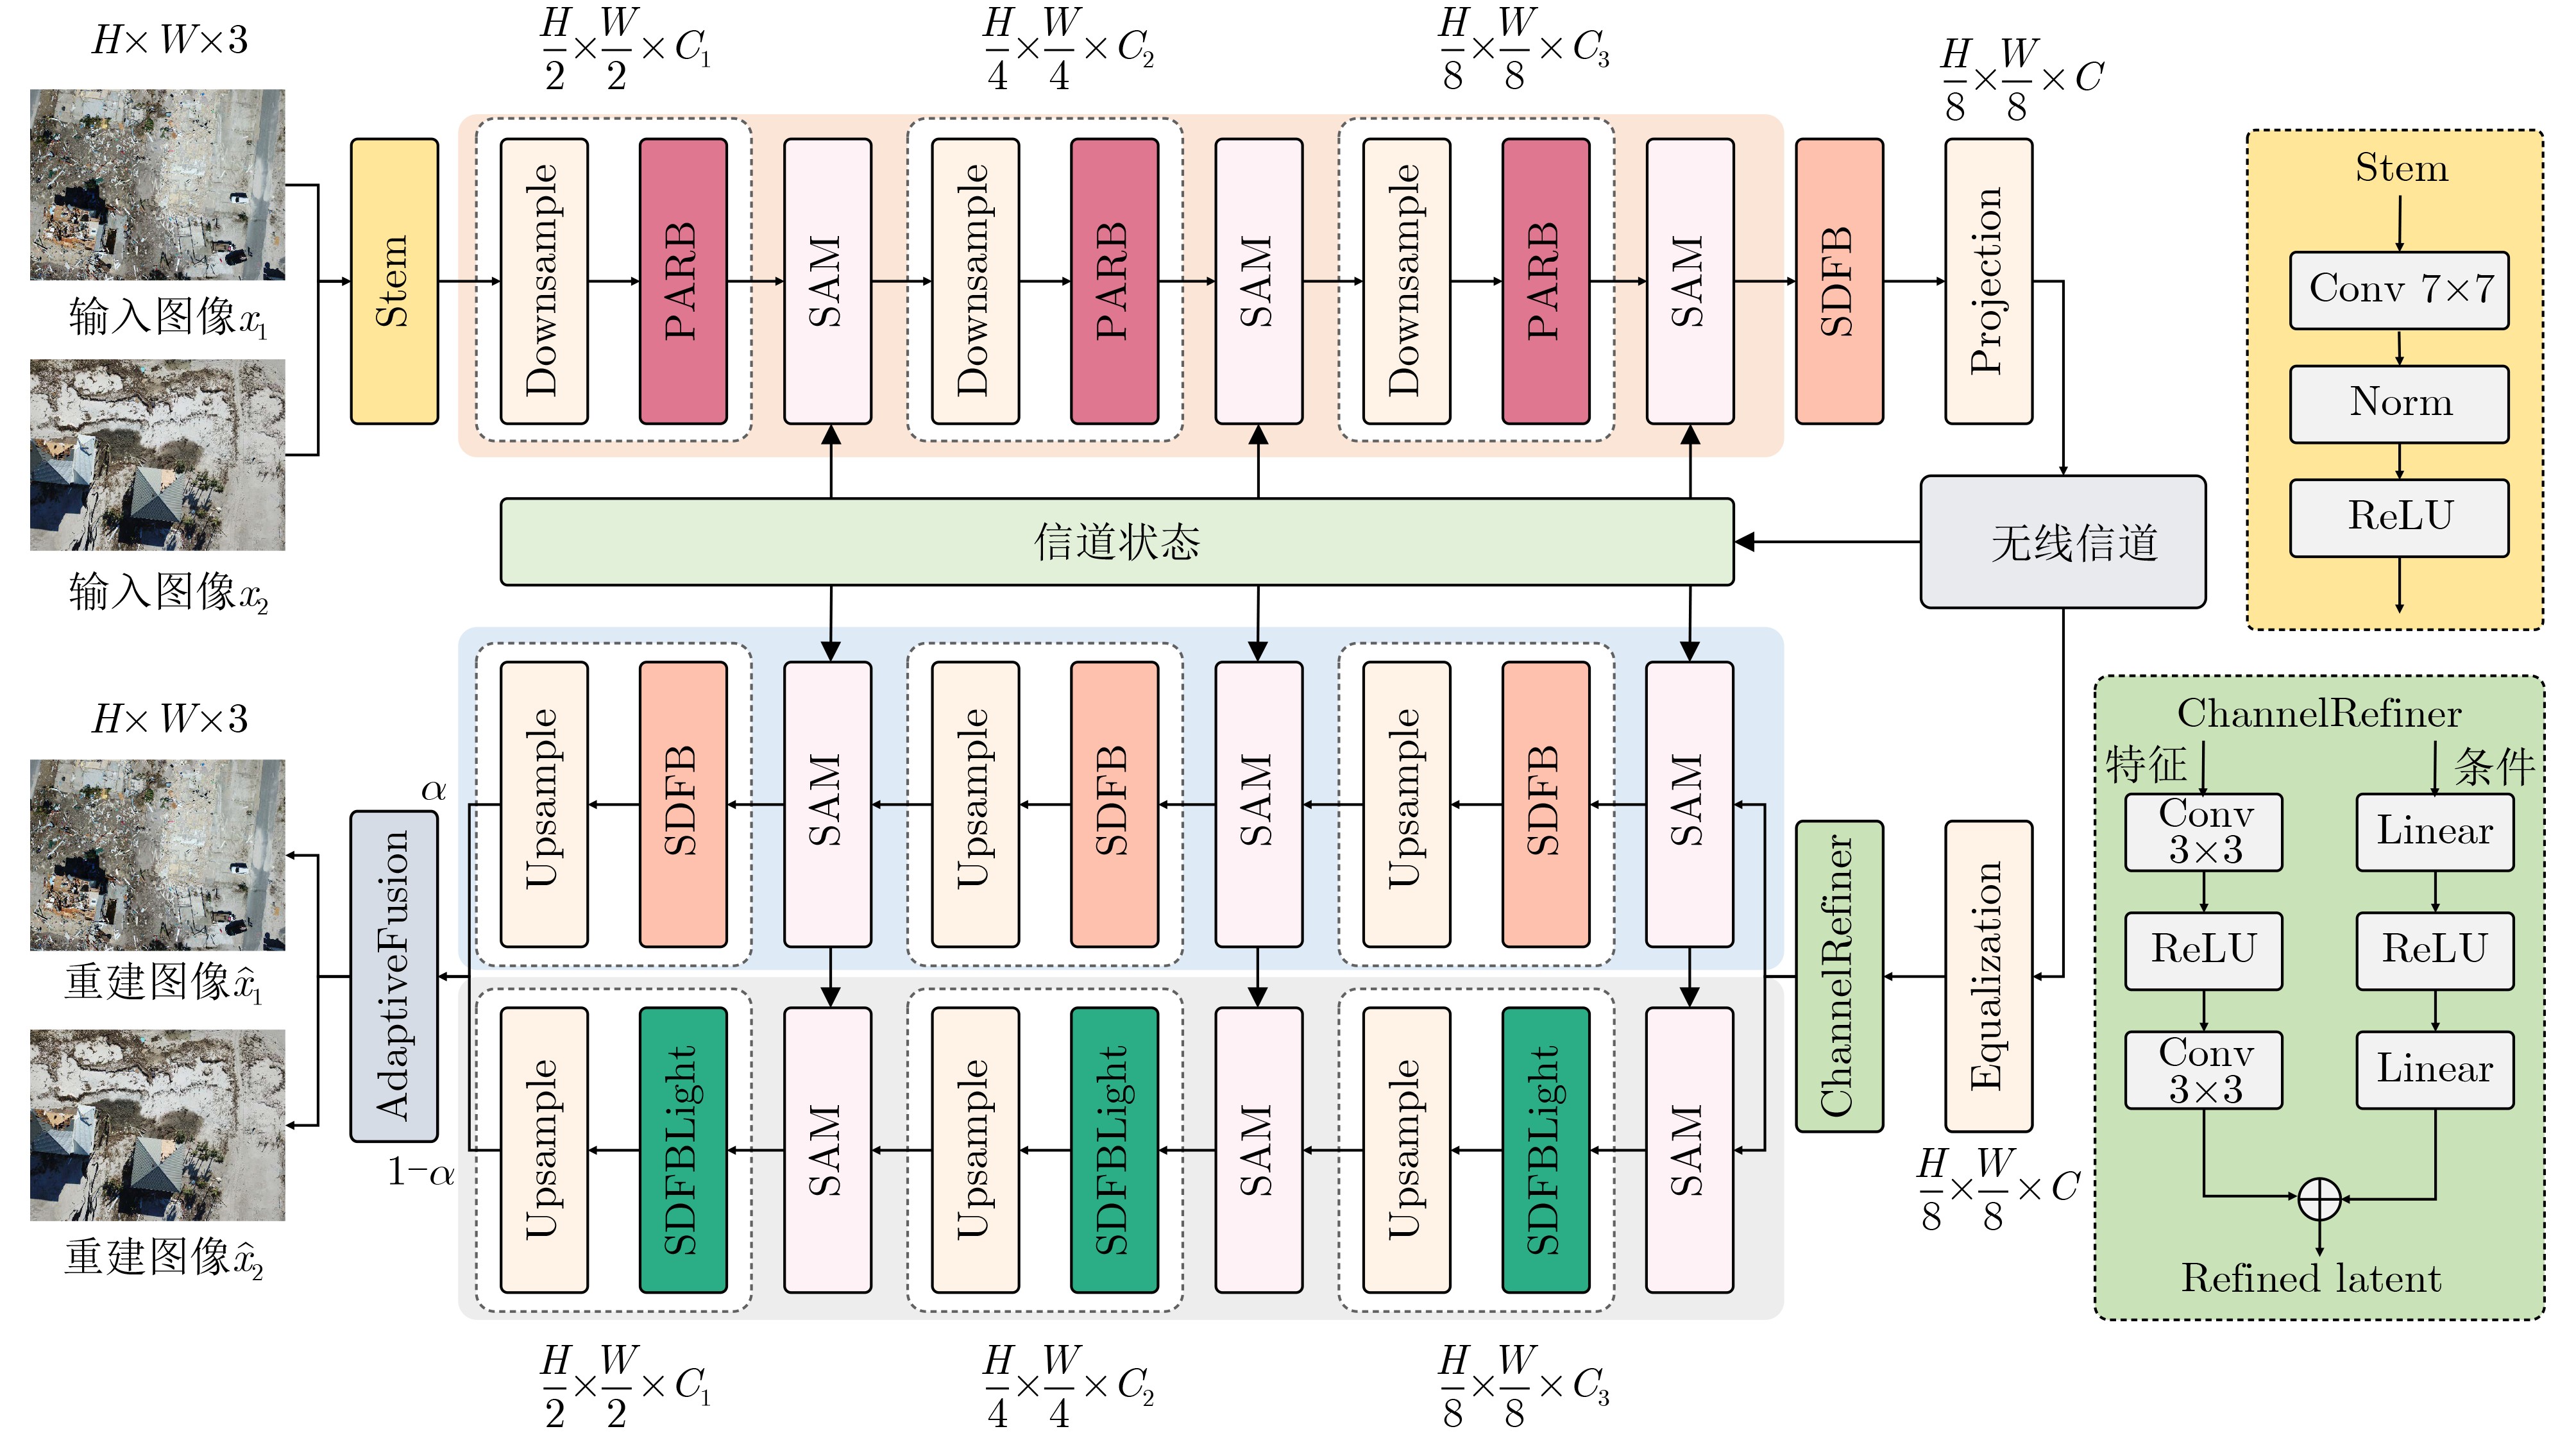
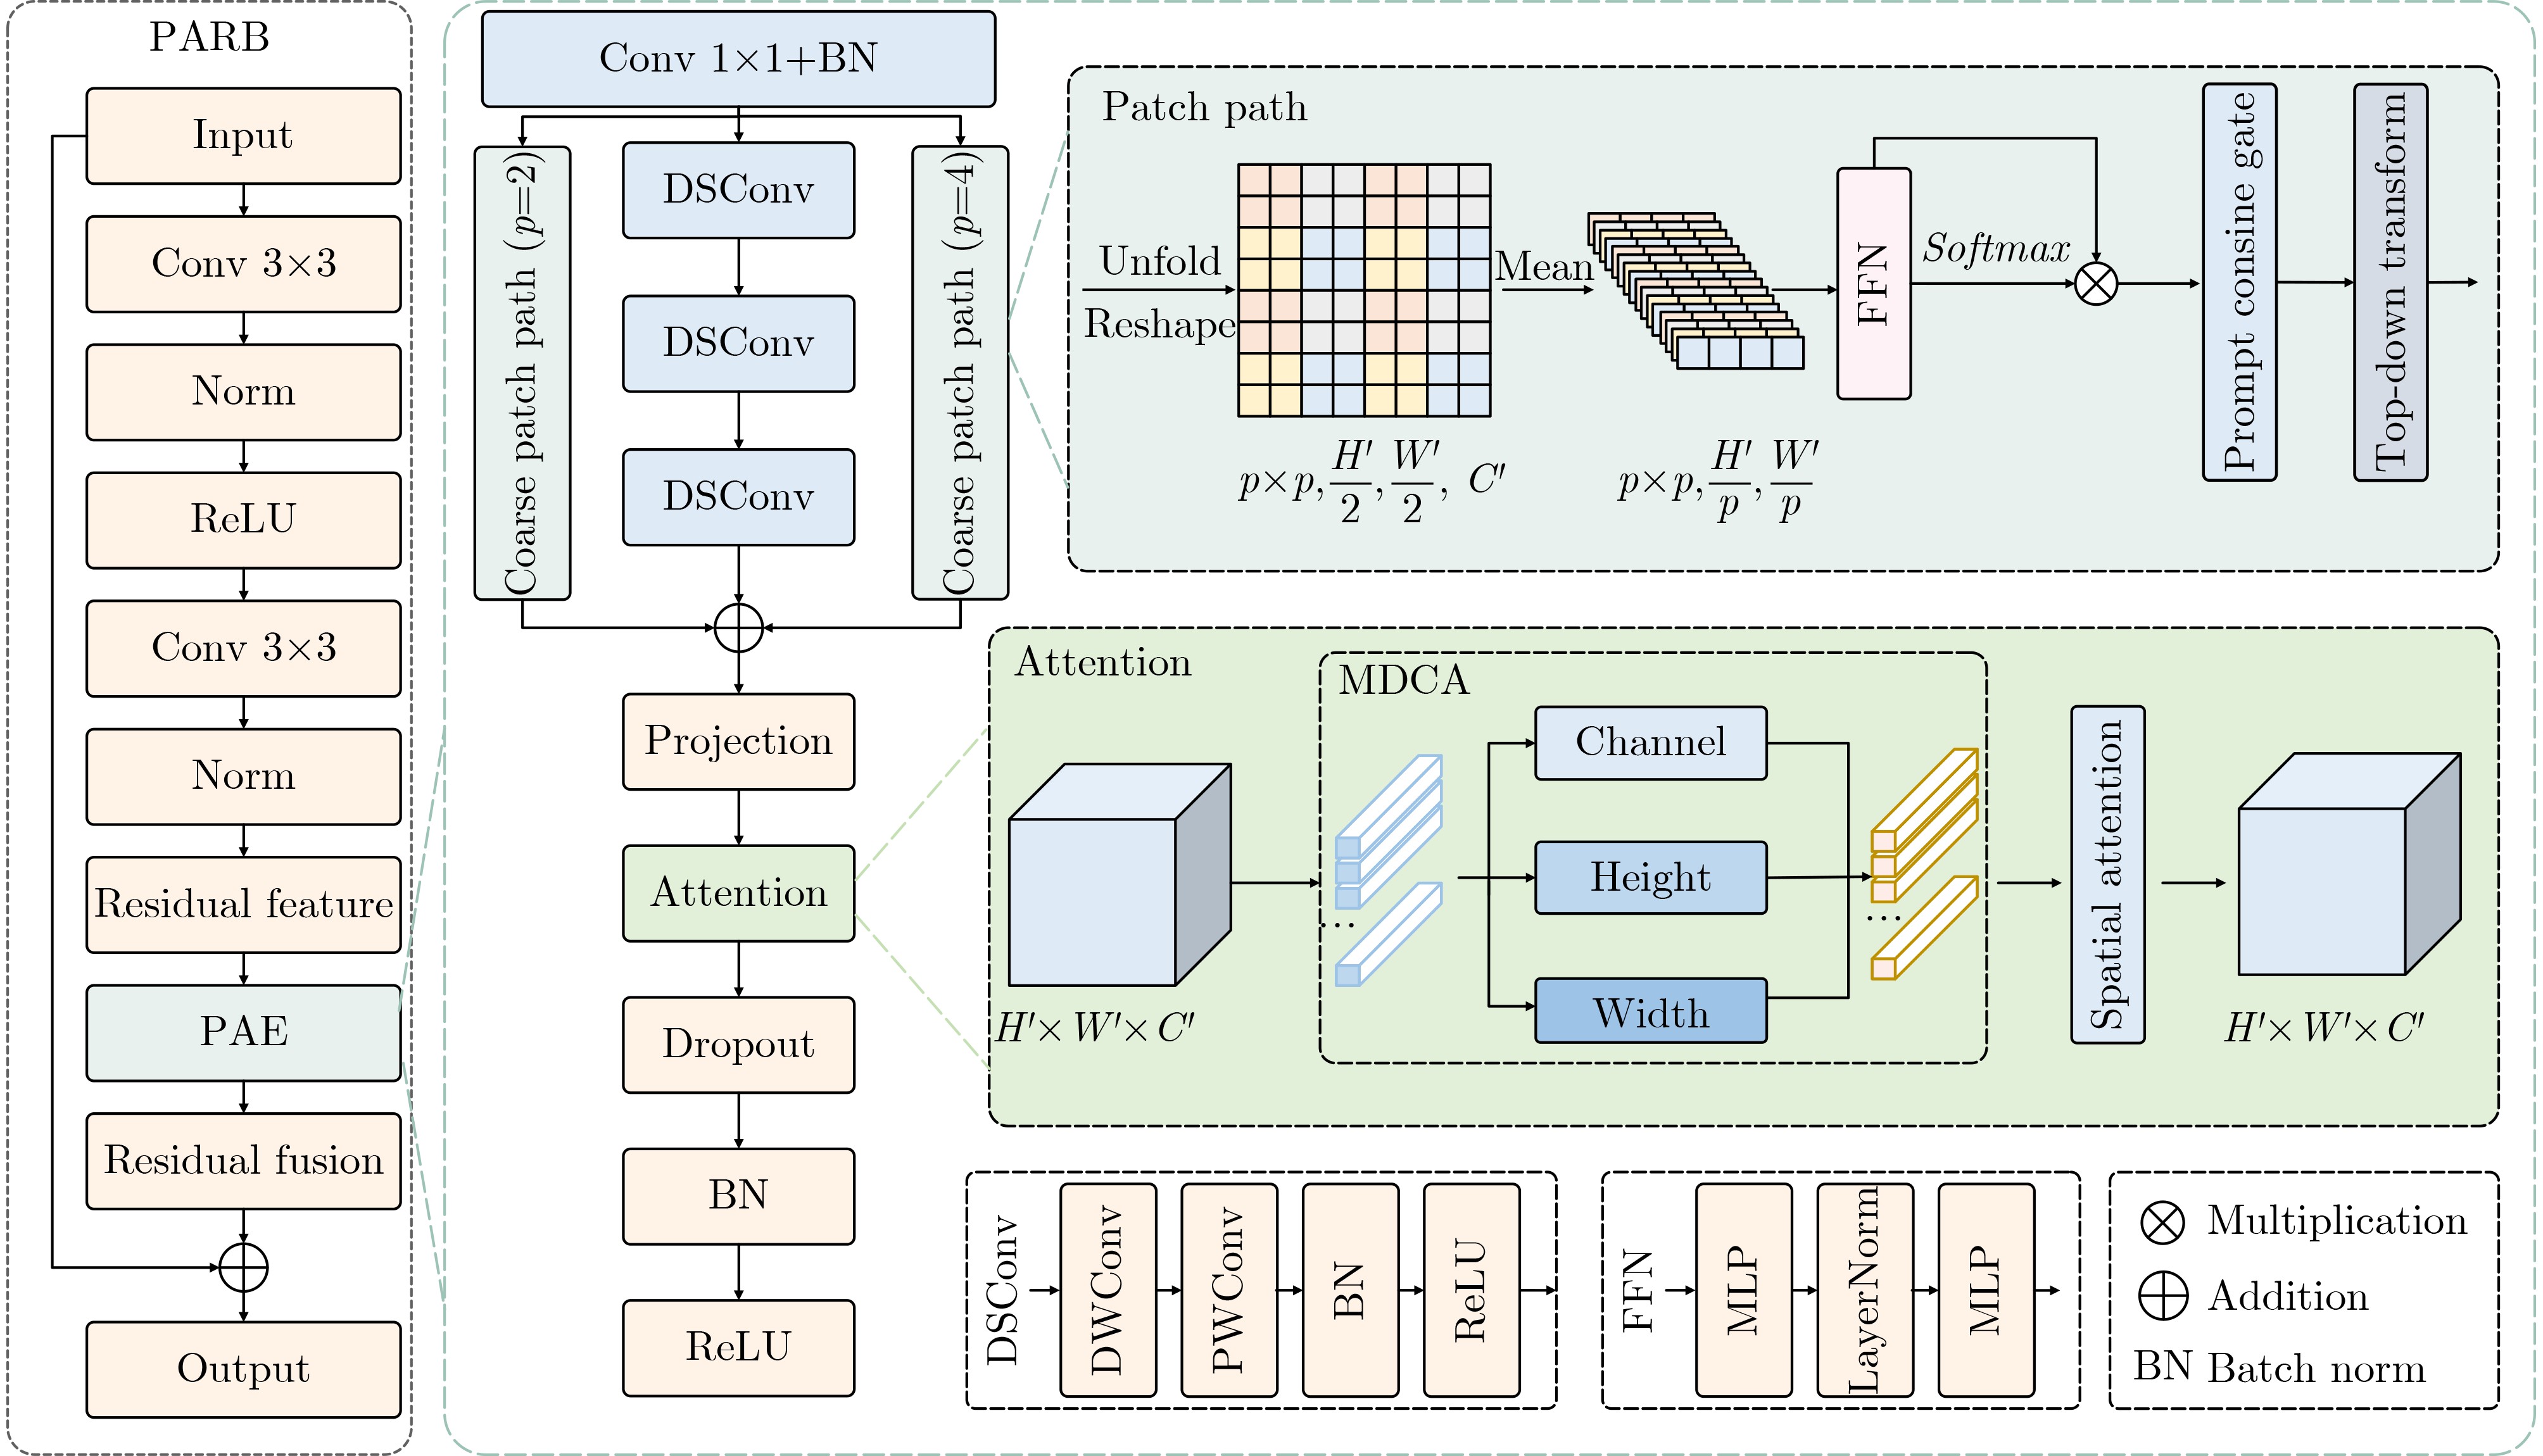
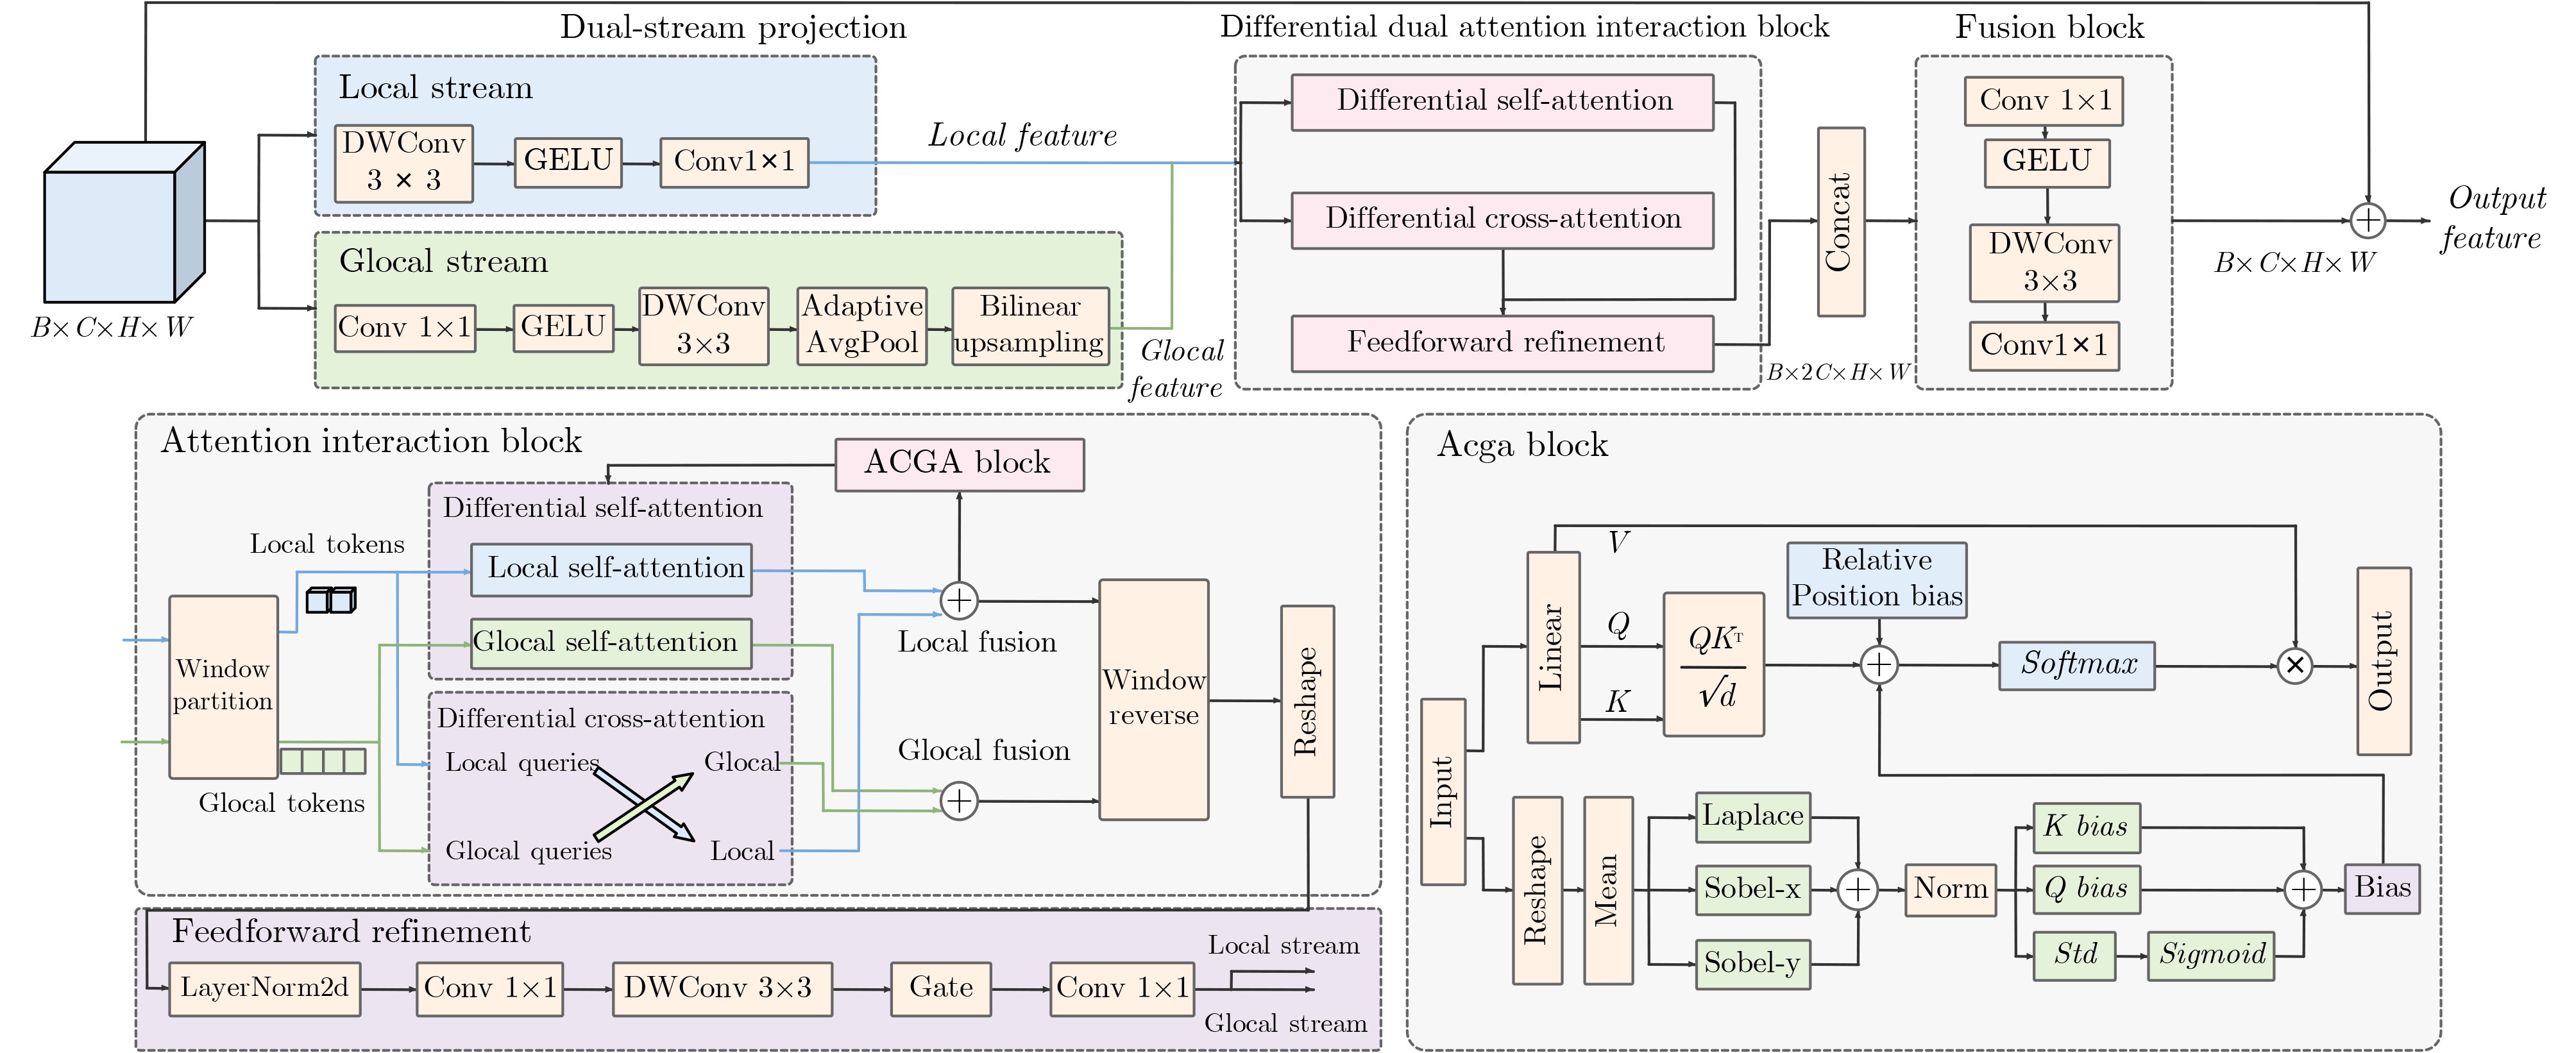
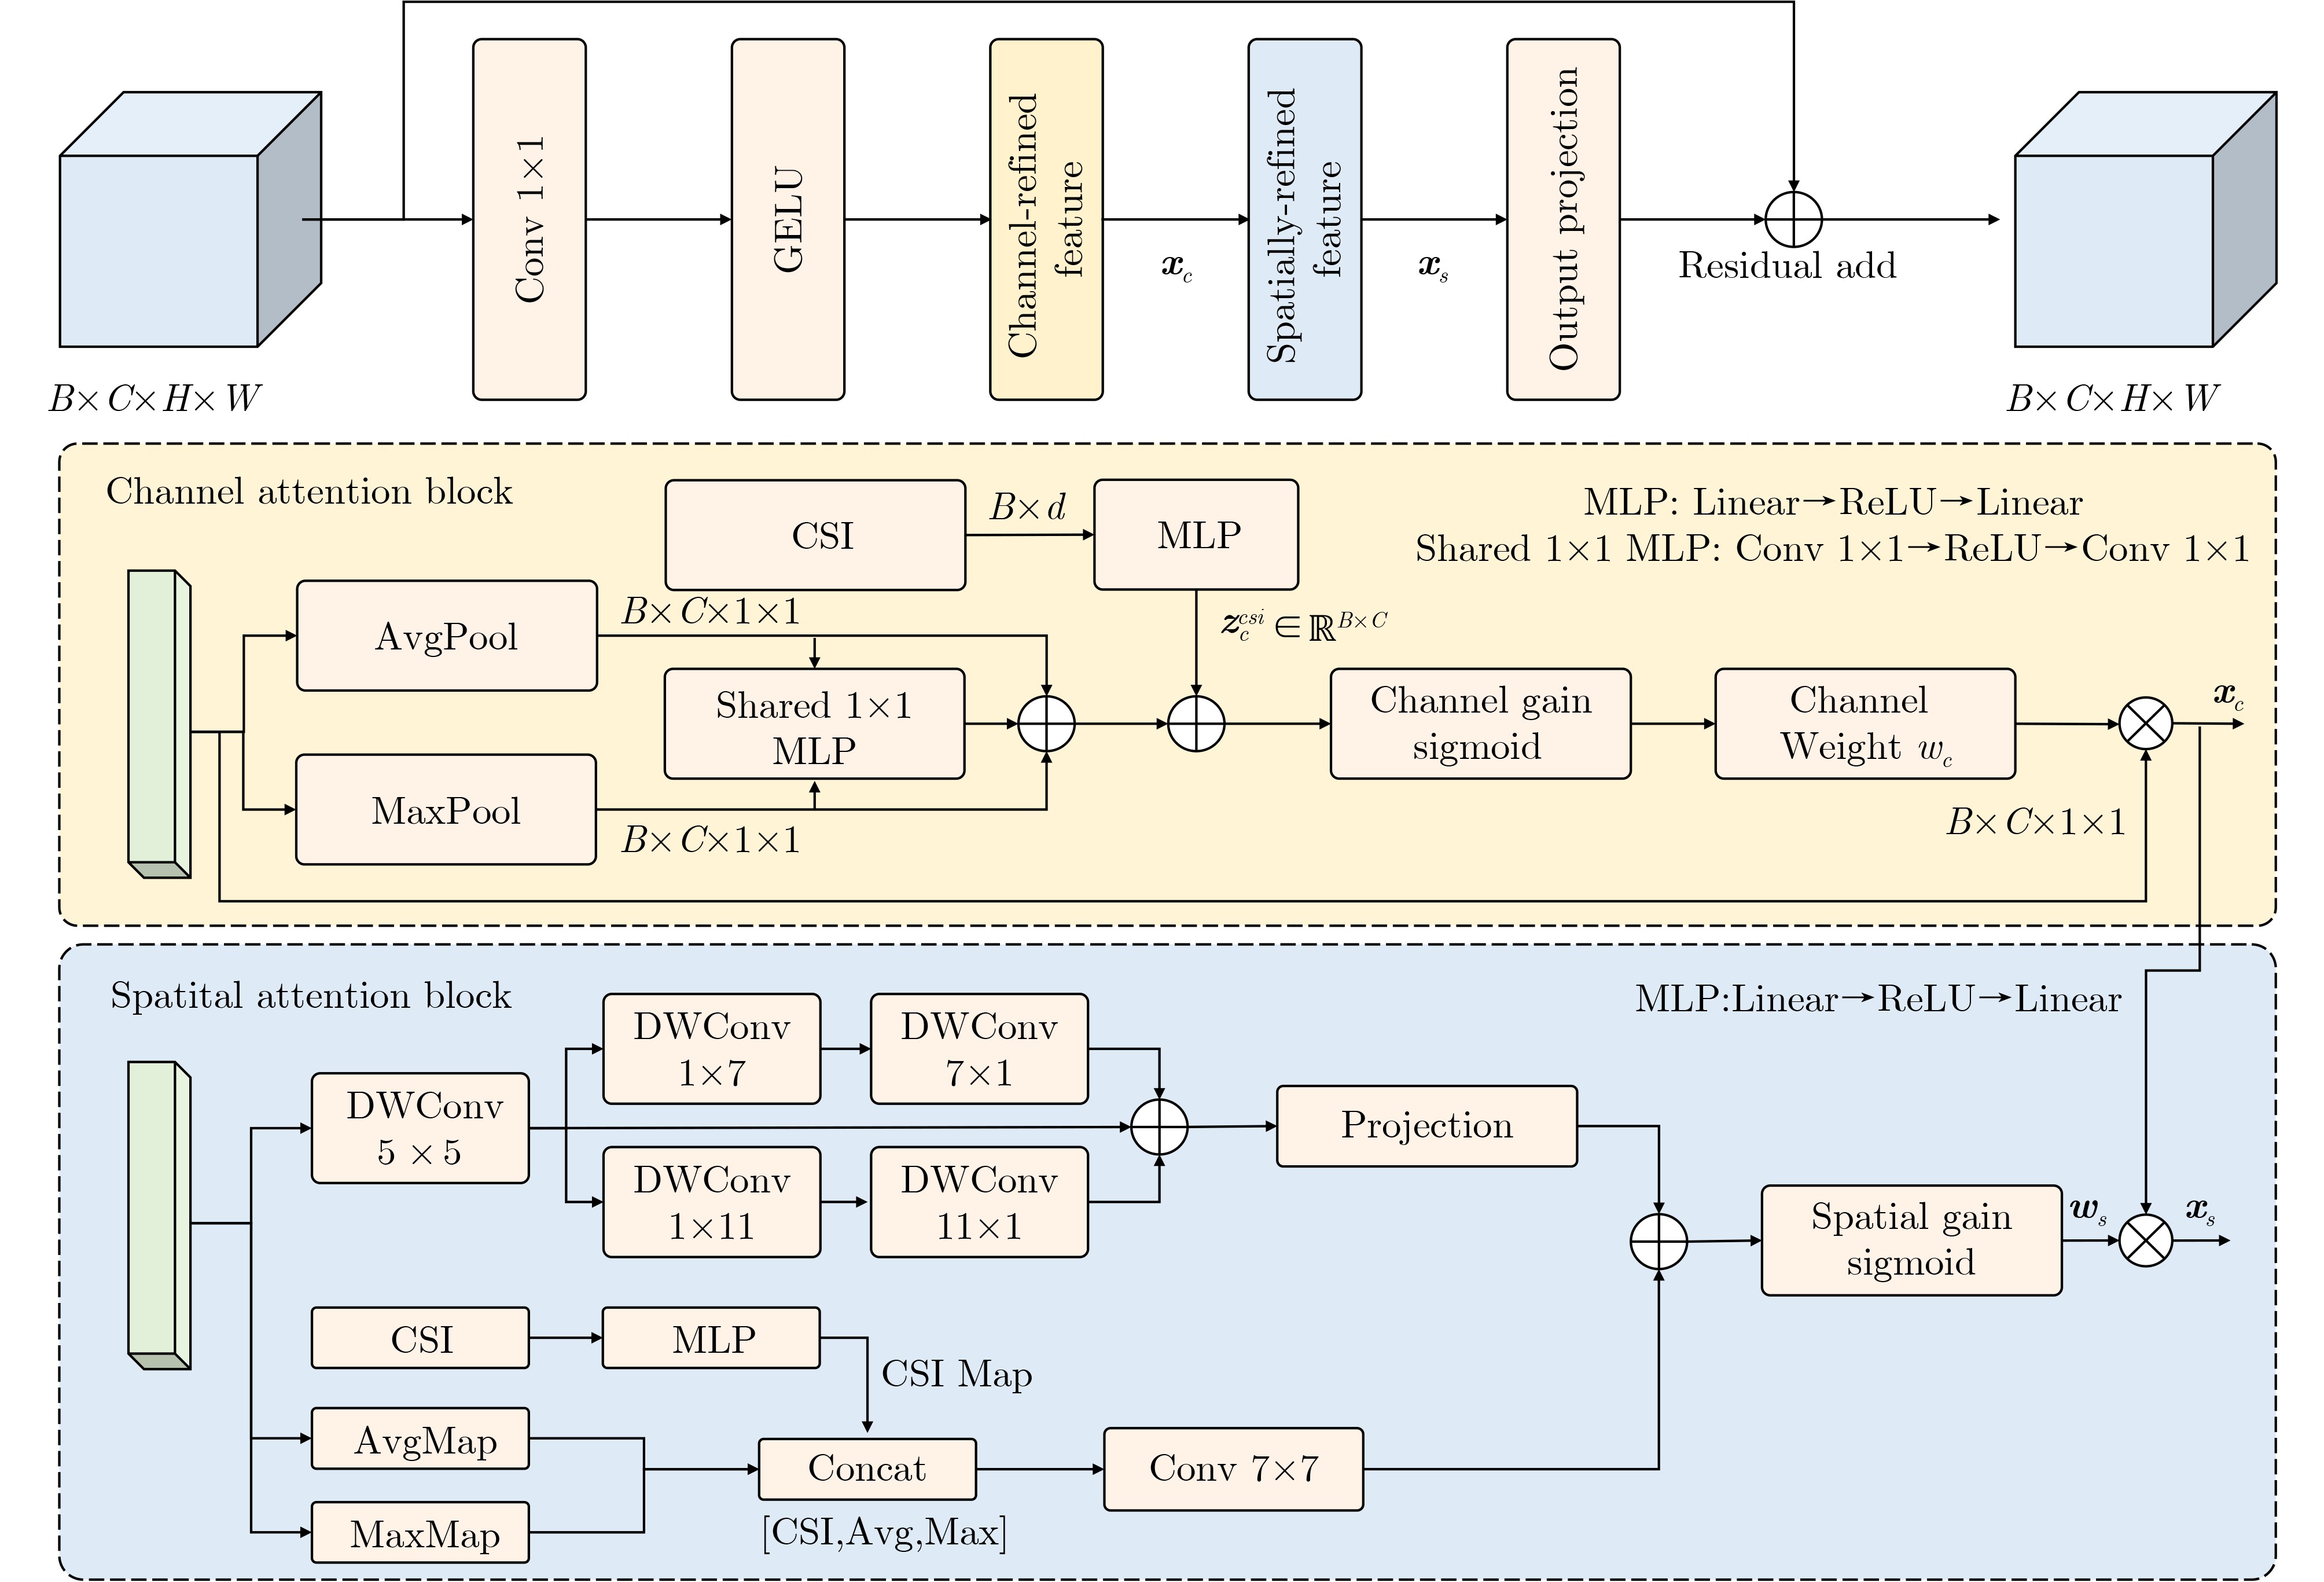
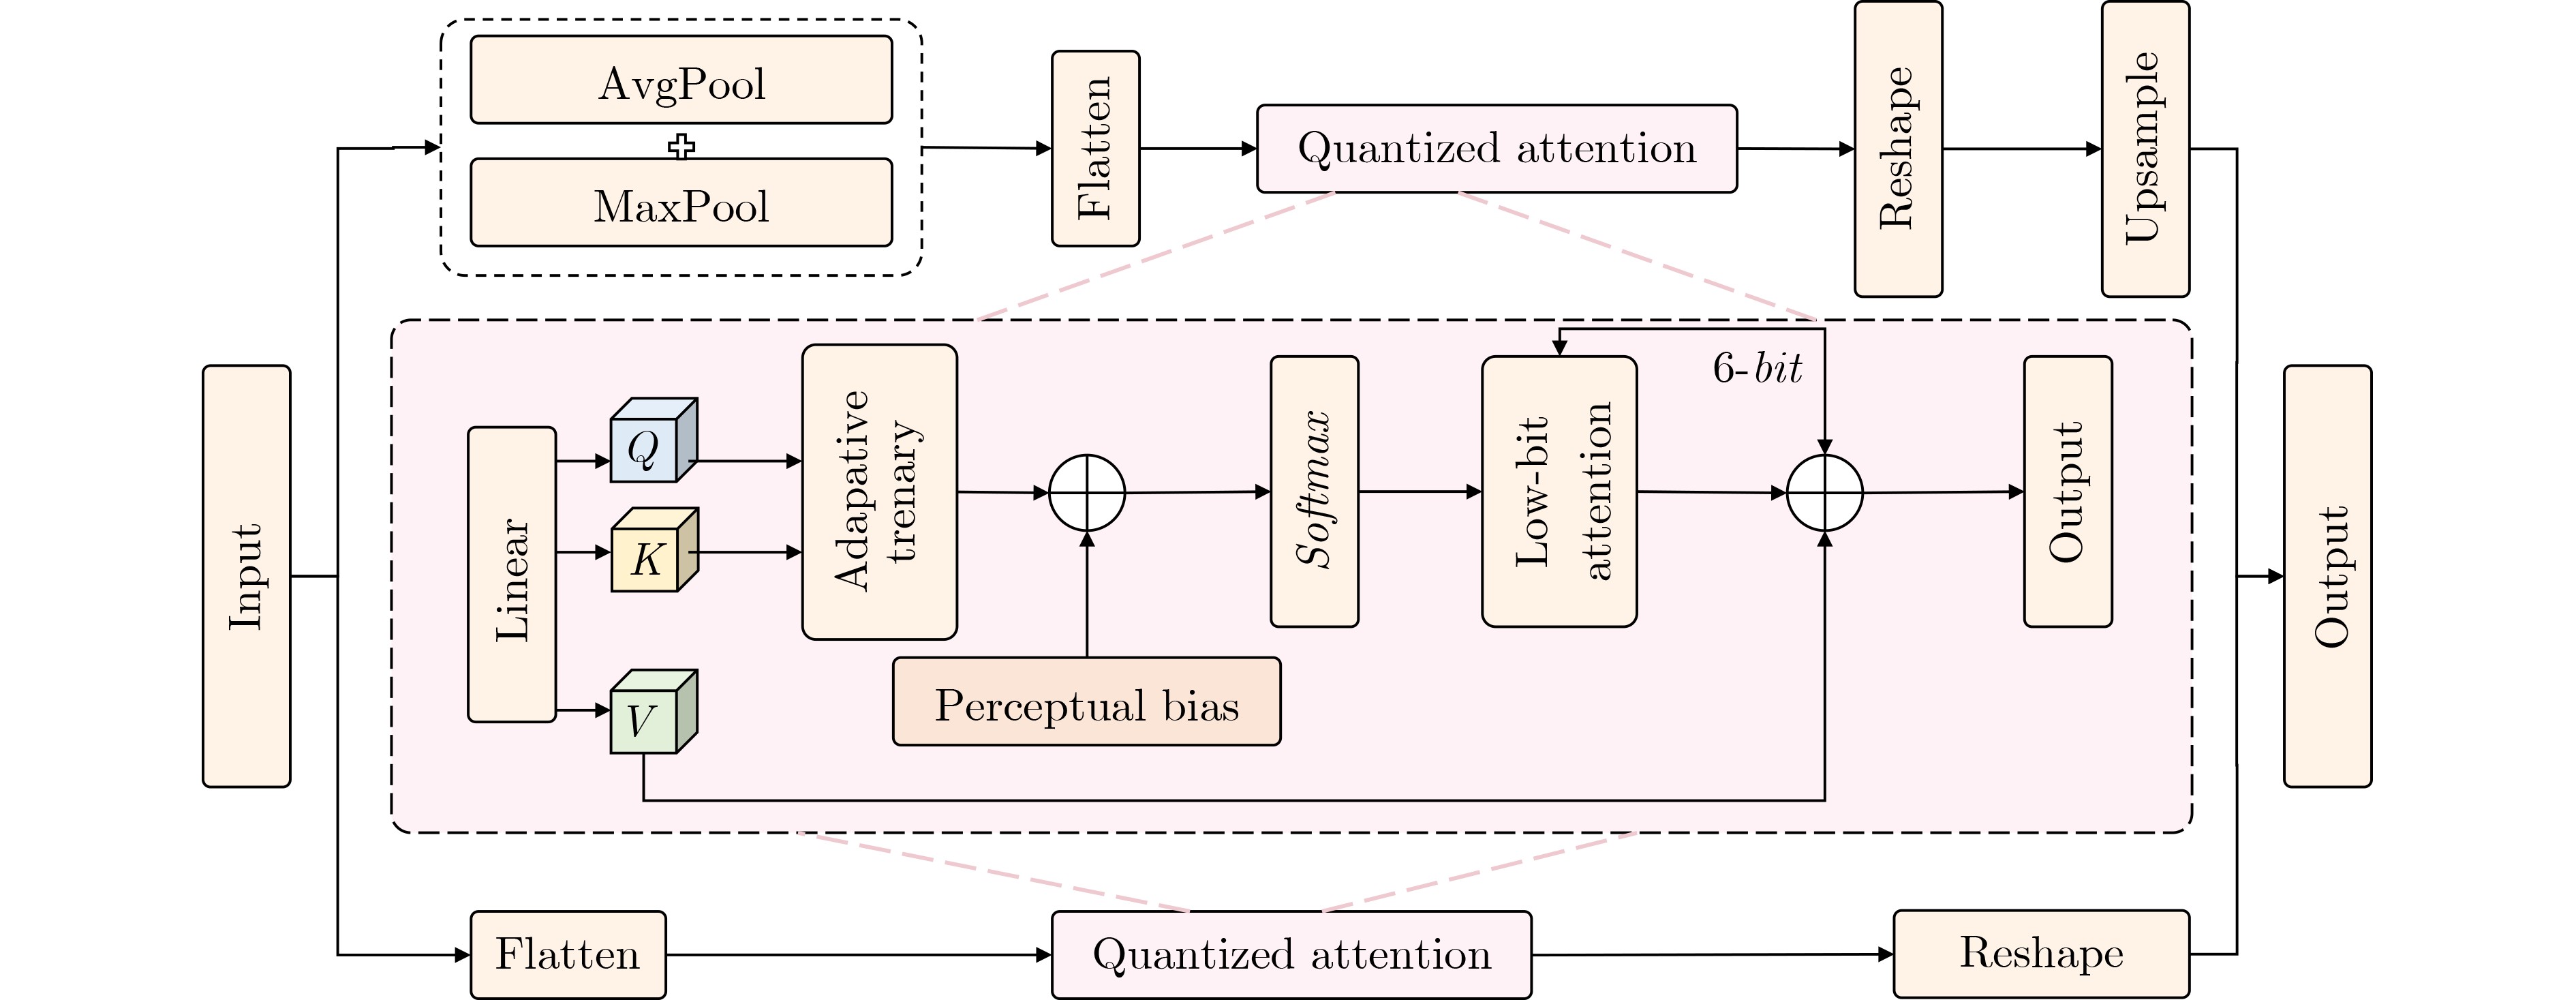
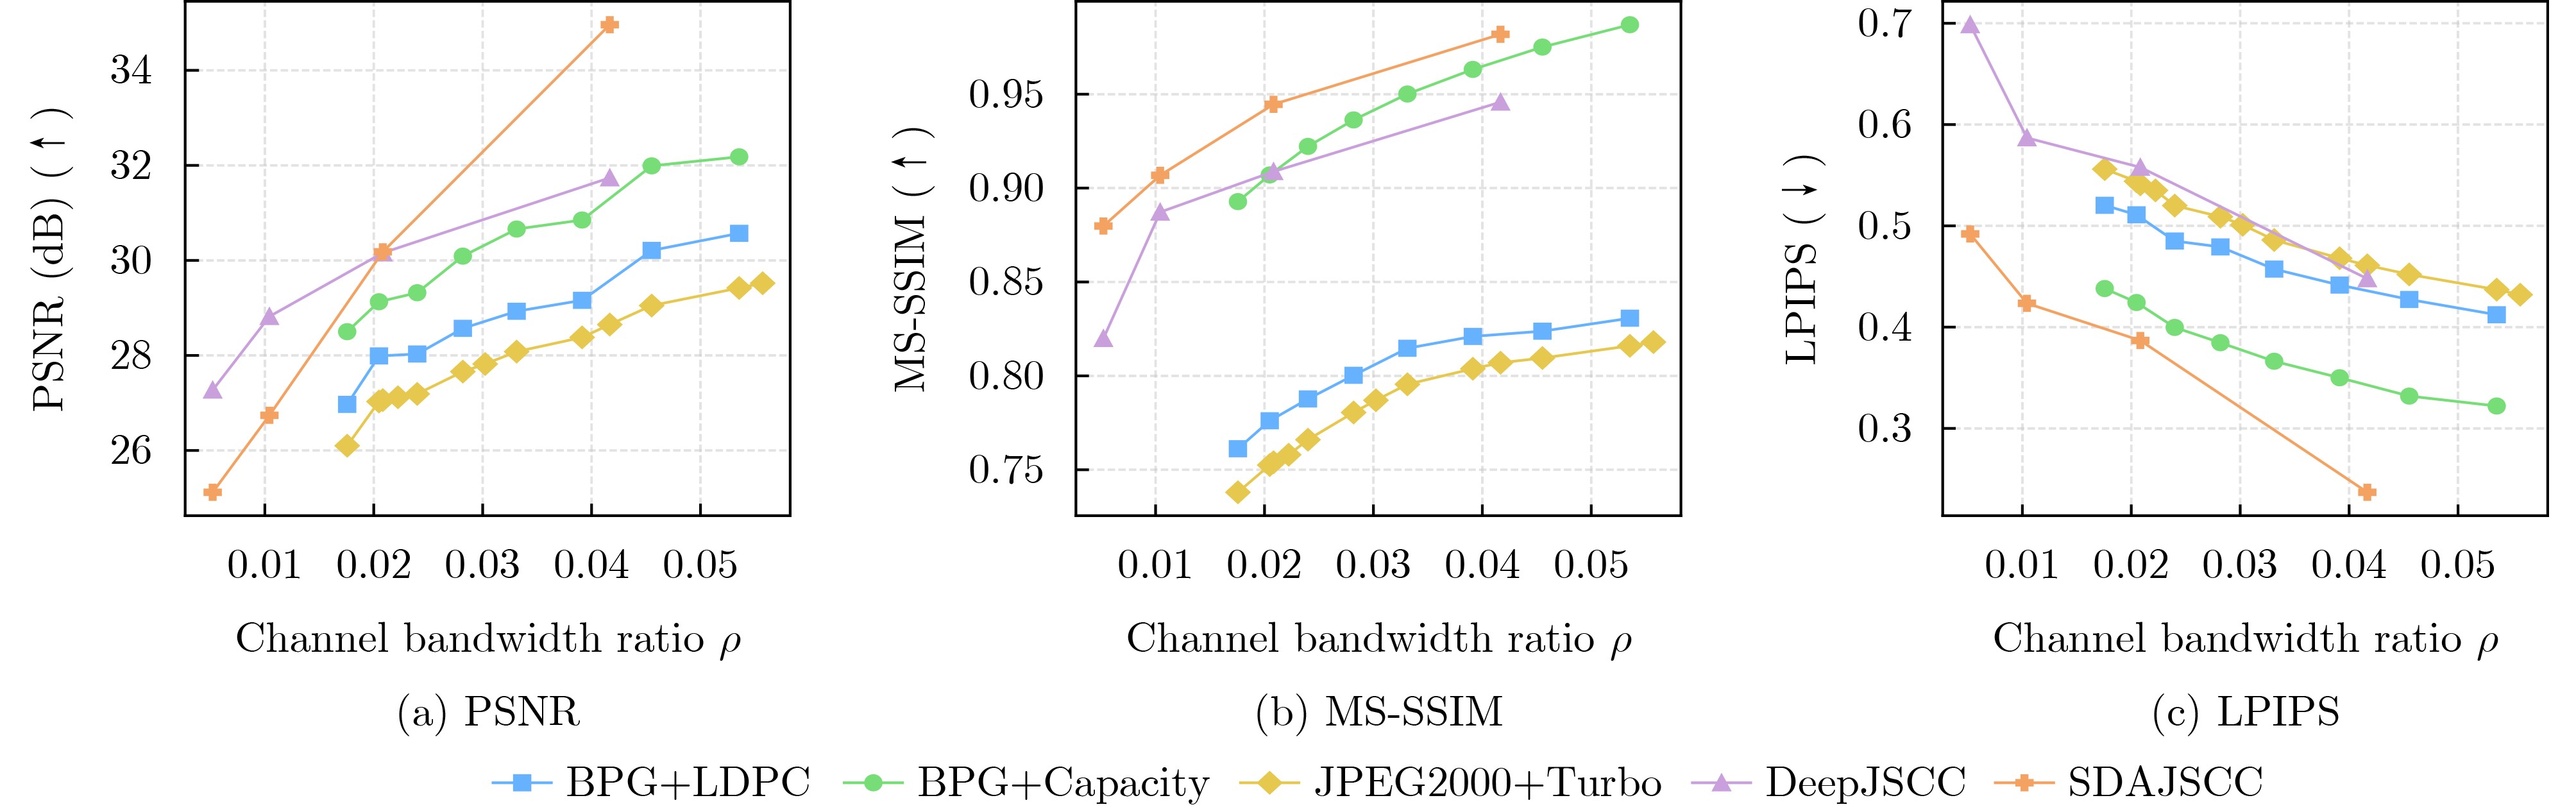
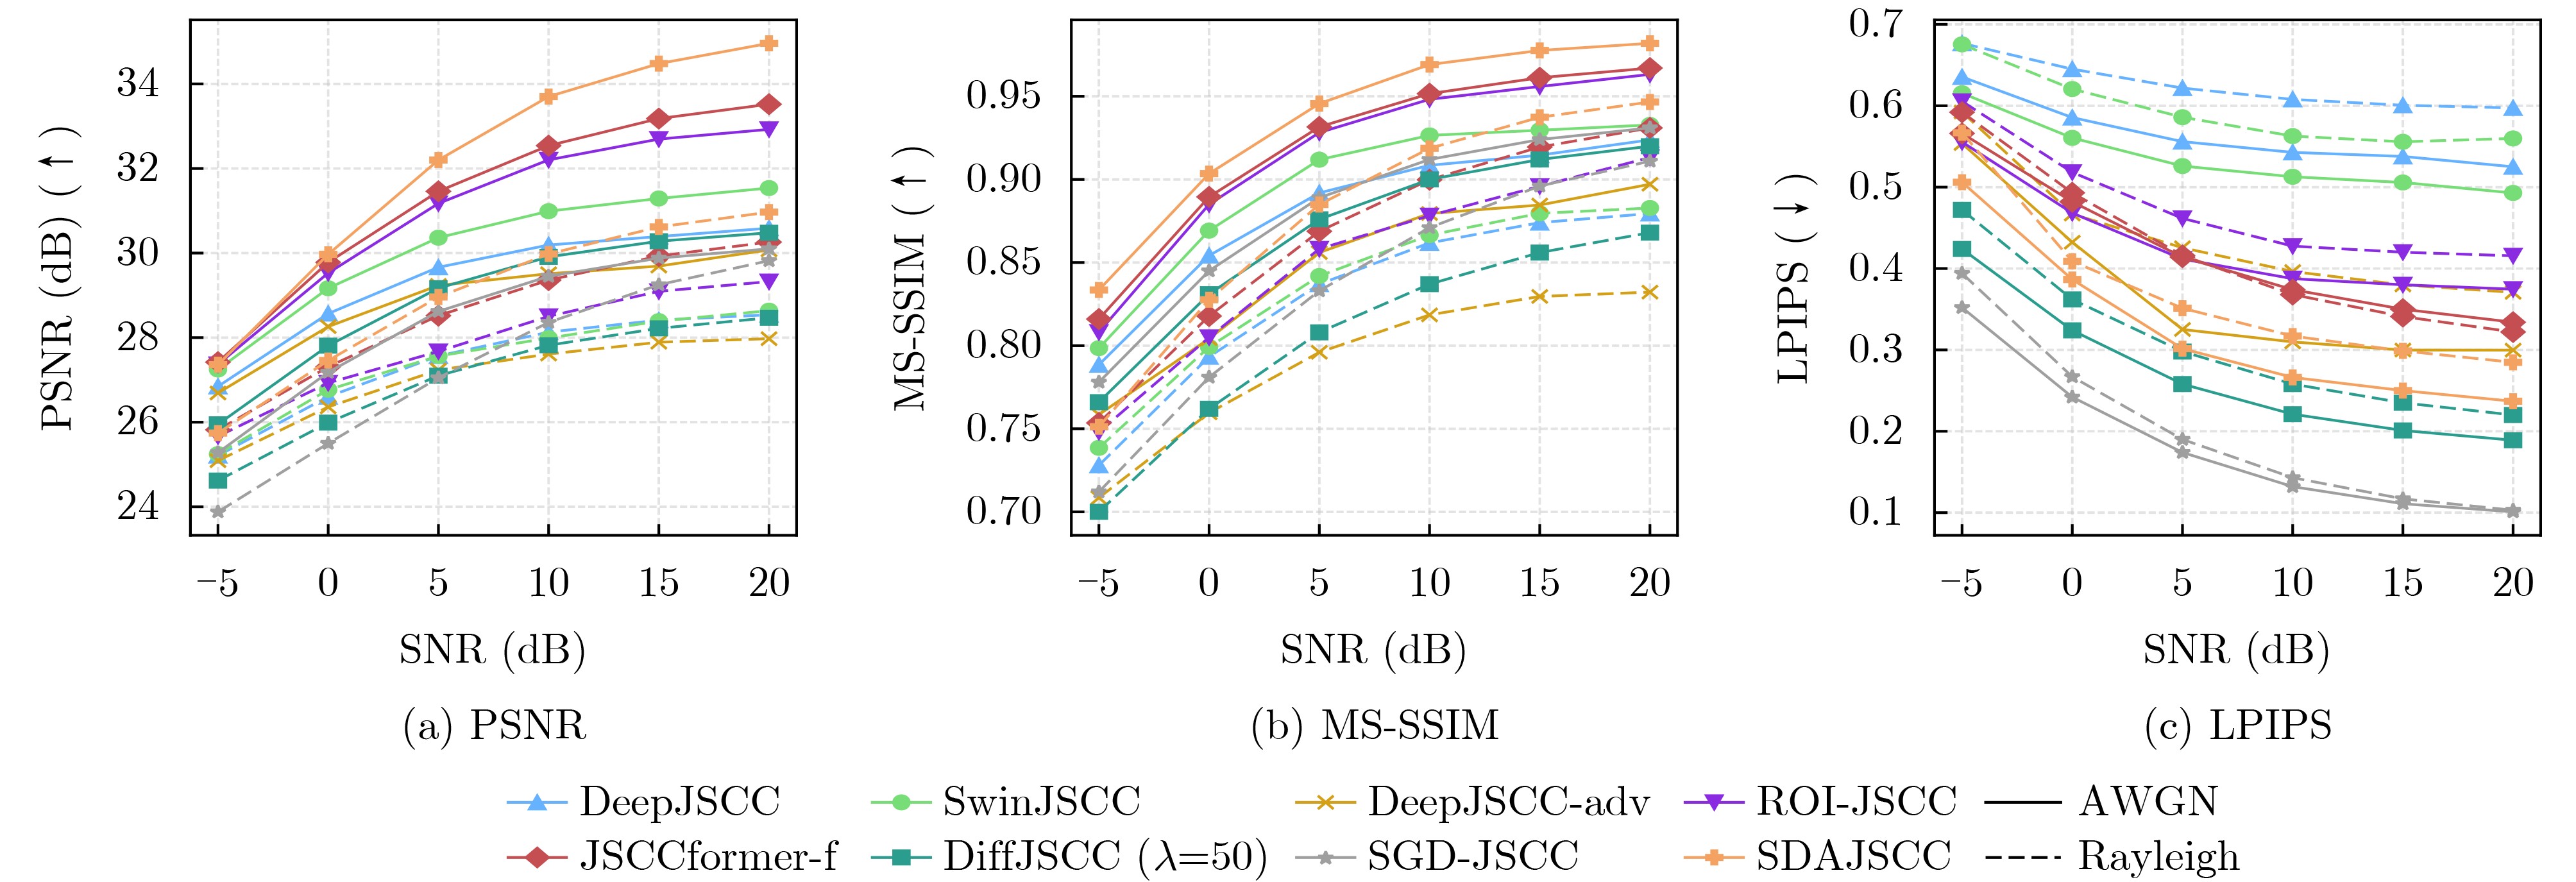
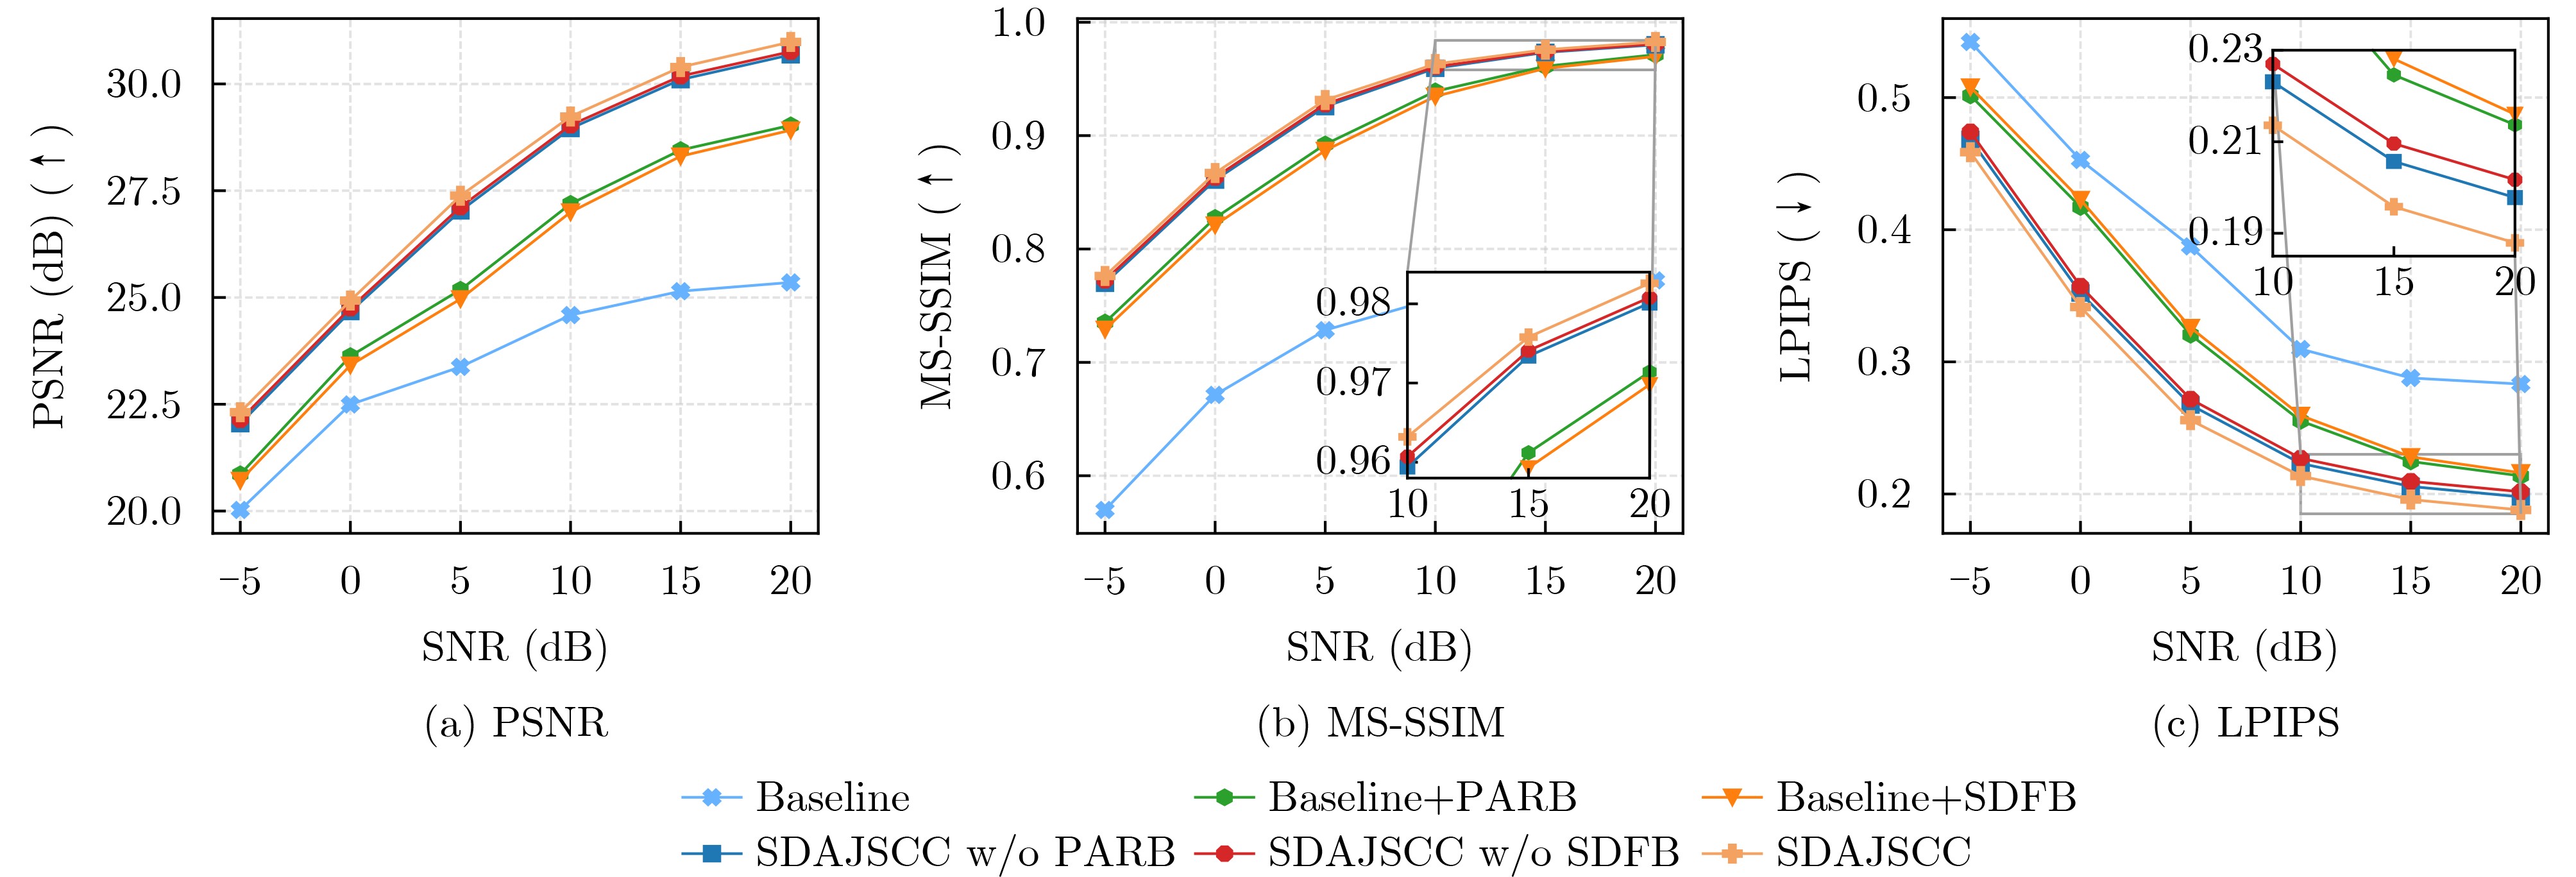
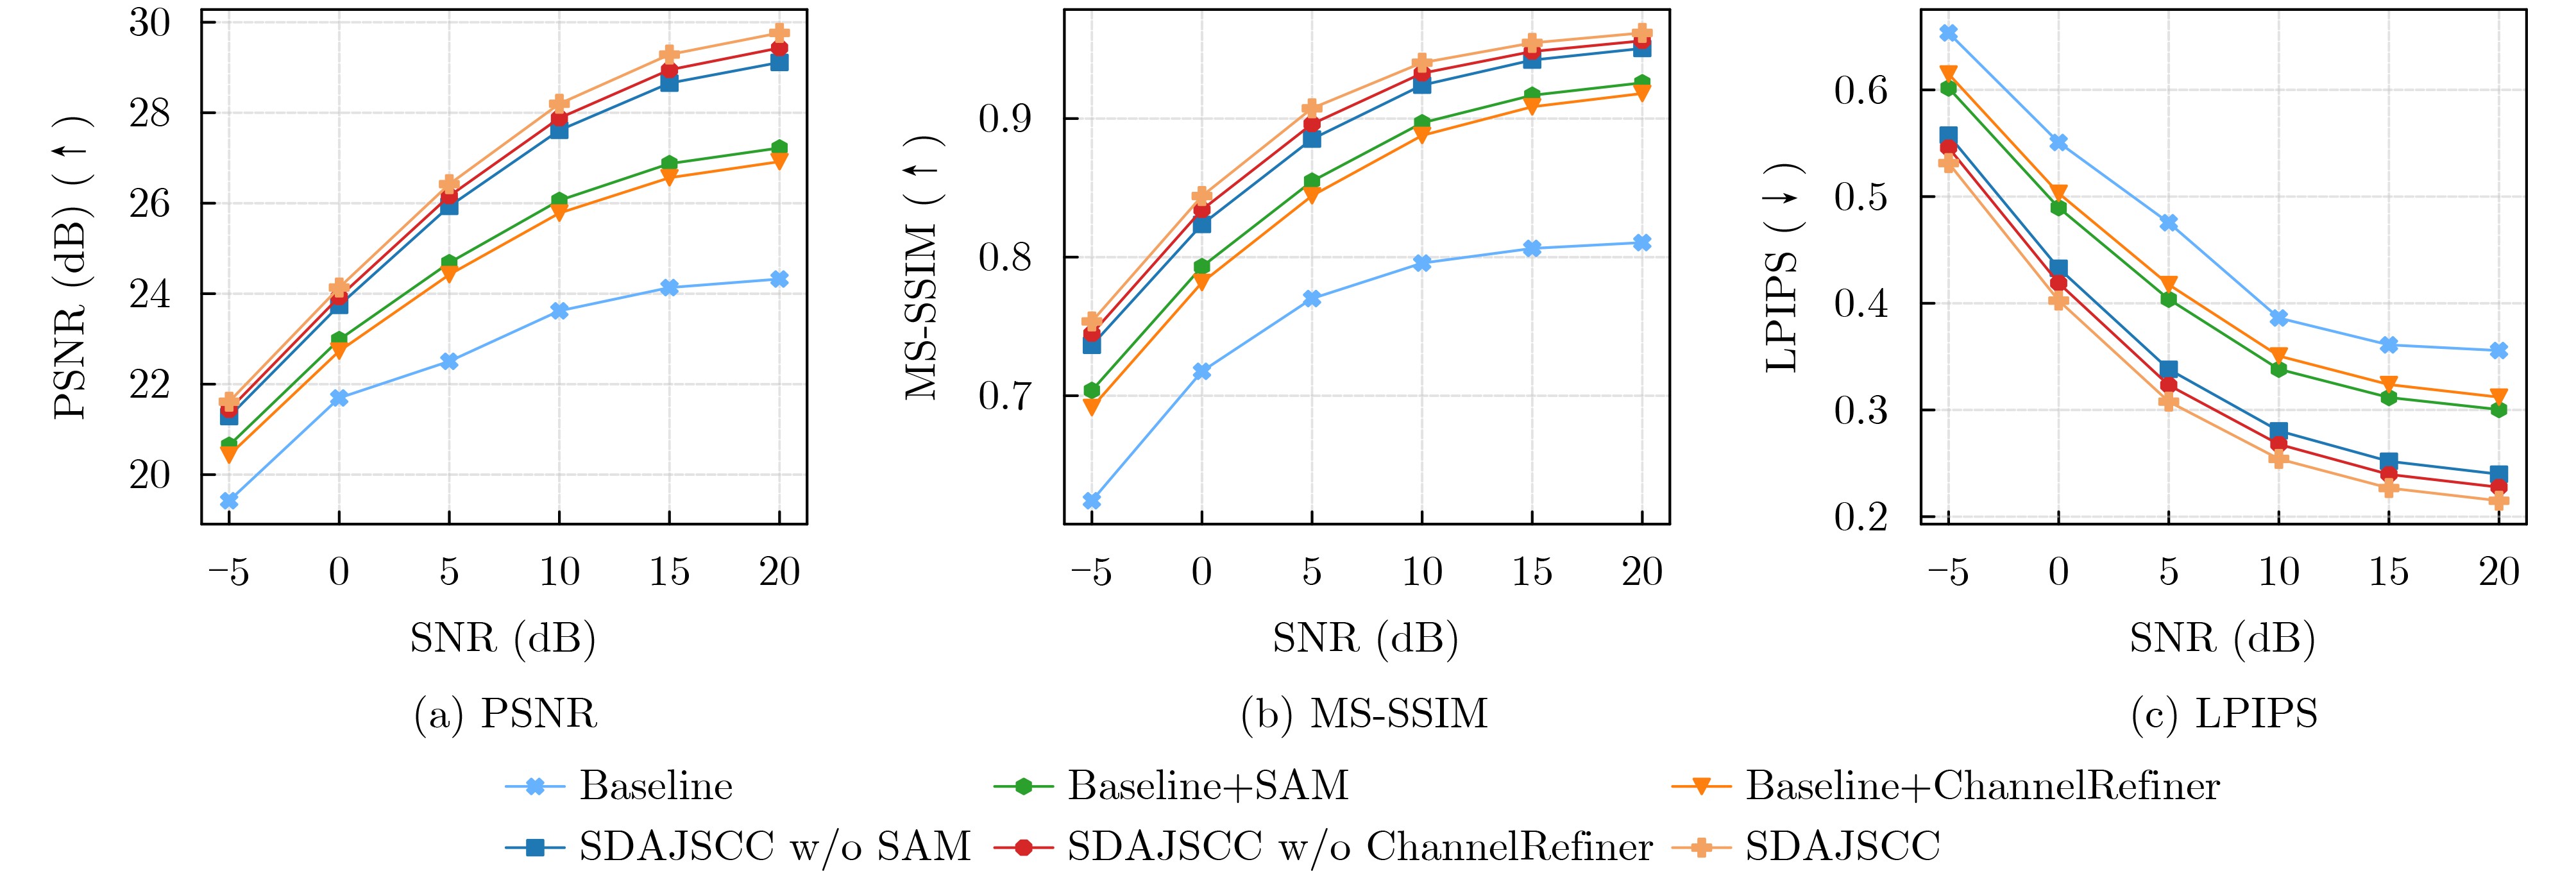
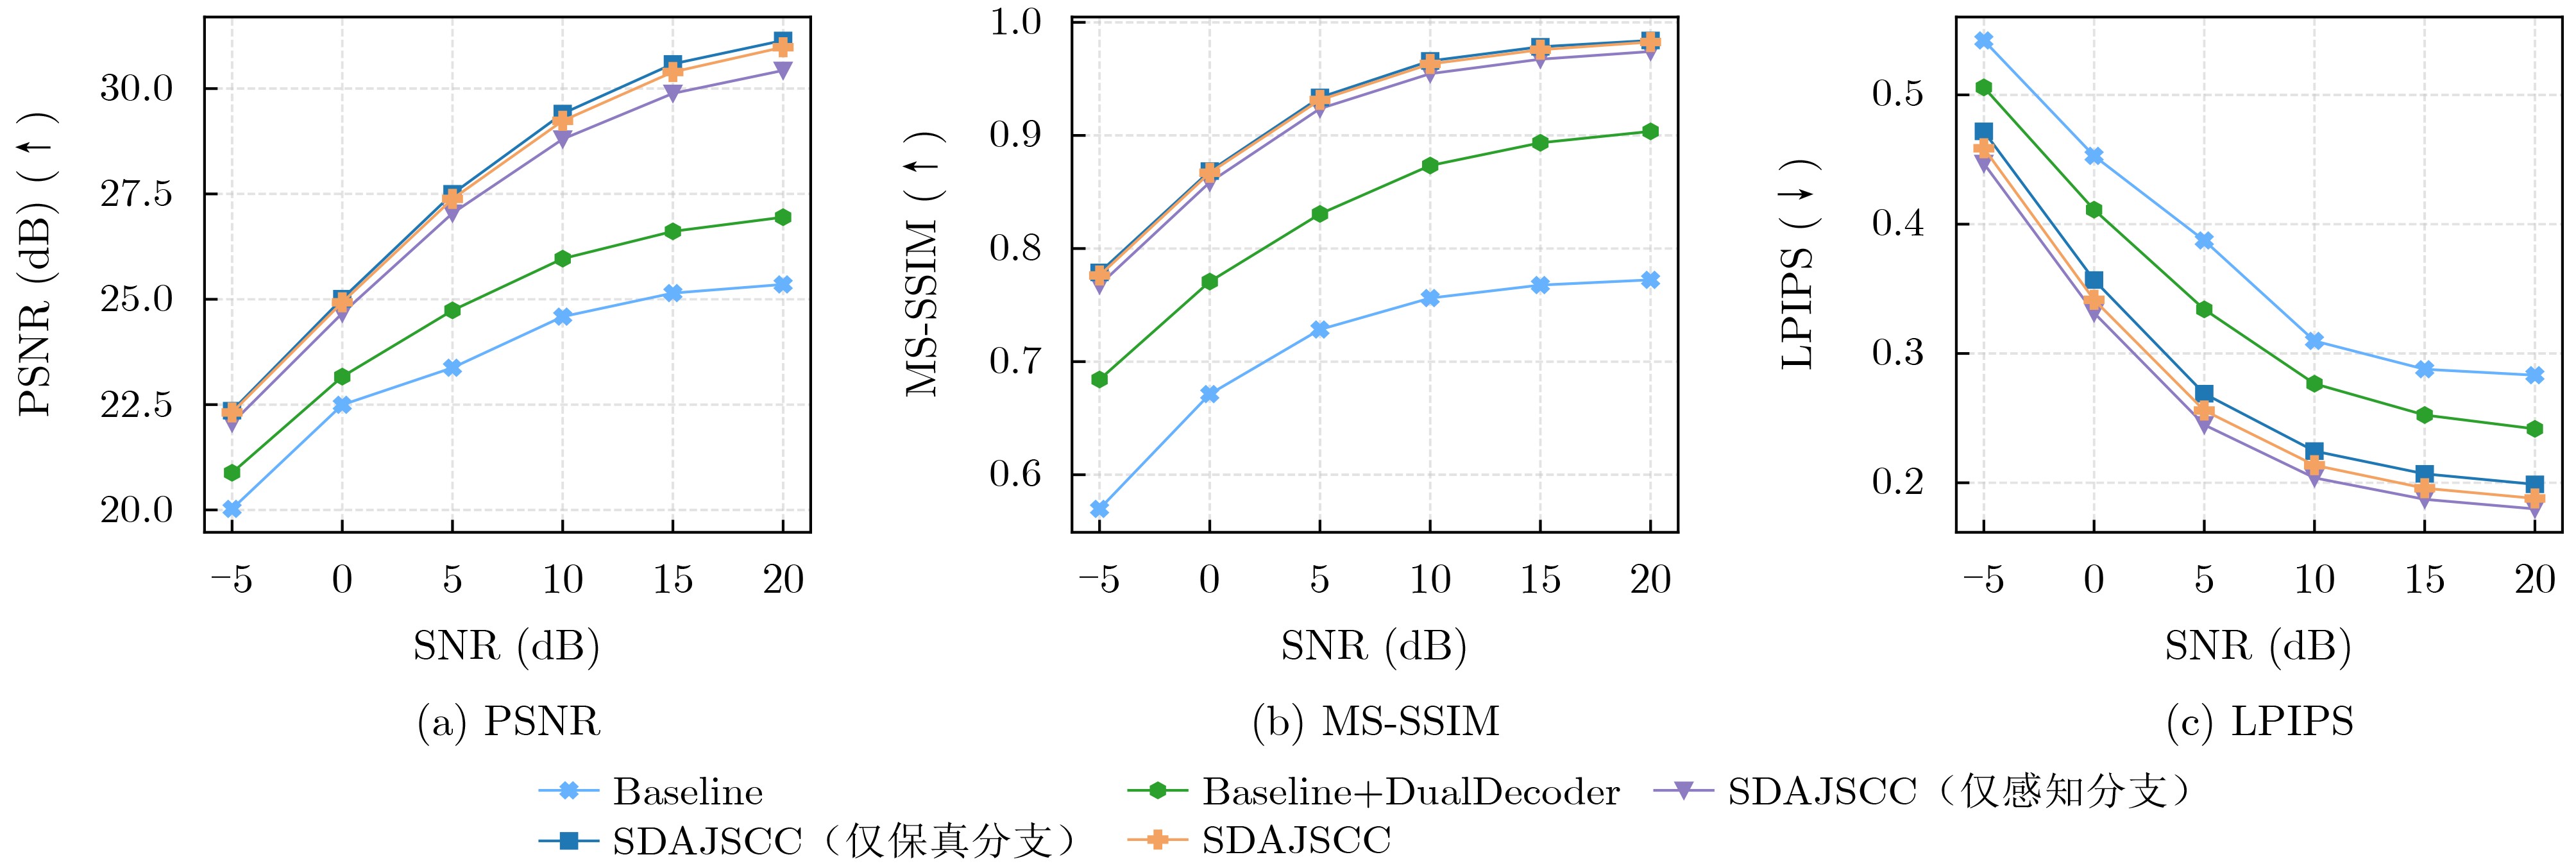
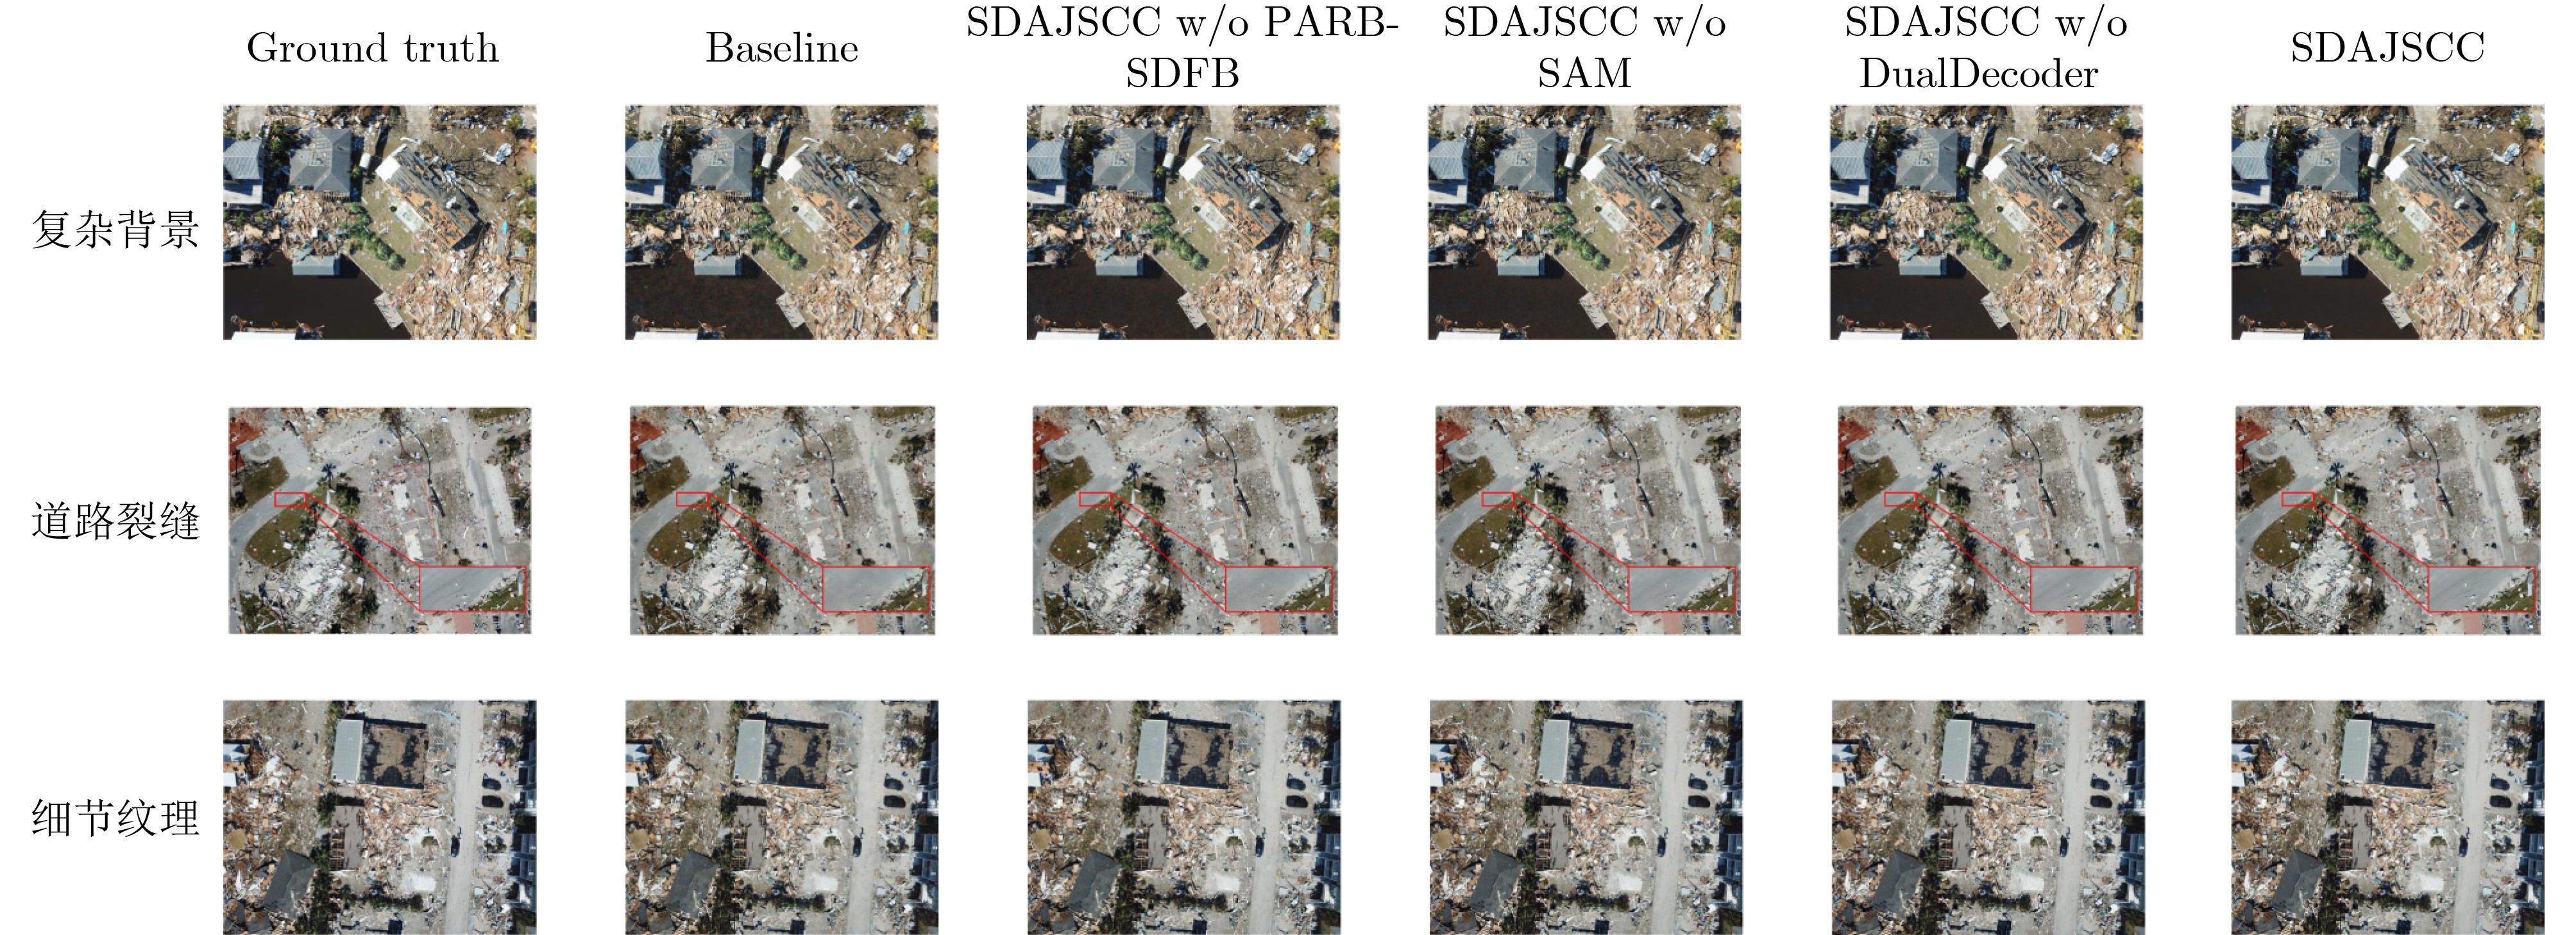
  •   Objective  Unmanned Aerial Vehicles (UAVs) provide flexible and rapid image acquisition for disaster assessment and emergency response. Reliable transmission of the acquired images is essential for interpreting damaged buildings, blocked roads, and other critical scene elements. However, disaster-area communication links are often constrained by limited bandwidth, noise, time-varying fading, and imperfect Channel State Information (CSI). Low-contrast boundaries, narrow cracks, and scattered damaged regions are particularly vulnerable to feature compression and channel distortion. Deep Joint Source-Channel Coding (DeepJSCC) enables image compression and transmission to be jointly optimized, but several limitations remain for disaster imagery. Global pixelwise objectives can assign insufficient importance to sparse weak structures, while feature downsampling can attenuate information that later channel adaptation cannot recover. Channel adaptation also needs to account for both channel conditions and the relative importance of image content. Furthermore, reconstruction must balance pixel fidelity, structural consistency, perceptual quality, and computational cost. This study therefore aims to develop a unified transmission framework that strengthens weak-structure representation, coordinates semantic features with channel conditions, and supports efficient reconstruction of UAV disaster images.  Methods  A Semantic-Driven Adaptive Joint Source-Channel Coding method, termed SDAJSCC, is proposed. Semantic importance is modeled implicitly in the feature domain through multiscale responses, curvature saliency, and channel-spatial attention. The encoder combines a Patch-Aware Residual Block (PARB) with a Semantic Differential Fusion Block (SDFB). PARB aggregates local and regional information at multiple patch scales, while SDFB combines local-global feature interaction with Adaptive Curvature-Guided Attention (ACGA). Curvature information supplements content similarity and relative positional information to strengthen responses to boundaries and structural discontinuities. A Semantic Adaptive Modulation (SAM) module is introduced at multiple encoding stages and at the final latent projection. Channel-dependent affine transformations and channel-spatial attention adjust feature responses using CSI and the Signal-to-Noise Ratio (SNR). This modulation operates before power normalization, allowing the relative responses of latent features to be adjusted while maintaining the average transmit-power constraint. The real-valued latent representation is mapped to complex channel symbols for transmission. At the receiver, regularized zero-forcing equalization limits noise amplification associated with small estimated channel gains. The remaining distortion is analyzed as a combination of signal-dependent mismatch and transformed noise. A ChannelRefiner then combines the equalized latent representation with channel information to predict a gated residual correction and a feature bias. The corrected features are reconstructed by two independently parameterized decoder branches. The fidelity branch emphasizes global structure and pixel consistency, whereas the perceptual branch incorporates a Perceptual Texture Transform Adaptation (PTTA) module. PTTA applies ternary quantization to query and key representations and 6-bit quantization to the value representation, together with a local texture bias. An AdaptiveFusion module predicts the relative contributions of the two reconstructions from their aggregated features and the channel state. All components are jointly trained using a primary reconstruction loss, auxiliary pixelwise supervision for both branches, and a Learned Perceptual Image Patch Similarity (LPIPS) loss. Experiments use xView2 and RescueNet image crops of 256 × 256 pixels. Training covers Additive White Gaussian Noise (AWGN) and Rayleigh fading channels, with SNR uniformly sampled from -5 to 20 dB. AdamW optimization and cosine learning-rate decay are used for 100,000 iterations with a batch size of 16. Evaluation includes Peak Signal-to-Noise Ratio (PSNR), Multi-Scale Structural Similarity (MS-SSIM), LPIPS, critical-region quality, edge preservation, feature similarity, and inference efficiency.  Results and Discussions  The bandwidth comparison on xView2 under AWGN at 20 dB shows improved structural and perceptual preservation under severe compression. At channel bandwidth ratios of 1/192 and 1/96, SDAJSCC has PSNR values 2.15 and 2.08 dB below DeepJSCC, respectively, but increases MS-SSIM by 0.0599 and 0.0196 and reduces LPIPS by 29.6% and 27.8%. At a bandwidth ratio of 1/24, it improves PSNR by 6.31 dB and MS-SSIM by 0.1749 over JPEG2000+Turbo, with a 48.6% reduction in LPIPS. These results indicate a trade-off between pixel fidelity and structural-perceptual preservation at very low bandwidth, followed by gains across all three metrics as bandwidth increases (Fig. 7). At a fixed bandwidth ratio of 1/24 and an SNR of 20 dB, SDAJSCC improves PSNR and MS-SSIM over JSCCFormer-f by 1.44 dB and 0.0149 under AWGN, with a 29.1% reduction in LPIPS. Under Rayleigh fading, the corresponding improvements are 0.708 dB, 0.0156, and an 11.6% reduction in LPIPS. Diffusion-based methods obtain lower LPIPS in some cases, but exhibit lower PSNR and MS-SSIM, demonstrating the need to assess fidelity and perceptual quality together (Fig. 8). Ablation experiments on RescueNet at a bandwidth ratio of 1/24 support the complementary roles of the proposed components. Under AWGN at 20 dB, removing PARB reduces PSNR by 0.300 dB, while removing SDFB increases LPIPS by 0.0138, indicating their respective contributions to reconstruction fidelity and perceptual preservation (Fig. 9). Under Rayleigh fading at 20 dB, removing SAM or ChannelRefiner reduces PSNR by 0.652 or 0.332 dB, respectively, supporting the combination of transmitter-side adaptation and receiver-side correction (Fig. 10). Under AWGN at 20 dB, the complete dual-branch decoder reduces LPIPS by 5.5% relative to the fidelity-only branch, with a PSNR decrease of 0.161 dB, demonstrating an effective fidelity-perception compromise (Fig. 11). For imperfect CSI, the forward-link SNR is fixed at 10 dB under Rayleigh fading, and the CSI estimation SNR is varied independently. At a CSI estimation SNR of 0 dB, SDAJSCC achieves a PSNR of 24.34 dB, an MS-SSIM of 0.817, and an LPIPS of 0.357. Relative to the baseline, PSNR increases by 3.62 dB and LPIPS decreases by 28.2%. Across the tested CSI estimation conditions, ChannelRefiner provides PSNR gains of 0.52-0.57 dB within the complete framework (Table 2). Critical-region evaluation on RescueNet under Rayleigh fading at 10 dB and a bandwidth ratio of 1/24 uses damaged-building and blocked-road annotations to define the evaluation regions. Compared with the Region-of-Interest-Guided method (ROI-JSCC), SDAJSCC improves critical-region PSNR by 0.73 dB and reduces critical-region LPIPS by 14.3%, while increasing edge F1 and high-level feature cosine similarity by 0.035 and 0.032, respectively (Table 3). Qualitative comparisons under AWGN at 20 dB also show clearer road structures, building contours, and local textures in the complete model (Fig. 12). The model contains 29.34 million parameters and requires 18.94 billion floating-point operations per image. With 256 × 256 inputs and a batch size of one on an NVIDIA RTX 4090 Graphics Processing Unit (GPU), its mean inference time is 0.029 s per image, equivalent to approximately 34.5 frames/s. The measurements exclude data loading and preprocessing. Compared with the tested diffusion-based methods using 50 reverse-denoising steps, inference latency decreases by 97.4%-98.5%, although JSCCFormer-f remains faster and less computationally demanding (Table 4).  Conclusions  SDAJSCC integrates multiscale semantic-structural representation, channel-semantic modulation, post-equalization latent correction, and adaptive dual-branch reconstruction within a jointly optimized framework. The experiments support improved preservation of disaster-relevant weak structures and robustness under the tested fading and imperfect-CSI conditions, together with a favorable balance between reconstruction quality and inference efficiency. The low-bandwidth results also identify the remaining trade-off between pixel fidelity and perceptual preservation. The reported processing speed is measured on a desktop GPU, while CSI robustness is evaluated using independent complex Gaussian estimation errors. Future work will investigate model compression, online adaptation to dynamic channels, and generalization to correlated and non-Gaussian CSI errors.
  • loading
  • [1]
    GUO Ziji, LIU Danpu, and ZHANG Zhilong. Perception enhanced multimodal multitask semantic communication and resource management for UAV-assisted ISAC systems[J]. IEEE Transactions on Vehicular Technology, 2026, 75(6): 11051–11065. doi: 10.1109/TVT.2025.3650639.
    [2]
    LU Hao, YUAN Liang, CAO Ning, et al. DRJSCC: Deep joint source-channel coding for fast transmission and reconstruction of UAV disaster images[J]. Digital Signal Processing, 2026, 176: 106083. doi: 10.1016/j.dsp.2026.106083.
    [3]
    KURKA D B and GÜNDÜZ D. Bandwidth-agile image transmission with deep joint source-channel coding[J]. IEEE Transactions on Wireless Communications, 2021, 20(12): 8081–8095. doi: 10.1109/TWC.2021.3090048.
    [4]
    BOURTSOULATZE E, KURKA D B, and GÜNDÜZ D. Deep joint source-channel coding for wireless image transmission[J]. IEEE Transactions on Cognitive Communications and Networking, 2019, 5(3): 567–579. doi: 10.1109/TCCN.2019.2919300.
    [5]
    YANG Mingyu and KIM H S. Deep joint source-channel coding for wireless image transmission with adaptive rate control[C]. ICASSP 2022—2022 IEEE International Conference on Acoustics, Speech and Signal Processing, Singapore, Singapore, 2022: 5193–5197. doi: 10.1109/ICASSP43922.2022.9746335.
    [6]
    WU Haotian, SHAO Yulin, OZFATURA E, et al. Transformer-aided wireless image transmission with channel feedback[J]. IEEE Transactions on Wireless Communications, 2024, 23(9): 11904–11919. doi: 10.1109/TWC.2024.3386052.
    [7]
    WU Haotian, SHAO Yulin, BIAN Chenghong, et al. Deep joint source-channel coding for adaptive image transmission over MIMO channels[J]. IEEE Transactions on Wireless Communications, 2024, 23(10): 15002–15017. doi: 10.1109/TWC.2024.3422794.
    [8]
    YANG Mingyu, BIAN Chenghong, and KIM H S. OFDM-guided deep joint source channel coding for wireless multipath fading channels[J]. IEEE Transactions on Cognitive Communications and Networking, 2022, 8(2): 584–599. doi: 10.1109/TCCN.2022.3151935.
    [9]
    YANG Ke, WANG Sixian, DAI Jincheng, et al. SwinJSCC: Taming Swin transformer for deep joint source-channel coding[J]. IEEE Transactions on Cognitive Communications and Networking, 2025, 11(1): 90–104. doi: 10.1109/TCCN.2024.3424842.
    [10]
    申滨, 李旋, 赖雪冰, 等. 基于Swin Transformer的宽带无线图传语义联合编解码方法[J]. 电子与信息学报, 2025, 47(8): 2665–2674. doi: 10.11999/JEIT250039.

    SHEN Bin, LI Xuan, LAI Xuebing, et al. Swin transformer-based wideband wireless image transmission semantic joint encoding and decoding method[J]. Journal of Electronics & Information Technology, 2025, 47(8): 2665–2674. doi: 10.11999/JEIT250039.
    [11]
    YANG Mingyu, LIU Bowen, WANG Boyang, et al. Diffusion-aided joint source channel coding for high realism wireless image transmission[J]. IEEE Transactions on Machine Learning in Communications and Networking, 2025, 3: 1227–1243. doi: 10.1109/TMLCN.2025.3628535.
    [12]
    TAN Kailin, DAI Jincheng, LIU Zhenyu, et al. Rate-distortion-perception controllable joint source-channel coding for high-fidelity generative semantic communications[J]. IEEE Transactions on Cognitive Communications and Networking, 2025, 11(2): 672–686. doi: 10.1109/TCCN.2024.3511960.
    [13]
    CHOI H and SEO D. Region-of-interest-guided deep joint source–channel coding for image transmission[J]. IEEE Communications Letters, 2026, 30: 392–396. doi: 10.1109/LCOMM.2025.3639610.
    [14]
    YILMAZ S F, NIU Xueyan, BAI Bo, et al. High perceptual quality wireless image delivery with denoising diffusion models[C]. IEEE INFOCOM 2024—IEEE Conference on Computer Communications Workshops, Vancouver, Canada, 2024: 1–5. doi: 10.1109/INFOCOMWKSHPS61880.2024.10620904.
    [15]
    ZHANG Maojun, WU Haotian, ZHU Guangxu, et al. Semantics-guided diffusion for deep joint source-channel coding in wireless image transmission[J]. IEEE Transactions on Wireless Communications, 2026, 25: 1547–1564. doi: 10.1109/TWC.2025.3591456.
    [16]
    王文远, 周明宇, 王朝炜, 等. 面向空天地网络的弹性语义通信[J]. 电子与信息学报, 2025, 47(10): 3646–3657. doi: 10.11999/JEIT250077.

    WANG Wenyuan, ZHOU Mingyu, WANG Chaowei, et al. Resilient semantic communication for space-air-ground networks[J]. Journal of Electronics & Information Technology, 2025, 47(10): 3646–3657. doi: 10.11999/JEIT250077.
    [17]
    张祖凡, 尹星然, 周建萍, 等. 面向语义重要性和鲁棒性的RIS增强语义通信系统[J]. 电子与信息学报, 2025, 47(8): 2608–2620. doi: 10.11999/JEIT250159.

    ZHANG Zufan, YIN Xingran, ZHOU Jianping, et al. RIS-enhanced semantic communication systems oriented towards semantic importance and robustness[J]. Journal of Electronics & Information Technology, 2025, 47(8): 2608–2620. doi: 10.11999/JEIT250159.
    [18]
    陈阳, 马欢, 姬智, 等. 面向图像恢复任务的语义通信网络能耗优化[J]. 电子与信息学报, 2026, 48(1): 183–190. doi: 10.11999/JEIT250915.

    CHEN Yang, MA Huan, JI Zhi, et al. Optimization of energy consumption in semantic communication networks for image recovery tasks[J]. Journal of Electronics & Information Technology, 2026, 48(1): 183–190. doi: 10.11999/JEIT250915.
    [19]
    ZHANG R, ISOLA P, EFROS A A, et al. The unreasonable effectiveness of deep features as a perceptual metric[C]. 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, USA, 2018: 586–595. doi: 10.1109/CVPR.2018.00068.
    [20]
    LIU Ze, LIN Yutong, CAO Yue, et al. Swin transformer: Hierarchical vision transformer using shifted windows[C]. 2021 IEEE/CVF International Conference on Computer Vision, Montreal, Canada, 2021: 9992–10002. doi: 10.1109/ICCV48922.2021.00986.
    [21]
    GUPTA R, GOODMAN B, PATEL N, et al. Creating xBD: A dataset for assessing building damage from satellite imagery[C]. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, Long Beach, USA, 2019: 10–17.
    [22]
    RAHNEMOONFAR M, CHOWDHURY T, and MURPHY R. RescueNet: A high resolution UAV semantic segmentation dataset for natural disaster damage assessment[J]. Scientific Data, 2023, 10(1): 913. doi: 10.1038/s41597-023-02799-4.
    [23]
    WANG Zhou, SIMONCELLI E P, and BOVIK A C. Multiscale structural similarity for image quality assessment[C]. Proceedings of the 37th Asilomar Conference on Signals, Systems & Computers, Pacific Grove, USA, 2003: 1398–1402. doi: 10.1109/ACSSC.2003.1292216.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(12)  / Tables(4)

    Article Metrics

    Article views (39) PDF downloads(14) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return