Advanced Search
Turn off MathJax
Article Contents
XU Sen, DENG Jubiao, XU Xiufang, YAO Shanliang, BIAN Xuesheng, BEN Xianye. A Heterogeneous Multi-View Semantic Fusion Training Method for Text Classification in Low-Resource Scenarios[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260365
Citation: XU Sen, DENG Jubiao, XU Xiufang, YAO Shanliang, BIAN Xuesheng, BEN Xianye. A Heterogeneous Multi-View Semantic Fusion Training Method for Text Classification in Low-Resource Scenarios[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260365

A Heterogeneous Multi-View Semantic Fusion Training Method for Text Classification in Low-Resource Scenarios

doi: 10.11999/JEIT260365 cstr: 32379.14.JEIT260365
Funds:  The National Natural Science Foundation of China (62676350, 52602749, 62301473, 62322111), Jiangsu University Qing Lan Project, Yancheng Industrial Innovation Technology Support (Industrial) Special Program (YCBG2025201), The Natural Science Foundation of Heilongjiang Province (ZD2025F004)
  • Received Date: 2026-03-30
  • Accepted Date: 2026-08-17
  • Rev Recd Date: 2026-08-17
  • Available Online: 2026-08-26
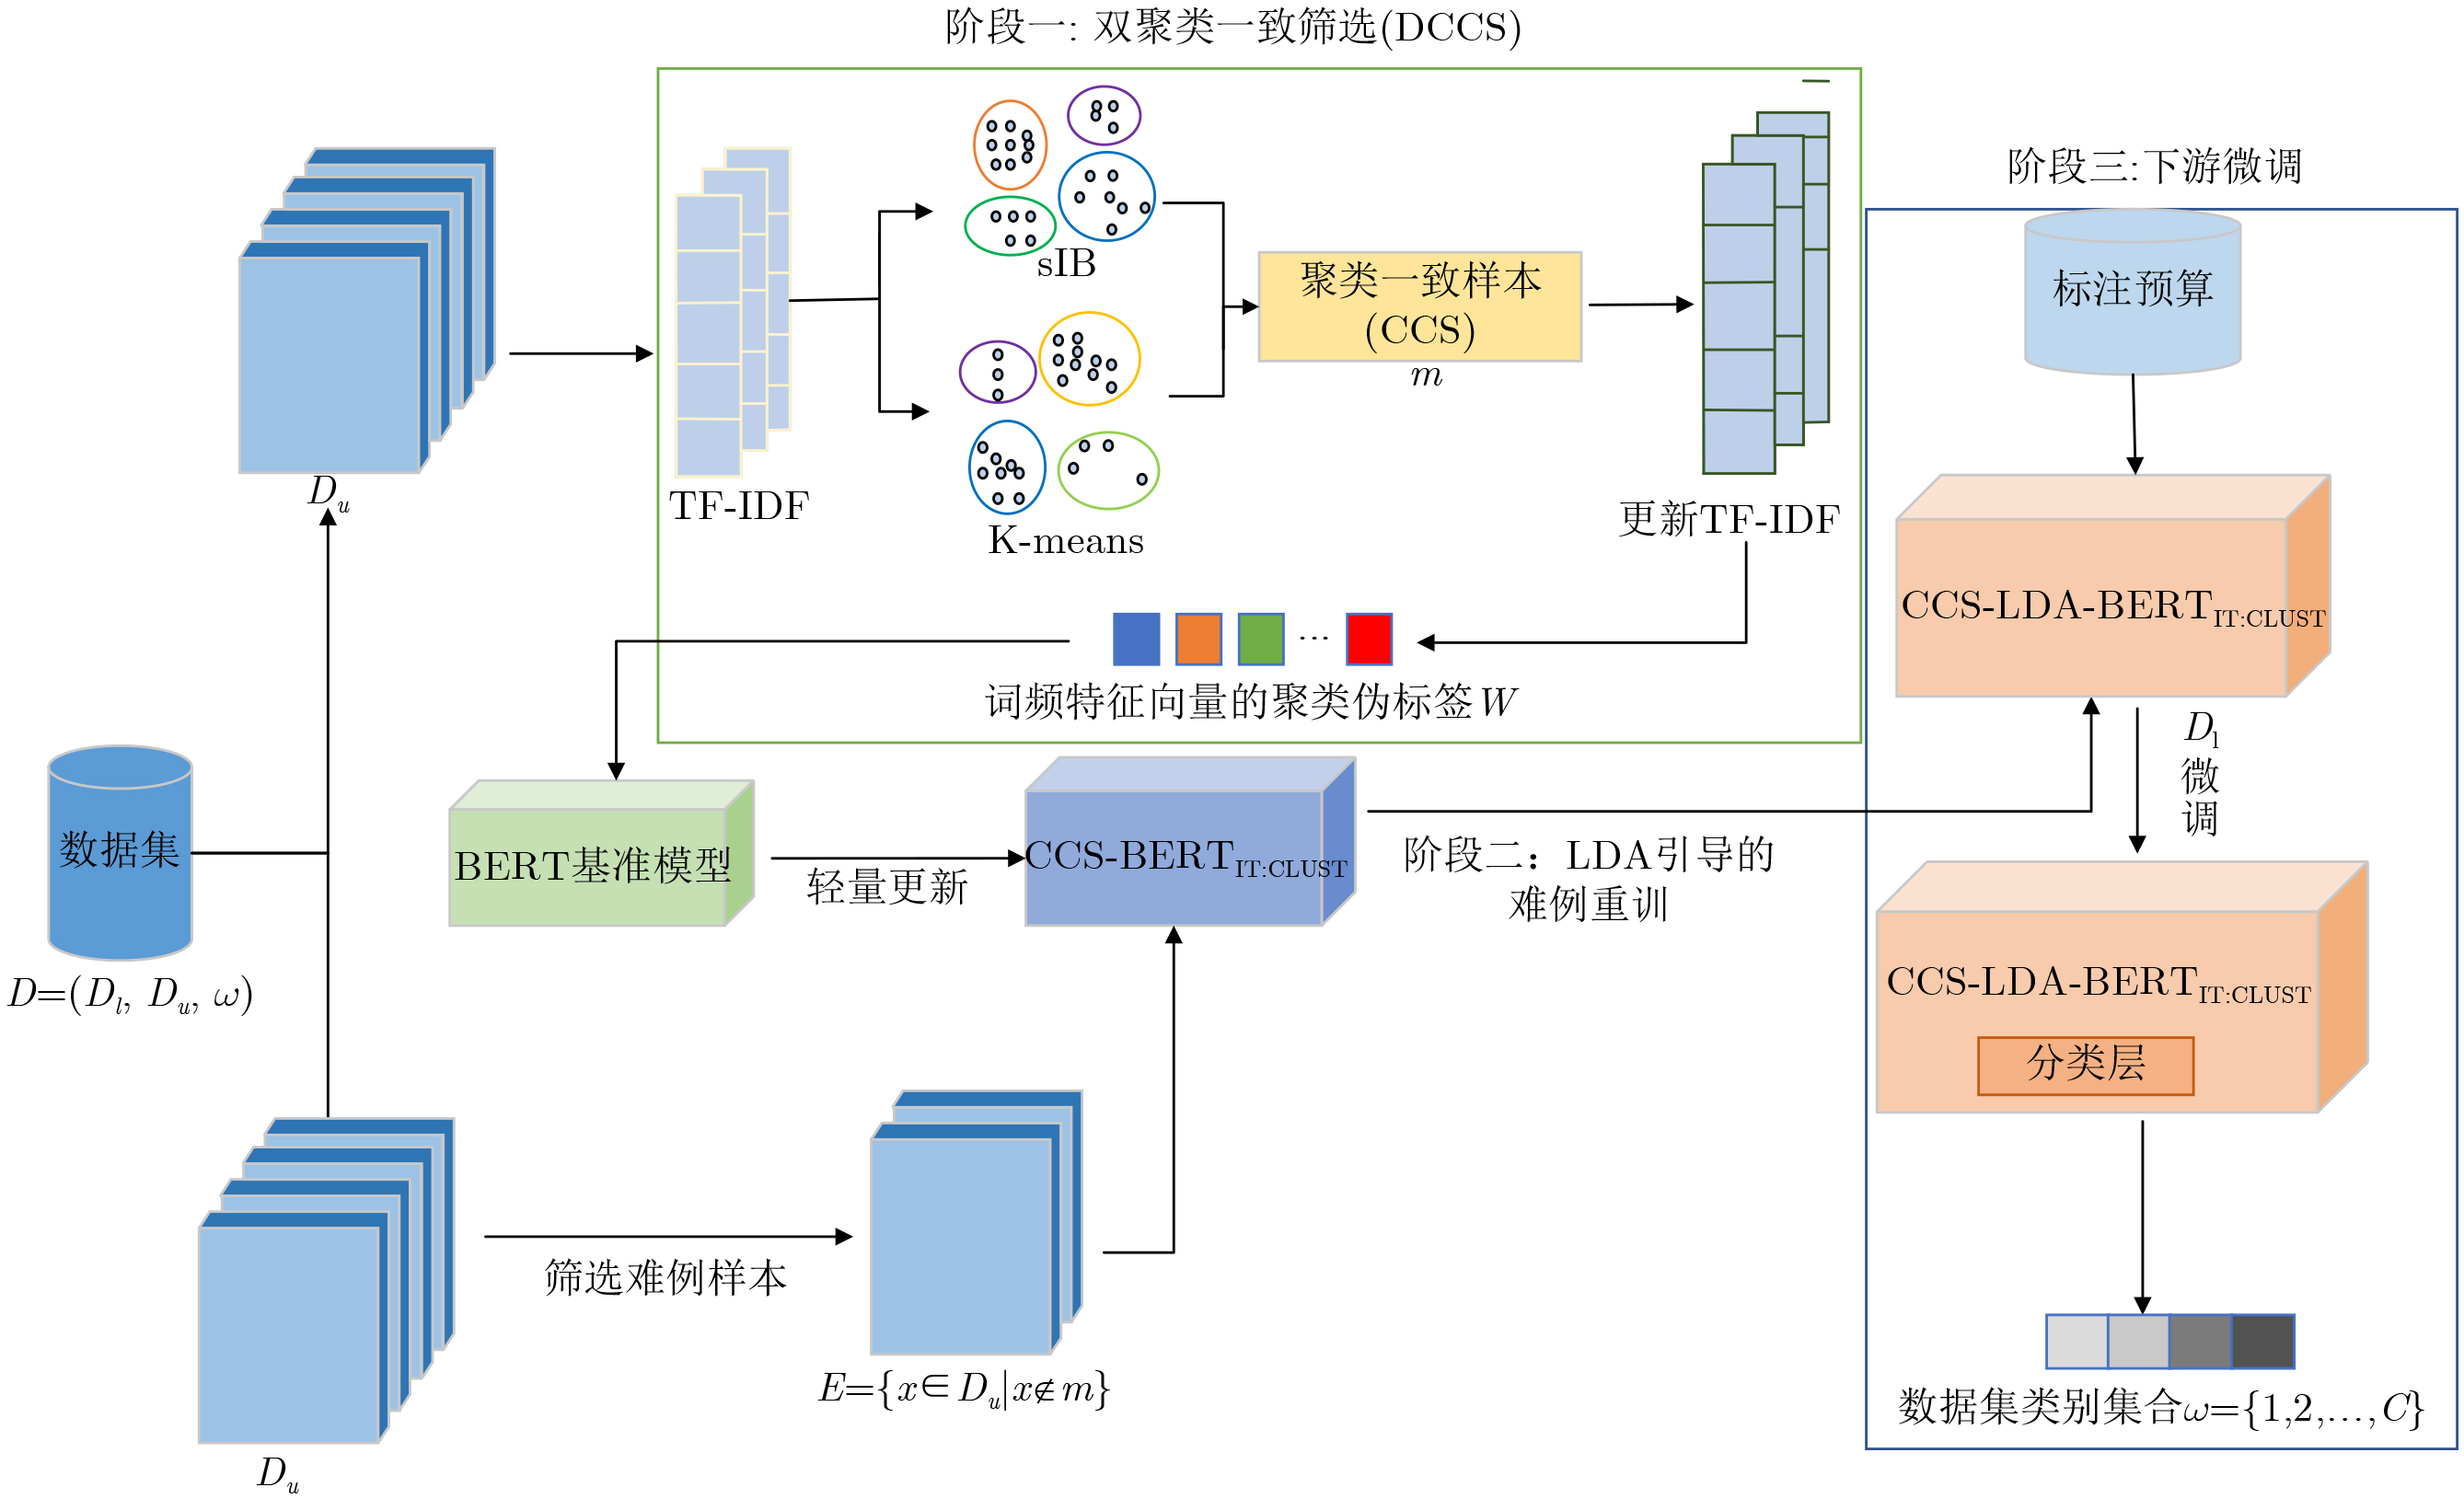
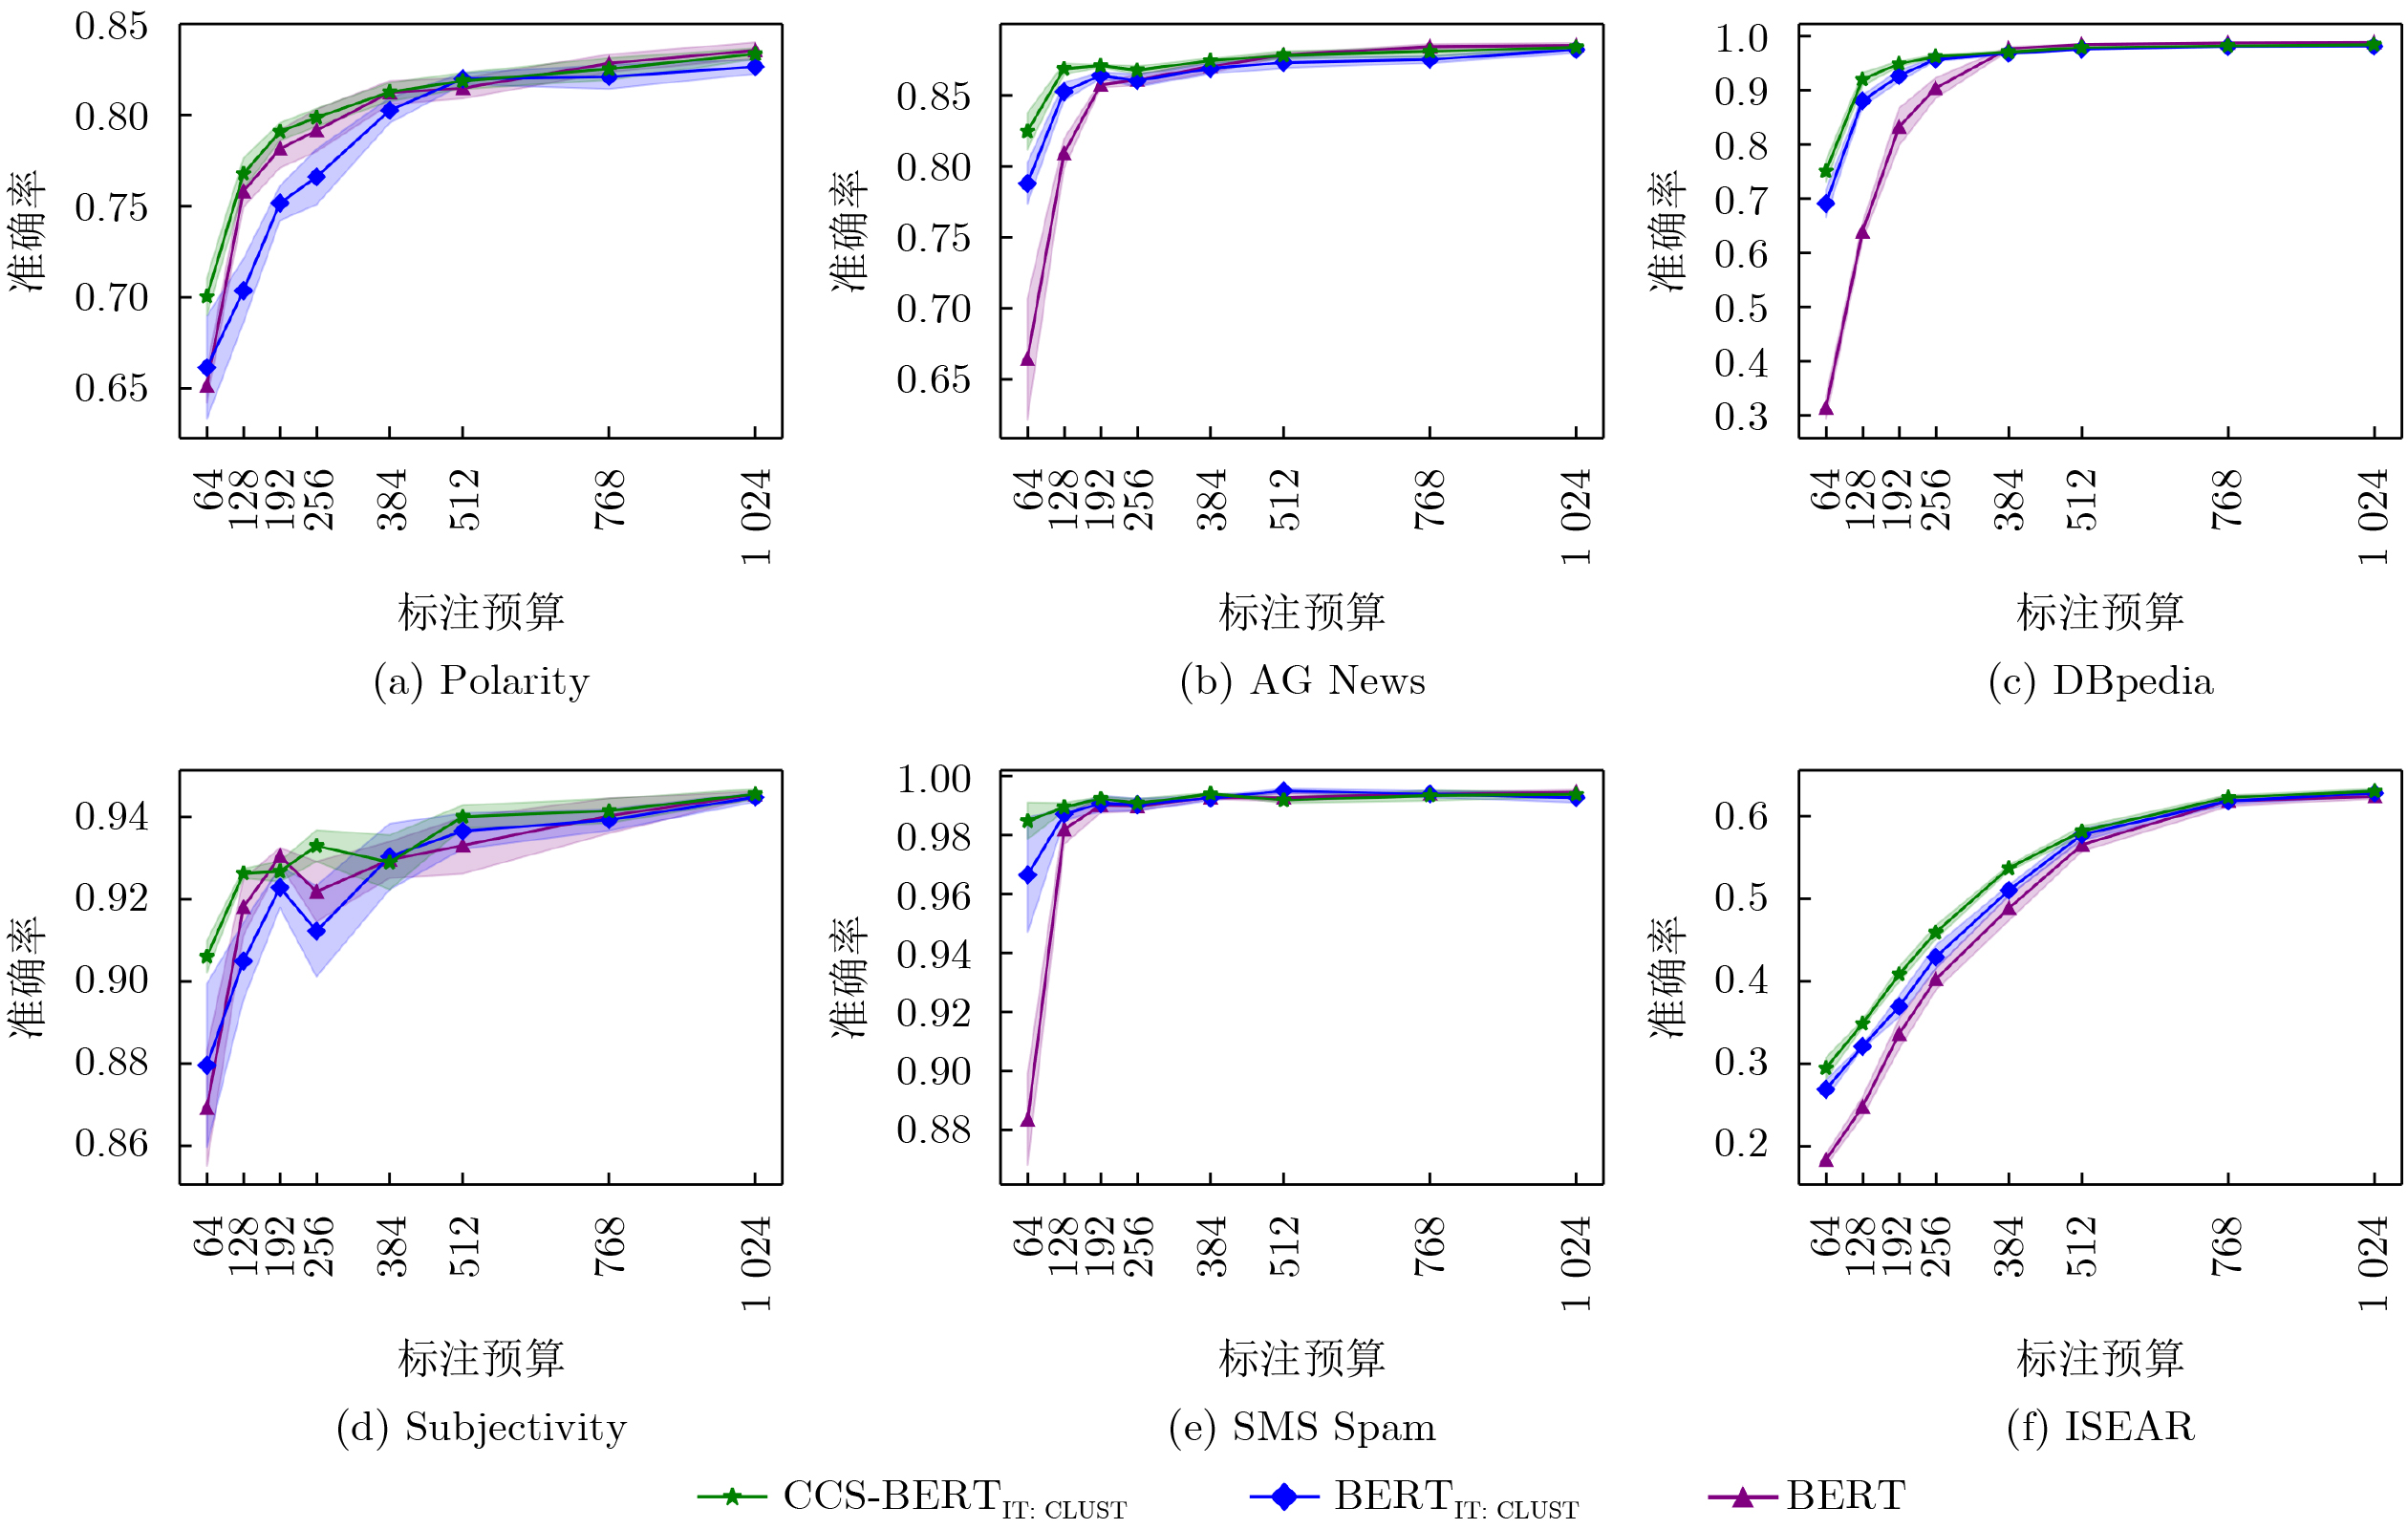
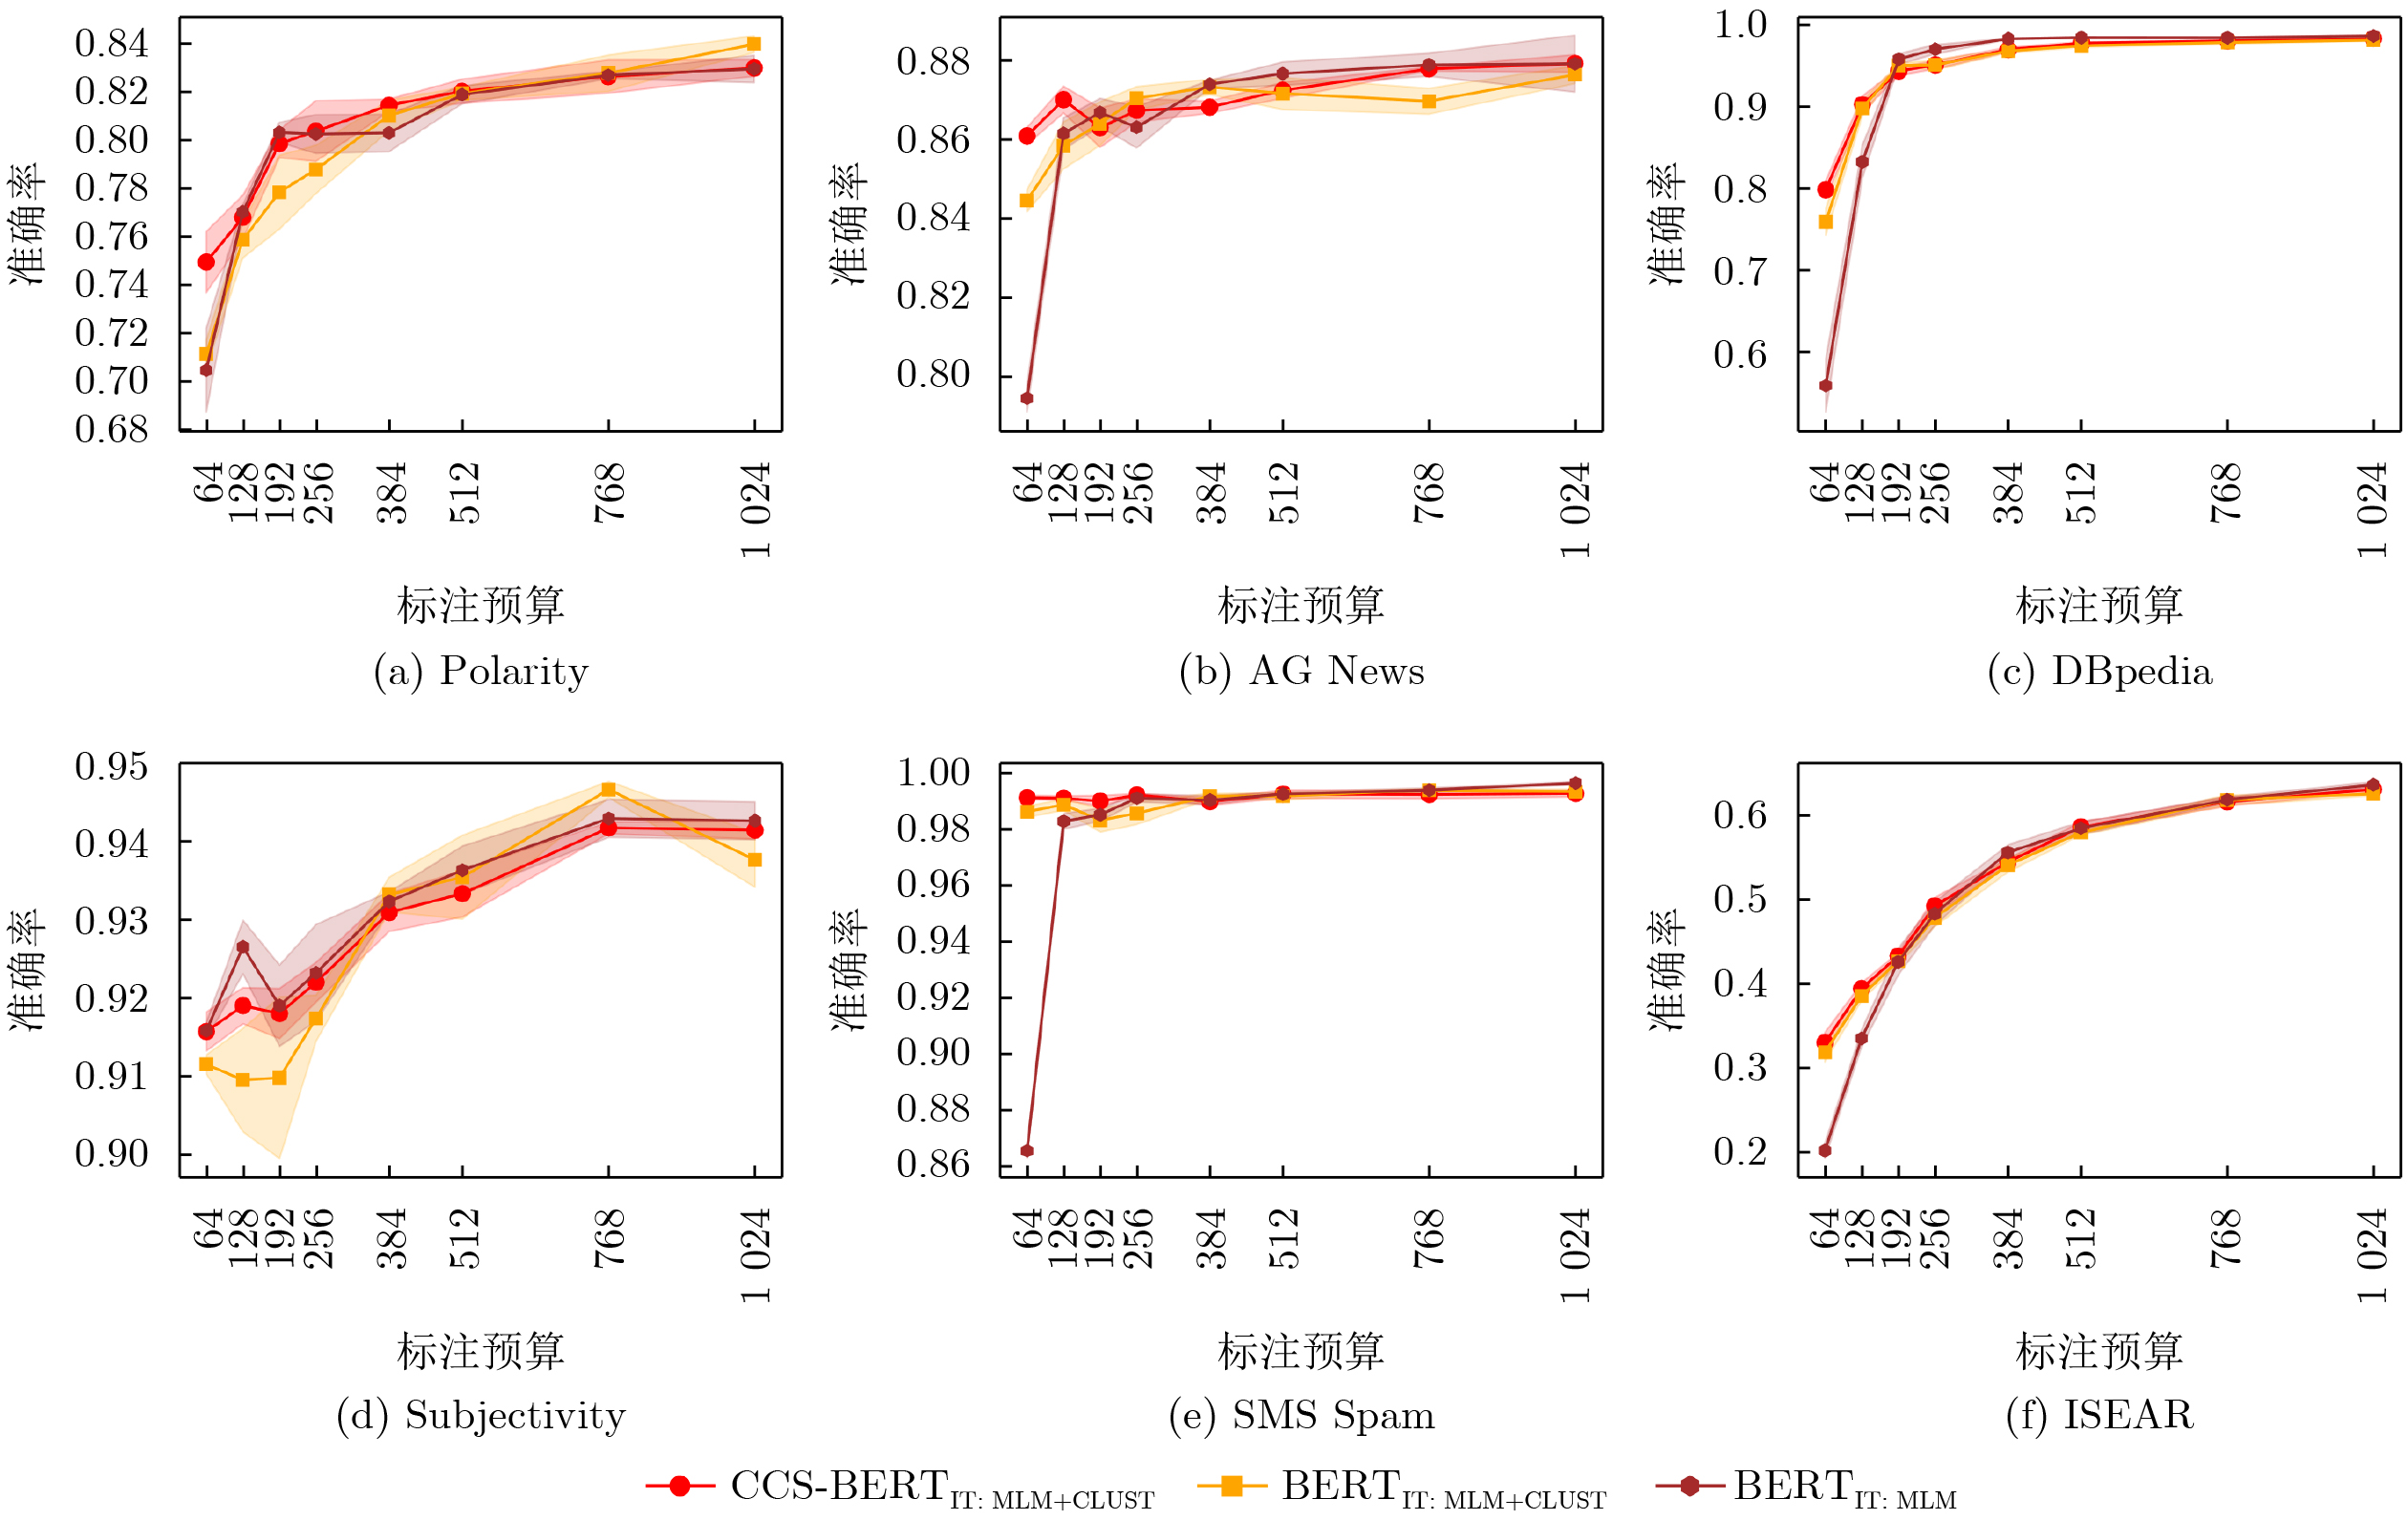
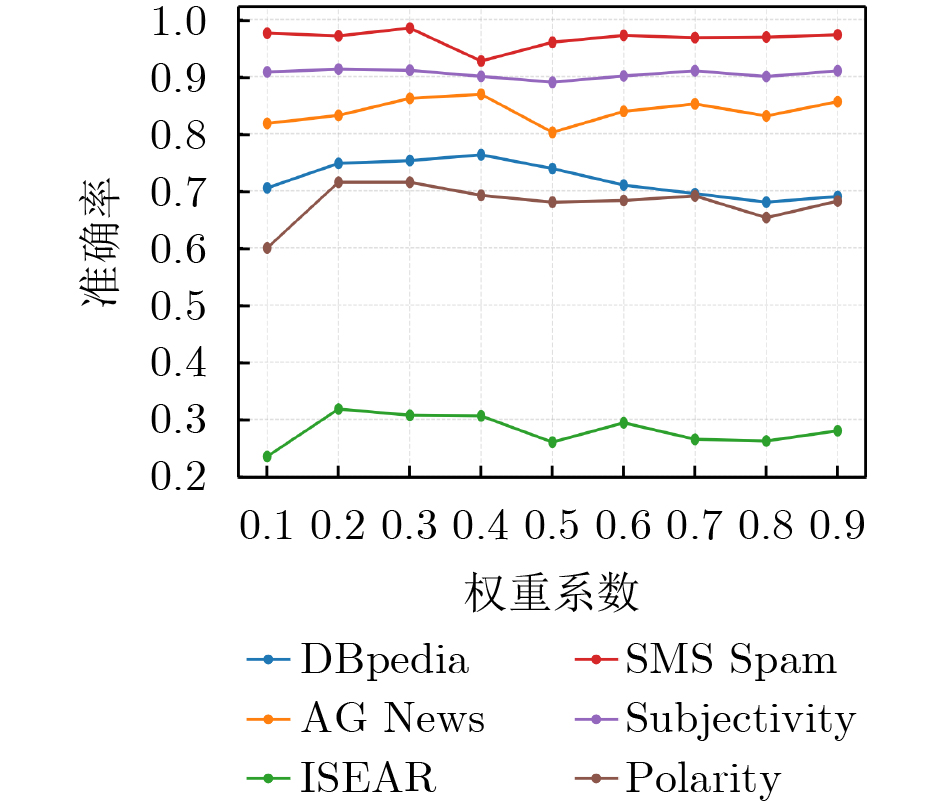
  •   Objective  The increasing demand for text classification in specialized domains, such as finance, healthcare, and social media, is often hindered by the scarcity of labeled data. Data-scarce scenarios significantly limit the effectiveness of conventional supervised learning and pre-trained language models, such as BERT, because of insufficient task-specific supervision. Existing methods that rely on single-view weak supervision or clustering often generate noisy pseudo-labels and fail to fully exploit the discriminative potential of hard examples. Therefore, a robust training method is needed to leverage unlabeled data, reduce sensitivity to noise, and enhance semantic representation under low-label conditions. This study proposes a text classification training method specifically designed for data-scarce scenarios.  Methods  A Heterogeneous Multi-View Semantic Fusion Training Method for Text Classification (HMVSF) is proposed to address these challenges. HMVSF consists of three main stages. (1) Dual Clustering Consistency Screening (DCCS): Text samples are first represented in the word-frequency view using TF-IDF vectors. Two heterogeneous clustering algorithms, sIB and an improved K-means initialized via a genetic algorithm, are applied to the same feature space. Samples consistently assigned to intersecting clusters are selected as high-confidence pseudo-labeled instances. These samples are then used for a lightweight supervised update of the shared encoder to provide a reliable initialization for subsequent training. (2) Latent Dirichlet Allocation (LDA)-Guided Hard-Example Retraining: The remaining hard examples, which are not selected in the first stage, typically exhibit low discriminability in the word-frequency view but retain global semantic and topic-level information. LDA is used to model their topic distributions. The optimal number of topics is adaptively determined using semantic coherence and statistical criteria. Hard and soft pseudo-labels are generated from the document-topic distributions. The model is then retrained using a combination of cross-entropy and symmetric KL divergence losses to integrate topic-level semantic information. (3) Downstream Fine-Tuning: The encoder is finally fine-tuned on a small labeled set by replacing the temporary heads with a task-specific classification head. Standard cross-entropy is used as the objective. The two-stage intermediate training is independent of the pre-training initialization, allowing HMVSF to be applied to both general-purpose BERT and Masked Language Model (MLM)-based initializations.  Results and Discussions  The effectiveness of HMVSF is evaluated on six publicly available datasets, including DBpedia, AGNews, ISEAR, SMS Spam, Subjectivity, and Polarity, covering both topic-based and non-topic-based text classification tasks. Two initialization routes are tested: Route A (BERT/BERTIT:CLUST) and Route B (BERTIT:MLM/BERTIT:MLM+CLUST). Under extremely low label budgets, such as 64 labeled samples, CCS-BERTIT:CLUST and CCS-BERTIT:MLM+CLUST outperform the baseline models and single-stage variants across the datasets (Figs. 2–3, Tables 2–3). For instance, in Route A, CCS-BERTIT:CLUST achieves accuracy gains of 8% on DBpedia and 9% on ISEAR compared with BERTIT:CLUST, while error rates decrease by 10–54% (Table 2). Normalized Mutual Information (NMI) and intra-cluster Euclidean distance analyses confirm that CCS selection produces stable and compact clusters, providing reliable pseudo-labels (Tables 4–5). Ablation experiments show that the two-stage design combining CCS and LDA outperforms the single-stage variants. The two components provide complementary benefits: CCS provides high-confidence core samples, whereas LDA captures latent semantic structures in hard examples (Table 7). Parameter analysis shows that the model remains robust across a wide range of cluster numbers and LDA weighting coefficients, with stable performance when the LDA weighting coefficient is set to 0.3 (Figs. 4–5). HMVSF also maintains competitive performance as the number of labeled samples increases. Computational experiments on an NVIDIA A40 GPU show that the two-stage intermediate training introduces acceptable additional computational overhead while improving representation quality and overall accuracy.  Conclusions  HMVSF provides a heterogeneous multi-view semantic fusion training method for data-scarce text classification. By integrating cluster-consistent sample screening in the word-frequency view with LDA-guided hard-example retraining, HMVSF effectively leverages unlabeled data, reduces pseudo-label noise, and enriches semantic representations. Extensive experiments across multiple datasets confirm that HMVSF improves classification accuracy under low-label conditions while remaining robust to different pre-training initializations. The method can be applied to various pre-trained language models and provides an effective and practical solution for text classification in data-scarce scenarios.
  • loading
  • [1]
    WANG Kunze, DING Yihao, and HAN S C. Graph neural networks for text classification: A survey[J]. Artificial Intelligence Review, 2024, 57(8): 190. doi: 10.1007/s10462-024-10808-0.
    [2]
    DEVLIN J, CHANG M W, LEE K, et al. BERT: Pre-training of deep bidirectional transformers for language understanding[C]. The 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Minneapolis, Minnesota, 2019: 4171–4186. doi: 10.18653/v1/N19-1423.
    [3]
    NI Shiwen and KAO H Y. KPT++: Refined knowledgeable prompt tuning for few-shot text classification[J]. Knowledge-Based Systems, 2023, 274: 110647. doi: 10.1016/j.knosys.2023.110647.
    [4]
    WANG Yimeng, YANG Zhiyao, and CHE Xiangjiu. A hierarchical mixture-of-experts framework for few labeled node classification[J]. Neural Networks, 2025, 188: 107285. doi: 10.1016/j.neunet.2025.107285.
    [5]
    CUI Yiming, CHE Wanxiang, LIU Ting, et al. Pre-training with whole word masking for Chinese BERT[J]. IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2021, 29: 3504–3514. doi: 10.1109/TASLP.2021.3124365.
    [6]
    SHNARCH E, GERA A, HALFON A, et al. Cluster & tune: Boost cold start performance in text classification[C]. The 60th Annual Meeting of the Association for Computational Linguistics, Dublin, Ireland, 2022: 7639–7653. doi: 10.18653/v1/2022.acl-long.526.
    [7]
    YU Tao, SONG Rui, PINTO S, et al. GEML: A graph-enhanced pre-trained language model framework for text classification via mutual learning[J]. Applied Intelligence, 2024, 54(23): 12215–12229. doi: 10.1007/s10489-024-05831-1.
    [8]
    CHEN Junfan, ZHANG Richong, ZHENG Yaowei, et al. DualCL: Principled supervised contrastive learning as mutual information maximization for text classification[C]. The ACM Web Conference 2024, Singapore, 2024: 4362–4371. doi: 10.1145/3589334.3645668.
    [9]
    ZHOU Nai, YAO Nianmin, HU Nannan, et al. CDGAN-BERT: Adversarial constraint and diversity discriminator for semi-supervised text classification[J]. Knowledge-Based Systems, 2024, 284: 111291. doi: 10.1016/j.knosys.2023.111291.
    [10]
    ZOU Haochen and WANG Zitao. A semi-supervised short text sentiment classification method based on improved bert model from unlabelled data[J]. Journal of Big Data, 2023, 10(1): 35. doi: 10.1186/s40537-023-00710-x.
    [11]
    LI Shujie, YUAN Guanghu, YANG Min, et al. Improving semi-supervised text classification with dual meta-learning[J]. ACM Transactions on Information Systems, 2024, 42(4): 109. doi: 10.1145/3648612.
    [12]
    LIAO Wenxiong, LIU Zhengliang, DAI Haixing, et al. Mask-guided BERT for few-shot text classification[J]. Neurocomputing, 2024, 610: 128576. doi: 10.1016/j.neucom.2024.128576.
    [13]
    HOU Zejiang, SALAZAR J, and POLOVETS G. Meta-learning the difference: Preparing large language models for efficient adaptation[J]. Transactions of the Association for Computational Linguistics, 2022, 10: 1249–1265. doi: 10.1162/tacl_a_00517.
    [14]
    HE Kai, MAO Rui, HUANG Yucheng, et al. Template-free prompting for few-shot named entity recognition via semantic-enhanced contrastive learning[J]. IEEE transactions on Neural Networks and Learning Systems, 2024, 35(12): 18357–18369. doi: 10.1109/TNNLS.2023.3314807.
    [15]
    李俊辉, 侯兴松. 基于伪监督注意力短期记忆与多尺度去伪影网络的图像分块压缩感知[J]. 电子与信息学报, 2024, 46(2): 472–480. doi: 10.11999/JEIT231069.

    LI Junhui and HOU Xingsong. Pseudo supervised attention short-term memory and multi-scale deartifacting network based on image block compressed sensing[J]. Journal of Electronics & Information Technology, 2024, 46(2): 472–480. doi: 10.11999/JEIT231069.
    [16]
    CHU Yonghe, CAO Heling, DIAO Yufeng, et al. Refined SBERT: Representing sentence BERT in manifold space[J]. Neurocomputing, 2023, 555: 126453. doi: 10.1016/j.neucom.2023.126453.
    [17]
    ALSUHAIBANI A, ZOGAN H, RAZZAK I, et al. IDoFew: Intermediate training using dual-clustering in language models for few labels text classification[C]. The 17th ACM International Conference on Web Search and Data Mining, Merida, Mexico, 2024: 18–27. doi: 10.1145/3616855.3635849.
    [18]
    杨春玲, 梁梓文. 静态与动态域先验增强的两阶段视频压缩感知重构网络[J]. 电子与信息学报, 2024, 46(11): 4247–4258. doi: 10.11999/JEIT240295.

    YANG Chunling and LIANG Ziwen. Static and dynamic-domain prior enhancement two-stage video compressed sensing reconstruction network[J]. Journal of Electronics & Information Technology, 2024, 46(11): 4247–4258. doi: 10.11999/JEIT240295.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(5)  / Tables(7)

    Article Metrics

    Article views (395) PDF downloads(39) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return