| Citation: | LAN Chaofeng, XIE yunxiang, CHEN Yingqi, HAN Chuang, GUO Xiaoxia, GUO Rui. Tri-Modal Speech Separation Model Driven by Improved Attention and Gating-Augmented Cross-Modal Attention Mechanism[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260009

|

| [1] |
CHERRY E C. Some experiments on the recognition of speech, with one and with two ears[J]. Journal of the Acoustical Society of America, 1953, 25: 975–979. doi: 10.1121/1.1907229.
|
| [2] |
GABBAY A, EPHRAT A, HALPERIN T, et al. Seeing through noise: Visually driven speaker separation and enhancement[C]. 2018 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Calgary, Canada, 2018: 3051–3055. doi: 10.1109/ICASSP.2018.8462527.
|
| [3] |
AFOURAS T, OWENS A, CHUNG J S, et al. Self-supervised learning of audio-visual objects from video[C]. 16th European Conference Computer Vision – ECCV 2020, Glasgow, UK, 2020: 208–224. doi: 10.1007/978-3-030-58523-5_13.
|
| [4] |
TAO Ruijie, SHI Zhan, JIANG Yidi, et al. Multi-stage face-voice association learning with keynote speaker diarization[C]. The 32nd ACM International Conference on Multimedia, Melbourne, Australia, 2024: 11342–11347. doi: 10.1145/3664647.3688980.
|
| [5] |
LI Kai, XIE Fenghua, CHEN Hang, et al. An audio-visual speech separation model inspired by cortico-thalamo-cortical circuits[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2024, 46(10): 6637–6651. doi: 10.1109/TPAMI.2024.3384034.
|
| [6] |
LI Kai, YANG Runxuan, SUN Fuchun, et al. IIANet: An intra-and inter-modality attention network for audio-visual speech separation[C]. The 41st International Conference on Machine Learning, Vienna, Austria, 2024: 1174.
|
| [7] |
WU Jian, XU Yong, ZHANG Shixiong, et al. Time domain audio visual speech separation[C]. 2019 IEEE Automatic Speech Recognition and Understanding Workshop (ASRU), Singapore, Singapore, 2019: 667–673. doi: 10.1109/ASRU46091.2019.9003983.
|
| [8] |
LIU Debang, ZHANG Tianqi, CHRISTENSEN M G, et al. Audio-visual fusion with temporal convolutional attention network for speech separation[J]. IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2024, 32: 4647–4660. doi: 10.1109/TASLP.2024.3463411.
|
| [9] |
YEMINI Y, BEN-ARI R, GANNOT S, et al. Diffusion-based unsupervised audio-visual speech separation in noisy environments with noise prior[C]. ICASSP 2026 - 2026 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Barcelona, Spain, 2026: 22707–22711. doi: 10.1109/ICASSP55912.2026.11464305.
|
| [10] |
SCHULZE-FORSTER K, DOIRE C S J, RICHARD G, et al. Joint phoneme alignment and text-informed speech separation on highly corrupted speech[C]. ICASSP 2020 - 2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Barcelona, Spain, 2020: 7274–7278. doi: 10.1109/ICASSP40776.2020.9053182.
|
| [11] |
KIM M, MIRA R, CHEN Honglie, et al. Contextual speech extraction: Leveraging textual history as an implicit cue for target speech extraction[C]. ICASSP 2025 - 2025 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Hyderabad, India, 2025: 1–5. doi: 10.1109/ICASSP49660.2025.10887655.
|
| [12] |
OHISHI Y, DELCROIX M, OCHIAI T, et al. ConceptBeam: Concept driven target speech extraction[C]. The 30th ACM International Conference on Multimedia, Lisboa, Portugal, 2022: 4252–4260. doi: 10.1145/3503161.3548397.
|
| [13] |
LI Chenda and QIAN Yanmin. Listen, watch and understand at the cocktail party: Audio-visual-contextual speech separation[C]. 21st Annual Conference of the International Speech Communication Association, Shanghai, China, 2020: 1426–1430.
|
| [14] |
RAHIMI A, AFOURAS T, and ZISSERMAN A. Reading to listen at the cocktail party: Multi-modal speech separation[C]. 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, USA, 2022: 10493–10502. doi: 10.1109/CVPR52688.2022.01024.
|
| [15] |
LIU Xubo, KONG Qiuqiang, ZHAO Yan, et al. Separate anything you describe[J]. IEEE Transactions on Audio, Speech and Language Processing, 2025, 33: 458–471. doi: 10.1109/TASLP.2024.3520017.
|
| [16] |
YUAN Yuan, LI Zhaojian, and ZHAO Bin. A survey of multimodal learning: Methods, applications, and future[J]. ACM Computing Surveys, 2025, 57(7): 167. doi: 10.1145/3713070.
|
| [17] |
GABBAY A, SHAMIR A, and PELEG S. Visual speech enhancement[C]. Interspeech 2018, Hyderabad, India, 2018: 1170–1174.
|
| [18] |
GOGATE M, DASHTIPOUR K, ADEEL A, et al. CochleaNet: A robust language-independent audio-visual model for real-time speech enhancement[J]. Information Fusion, 2020, 63: 273–285. doi: 10.1016/j.inffus.2020.04.001.
|
| [19] |
兰朝凤, 蒋朋威, 陈欢, 等. 结合光流算法与注意力机制的U-Net网络跨模态视听语音分离[J]. 电子与信息学报, 2023, 45(10): 3538–3546. doi: 10.11999/JEIT221500.
LAN Chaofeng, JIANG Pengwei, CHEN Huan, et al. Cross-modal audiovisual separation based on U-Net network combining optical flow algorithm and attention mechanism[J]. Journal of Electronics & Information Technology, 2023, 45(10): 3538–3546. doi: 10.11999/JEIT221500.
|
| [20] |
SUBAKAN C, RAVANELLI M, CORNELL S, et al. Attention is all you need in speech separation[C]. ICASSP 2021 - 2021 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Toronto, Canada, 2021: 21–25. doi: 10.1109/ICASSP39728.2021.9413901.
|
| [21] |
WAHAB F E, SALEEM N, HUSSAIN A, et al. Multi-model dual-transformer network for audio-visual speech enhancement[C]. 3rd COG-MHEAR Workshop on Audio-Visual Speech Enhancement, Kos, Greece, 2024: 1–5. doi: 10.21437/AVSEC.2024-1. (查阅网上资料,未找到本条文献出版地信息,请确认).
|
| [22] |
LI Junjie, ZHANG Ke, WANG Shuai, et al. MoMuSE: Momentum multi-modal target speaker extraction for real-time scenarios with impaired visual cues[C]. 2025 IEEE International Conference on Multimedia and Expo (ICME), Nantes, France, 2025: 1–6. doi: 10.1109/ICME59968.2025.11209435.
|
| [23] |
YU Cheng, AHMADI KALKHORANI V, XU Buye, et al. Online AV-CrossNet: A causal and efficient audiovisual system for speech enhancement and target speaker extraction[C]. Interspeech 2025, Rotterdam, The Netherlands, 2025: 2985–2989.
|
| [24] |
兰朝凤, 蒋朋威, 陈欢, 等. 基于双路径递归网络与Conv-TasNet的多头注意力机制视听语音分离[J]. 电子与信息学报, 2024, 46(3): 1005–1012. doi: 10.11999/JEIT230260.
LAN Chaofeng, JIANG Pengwei, CHEN Huan, et al. Multi-head attention time domain audiovisual speech separation based on dual-path recurrent network and Conv-TasNet[J]. Journal of Electronics & Information Technology, 2024, 46(3): 1005–1012. doi: 10.11999/JEIT230260.
|
| [25] |
HOCHREITER S and SCHMIDHUBER J. Long short-term memory[J]. Neural Computation, 1997, 9(8): 1735–1780. doi: 10.1162/neco.1997.9.8.1735.
|
| [26] |
ZHAO Shengkui, MA Yukun, NI Chongjia, et al. MossFormer2: Combining transformer and RNN-free recurrent network for enhanced time-domain monaural speech separation[C]. ICASSP 2024 - 2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Seoul, South Korea, 2024: 10356–10360. doi: 10.1109/ICASSP48485.2024.10445985.
|
| [27] |
YU Yinfeng and SUN Shiyu. DGFNet: End-to-end audio-visual source separation based on dynamic gating fusion[C]. The 2025 International Conference on Multimedia Retrieval, Chicago, USA, 2025: 1730–1738. doi: 10.1145/3731715.3733305.
|
| [28] |
张天骐, 柏浩钧, 叶绍鹏, 等. 基于注意力门控膨胀卷积网络的单通道语音增强[J]. 电子与信息学报, 2022, 44(9): 3277–3288. doi: 10.11999/JEIT210654.
ZHANG Tianqi, BAI Haojun, YE Shaopeng, et al. Monaural speech enhancement based on attention-gate dilated convolution network[J]. Journal of Electronics & Information Technology, 2022, 44(9): 3277–3288. doi: 10.11999/JEIT210654.
|
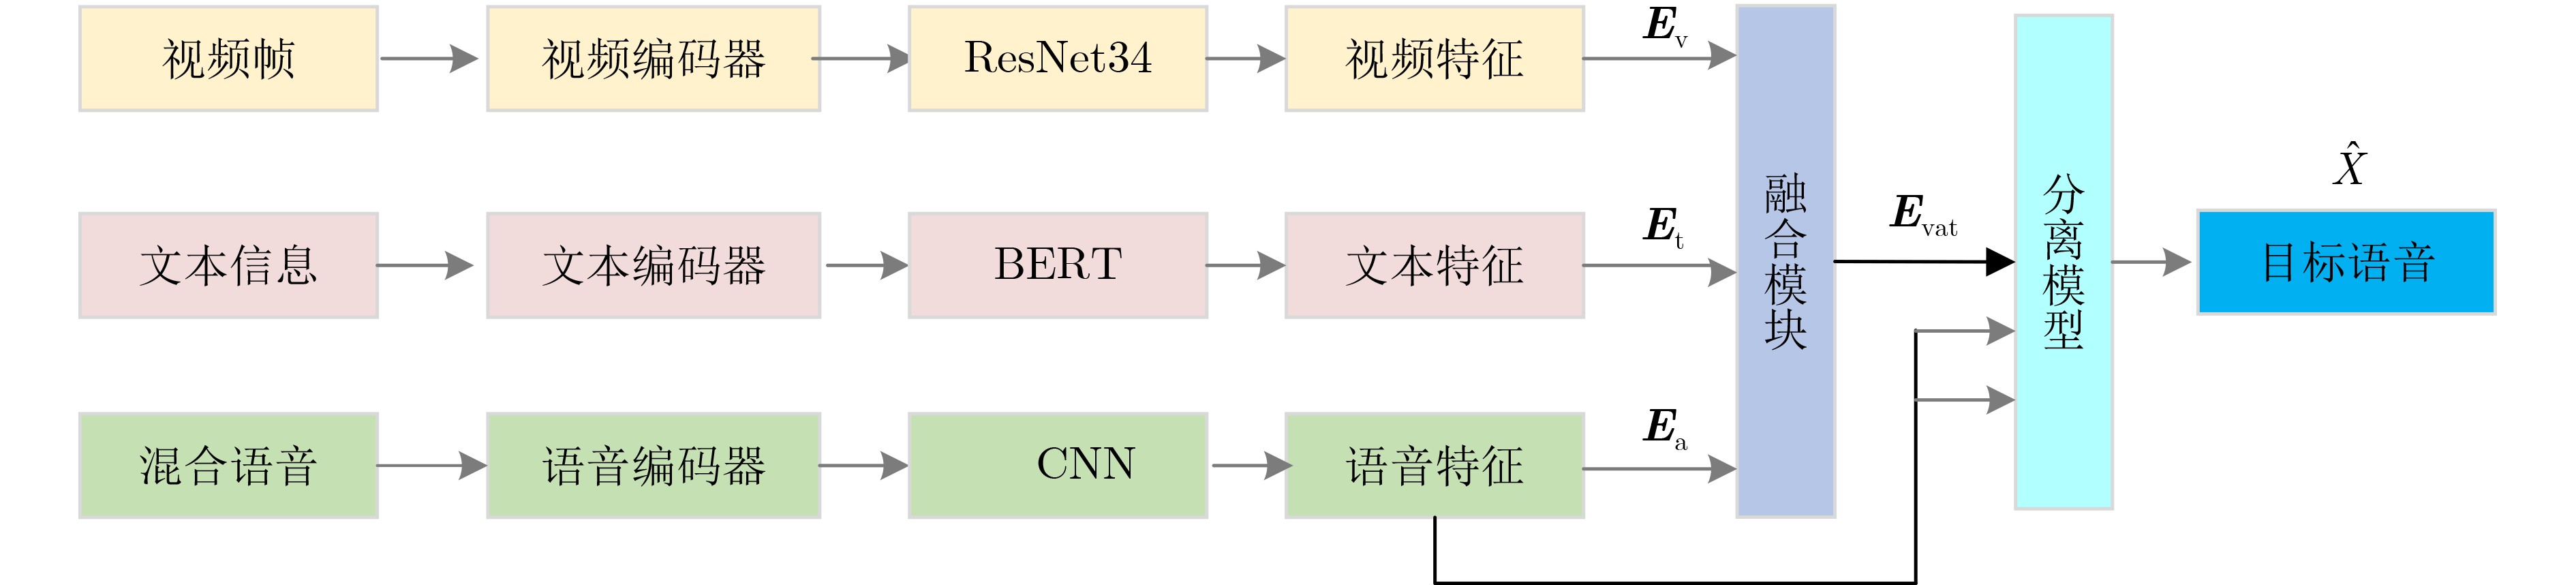
Figures(4) / Tables(4)


 DownLoad: