



A Low-Power CNN/SNN Hybrid Hardware Accelerator with Configurable Time-Window Architecture
-
摘要: 近年来,融合卷积神经网络(Convolutional Neural Networks, CNN)与脉冲神经网络(Spiking Neural Network, SNN)的脉冲卷积神经网络加速器在边缘智能中展现出显著优势。然而,现有设计多采用固定时间窗口(Time Windows, TW)执行积分迭代,难以适配不同任务的时序复杂度。本文提出一种基于可配置TW的低功耗混合硬件加速器架构。首先,基于不同任务的时空复杂度分析,提出可配置TW自定义指令集,减少推理延迟与计算开销;其次,构建支持零跳跃的数据复用计算阵列,并引入CNN/SNN多模式算子统一映射,提升计算资源利用率;最后,提出事件驱动执行机制与细粒度时钟门控策略,减少计算过程与数据传输过程中无效操作和冗余访存。在TSMC 28 nm工艺实现CNN/SNN混合加速器,芯片核心面积为0.75 mm2。在0.81 V供电电压和100 MHz工作频率下,该加速器面向MIT-BIH、N-TIDIGITS、N-MNIST、IMAGE-100和UniMiB SHAR等多类任务实现75.3%–98.4%的识别精度,最低单次推理能耗仅为147.78 nJ。与相关工作比较,所提出的可配置TW机制在保证识别精度的同时,可实现1.24×–30×的能耗降低,显著提升系统能效。Abstract:
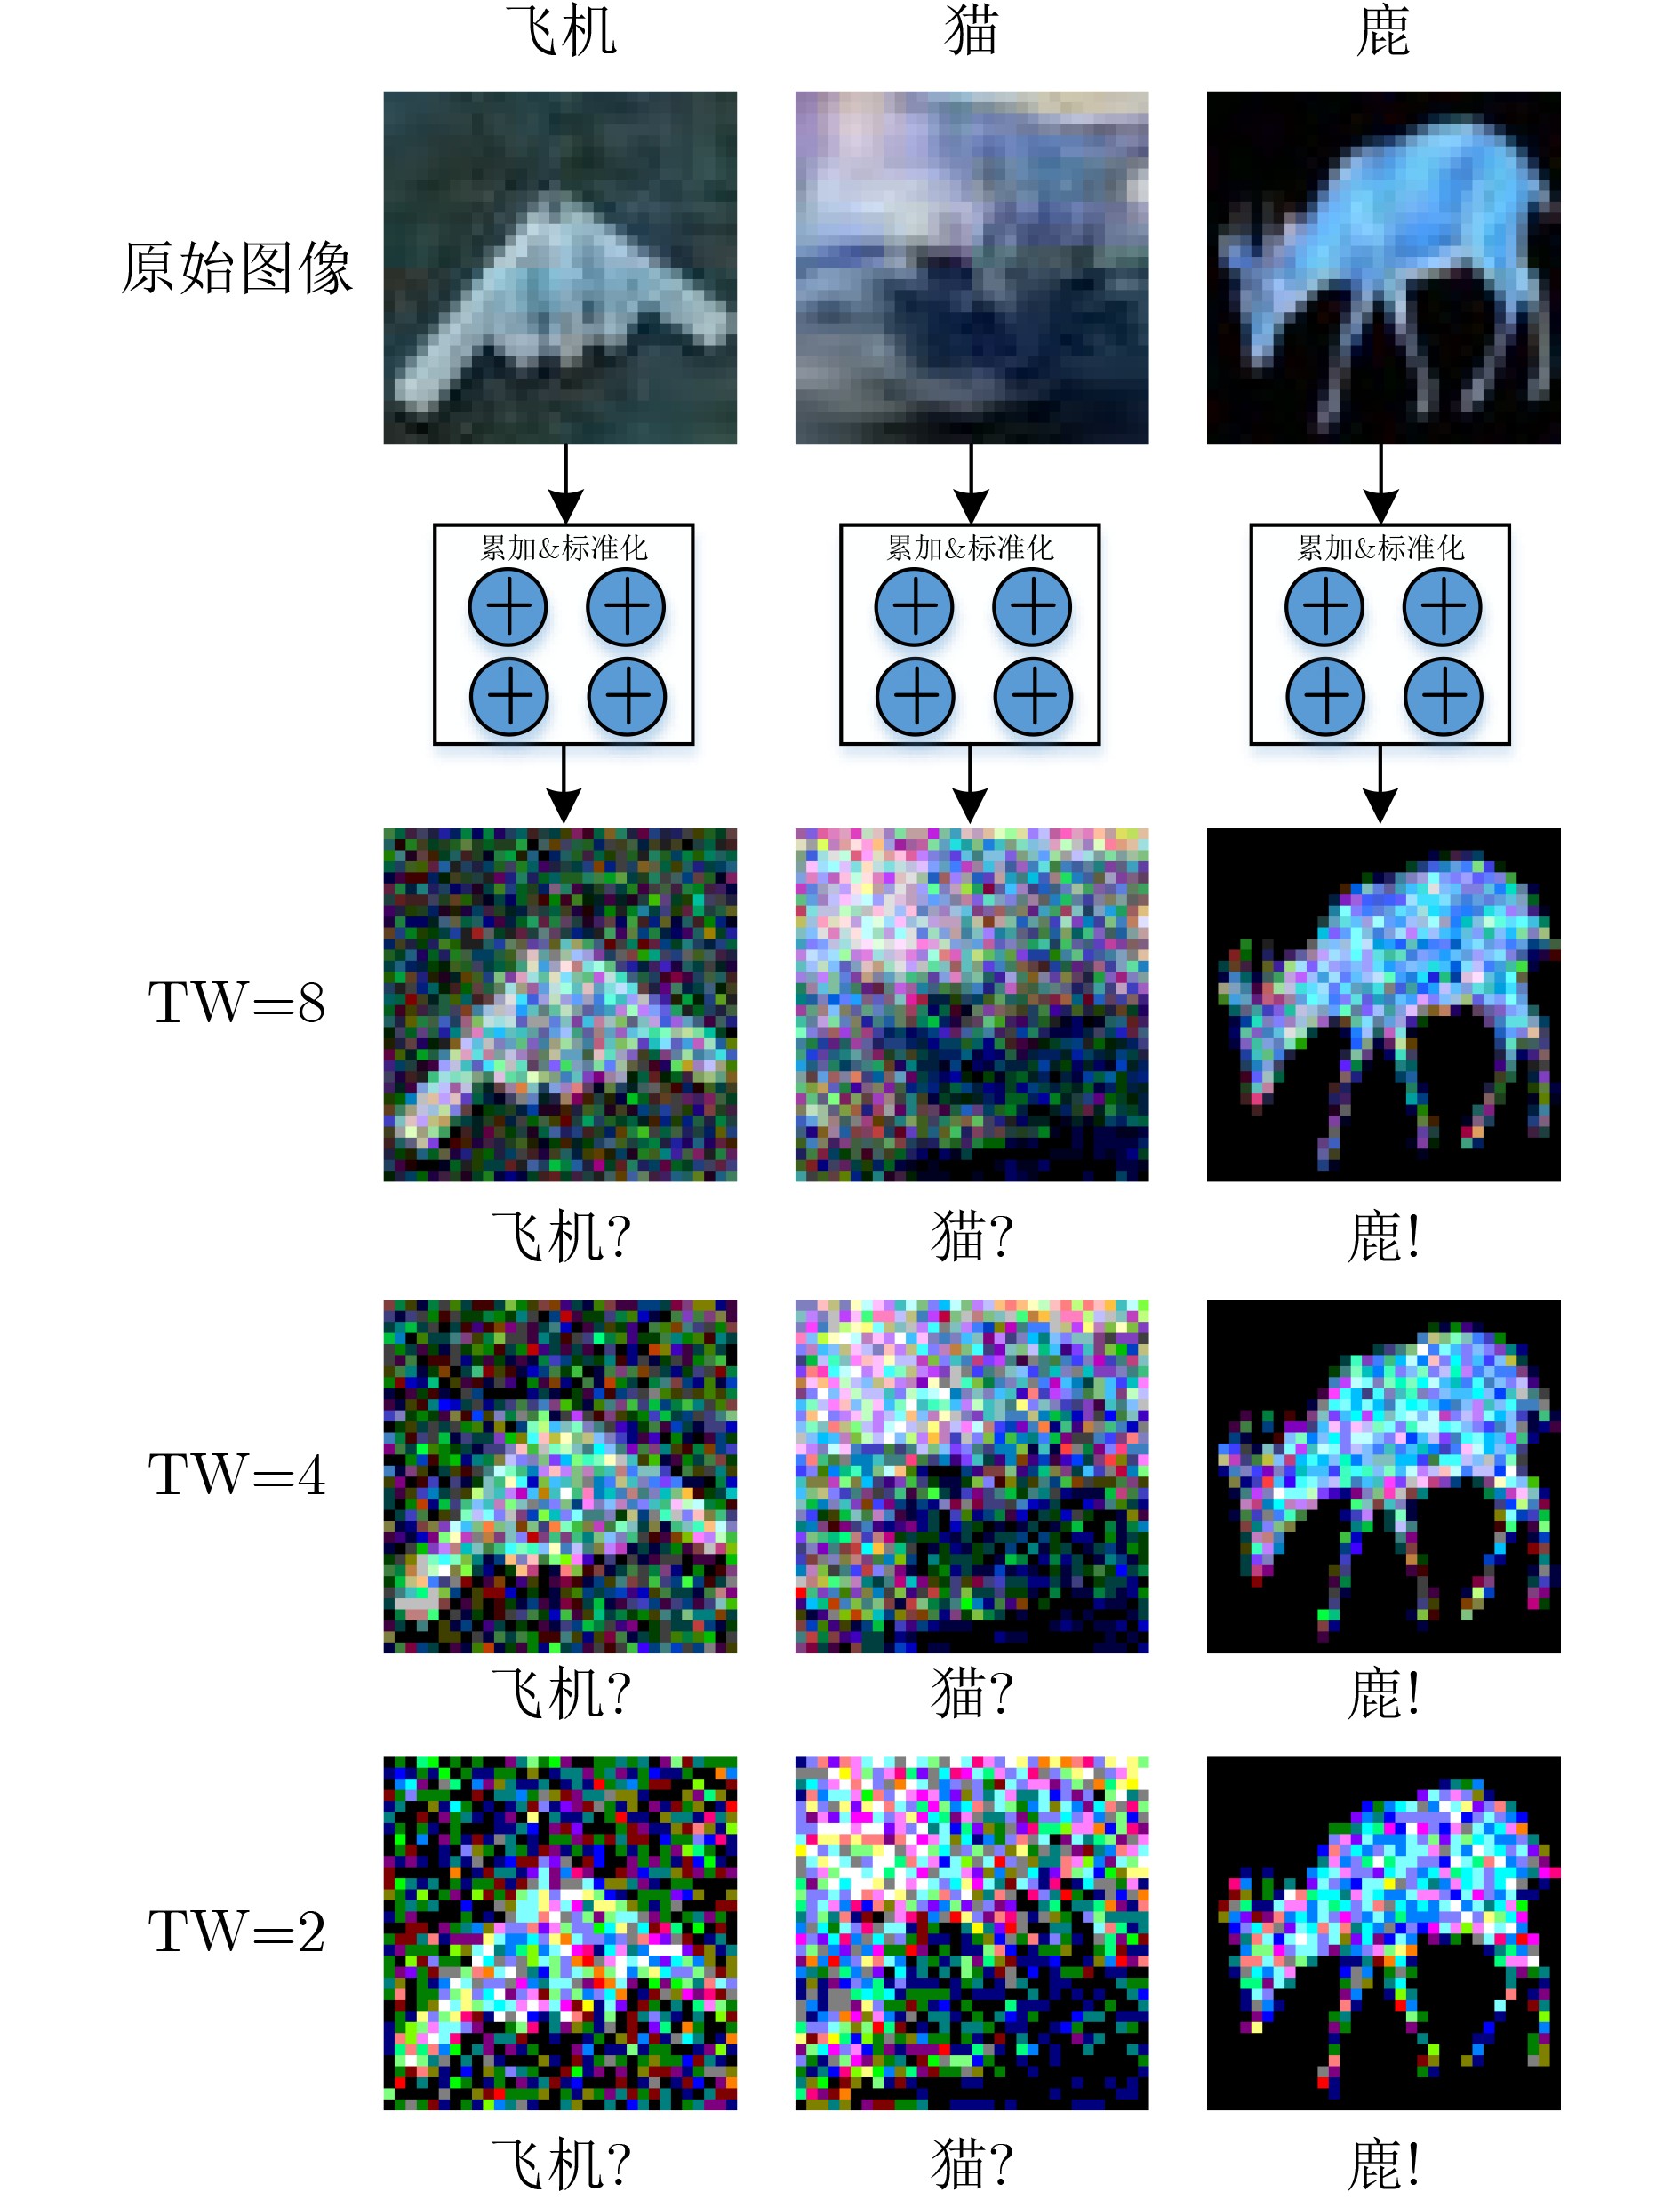
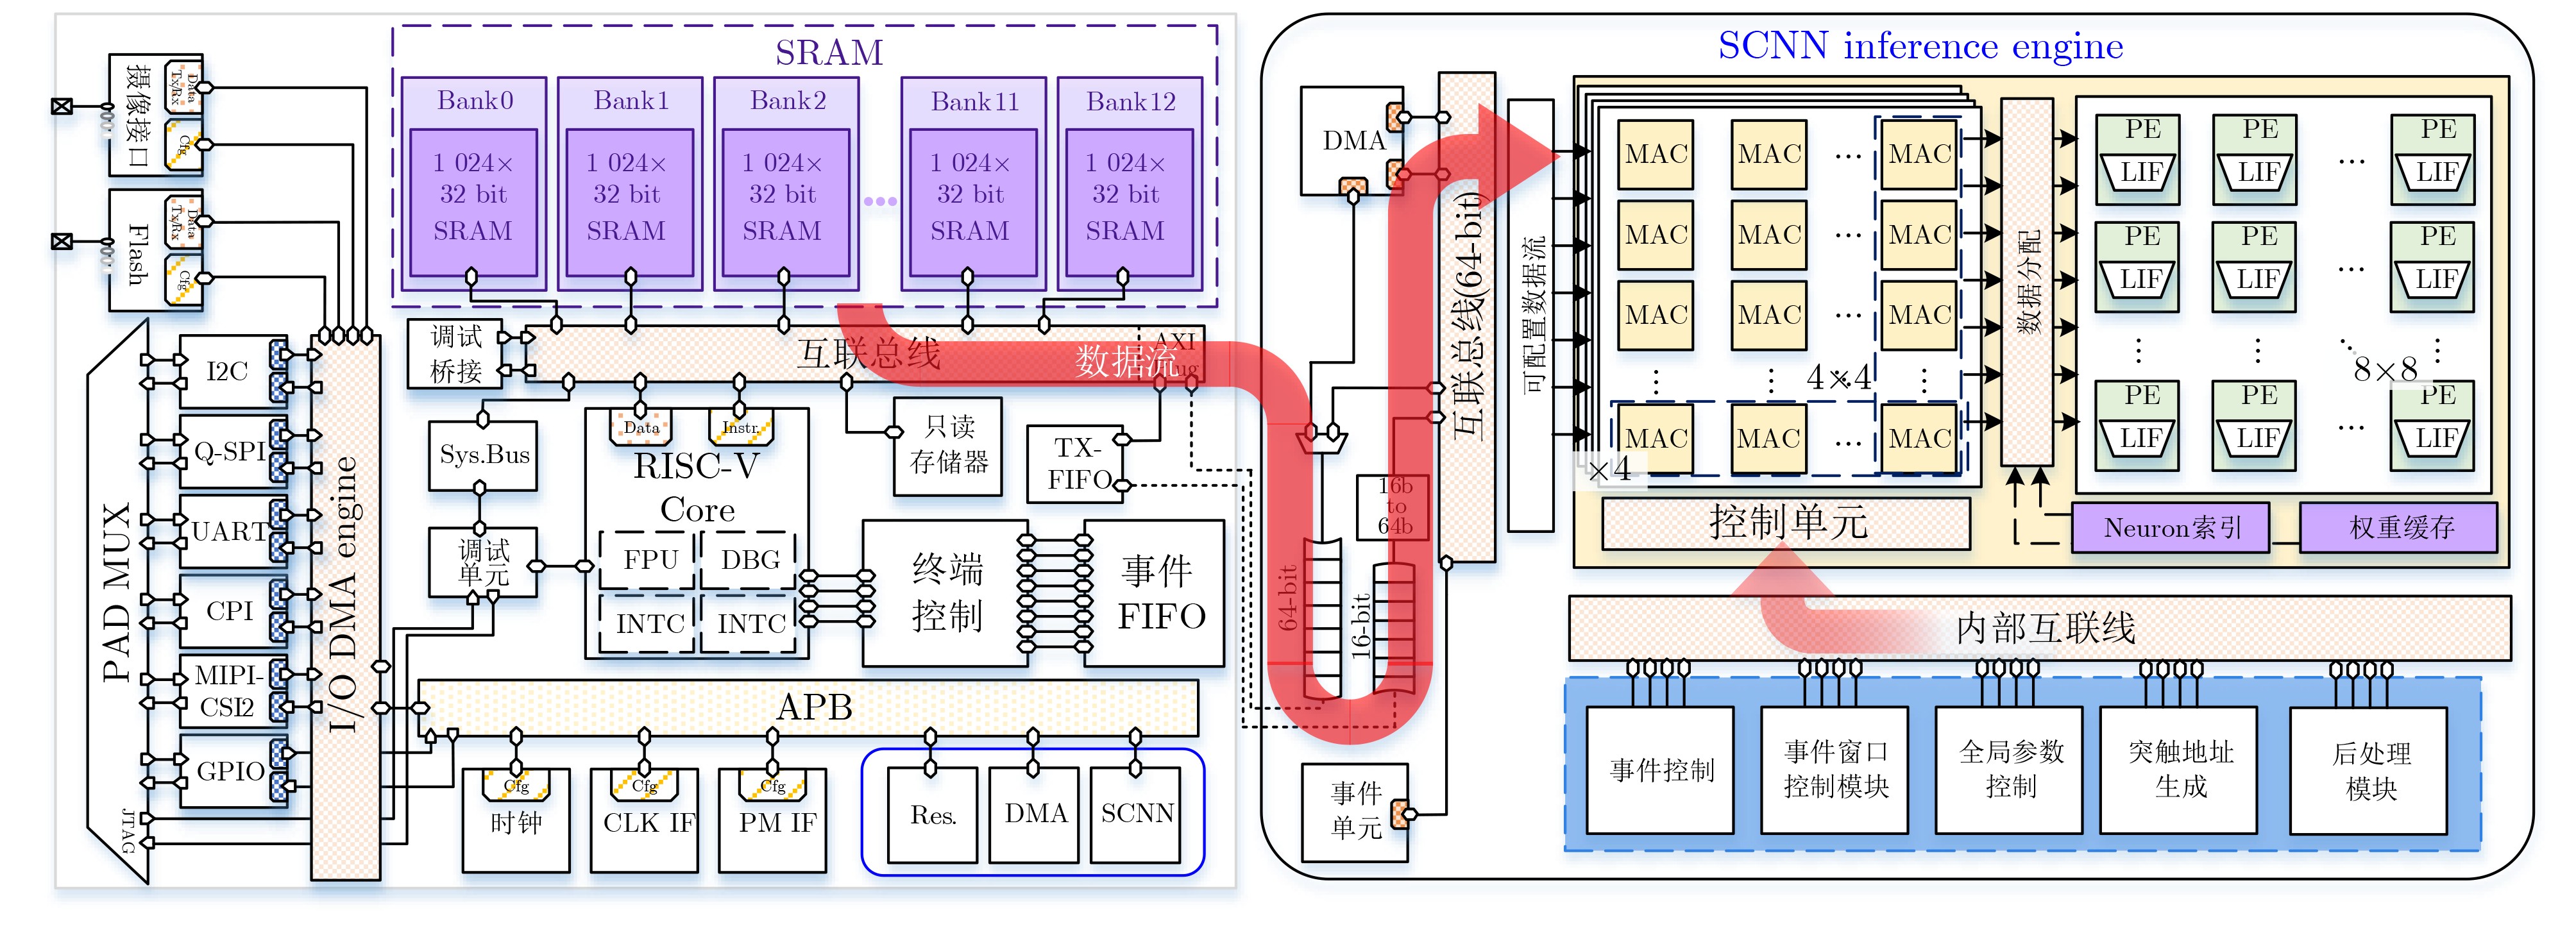
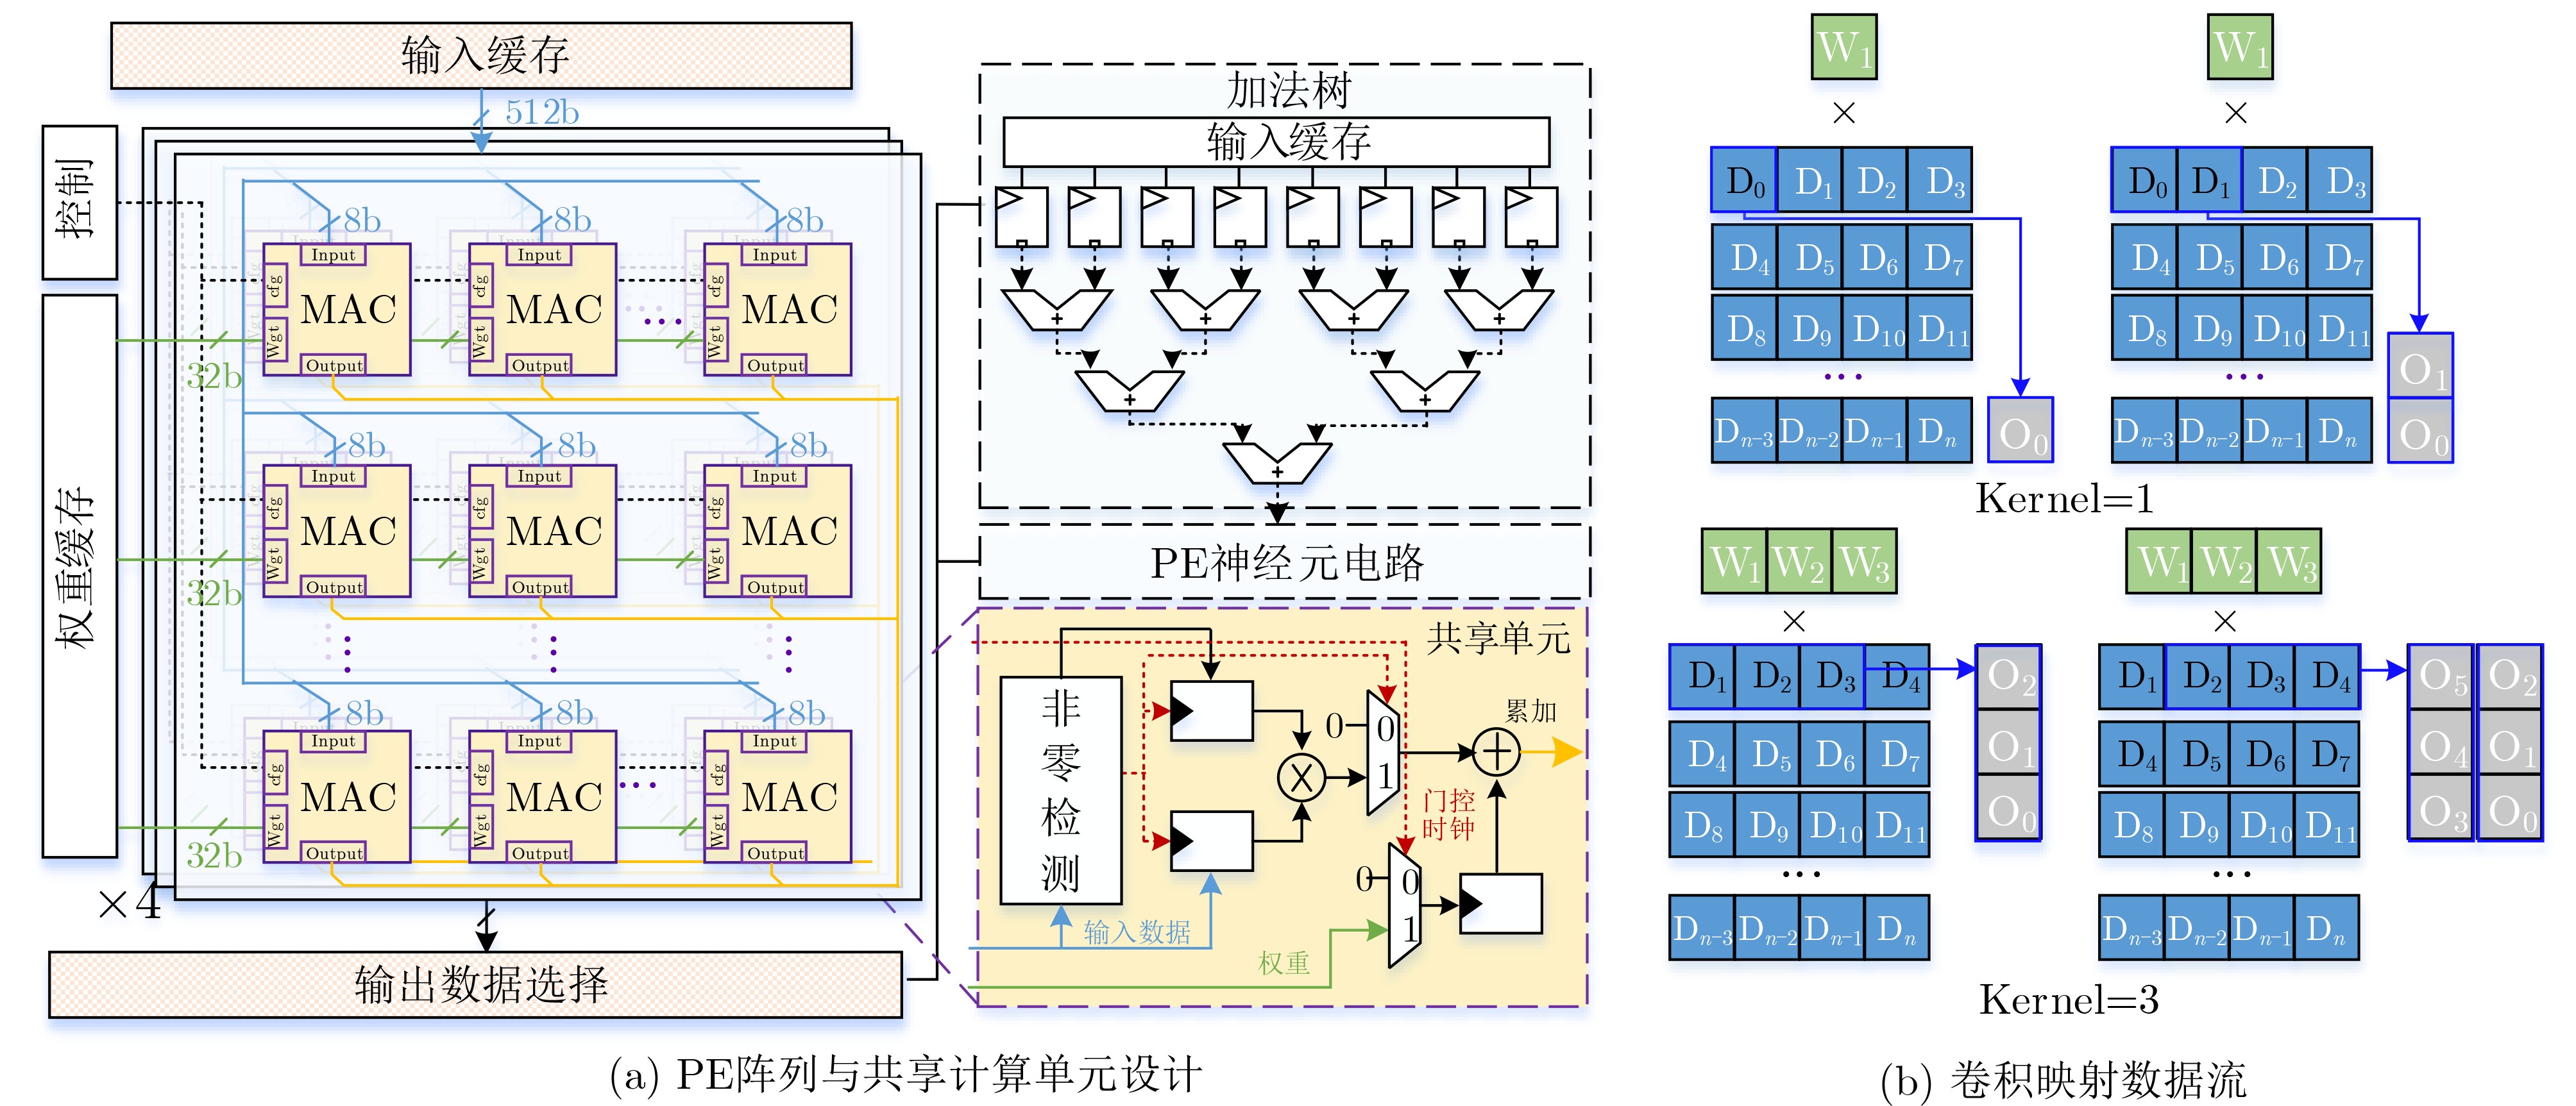
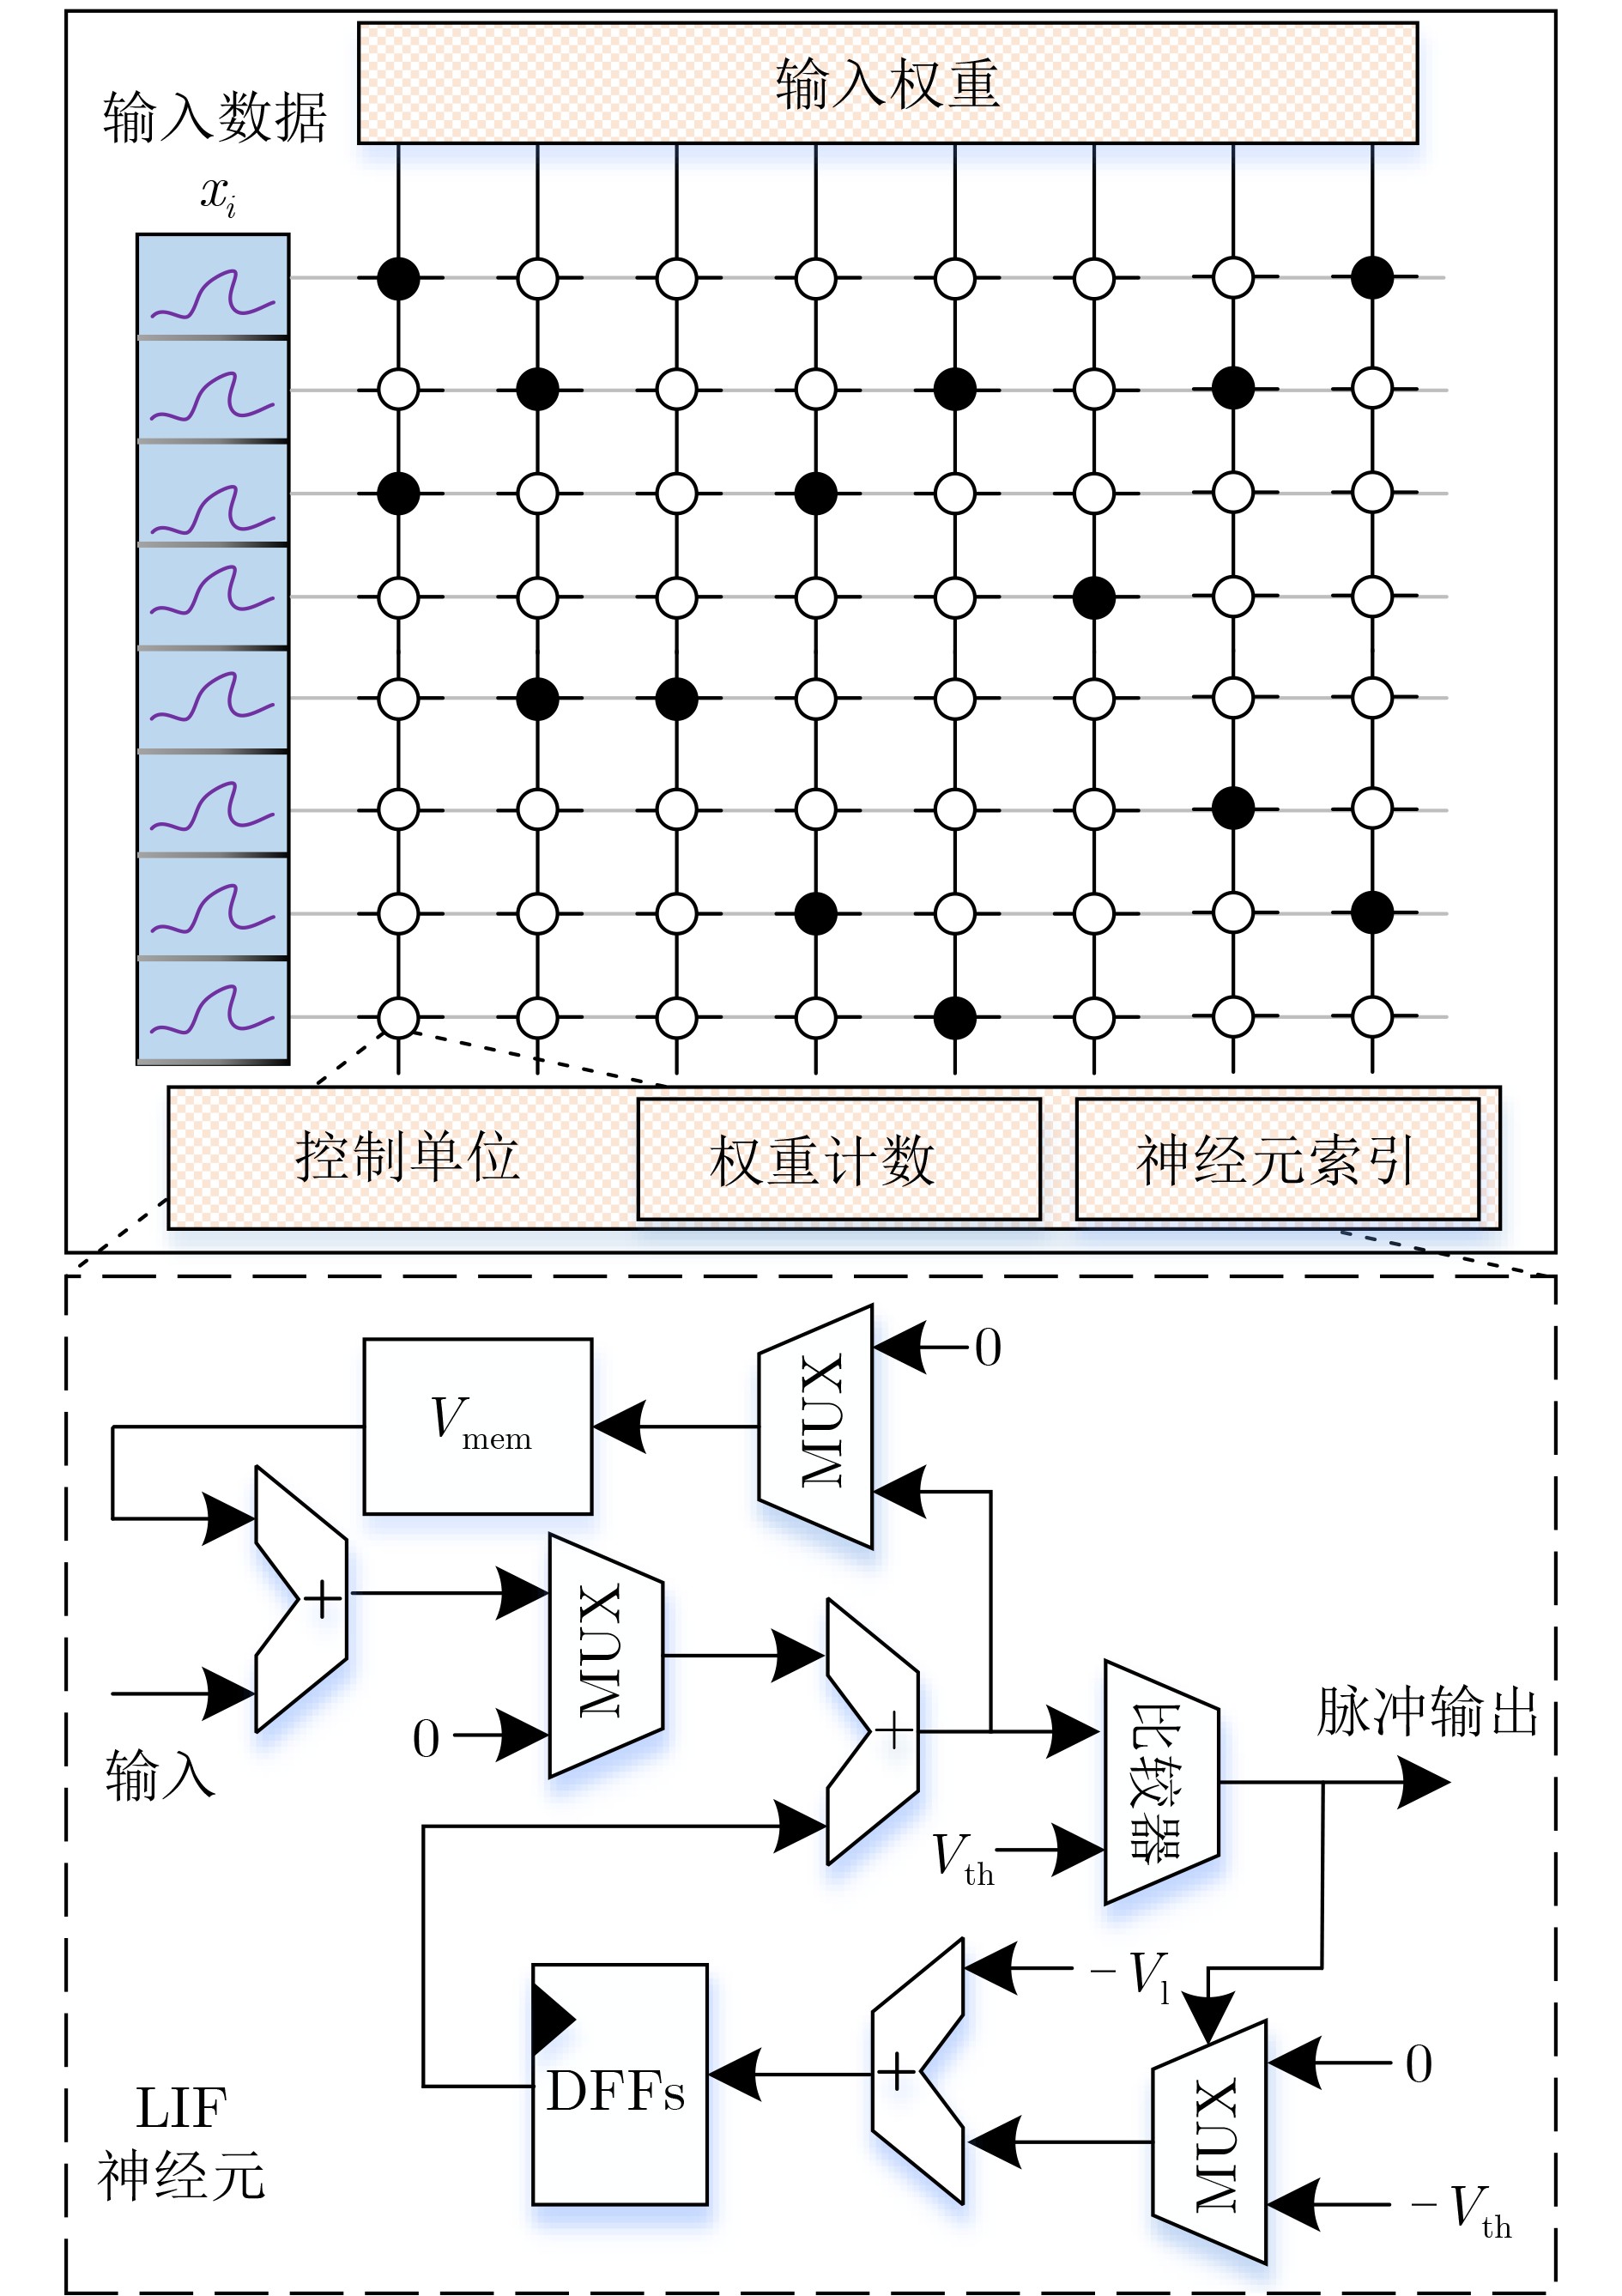
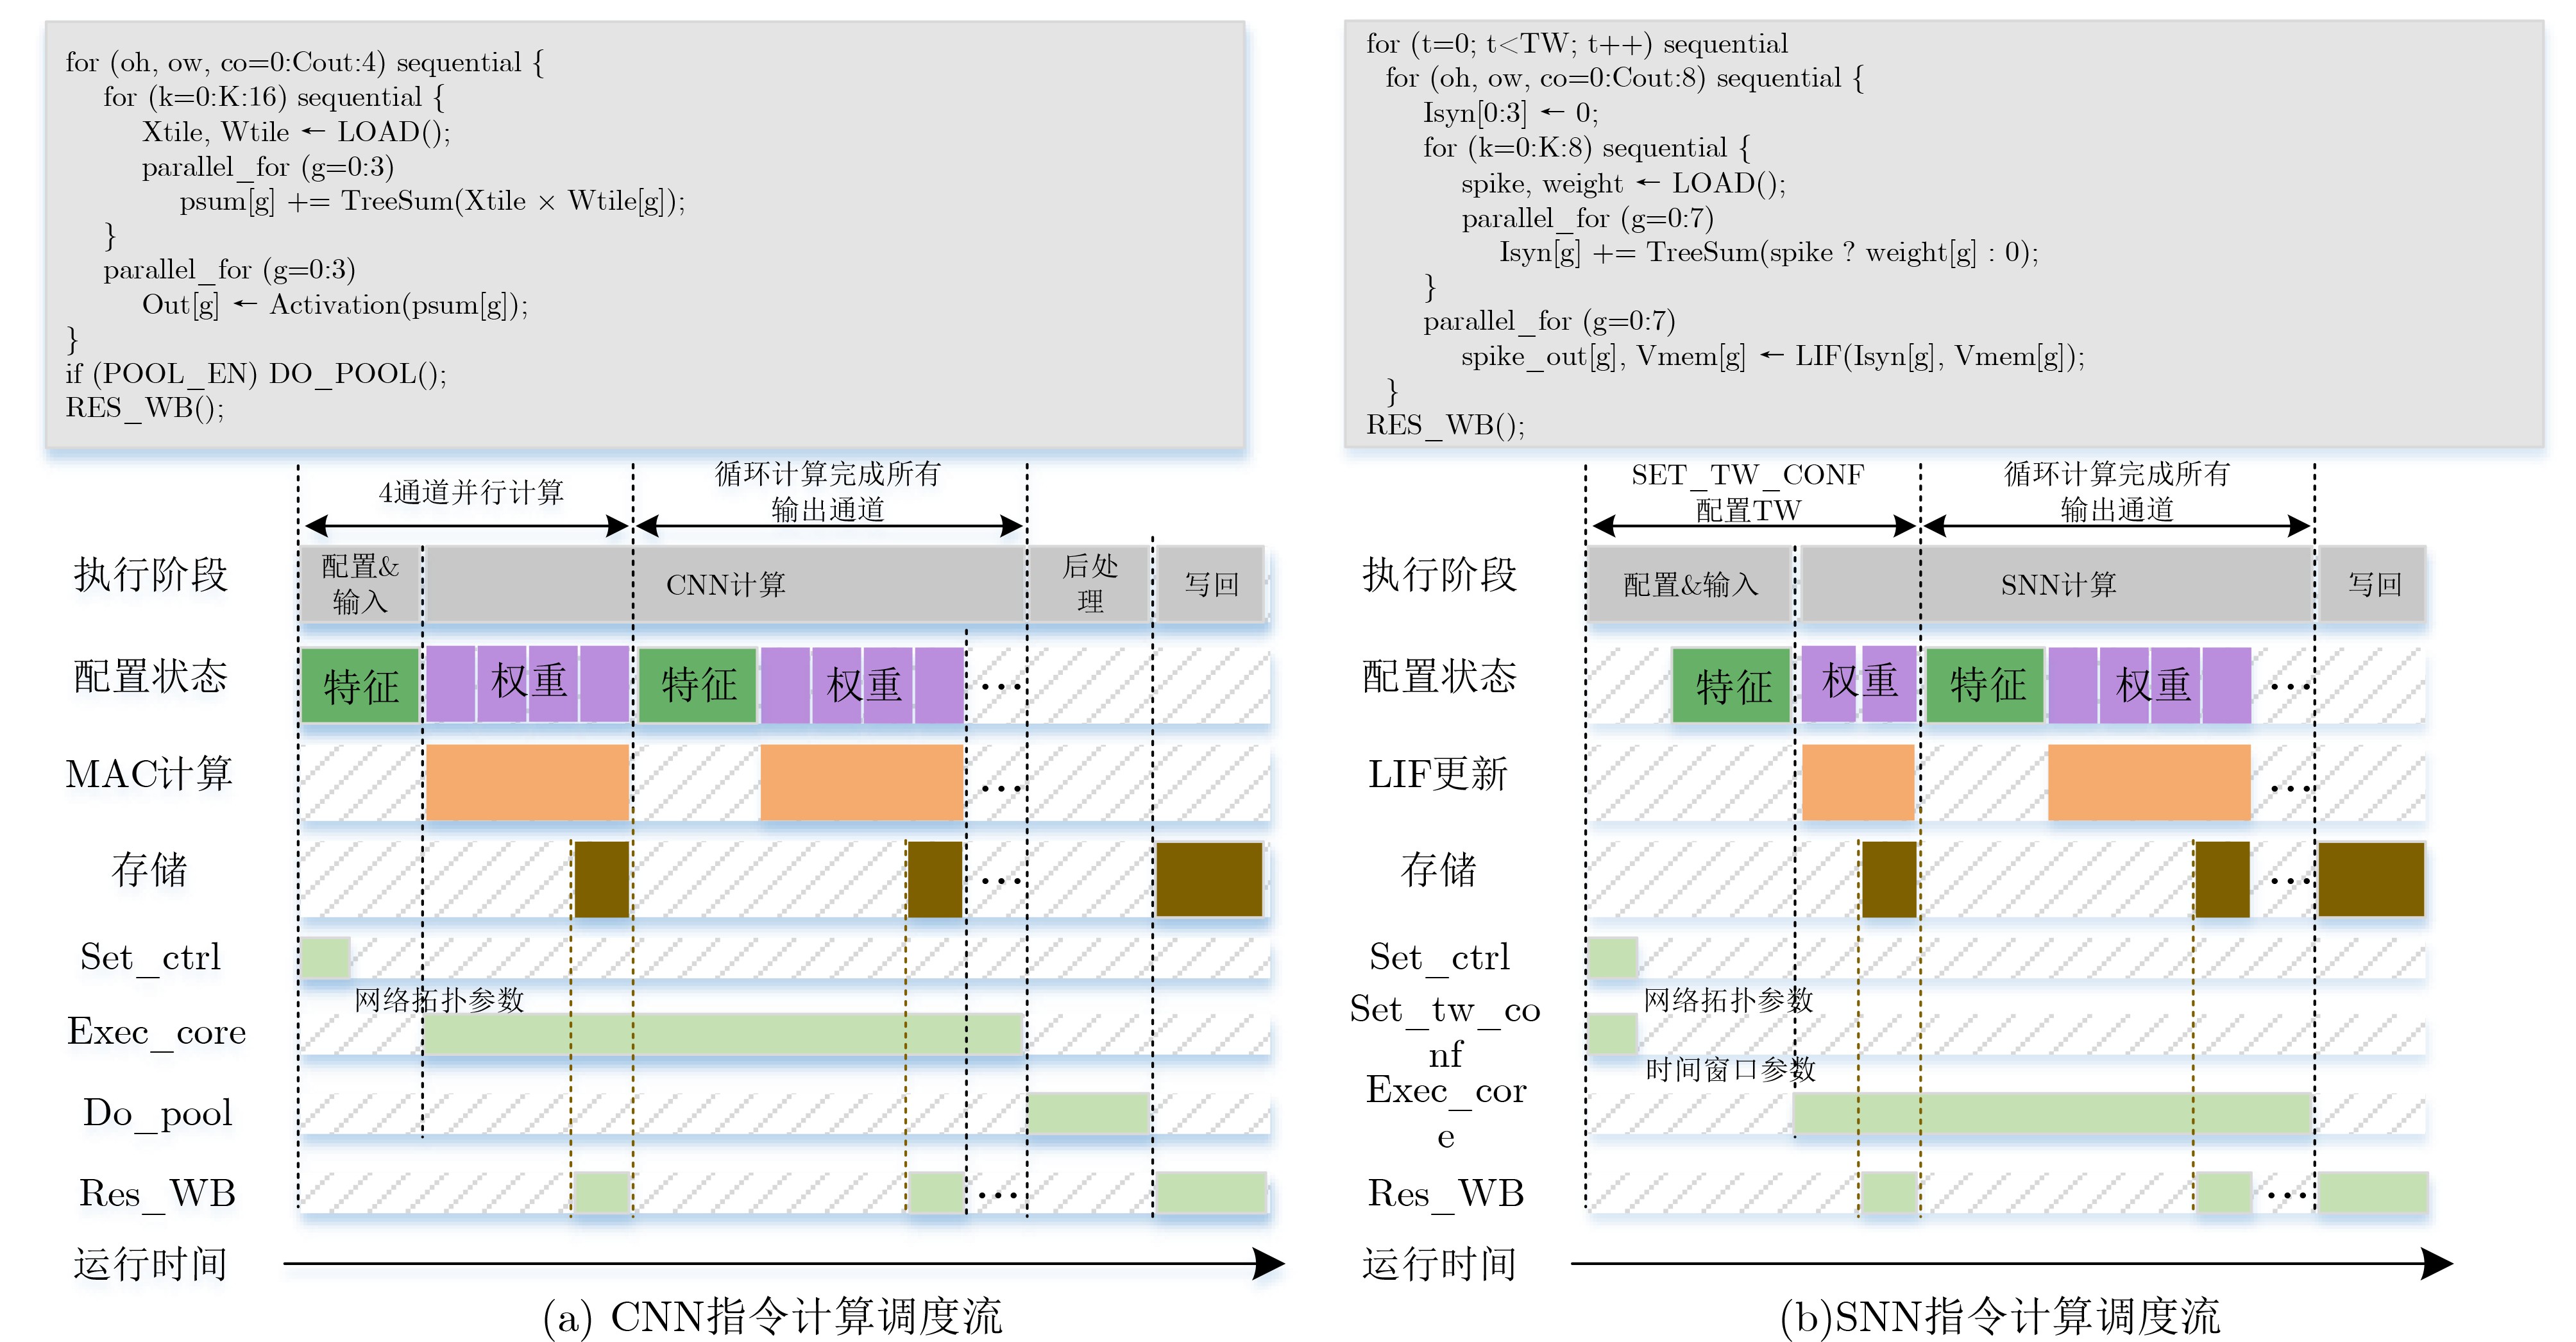
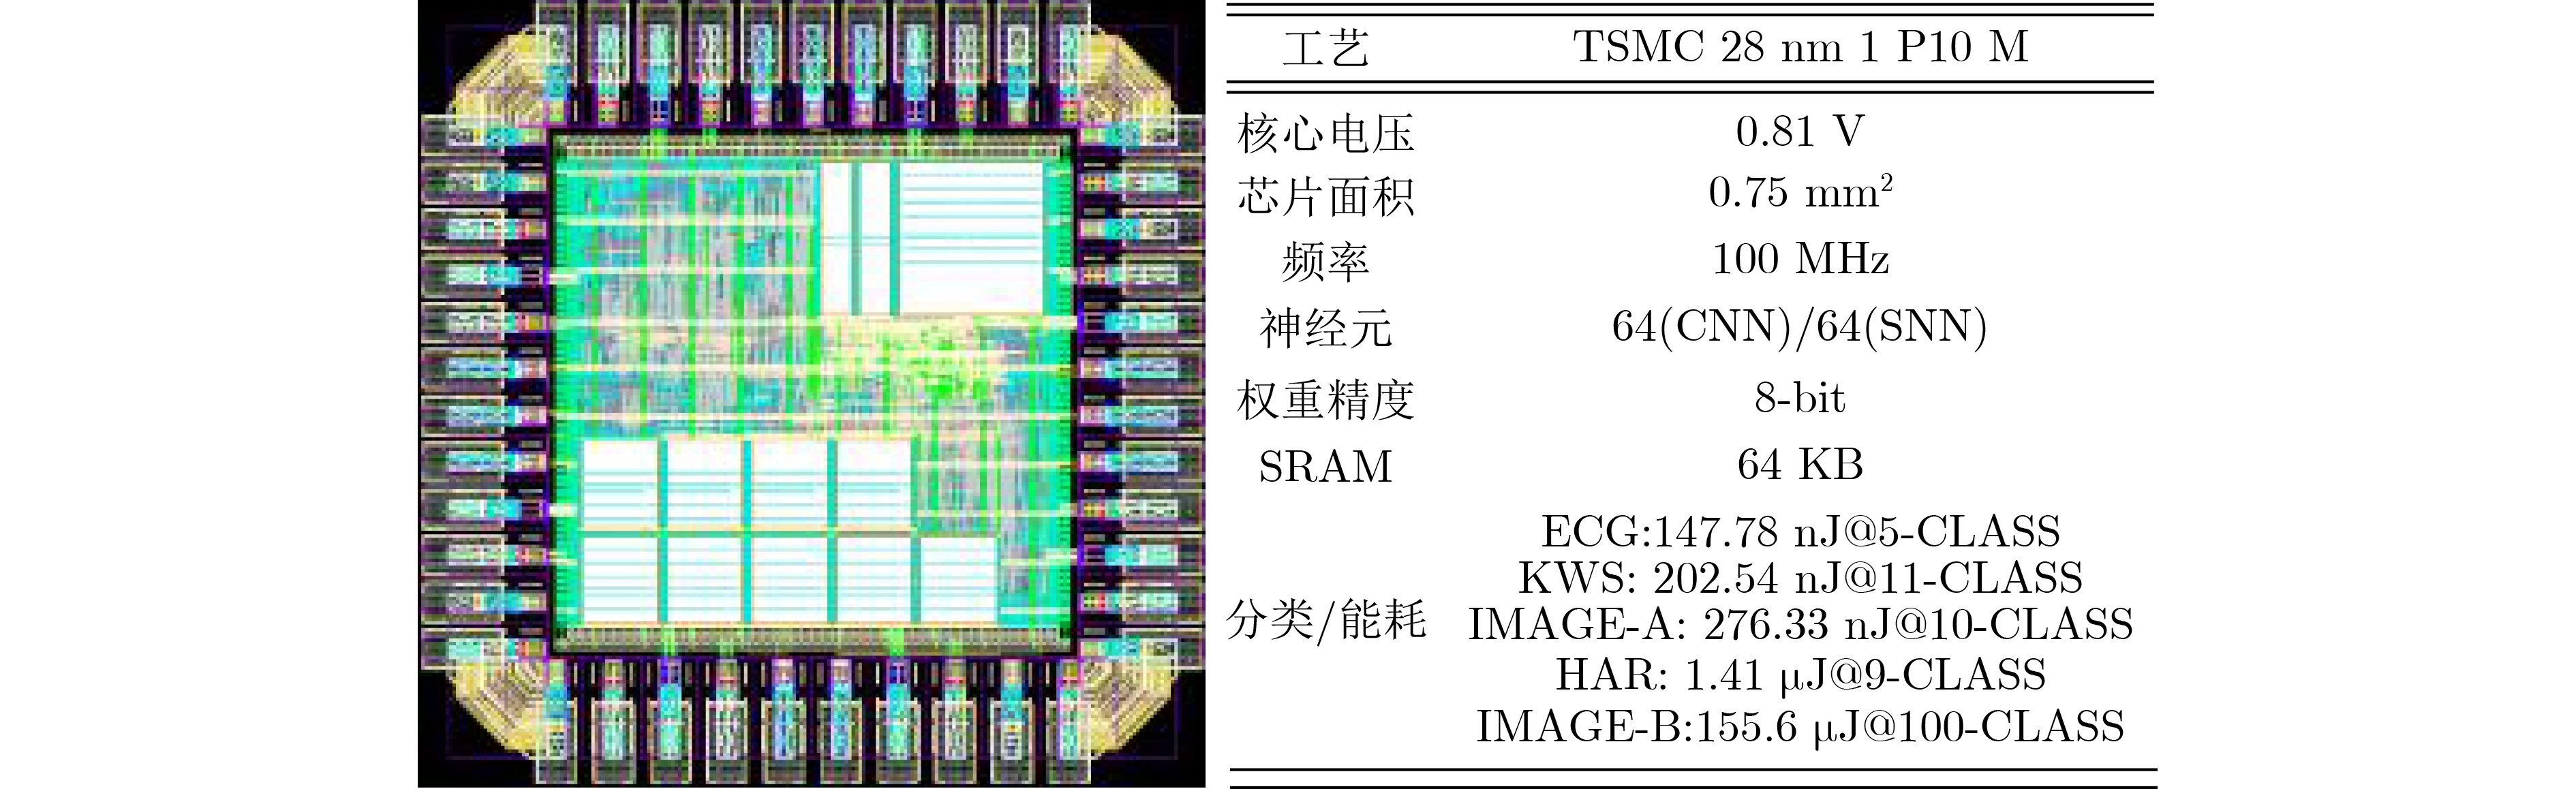
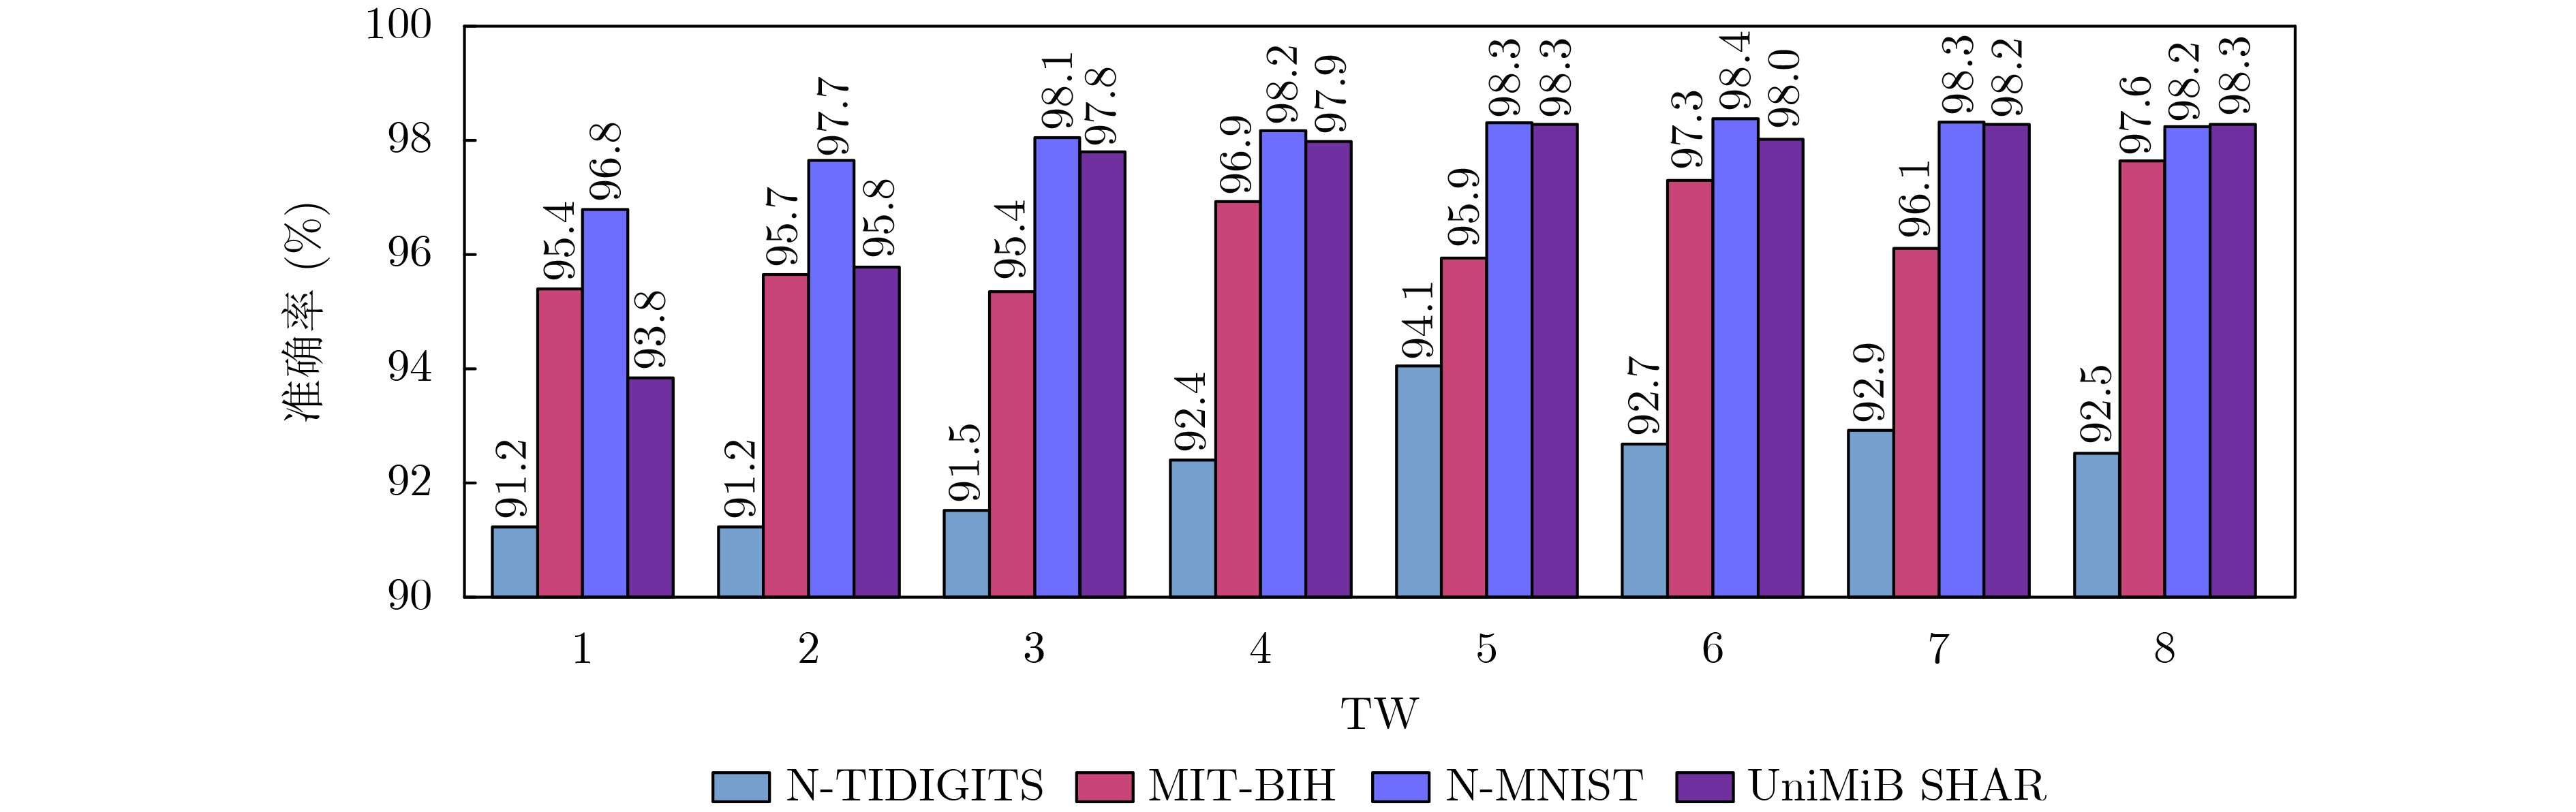
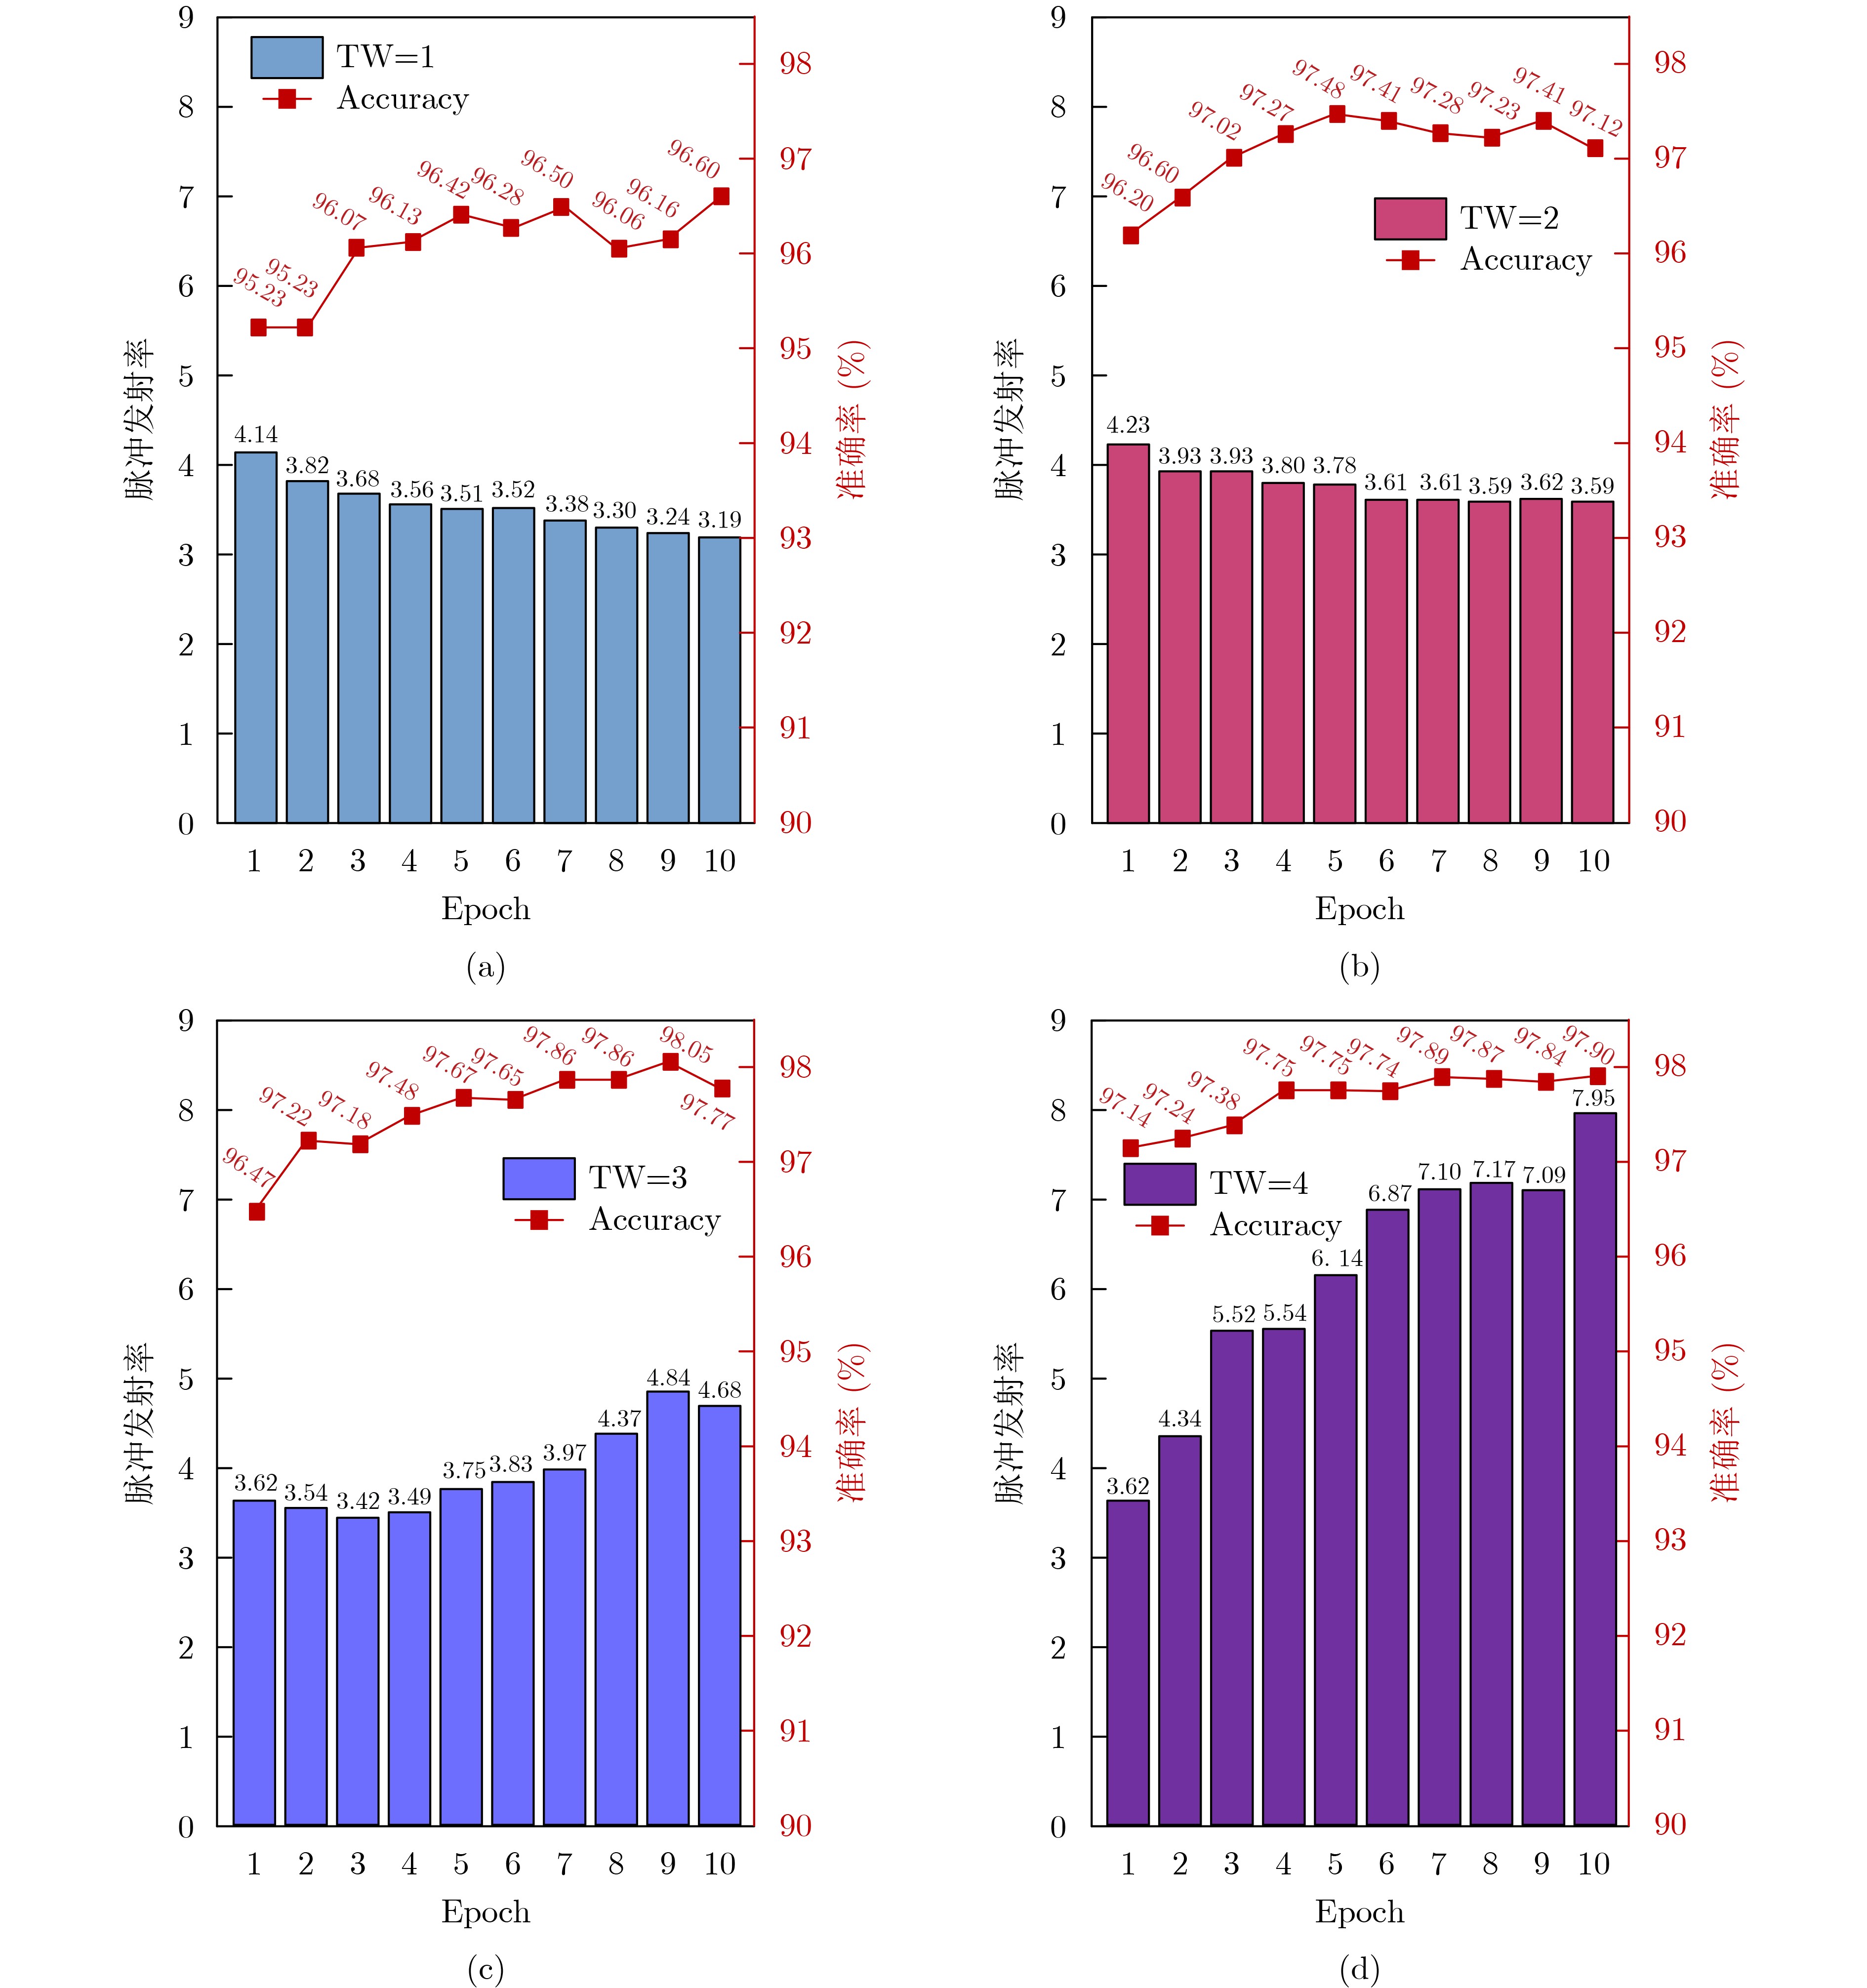
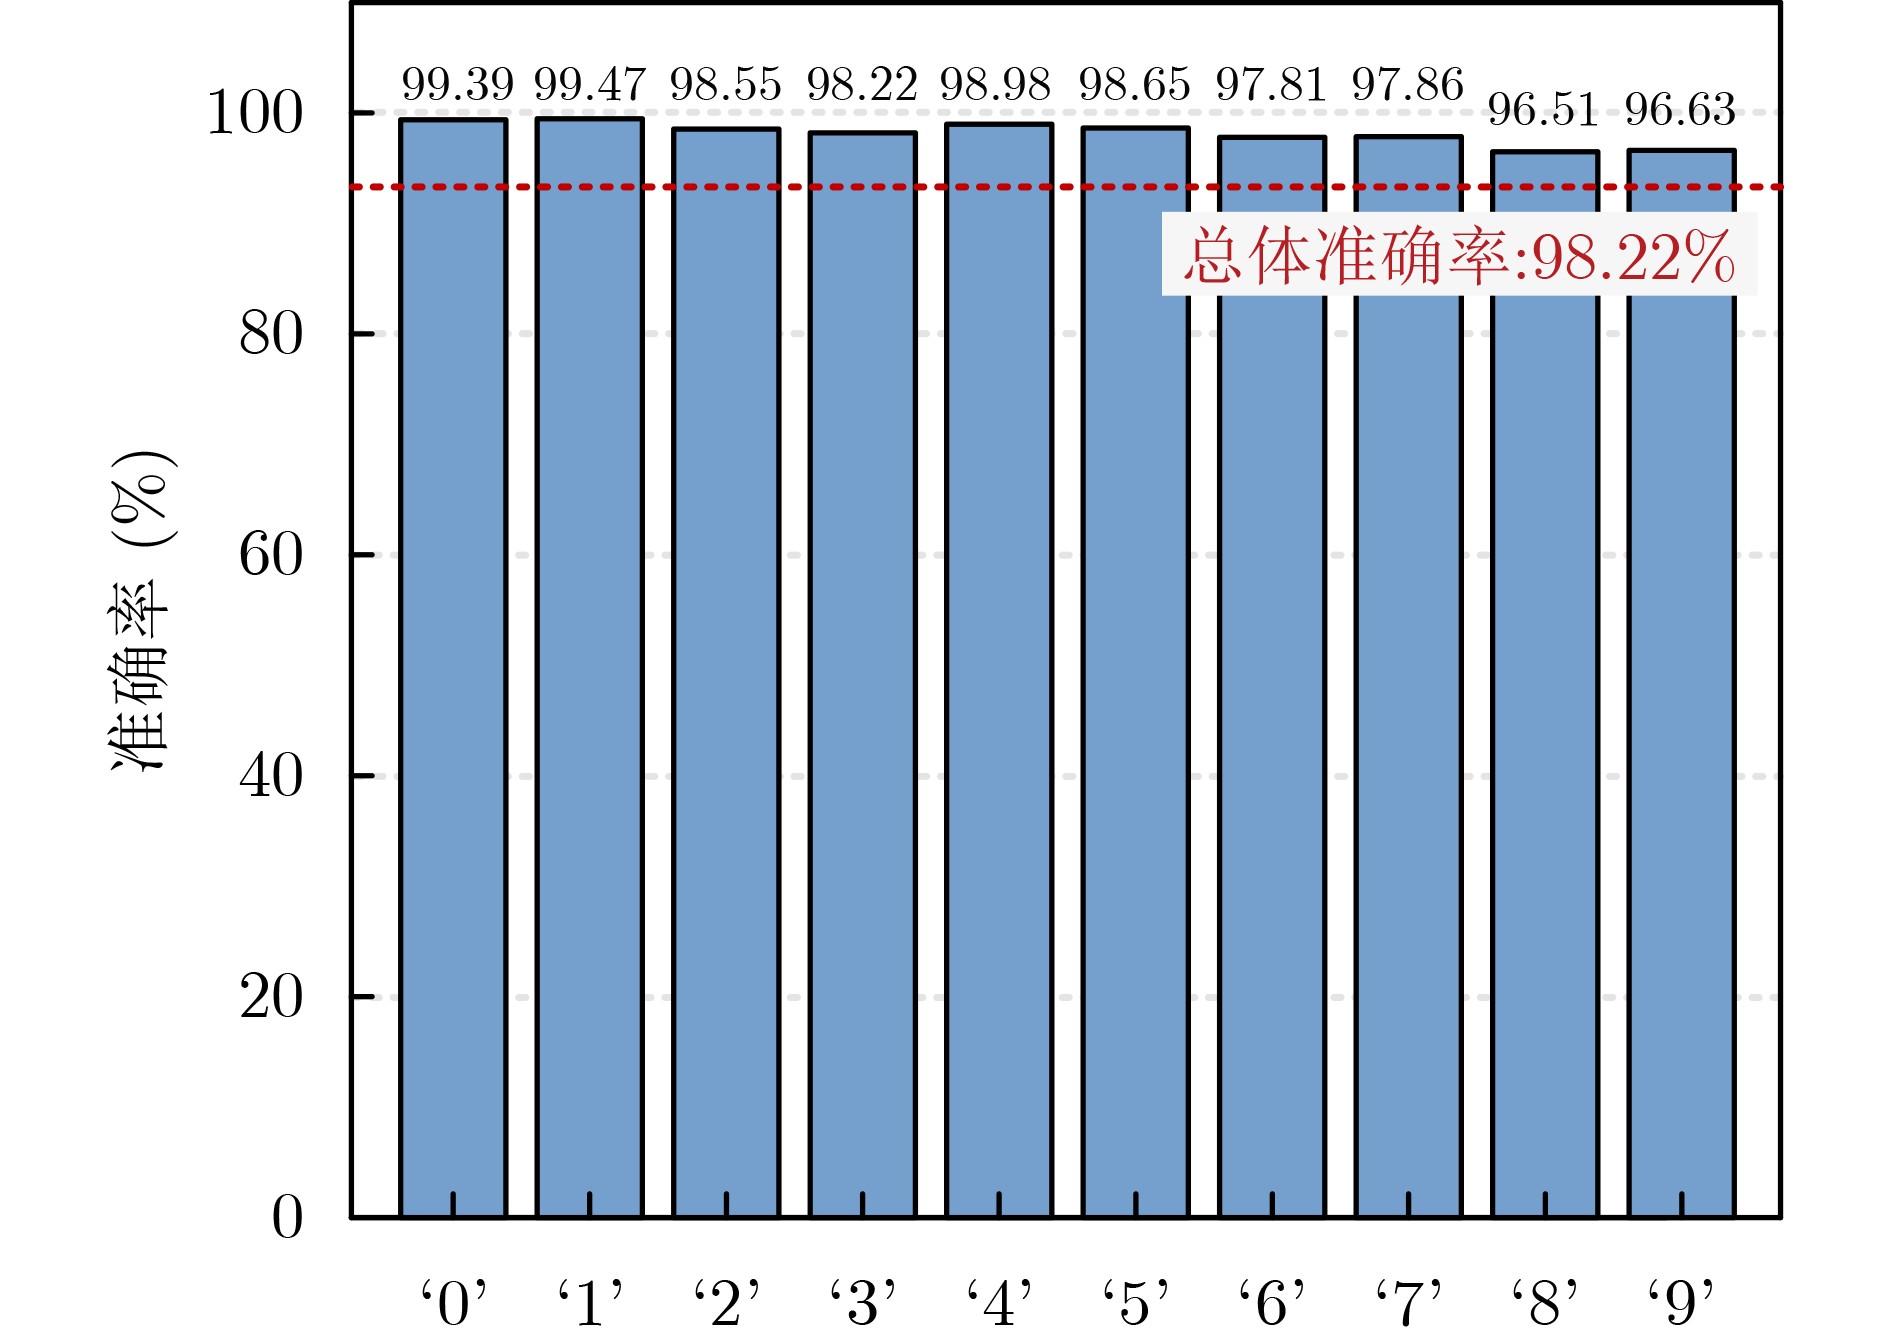
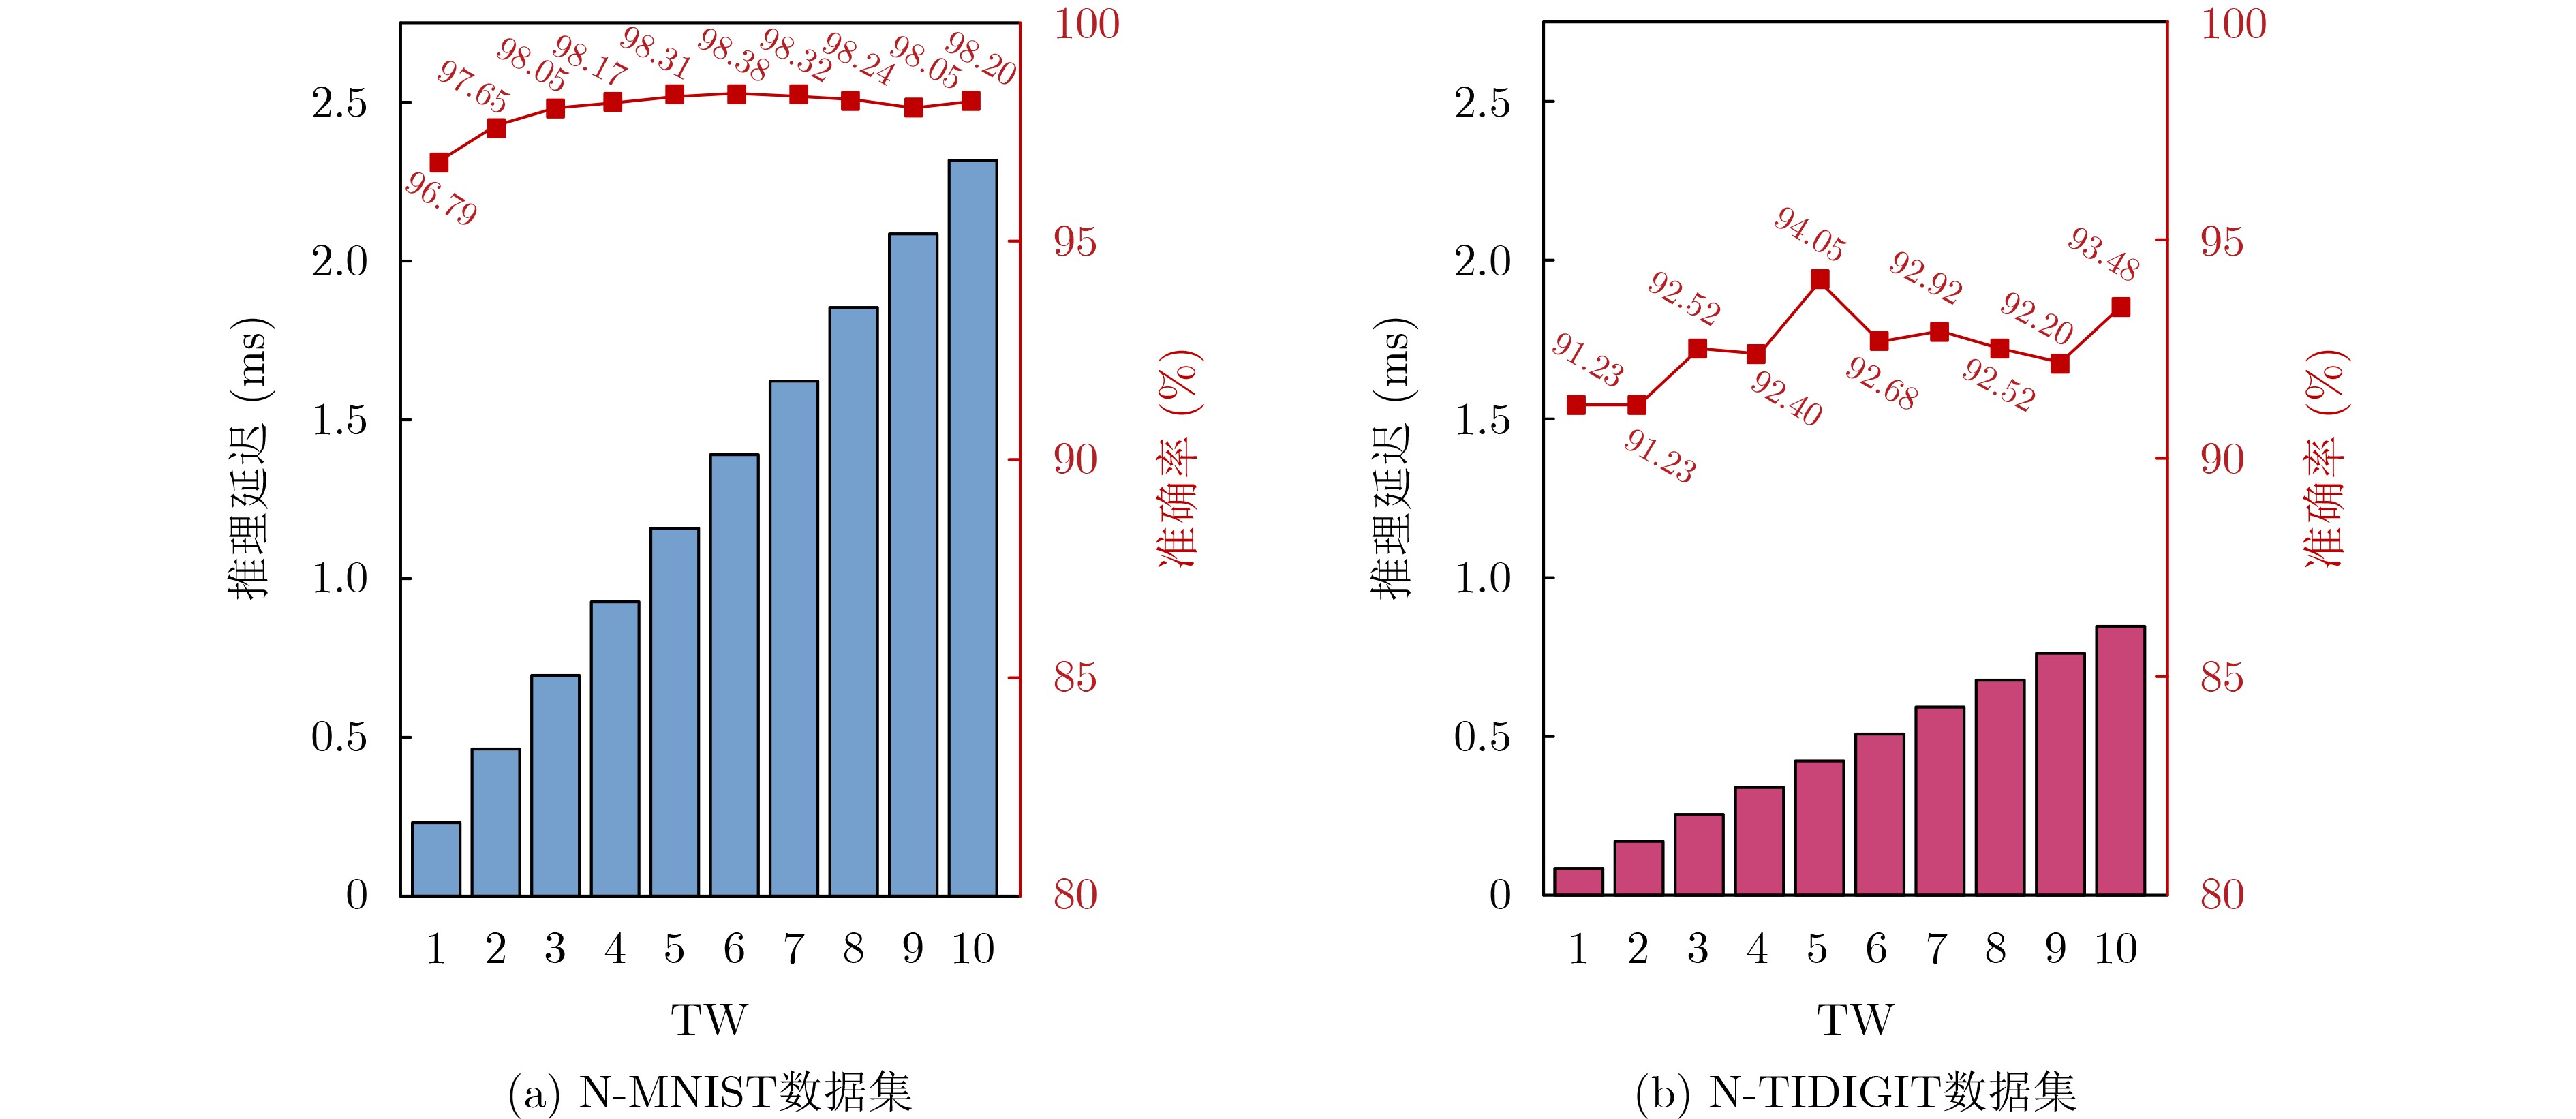
In recent years, hybrid convolutional neural network (CNN) and spiking neural network (SNN) accelerators have shown great potential for edge intelligence. However, existing designs typically employ fixed time windows (TW) for temporal integration, limiting their adaptability to tasks with different temporal complexities. This work presents a low-power hybrid CNN/SNN accelerator with configurable TWs. First, a configurable TW instruction set is developed based on the spatiotemporal complexity of different tasks to reduce inference latency and computational overhead. Second, a zero-skipping data-reuse processing array with unified CNN/SNN operator mapping is designed to improve computational resource utilization. Finally, an event-driven execution scheme and fine-grained clock-gating strategy are introduced to eliminate redundant operations and memory accesses during computation and data transfer. The proposed CNN/SNN accelerator is fabricated in a 28-nm TSMC CMOS process, occupying a core area of 0.75 mm2. At 0.81 V and 100 MHz, it achieves classification accuracies ranging from 75.3% to 98.4% across MIT-BIH, N-TIDIGITS, N-MNIST, IMAGE-100, and UniMiB SHAR, with a minimum energy consumption of 147.78 nJ per inference. Compared with prior works, the configurable-TW mechanism reduces energy consumption by 1.24×–7.6× while maintaining competitive classification accuracy, significantly improving the overall energy efficiency. Objective The goal of this work is to design an efficient and low-power CNN/SNN hybrid neuromorphic SoC based on the RISC-V architecture, addressing the limitations of conventional SNN hardware with fixed TW under different task requirements. By introducing a configurable TW mechanism, the temporal integration length can be flexibly adjusted according to task complexity, thereby reducing redundant time-step computations and lowering inference latency and energy consumption. Methods To address the varying time-window requirements of different tasks, this work presents a RISC-V-based SCNN processor with a configurable TW. First, a custom instruction set is developed to configure the TW threshold of the underlying hardware according to the complexity of input samples, enabling demand-driven computation while reducing inference latency and computational overhead. Second, a zero-skipping data-reuse processing array is designed to improve computational resource utilization. Finally, an event-driven execution mechanism and fine-grained clock-gating strategy are introduced to eliminate redundant operations and unnecessary memory accesses during computation and data transfer. The chip is fabricated in a 28-nm TSMC CMOS process with a core area of 0.75 mm2. Across MIT-BIH, N-TIDIGITS, N-MNIST, IMAGE-100, and UniMiB SHAR tasks, the accelerator achieves classification accuracies ranging from 75.3% to 98.4%, with a minimum energy consumption of 147.78 nJ per inference. Results and Discussions Experimental results validate the effectiveness of the proposed configurable-TW SCNN processor under diverse workloads. Cross-task analysis ( Fig. 7 ) shows that accuracy generally improves with increasing TW, but sensitivity varies significantly across tasks. Event-driven datasets such as N-MNIST and UniMiB SHAR exhibit strong temporal redundancy, achieving near-saturated accuracy (97.8%–98.4%) at small TW (≥3), whereas temporally dependent tasks like N-TIDIGITS require larger TW to maintain performance, indicating that TW demand is inherently data-modality dependent. Single-task evaluation (Fig. 8 andFig. 9 ) further demonstrates that reducing TW can significantly lower spike rates and computational cost with negligible accuracy degradation. The latency–accuracy trade-off (Fig. 10 ) reveals that blindly increasing TW leads to exponential growth in addition operations and inference latency without proportional accuracy gains. The optimal TW varies across tasks, highlighting the necessity of dynamic TW adaptation.Conclusions This work presents a hybrid hardware accelerator with a configurable TW. By dynamically adjusting the TW, the proposed design addresses the performance and energy-efficiency limitations of fixed temporal resolution in conventional SNN hardware. Implemented in a TSMC 28-nm process, the accelerator occupies a core area of only 0.75 mm2 and supports multimodal tasks, including physiological-signal, speech, visual, and activity recognition. It achieves classification accuracies of 75.3%–98.4% and a minimum energy consumption of 147.78 nJ per inference. Compared with fixed-TW designs, the proposed accelerator offers greater task adaptability, computational efficiency, and energy efficiency, reducing energy consumption by 1.24×–7.6× under the same process technology. -
Key words:
- Configurable time window /
- Spiking neural network /
- RISC-V /
- Hardware accelerator
-
表 1 与相关文献比较结果
参考 文献[13] 文献[14] 文献[15] 文献[16] 文献[17] 文献[18] 本文 工艺 28 nm 40 nm 28 nm 28 nm 28 nm 40 nm 28 nm 芯片
面积1.25 mm2 0.66 mm2 0.45 mm2 10.24 mm2 14.44 mm2 0.738 mm2 0.75 mm2 频率 40 MHz 30-130 MHz 13-115 MHz 100 MHz 300 MHz 30 MHz 100 MHz 内存 266.5 KB 66 KB 138 KB 1711 KB 3.3 MB 40 KB 64 KB 网络
类型SNN SNN SRNN SNN SNN SNN SCNN 位宽
(bits)8 bit 4 bit 8 bit 4 bit 8 bit 8 bit 8/4 bit 数
据
集N-MNIST
N-TIDIGIT
IBM DVS
GestureMIT-BIH
MNIST
N-MNISTIBM DVS Gesture
Spiking
Heidelberg Digits
Delayed cue
integrationMNIST
N-MNIST
GestureMNIST
CIFAR10MIT-BIH
ETH-80
MNISTMIT-BIH
N-TIDIGIT
N-MNIST
UniMiB SHAR
IMAGE-100网络
架构1024 -512-10ECG: 96-80-40 -5
IMAGE: 256-128-10
IMAGE-A: 384-128-10256-256-16 N/A N/A N/A ECG:c16-c32-c32-fc32-5
KWS:c32-c128-f64-11
IMAGE-A:c32-c32-f64-10
HAR:c32-c64-c64-f64-9
CIFAR-100: Resnet-18准
确
率IMAGE-A:96%
KWS:92.6%
Gesture:92%ECG:97.12%
IMAGE:97.26%
IMAGE-A:96.08%Gesture: 87.3%
KWS:90.7%
Nav:96.4%MNIST:99.2%
N-MNIST:98.2%
Gesture:94.3%MNIST:
99.48%
CIFAR10:
93.52%ECG:89.8%
Object:94.2%
IMAGE:
81.8%ECG:97.6%
KWS:94.5%
IMAGE-A:98.4%
HAR:98.28%
IMAGE-B: 75.3%分类/
能效IMAGE-A: 343 nJ
KWS: 6.1 μJ
Gesture:3.9 μJECG:42.57 nJ
IMAGE:146.8 nJ
IMAGE-A:
194.6nJGesture:46.1 μJ
KWS: 4.4 μJ
Nav:1.4 μJIMAGE:0.91mJ
IMAGE-A:
2.1mJ
Gesture:3.6mJMNIST:76.6 μJ
CIFAR10:
4.2mJECG:97.7 nJ
Object:6.3μJ
IMAGE:
27.35 μJECG:147.78 nJ
KWS: 202.54 nJ
IMAGE-A:276.33 nJ
HAR: 1.41 μJ
IMAGE-B: 155 μJ 下载: 导出CSV
-
[1] 王子华, 叶莹, 刘洪运, 等. 基于脉冲序列标识的深度脉冲神经网络时空反向传播算法[J]. 电子与信息学报, 2024, 46(6): 2596–2604. doi: 10.11999/JEIT230705.WANG Zihua, YE Ying, LIU Hongyun, et al. Spiking sequence label-based spatio-temporal back-propagation algorithm for training deep spiking neural networks[J]. Journal of Electronics & Information Technology, 2024, 46(6): 2596–2604. doi: 10.11999/JEIT230705. [2] 卢迪, 王振发. 脉动阵列协同层融合的卷积神经网络加速器设计[J]. 电子与信息学报, 2026, 48(3): 1280–1291. doi: 10.11999/JEIT250867.LU Di and WANG Zhenfa. Design of a CNN accelerator based on systolic array collaboration with inter-layer fusion[J]. Journal of Electronics & Information Technology, 2026, 48(3): 1280–1291. doi: 10.11999/JEIT250867. [3] 周雅, 栗心怡, 武喜艳, 等. 基于DT-LIF神经元与SSD的脉冲神经网络目标检测方法[J]. 电子与信息学报, 2023, 45(8): 2722–2730. doi: 10.11999/JEIT221367.ZHOU Ya, LI Xinyi, WU Xiyan, et al. Object detection method with spiking neural network based on DT-LIF neuron and SSD[J]. Journal of Electronics & Information Technology, 2023, 45(8): 2722–2730. doi: 10.11999/JEIT221367. [4] LI Qikang, WANG Lixun, ZHANG Huihong, et al. FinSAA: Sparse-aware CNN accelerator with fast irregular index decoding and adaptive dense-sparse convolution architecture[J]. IEEE Transactions on Very Large Scale Integration (VLSI) Systems, 2026, 34(9): 2769–2782. doi: 10.1109/TVLSI.2026.3697791. [5] AKOPYAN F, SAWADA J, CASSIDY A, et al. TrueNorth: Design and tool flow of a 65 mW 1 million neuron programmable neurosynaptic chip[J]. IEEE Transactions on Computer-Aided Design of Integrated Circuits and Systems, 2015, 34(10): 1537–1557. doi: 10.1109/TCAD.2015.2474396. [6] DAVIES M, SRINIVASA N, LIN T H, et al. Loihi: A neuromorphic manycore processor with on-chip learning[J]. IEEE Micro, 2018, 38(1): 82–99. doi: 10.1109/MM.2018.112130359. [7] ZHANG Tao, ZHONG Yi, YANG Youming, et al. UniPRE: An SNN-ANN accelerator with unified max-pooling prediction and redundancy elimination[J]. IEEE Transactions on Circuits and Systems II: Express Briefs, 2025, 72(8): 1088–1092. doi: 10.1109/TCSII.2025.3582265. [8] KIM S, KIM S, HONG S, et al. C-DNN: An energy-efficient complementary deep-neural-network processor with heterogeneous CNN/SNN core architecture[J]. IEEE Journal of Solid-State Circuits, 2024, 59(1): 157–172. doi: 10.1109/JSSC.2023.3330483. [9] LIEN H H, HSU C W, and CHANG T S. VSA: Reconfigurable vectorwise spiking neural network accelerator[C]. Proceedings of the 2021 IEEE International Symposium on Circuits and Systems, Daegu, Korea, 2021: 1–5. doi: 10.1109/ISCAS51556.2021.9401181. [10] LI Yuhang, MOITRA A, TGELLER T, et al. Input-aware dynamic timestep spiking neural networks for efficient in-memory computing[C]. Proceedings of the 2023 60th ACM/IEEE Design Automation Conference, San Francisco, USA, 2023: 1–6. doi: 10.1109/DAC56929.2023.10247869. [11] CHEN Boyu and CHANG T S. Hardware efficient accelerator for spiking transformer with reconfigurable parallel time step computing[C]. Proceedings of the 2025 IEEE International Symposium on Circuits and Systems, London, United Kingdom, 2025: 1–5. doi: 10.1109/ISCAS56072.2025.11043330. [12] IZHIKEVICH E M. Simple model of spiking neurons[J]. IEEE Transactions on Neural Networks, 2003, 14(6): 1569–1572. doi: 10.1109/TNN.2003.820440. [13] ZHANG Jilin, HUO Dexuan, ZHANG Jian, et al. ANP-I: A 28-nm 1.5-pJ/SOP asynchronous spiking neural network processor enabling Sub-0.1-μJ/sample on-chip learning for edge-AI applications[J]. IEEE Journal of Solid-State Circuits, 2024, 59(8): 2717–2729. doi: 10.1109/JSSC.2024.3357045. [14] YANG Jinqiao, ZHU Zikai, CHU Haoming, et al. A 0.66-mm2 0.49 pJ/SOP SNN processor with temporal-spatial post-neuron-processing and model-adaptive crossbar in 40-nm CMOS[J]. IEEE Transactions on Biomedical Circuits and Systems, 2025, 19(6): 1187–1201. doi: 10.1109/TBCAS.2025.3582246. [15] FRENKEL C and INDIVERI G. ReckOn: A 28nm Sub-mm2 task-agnostic spiking recurrent neural network processor enabling on-chip learning over second-long timescales[C]. Proceedings of the 2022 IEEE International Solid-State Circuits Conference, San Francisco, USA, 2022: 1–3. doi: 10.1109/ISSCC42614.2022.9731734. [16] CHEN Faquan, TIAN Qingyang, XIE Lisheng, et al. EPOC: A 28-nm 5.3 pJ/SOP event-driven parallel neuromorphic hardware with neuromodulation-based online learning[J]. IEEE Transactions on Biomedical Circuits and Systems, 2025, 19(3): 629–644. doi: 10.1109/TBCAS.2024.3470520. [17] DENG Lei, WANG Guanrui, LI Guoqi, et al. Tianjic: A unified and scalable chip bridging spike-based and continuous neural computation[J]. IEEE Journal of Solid-State Circuits, 2020, 55(8): 2228–2246. doi: 10.1109/JSSC.2020.2970709. [18] FANG Chaoming, WANG Chuanqing, ZHAO Shiqi, et al. A 510 μW 0.738-mm2 6.2-pJ/SOP online learning multi-topology SNN processor with unified computation engine in 40-nm CMOS[J]. IEEE Transactions on Biomedical Circuits and Systems, 2023, 17(3): 507–520. doi: 10.1109/TBCAS.2023.3279367. -

 下载:

图(10) / 表(1)
计量
- 文章访问数: 15
- HTML全文浏览量: 1
- PDF下载量: 2
- 被引次数: 0
