

Software-Hardware Co-Optimization of SwiGLU and RMSNorm Operators for Edge Deployment of Large Models
-
摘要: 当前大模型的端侧部署应用中,非线性算子已逐步成为性能瓶颈。因此针对SwiGLU与RMSNorm两类高频算子,开展算法与硬件协同的优化方法研究。为解决SwiGLU中SiLU激活计算复杂、硬件代价较高的问题,提出基于分布感知分段建模与2n多项式斜率拟合的近似方法,并设计两级区间判定数据通路以降低电路复杂度;针对RMSNorm,提出词元(token)级重叠流式架构,通过多bank缓冲、选择性压缩与倒数平方根指数补偿等方式实现统计路径与缩放路径的解耦。基于TinyLlama-1.1B的算法评估与FPGA实现结果表明,所提方法在保持模型性能可用的同时,能够显著降低非线性算子的资源开销与功耗,适用于大模型端侧部署场景。Abstract:
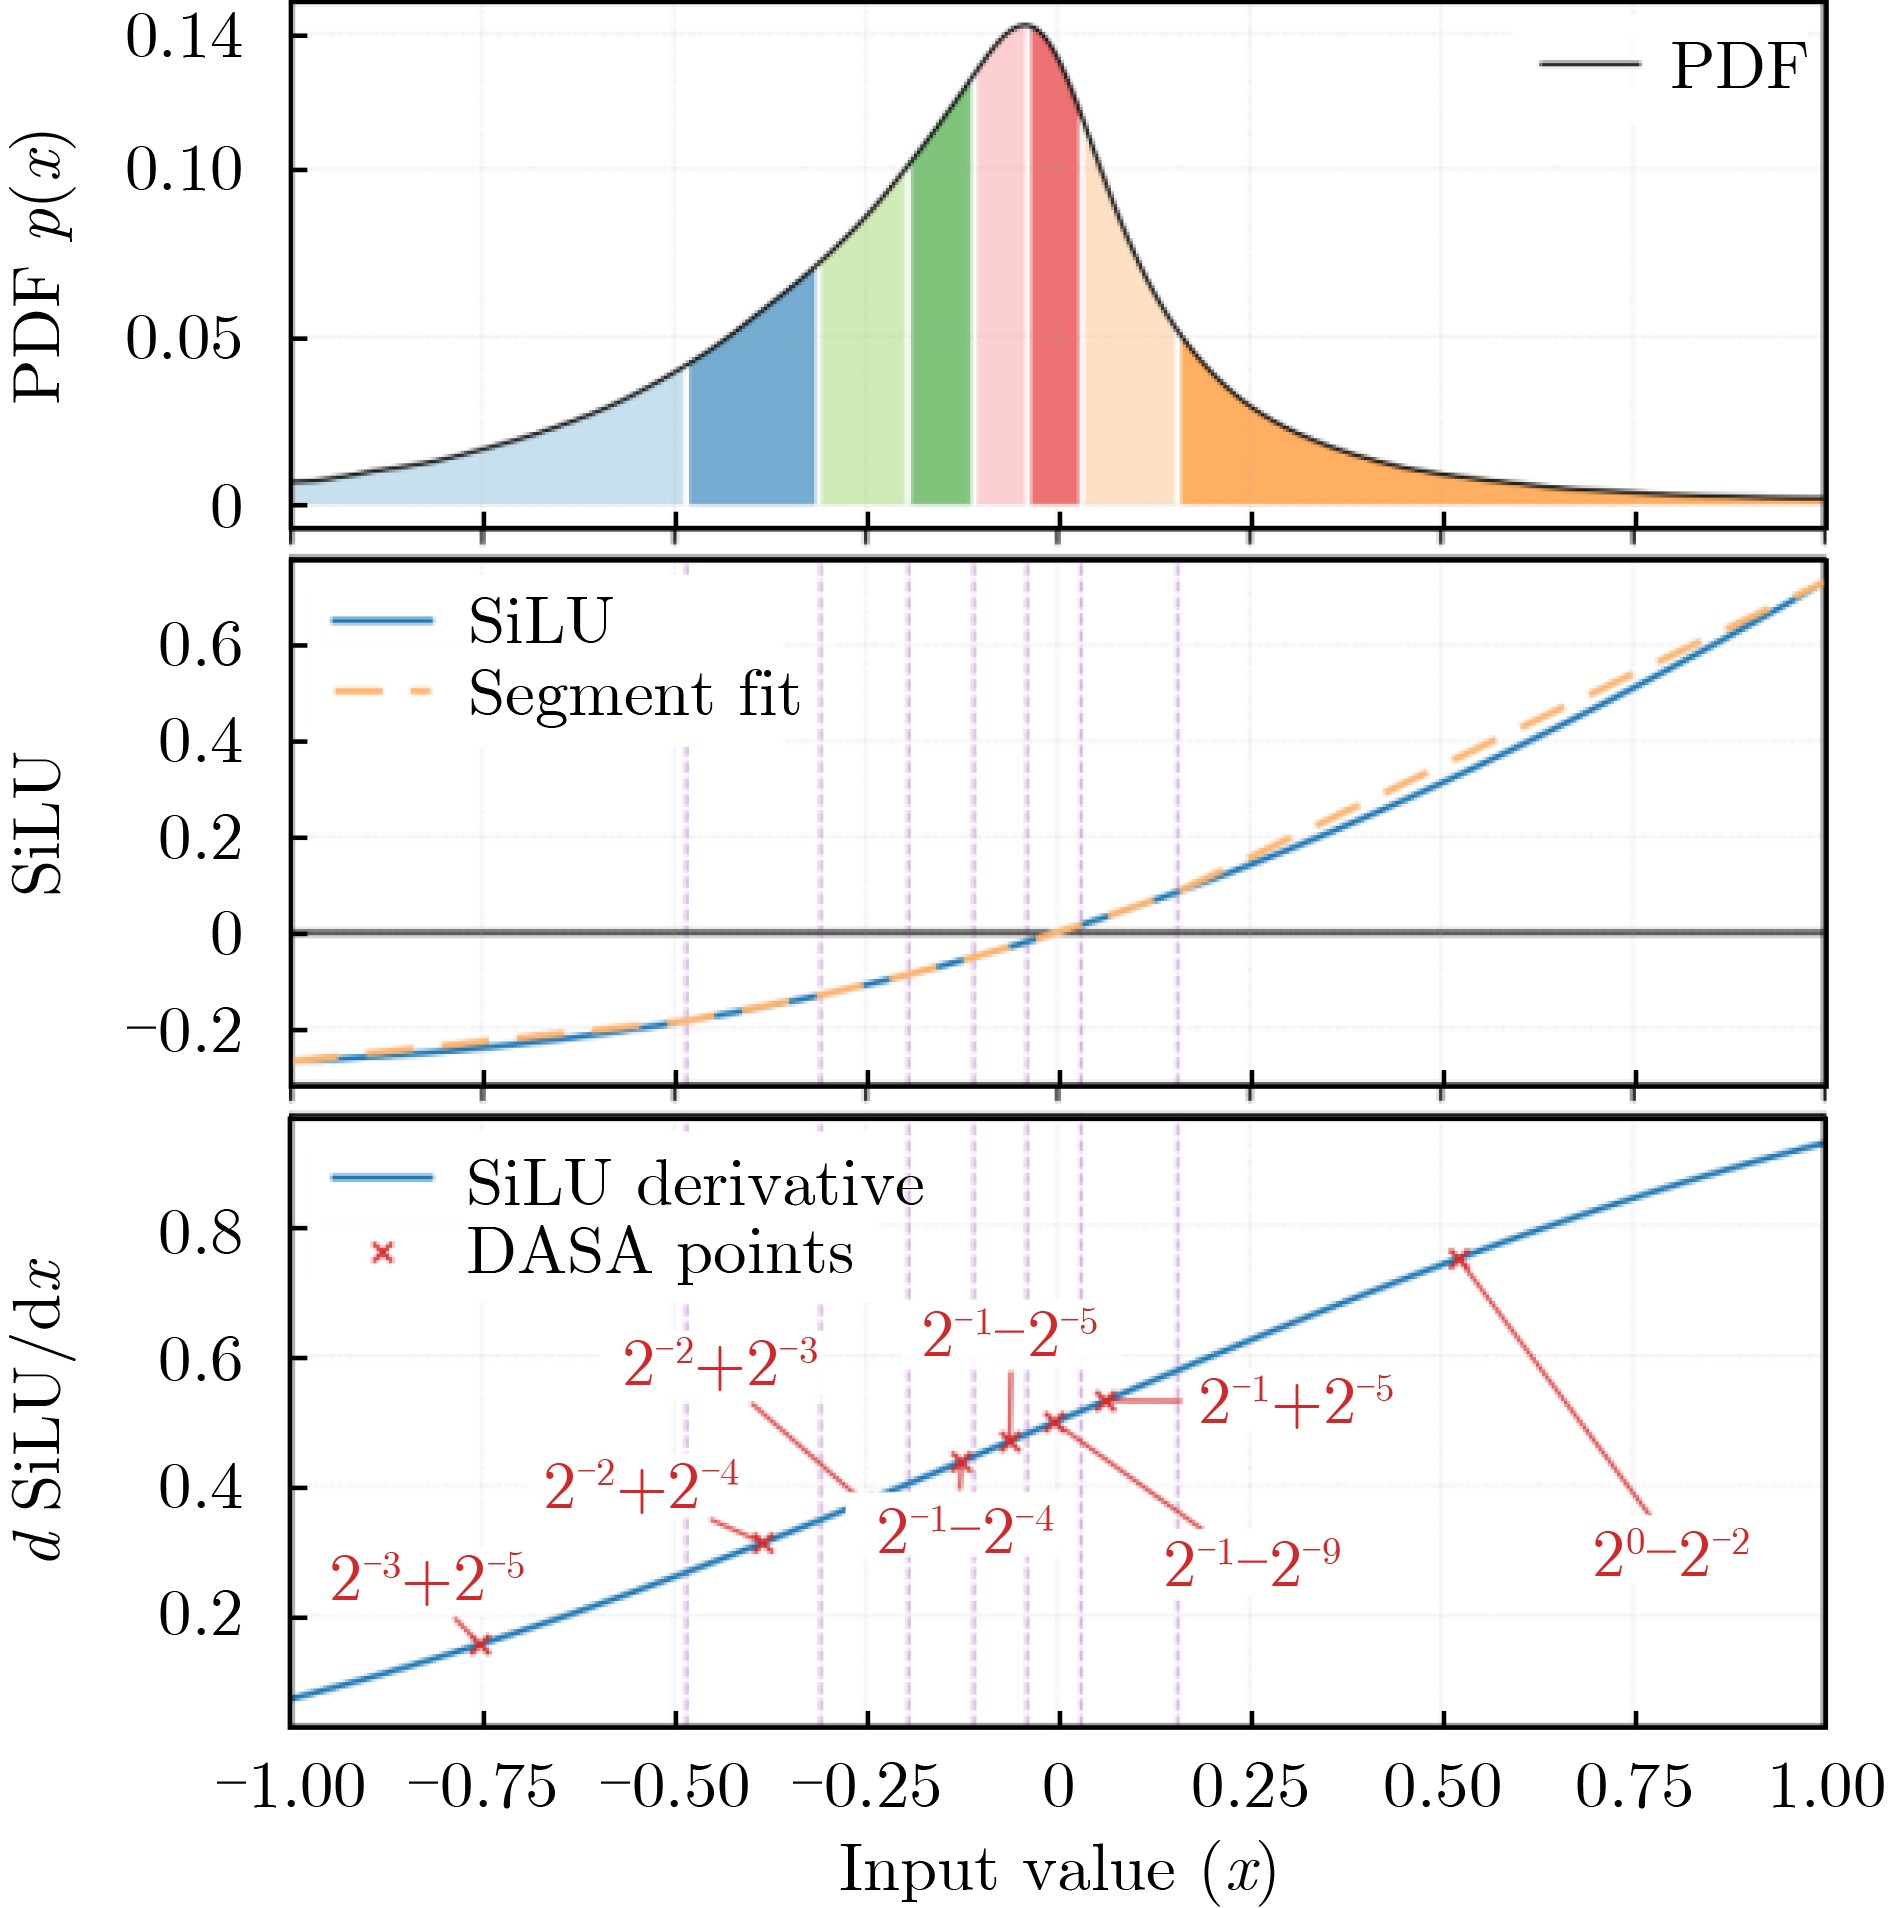
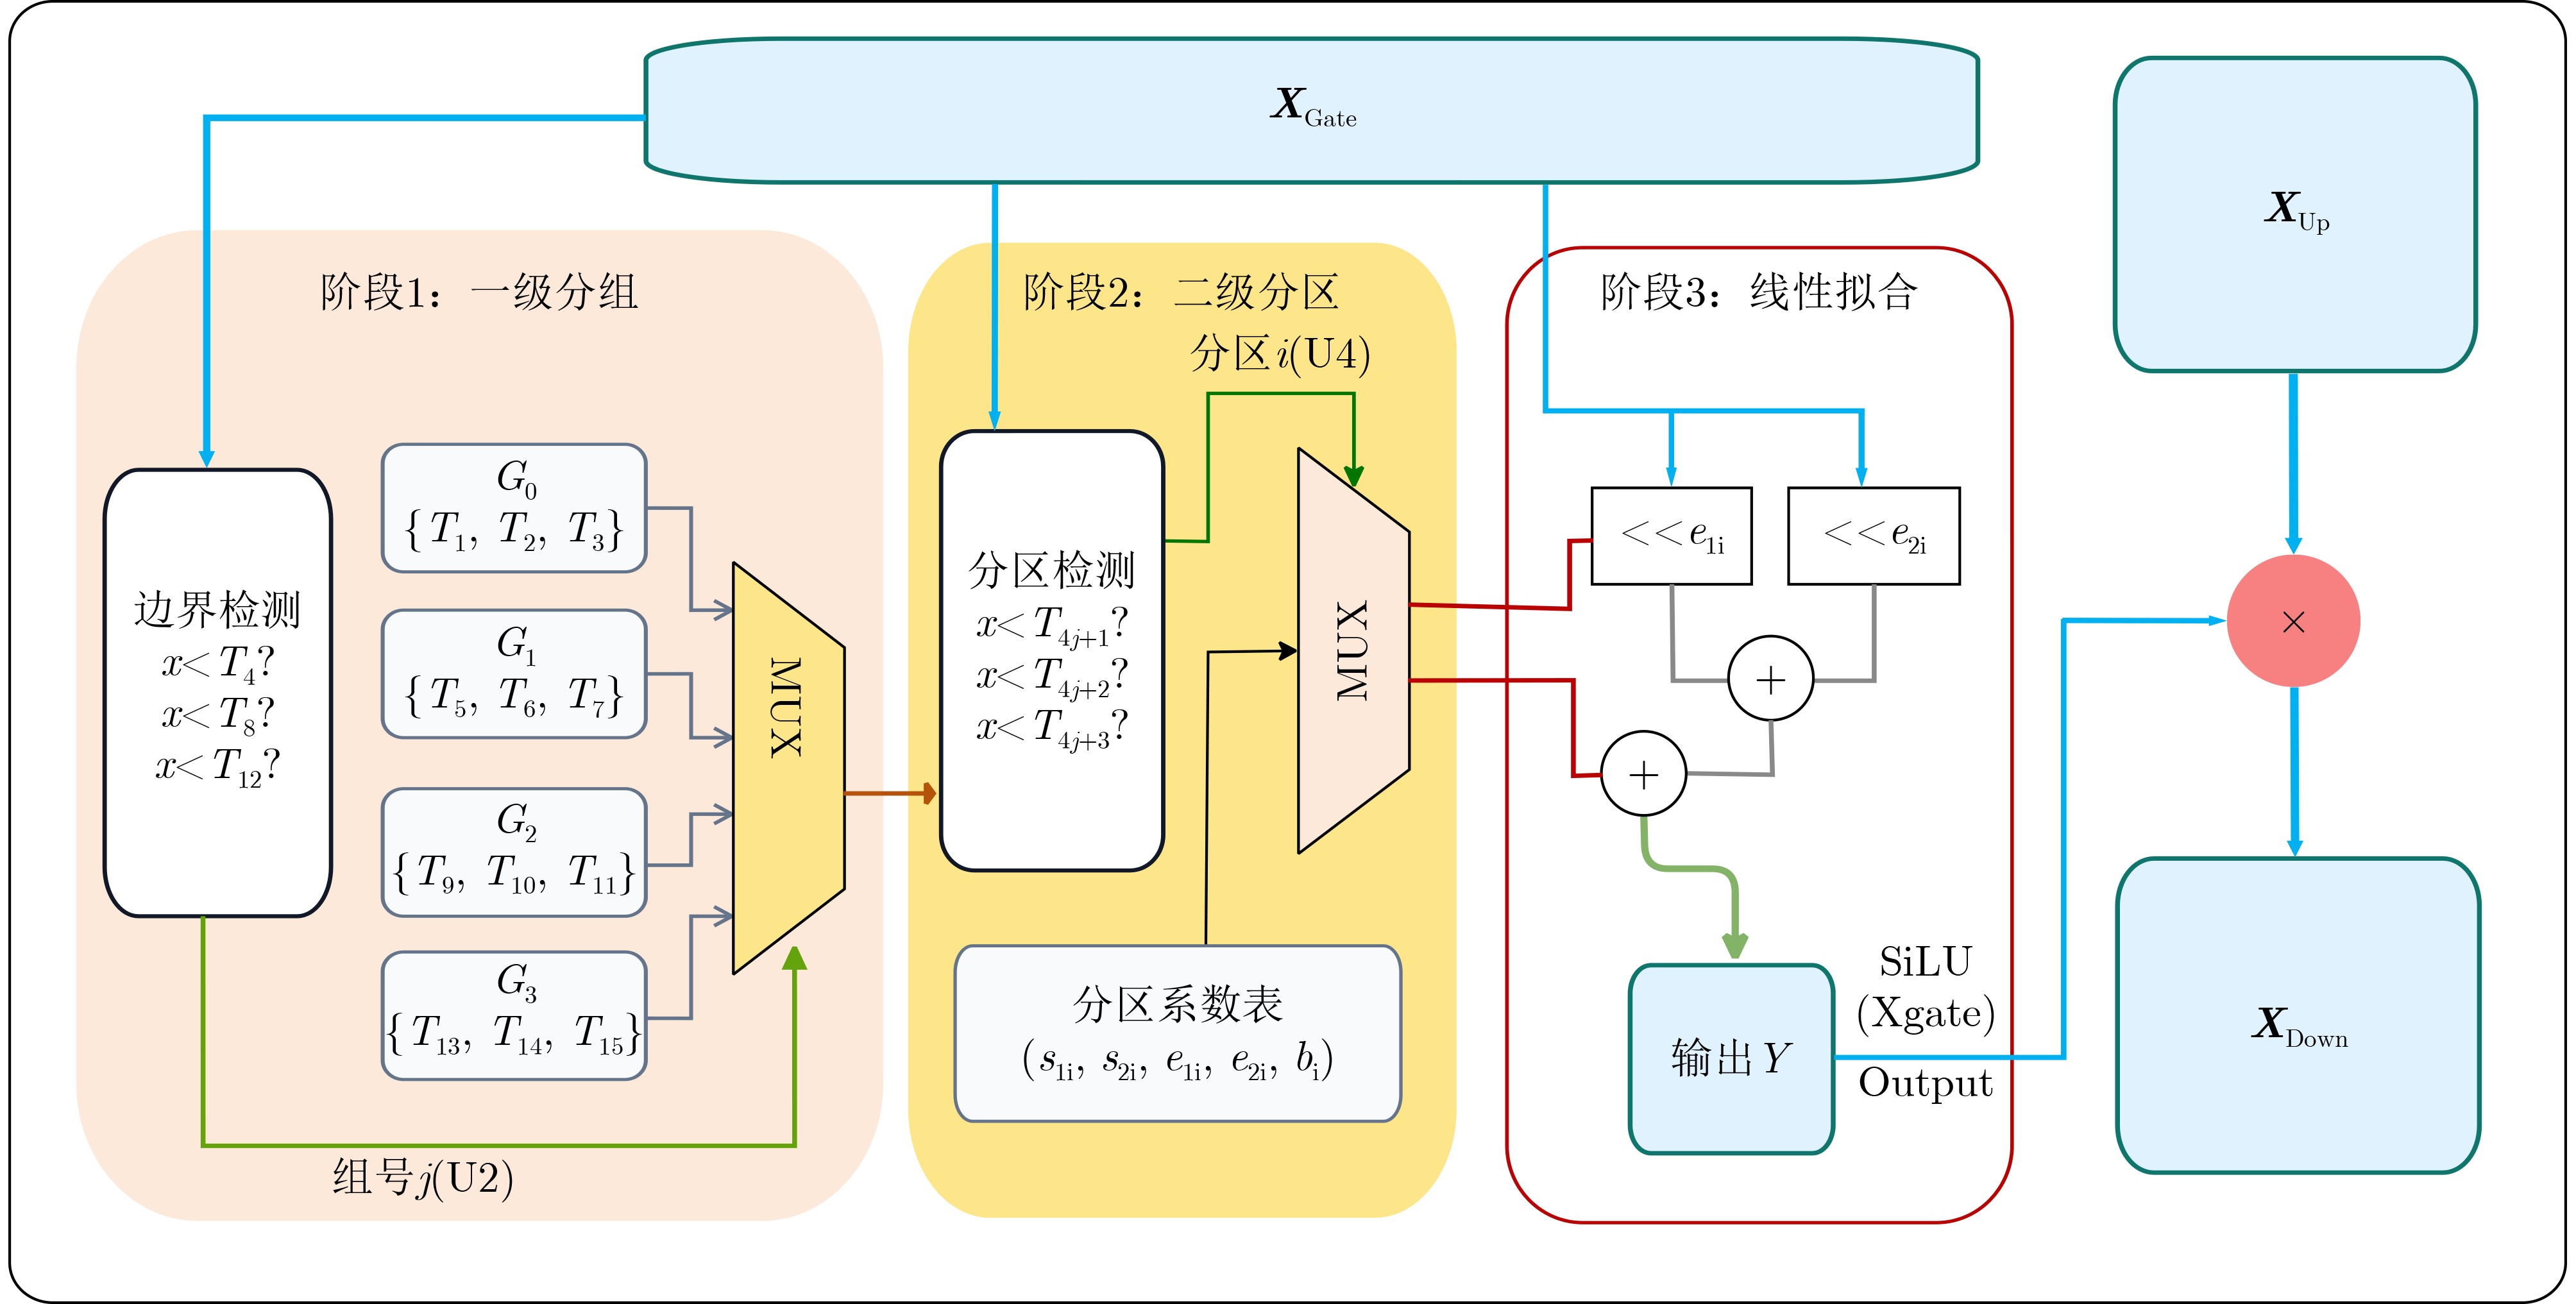
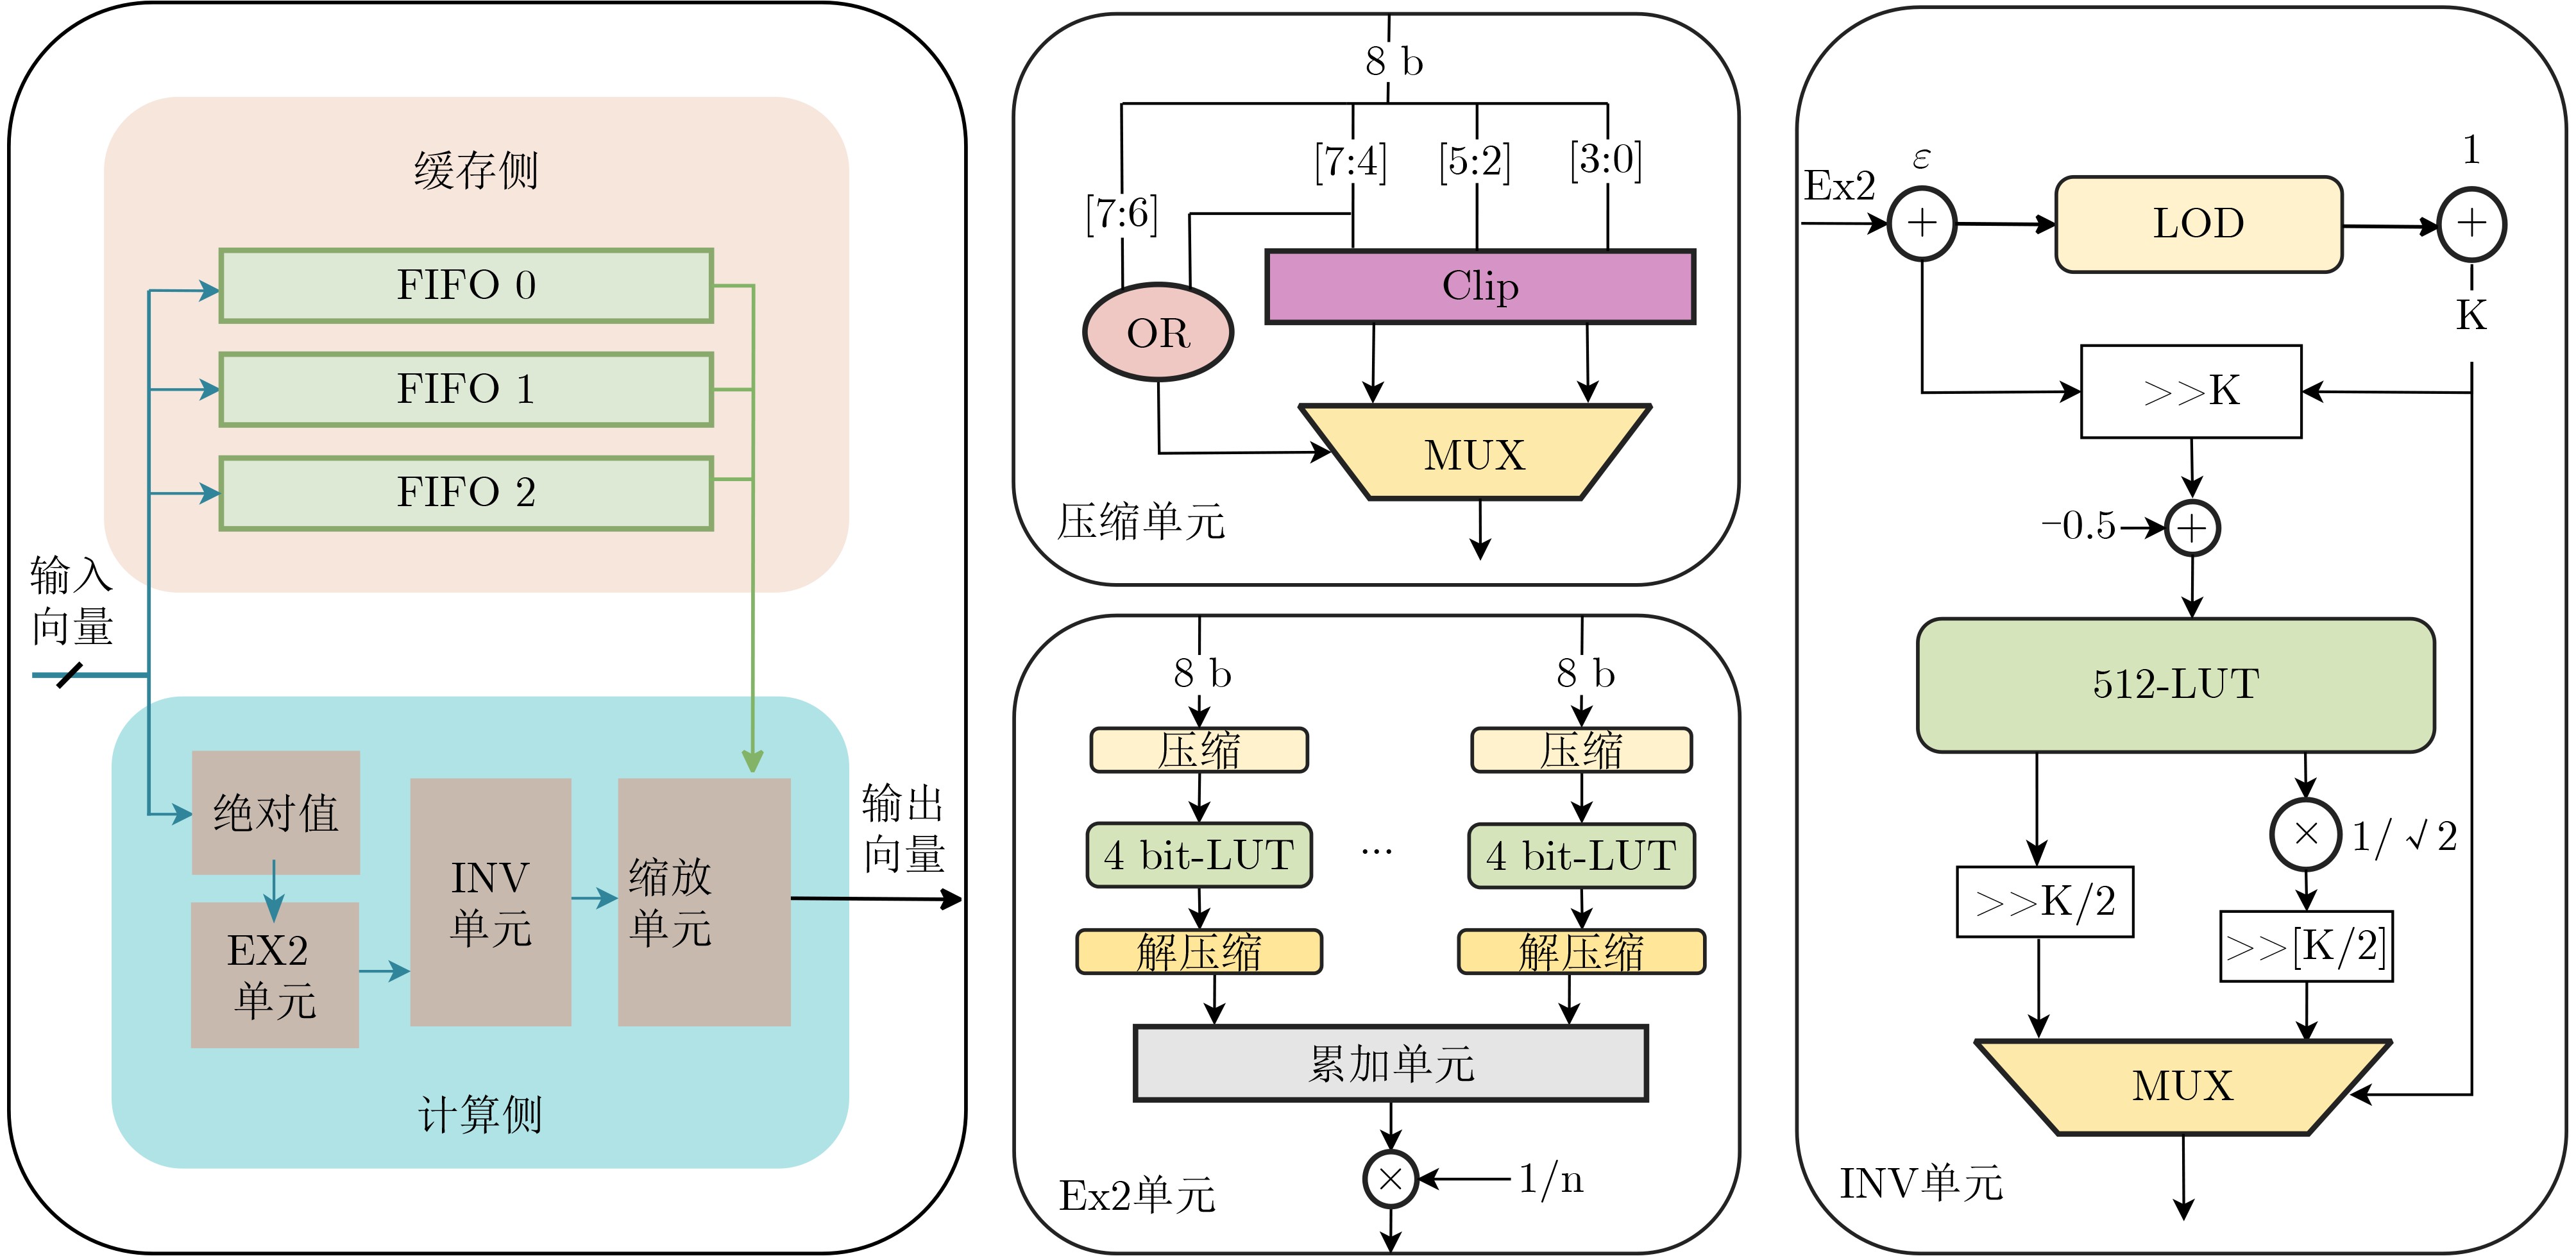
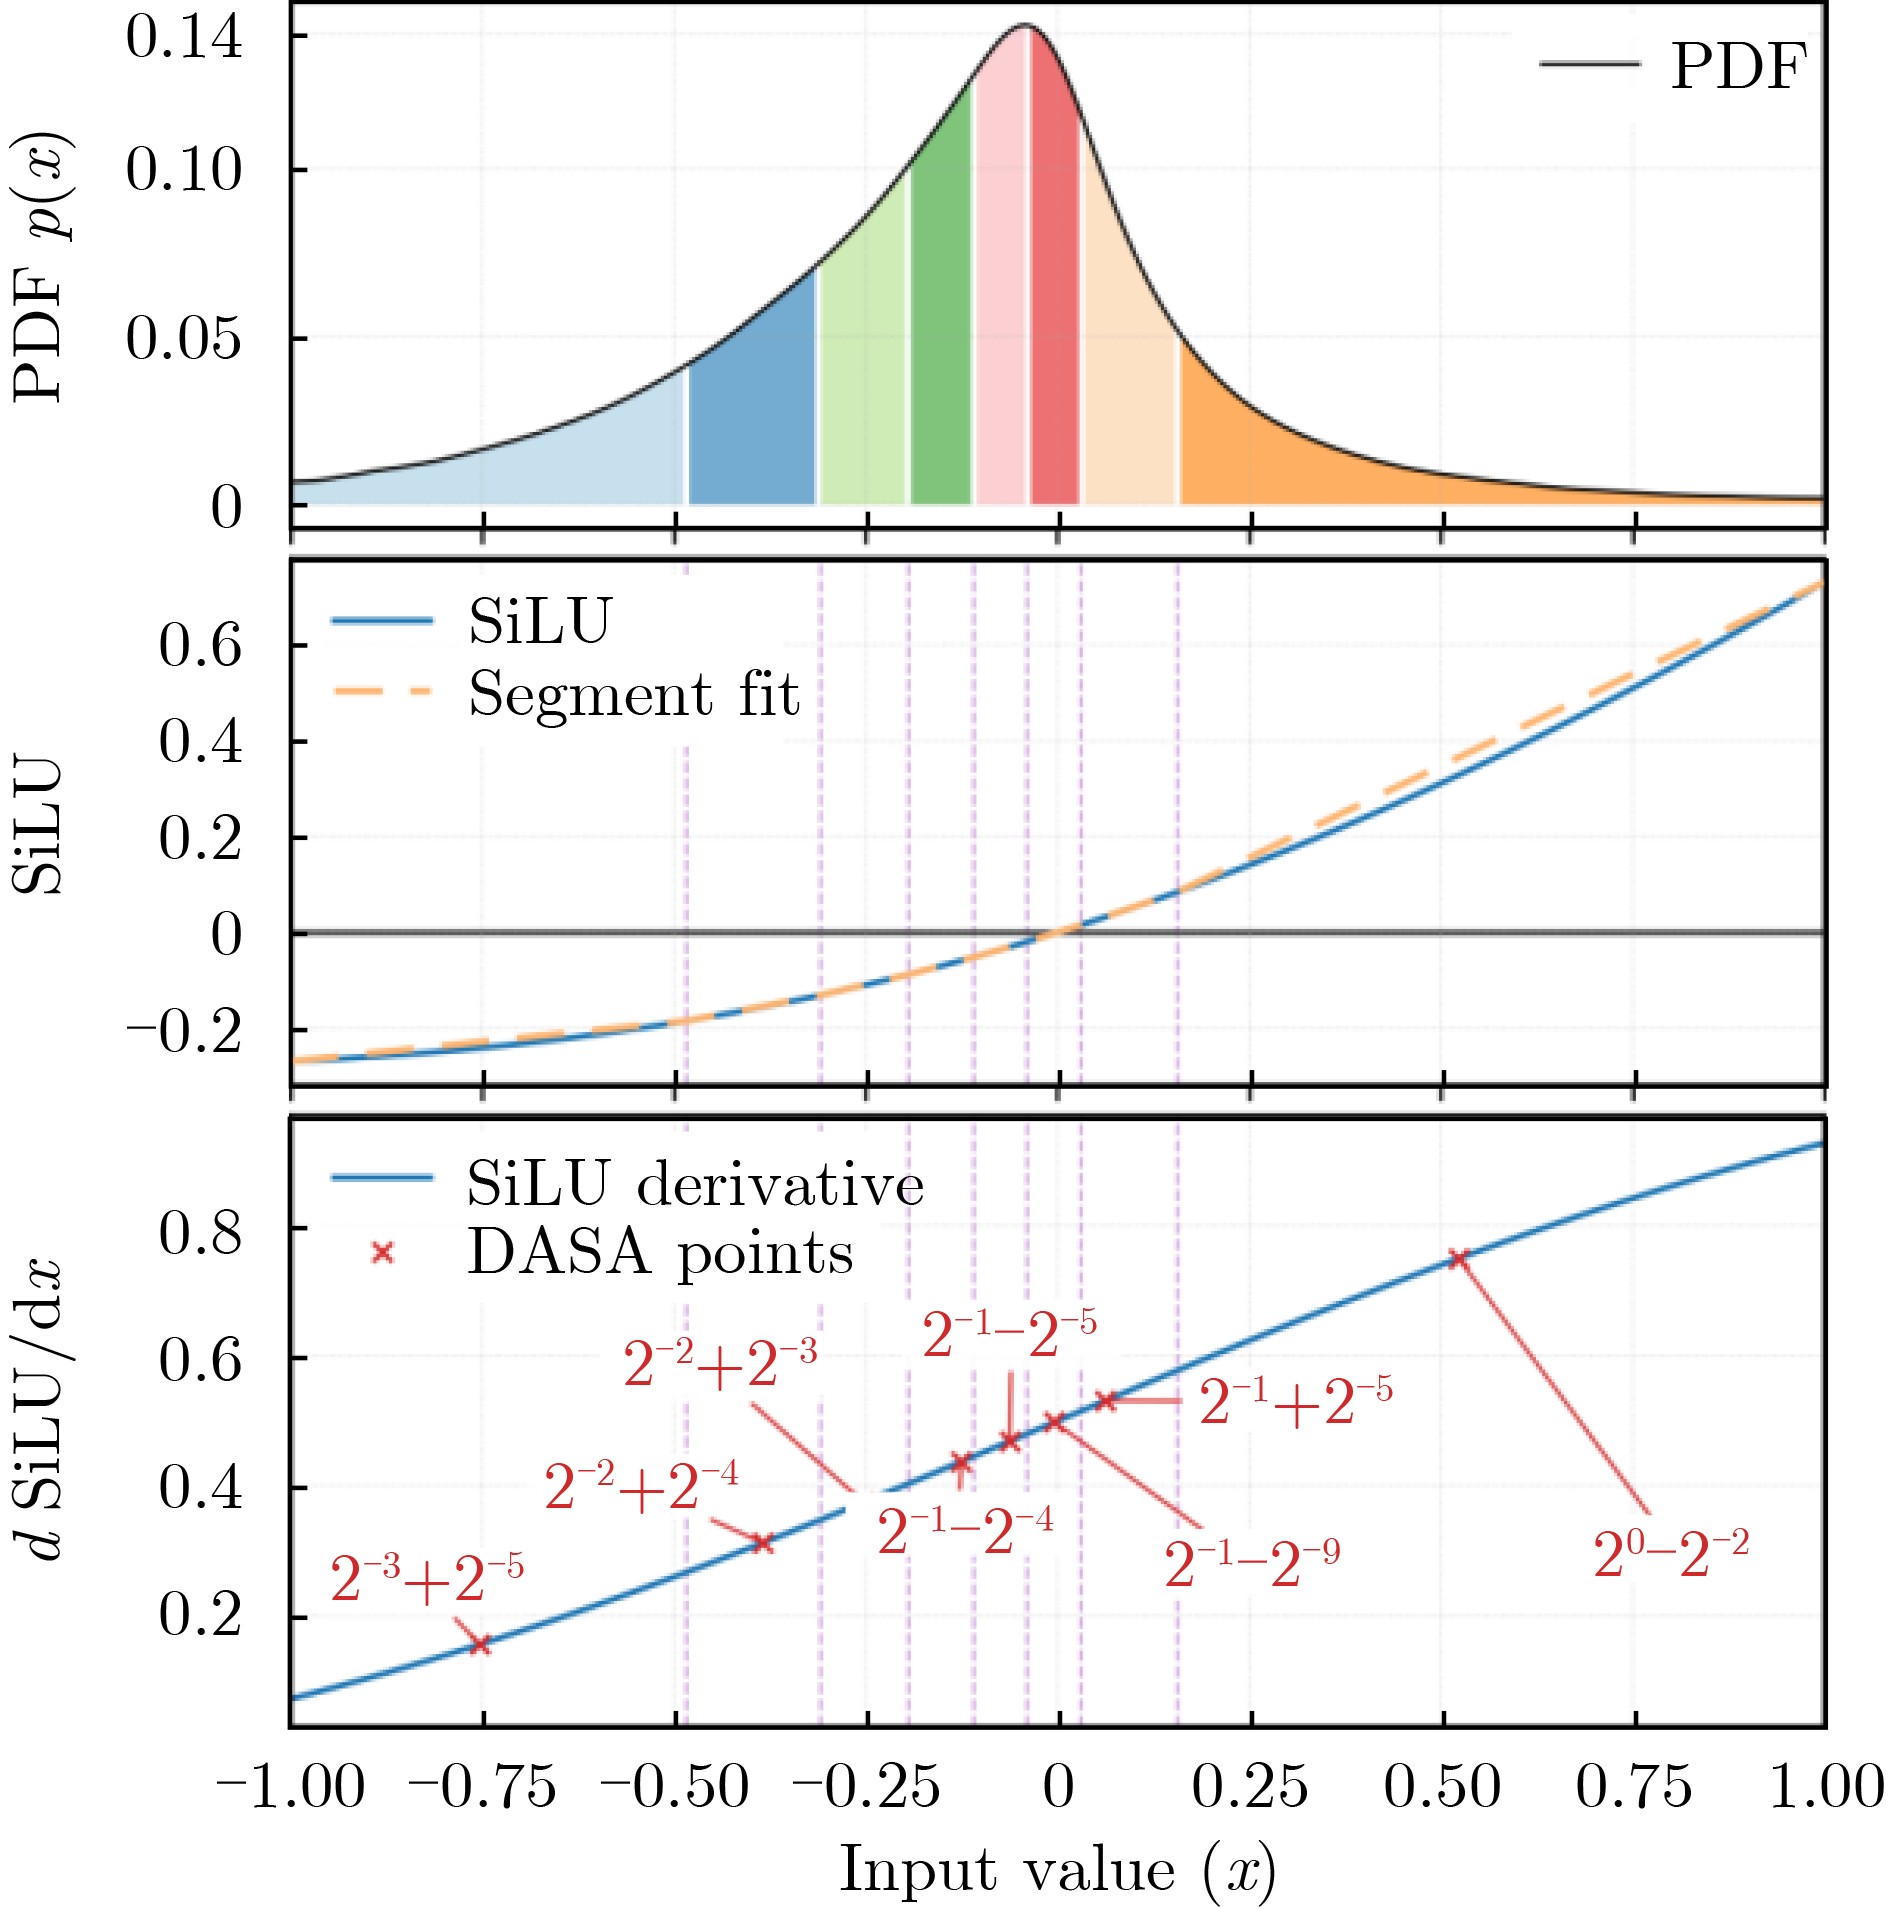
Objective Large-model inference is increasingly moving from cloud platforms to edge devices, where power, on-chip storage, memory bandwidth, and programmable logic resources are strictly constrained. As matrix multiplication and attention are progressively accelerated through quantization and dedicated architectures, nonlinear operators account for a growing proportion of end-to-end latency and energy consumption. SwiGLU and RMSNorm are now widely used in large language and multimodal models, but both remain difficult to map efficiently onto resource-constrained hardware. The SiLU function within SwiGLU ordinarily requires exponential, division, polynomial, or large lookup-table operations, whereas RMSNorm combines vector-wide square accumulation, inverse-square-root computation, and broadcast scaling under a strict reduction-before-scaling dependency. This study therefore investigates operator-specific software-hardware co-optimization strategies for these two nonlinear operators. The objective is to reduce arithmetic complexity, hardware-resource utilization, and power consumption while preserving full operator functionality and external streaming interfaces, with model quality maintained at a level suitable for practical edge deployment. Particular attention is paid to the different error sensitivities of activation and normalization approximations, because a function-level approximation that is efficient in hardware may still degrade task-level performance after its errors propagate through the network. Methods For SwiGLU, a Distribution-Aware Shift-Add approximation, termed DASA, is developed for the SiLU path. INT8 gate-activation samples are first collected from TinyLlama-1.1B. Approximately 97.0% of the samples fall within [–1, 1], while the remaining samples form sparse long tails. An empirical cumulative distribution function is therefore used to clip the tails at selected quantiles and divide the retained domain into non-uniform intervals with approximately equal probability mass. Dense regions receive finer segmentation, whereas low-probability regions receive coarser segmentation, enabling a limited segment budget to focus on frequently occurring inputs ( Fig. 1 ). For each interval, the slope is selected from a discrete candidate set in which every value is represented by a combination of two power-of-two terms. The candidate that minimizes the local fitting error around a derivative-based representative point is selected, and the intercept is then determined by constraining the fitted line to pass through that point. The resulting parameter-generation procedure, followed by gate activation, element-wise multiplication with the up branch, and down projection, is summarized in Algorithm 1. Because the slope constraint is imposed during fitting rather than after floating-point optimization, each segment can be directly implemented using shift operations, an adder or subtractor, and a constant bias.The corresponding SwiGLU hardware preserves the complete gate-by-up computation and replaces only the computationally expensive SiLU path. A two-stage interval-decision network is employed. The first stage compares the input with a small set of group boundaries and records the selected group, whereas the second stage performs only the local comparisons within that group. For a 16-segment configuration, a compact coefficient table supplies the shift exponents and bias, after which multiplexers and a shift-add datapath evaluate the approximation (Fig. 2 ). This organization avoids a long flat comparator chain and eliminates the exponential and division units used in the baseline. Both the baseline and optimized complete SwiGLU operators use signed 16-bit Q12 data and a three-stage valid-ready pipeline. The baseline approximates the exponential term over [–8, 8] using a sixth-order Taylor expansion and implements division in RTL, whereas the optimized design uses the DASA datapath under the same interface and implementation constraints.For RMSNorm, selective compression is applied to the mean-square statistics path. The magnitude of each signed INT8 input is reduced to a 4-bit value according to its high-order bits. The compressed value is clipped to [0, 15], squared using a 4-bit lookup table, and rescaled using a shift amount indicated by a one-bit compression flag. This transformation replaces high-width squaring with comparison, selection, small-table, and shift operations. The inverse-square-root factor is generated by decomposing the positive mean-square term, including the numerical-stability constant, into a normalized mantissa and a signed exponent. A leading-one detector locates the most significant nonzero bit, the mantissa is shifted into a fixed interval, and a small lookup table approximates its inverse square root. The exponent is decomposed into an integer shift and a parity term. Dynamic-range recovery is then completed using a bidirectional shift and, when required, multiplication by a fixed correction constant. The complete low-complexity procedure is summarized in Algorithm 2.A token-level overlapped streaming architecture is further designed to decouple statistical computation from vector scaling. The input and output are 128-bit streams carrying 16 two's-complement INT8 elements per cycle and use valid-ready-last handshaking. Incoming elements are simultaneously written into one of three rotating token buffers and sent to 16 parallel selective-compression lanes. Their approximate squares are reduced by an adder tree and accumulated in a 32-bit register. The inverse-root unit produces a 16-bit Q2.14 factor, which is multiplied by the buffered signed inputs to form 24-bit Q14 intermediate results; rounding and saturation then produce INT8 outputs (Fig. 3 ). Each buffer stores one 2048-element token as 32 x 128-bit words. A bank-index queue and a scalar-factor FIFO maintain the correspondence between the buffered tokens and their statistical results, while one statistics unit, one inverse-root unit, and one scaling unit are time-multiplexed across tokens. Consequently, token writing, statistical reduction, inverse-root generation, and readback scaling are overlapped across consecutive tokens (Table 1 ). Algorithm-level evaluation covers WikiText perplexity and the accuracies on HellaSwag, PIQA, BoolQ, and ARC-Easy under FP32, INT8, SwiGLU-only approximation, RMSNorm-only approximation, and joint approximation. Hardware evaluation is conducted using Vivado2022.2 for a Xilinx Artix-7 XC7A200T-1FFV1156 FPGA at 100 MHz. Complete baseline and optimized operators are compared under matched interfaces, data widths, and implementation constraints without using vendor arithmetic IP cores.Results and Discussions The INT8 baseline achieves a WikiText perplexity of 7.236 and a mean accuracy of 0.573 across the four classification tasks, closely matching the FP32 values of 7.199 and 0.576. Replacing only RMSNorm yields a perplexity of 7.337 and a mean accuracy of 0.584; the HellaSwag, PIQA, BoolQ, and ARC-Easy accuracies are 0.576, 0.720, 0.600, and 0.440, respectively. These results indicate that the proposed low-precision statistics and inverse-square-root approximation do not cause systematic degradation across the evaluated task set. Replacing only the SiLU path produces a perplexity of 7.852 and a mean accuracy of 0.549. When both approximations are enabled, the perplexity increases to 9.097 and the mean accuracy decreases to 0.524. The PIQA accuracy decreases from 0.714 for the INT8 baseline to 0.639, while the ARC-Easy accuracy decreases from 0.409 to 0.304, corresponding to losses of 7.5 and 10.5 percentage points, respectively ( Table 2 ). This contrast indicates that RMSNorm is more tolerant of the proposed approximation than the SiLU gate activation. The additional degradation observed under joint approximation also suggests that approximation errors may propagate between the two operators: perturbations introduced by RMSNorm may alter the input distribution of the gate, after which SiLU approximation and multiplicative gating may amplify the accumulated error. Accordingly, RMSNorm-only replacement is preferable for accuracy-sensitive workloads, whereas joint replacement may be considered when reductions in logic utilization and power are assigned higher priority.The hardware results confirm that the two operators benefit from different optimization mechanisms. For the complete SwiGLU operator, LUT utilization decreases from 27,590 to 17,063 and DSP utilization decreases from 145 to 91, corresponding to reductions of 38.2% and 37.2%, respectively. FF utilization changes only from 1,323 to 1,310, and BRAM usage remains unchanged at nine tiles. The estimated total power decreases from 1.083 W to 0.572 W, while the estimated dynamic power decreases from 0.997 W to 0.487 W, corresponding to reductions of 47.2% and 51.2%, respectively. These gains arise from replacing the exponential, high-order polynomial, and division path with interval comparisons and shift-add arithmetic while preserving the final gate-by-up multiplication. Under no-backpressure RTL simulation, the baseline and optimized SwiGLU implementations achieve the same cycle-level throughput, indicating that the reductions in resource utilization and estimated power do not introduce a throughput penalty under the evaluated conditions.For RMSNorm, LUT utilization decreases from 5,660 to 1,976 and FF utilization decreases from 4,917 to 938, corresponding to reductions of 65.1% and 80.9%, respectively. The estimated total power decreases from 0.269 W to 0.158 W, and the estimated dynamic power decreases from 0.138 W to 0.027 W, corresponding to reductions of 41.3% and 80.4%, respectively. The cost of overlapping is explicit: DSP utilization increases slightly from 16 to 17, and BRAM usage rises from two to six tiles because the three rotating buffers are required to hold tokens in flight. Under the no-backpressure RTL simulation used in this study, the optimized design overlaps reduction, inverse-root generation, and scaling across different tokens, thereby improving token-level throughput relative to the serial baseline. The resulting trade-off exchanges additional on-chip storage and one DSP for substantial reductions in logic utilization and dynamic power (Table 3 ). Overall, the results demonstrate that activation approximation should primarily simplify nonlinear arithmetic, whereas normalization optimization should jointly restructure arithmetic, buffering, and scheduling.Conclusions Operator-specific software-hardware co-optimization provides an effective approach to reducing the cost of nonlinear operators in edge inference of large models. The proposed DASA method concentrates approximation capacity in statistically important regions and constrains each local slope to a directly implementable combination of two power-of-two terms. Its two-stage interval-decision hardware substantially reduces the resource utilization and estimated power of the complete SwiGLU operator without reducing cycle-level throughput under the evaluated conditions. The proposed RMSNorm design combines selective compression, mantissa-based lookup-table approximation of the inverse square root, exponent compensation, and three-bank token buffering to decouple vector statistics from scaling. It achieves substantial reductions in logic utilization and dynamic power and improves token-level throughput, at the cost of additional BRAM and one DSP. Model-level results further show that numerical robustness is operator dependent: RMSNorm approximation can be deployed alone when task quality is prioritized, whereas joint approximation provides a more aggressive option for resource-constrained scenarios. These findings establish a practical design principle for edge accelerators: nonlinear operators should not be optimized using a uniform approximation strategy; instead, approximation error, complete-operator functionality, streaming dependencies, and task-level error propagation should be considered together. Future work will investigate runtime-selectable accuracy-resource modes and coordinated optimization of multiple nonlinear operators so that the accelerator can adapt to different models and workload requirements. -
Key words:
- nonlinear operator acceleration /
- SwiGLU /
- SiLU /
- RMSNorm /
- edge deployment /
- algorithm-hardware co-design
-
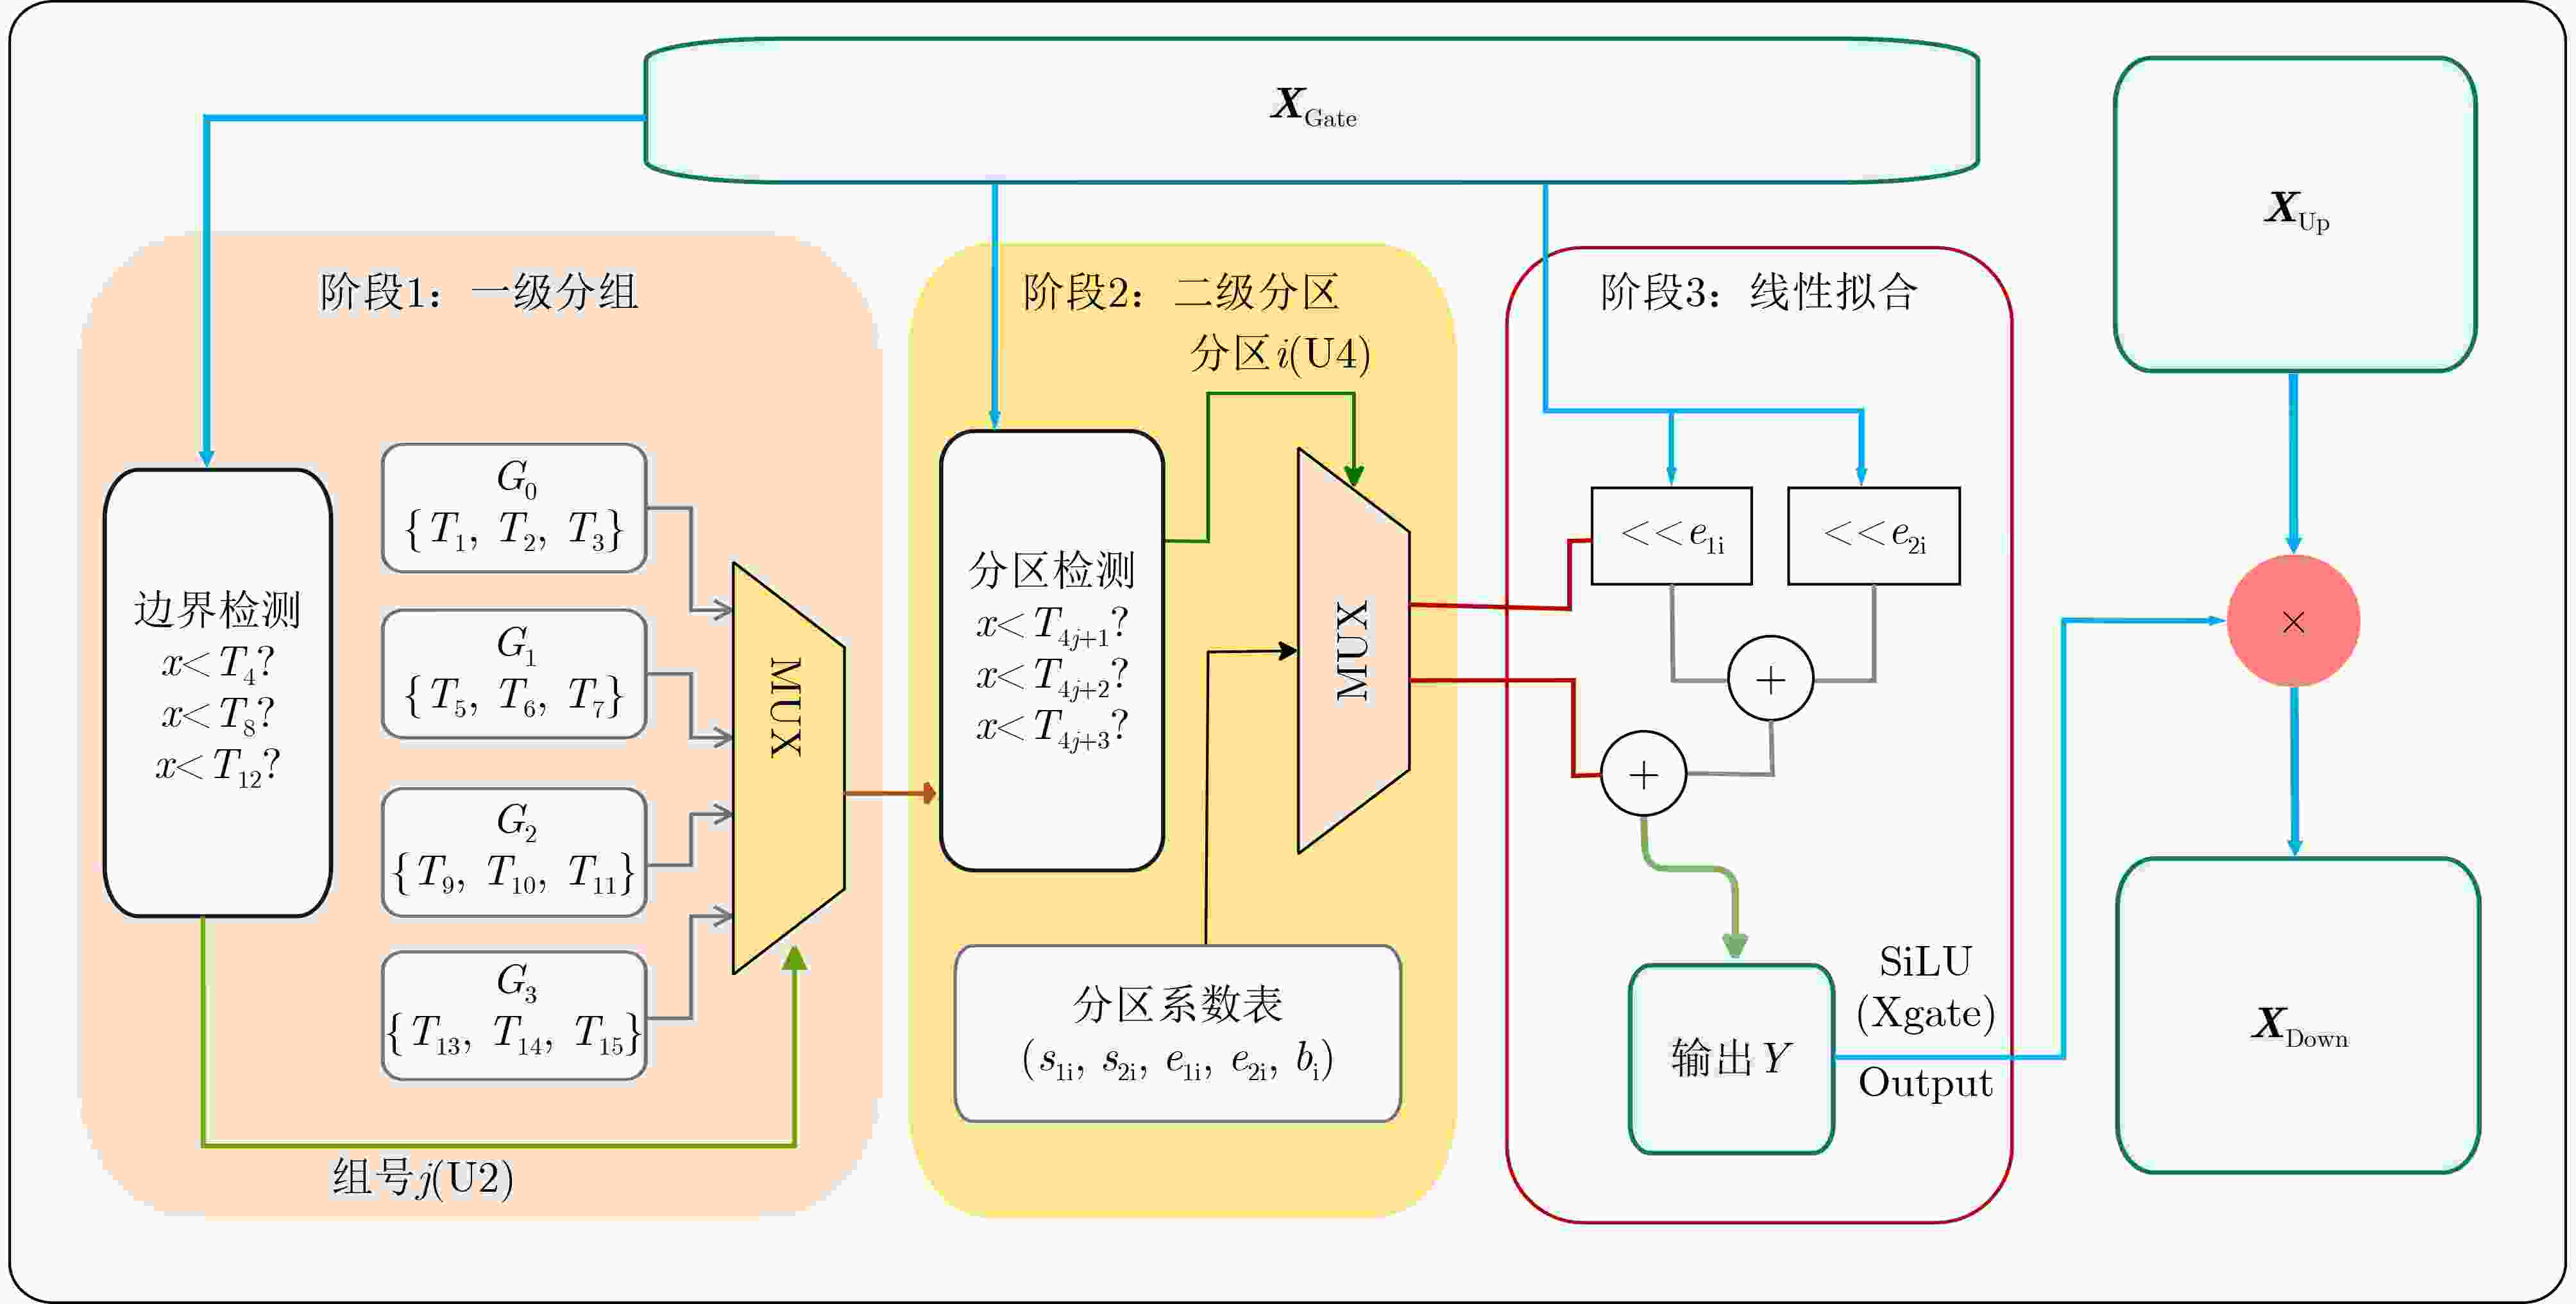
图 2 包含两级区间判定SiLU近似的SwiGLU硬件架构(以N=16为例)。
注:Tk(k=1,…,15)为按升序排列的分段阈值;Gj(j=0,…,3)为第j个组内阈值集合精度为S-INT8;j和i分别表示一级组号和最终分区号,采用U2和U4格式。输入输出则都为S-INT8。S/U分别表示有符号/无符号整数。
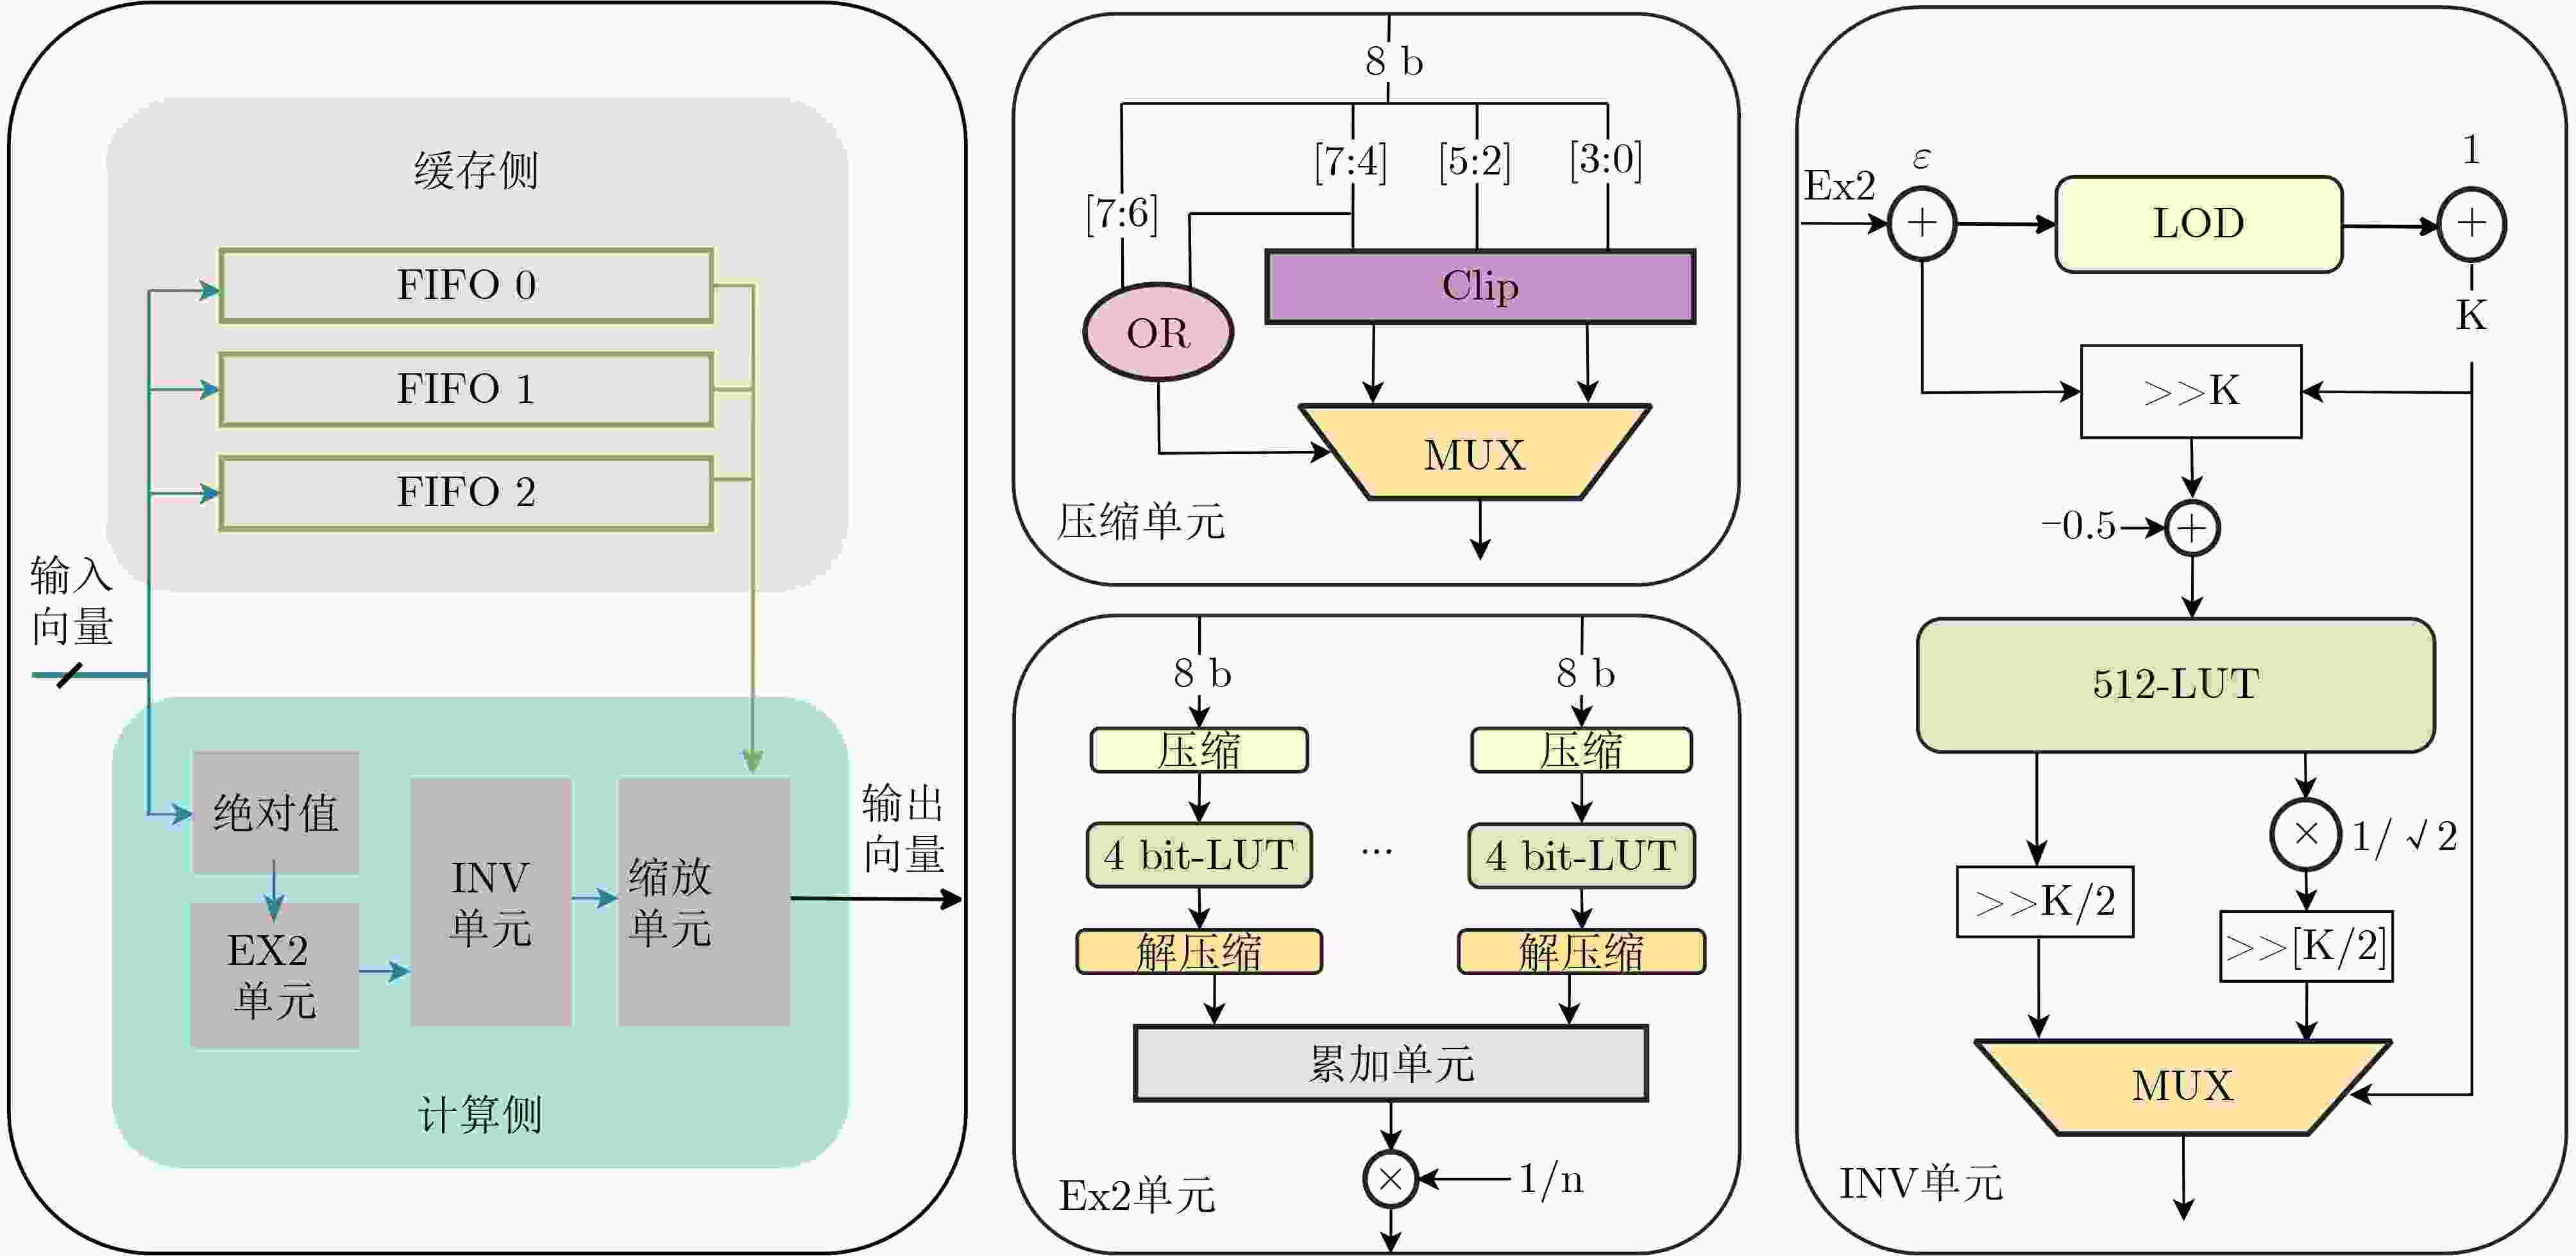
图 3 RMSNorm的流式硬件架构
注:输入、输出均为128 bit数据流,每拍包含16个补码S-INT8数据,并采用valid-ready-last握手。平方统计结果为32 bit, inv_rms采用16 bit Q2.14格式;3个轮转FIFO的单Bank深度均为32×128 bit。
1 $ \text{SwiGLU(g)=(SiLU(X*}{\text{W}}_{\text{g}})\odot\text{(X*}{\text{W}}_{\text{u}})){\text{W}}_{\text{o}} $
输入:量化预输入激活$ \mathrm{X }=\left\{{\mathrm{x}}_{\mathrm{t}}\right\} $,分区数N,截断区间
[$ {\mathrm{x}}_{\min },{\mathrm{x}}_{\max } $],幂指数范围[${\mathrm{e}}_{\min},{\mathrm{e}}_{\max}$],$ {\mathrm{W}}_{\text{gate}} $, $ {\mathrm{W}}_{\text{up}} $, $ {\mathrm{W}}_{\text{down}} $输出:分区集合$ {\{\tau }_{\mathrm{i}}\} $,分区近似参数集合$ \{{\hat{\mathrm{a}}_{\mathrm{i}}},{\hat{\mathrm{b}}_{\mathrm{i}}}\} $, Y 阶段1: 1: $ {\text{x}}_{\text{clip}}\leftarrow\text{Clip(}{\text{x}}_{\min },{\text{x}}_{\max }\text{,X)} $ 2: $ \hat{\text{F}}({\mathrm{x}})\leftarrow\text{EmpiricalCDF(}{\text{x}}_{\text{clip}}) $ 3: $ {{\mathrm{for}}\; {\mathrm{i}}\leftarrow 0 \;{\mathrm{to}}\; {\mathrm{N}}\; {\mathrm{do}}} $ 4: $ {\text{I}}_{\text{i}},[{\tau}_{\text{i}},{\tau}_{\text{i+1}})\leftarrow\hat{\text{F}}\text{(x)} $ 5: end for 阶段2: 6: $ {\text{S}}_{\text{DASA}}\leftarrow \varnothing $ 7: $ \text{for}\;{\text{e}}_{1},{\text{e}}_{2}\leftarrow {\text{e}}_{\min }\;\text{to}\;{\text{e}}_{\max }\;\text{do} $ 8: $ \text{for}\;{\text{s}}_{1},{\text{s}}_{2}\in{{-1,0,1} \;{\mathrm{do}}} $ 9: $ {{{\mathrm{a}}\leftarrow{\mathrm{s}}}}_{1}{2}^{{{\text{e}}_{1}}}+{\text{s}}_{2}{2}^{{{\text{e}}_{2}}} $ 10: $ {\text{S}}_{\text{DASA}}\leftarrow {\text{S}}_{\text{DASA}}\cup\text{{a}} $ 11: end for 12: end for 13: $ {{\mathrm{for}}\; {\mathrm{i}}\leftarrow 0 \;{\mathrm{to}}\; {\mathrm{N}}\; {\mathrm{do}}} $ 14: $ {\text{I}}_{\text{i}},{\xi}_{\text{i}}\leftarrow[{\tau}_{\text{i}},{\tau}_{\text{i+1}}) $ 15: $ {\text{N}}_{\text{i}}\leftarrow\text{KNearest(}{\text{x}}_{\text{clip}}\cap{\text{I}}_{\text{i}},{\xi}_{\text{i}}) $ 16: $ \text{for each a }\in{\text{S}}_{\text{DASA}}\;\text{do} $ 17: $ {{{\mathrm{b}} \leftarrow {\mathrm{f}}(}{{\xi}_{\text{i}}}{) - {\mathrm{a}}\cdot\xi}}_{\text{i}} $ 18: $ {{\mathrm{E}}({\mathrm{a}})\leftarrow \displaystyle\sum {\mathrm{[f(x)}}-({\mathrm{a}}\cdot{\mathrm{x+b}})}{]}^{2} $ 19: $ {{{\mathrm{if E(a}}) <{\mathrm{E}}}}_{\text{i}}\;\text{then} $ 20: $ {\text{E}}_{\text{i}},\hat{{\text{a}}_{\text{i}}},\hat{{\text{b}}_{\text{i}}}\leftarrow\text{E(a),a,b} $ 21: end if 22: end for 23: end for 阶段3: 24: $ \text{g}\leftarrow{\text{W}}_{\text{gate}}\text{X, u}\leftarrow{\text{W}}_{\text{up}}\text{X} $ 25: $ {{\mathrm{h}}}\leftarrow({\hat{\text{a}}_{\text{i}}}\text{g}+\hat{{\text{b}}_{\text{i}}}) \odot $u 26: $ \text{Y}\leftarrow{\text{W}}_{\text{down}}\text{h} $ 27: Return Y  下载: 导出CSV
2 RMSNorm(x)
输入:输入激活向量X,稳定项$ \mathrm{\epsilon } $,仿射权重$ \gamma $ 输出:归一化输出激活值Y 阶段1: 1: $ \text{for i}\leftarrow {\text{0 to C do}} $ 2: $ {\text{A}}_{\text{i}}\leftarrow \text{UnsignedAbs(}{\text{X}}_{\text{i}}) $ 3: $ {\text{X}}_{\text{ci}},{\text{S}}_{\text{i}}\leftarrow \text{SC(}{\text{A}}_{\text{i}}) $ 4: $ {\text{S}}_{\text{qi}}\leftarrow ({\text{X}}_{\text{ci}}\cdot{\text{X}}_{\text{ci}})<<(2{\text{S}}_{\text{i}}) $ 5: $ {\text{Ex}}^{2}\leftarrow {\text{Ex}}^{2}+{\text{S}}_{\text{qi}} $ 6: $ \text{end for} $ $ \text{阶段2} $: 7: $ {\text{Ex}}^{2}\leftarrow {\text{Ex}}^{2}{\text{Ex}}^{2}\cdot\text{1/C} $ 8: $ \text{u} \leftarrow {\text{Ex}}^{2}{+ \epsilon } $ 9: $ {\text{p}} \leftarrow {\mathrm{LOD(u); k }}\leftarrow {\mathrm{p}}-{\mathrm{F}}+1; {\mathrm{m}} \leftarrow {\mathrm{u}}\cdot 2^\wedge (-{\mathrm{k}})$
$\triangleright{\mathrm{u}}={\mathrm{m}}\cdot{2}^{\text{k}}{,{\mathrm{m}}\in[0.5,1)} $10: $ \text{idx} \leftarrow {\text{Map(m)}} $ 11: $ {\text{y}}_{0}\leftarrow \text{LUT(idx)} \quad \triangleright {\text{y}}_{0}\approx \text{1/sqrt(m)} $ 12: $ {\mathrm{t}} \leftarrow \text{floor(k/2),r} \leftarrow {\mathrm{k}} - {\mathrm{2t}} $ 13: $ \text{inv}\_\text{rms} \leftarrow {\text{y}}_{0}\cdot{2}^{\text{(-t)}}\cdot\text{(1/sqrt(2)}{)}^{\text{r}} $ $ \text{阶段3} $: 14: $ {\text{for i}} \leftarrow \text{0 to C do Stage2} $ 15: $ {\text{Y}}_{\text{i}}\leftarrow {\text{X}}_{\text{i}}\text{· inv}\_\text{rms} $ 16: $ {\mathrm{if}}\; \gamma \text{is used then} $ 17: $ {\text{Y}}_{\text{i}}\leftarrow {\gamma}_{\text{i}}\cdot{\text{Y}}_{\text{i}} $ 18: $ \text{end if} $ 19: end for 20: return Y
下载: 导出CSV
表 1 RMSNorm硬件流水调度示意
T0 T1 T2 T3 T4 T5 T6 T7 FIFO 0 W(A) R(A) W(D) R(D) ··· FIFO 1 W(B) R(B) W(E) R(E) ··· FIFO 2 W(C) R(C) W(F) R(F) E(x2) A B C D E F G H INV A B C D E F G Scale A B C D E F 注:A、B、…表示连续输入的不同token;Ti表示流水调度时刻;W/R分别表示token在FIFO中的写入与回读;E(x2)、INV和Scale分别表示平方统计、倒数平方根生成和逐元素缩放三个阶段。
下载: 导出CSV
表 2 TinyLlama-1.1B 在不同算子部署设置下的算法级评估结果。
Run precision Wikitext
(ppl)Hellaswag
(acc)PIQA
(acc)BoolQ
(acc)ARC-Easy
(acc)Stability
meanStability
stdfp32 fp32 7.199 0.570 0.719 0.600 0.418 0.576 0.107 int8 int8 7.236 0.568 0.714 0.604 0.409 0.573 0.109 int8+swiglu int8 7.852 0.550 0.675 0.616 0.356 0.549 0.120 int8+rmsnorm int8 7.337 0.576 0.720 0.600 0.440 0.584 0.099 int8+hw int8 9.097 0.544 0.639 0.610 0.304 0.524 0.131 注:PPL(困惑度)是衡量语言模型对文本预测能力的指标,数值越低,说明模型对文本的预测越准确。ACC(准确率)是模型预测结果中正确样本占总样本的比例,数值越高代表模型的预测正确率越高。
下载: 导出CSV
表 3 完整SwiGLU与RMSNorm算子在基线实现和优化实现下的硬件开销与功耗对比
算子 实现 LUT FF DSP BRAM 总功耗(W) 动态功耗(W) SwiGLU base 27590 1323 145 9 1.083 0.997 opt 17063 1310 91 9 0.572 0.487 Δ –38.2% –0.98% –37.2% - –47.2% –51.2% RMSNorm base 5660 4917 16 2 0.269 0.138 opt 1976 938 17 6 0.158 0.027 Δ –65.1% –80.9% +6.3% +4 –41.3% –80.4%
下载: 导出CSV
-
[1] VASWANI A, SHAZEER N, PARMAR N, et al. Attention is all you need[C]. Proceedings of the 31st International Conference on Neural Information Processing Systems, Long Beach, USA, 2017: 6000–6010. [2] PENG Tianfan, XIA Tianhua, QIN Jiajun, et al. HAAN: A holistic approach for accelerating normalization operations in large language models[C]. 2025 Design, Automation & Test in Europe Conference (DATE), Lyon, France, 2025: 1–7. doi: 10.23919/DATE64628.2025.10993005. [3] ZHANG Jiawen, CHEN Kejia, HE Lipeng, et al. Activation approximations can incur safety vulnerabilities even in aligned LLMs: Comprehensive analysis and defense[C]. Proceedings of the 34th USENIX Conference on Security Symposium, Seattle, USA, 2025: 18. [4] WANG Wenxun, ZHOU Shuchang, SUN Wenyu, et al. SOLE: Hardware-software co-design of Softmax and LayerNorm for efficient transformer inference[C]. 2023 IEEE/ACM International Conference on Computer Aided Design (ICCAD), San Francisco, USA, 2023: 1–9. doi: 10.1109/ICCAD57390.2023.10323725. [5] KIM R, LEE D, KIM J, et al. Hardware accelerator for approximation-based Softmax and layer normalization in transformers[J]. Electronics, 2025, 14(12): 2337. doi: 10.3390/electronics14122337. [6] 刘海莹, 乔瑞秀, 陈刚, 等. 一种高效的Softmax函数计算方法及硬件电路[J]. 微电子学与计算机, 2024, 41(2): 91–100. doi: 10.19304/J.ISSN1000-7180.2023.0141.LIU Haiying, QIAO Ruixiu, CHEN Gang, et al. An efficient calculation method and implementation of Softmax function[J]. Microelectronics & Computer, 2024, 41(2): 91–100. doi: 10.19304/J.ISSN1000-7180.2023.0141. [7] GERBER I. Attention is not all you need: The importance of feedforward networks in transformer models[EB/OL]. https://arxiv.org/abs/2505.06633, 2025. [8] KOCA N A, DO A T, and CHANG C H. Accuracy-preserving layer normalization approximations for efficient transformer hardware accelerators[C]. IEEE International Symposium on Circuits and Systems (ISCAS), London, United Kingdom, 2025: 1–5. doi: 10.1109/ISCAS56072.2025.11044257. [9] FINI E, SHUKOR M, LI Xiujun, et al. Multimodal autoregressive pre-training of large vision encoders[C]. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, USA, 2025: 9641–9654. doi: 10.1109/CVPR52734.2025.00901. [10] TANASE A V and PELICAN E. Supernova: Achieving more with less in transformer architectures[EB/OL]. https://arxiv.org/abs/2507.15773, 2025. [11] GRAEF N, CLAPP M, and WASIELEWSKI A. Flash normalization: Fast RMSNorm for LLMs[EB/OL]. https://arxiv.org/abs/2407.09577v1, 2024. [12] PARK J, SHIN G, and YOO H. Implementation of Activation Functions using various approximation methods[C]. 2024 21st International SoC Design Conference (ISOCC), Sapporo, Japan, 2024: 175–176. doi: 10.1109/ISOCC62682.2024.10762658. [13] BASTERRETXEA K, TARELA J M, and DEL CAMPO I. Approximation of sigmoid function and the derivative for hardware implementation of artificial neurons[J]. IEE Proceedings - Circuits, Devices and Systems, 2004, 151(1): 18–24. doi: 10.1049/ip-cds:20030607. [14] XIE Yusheng, RAJ A N J, HU Zhendong, et al. A twofold lookup table architecture for efficient approximation of activation functions[J]. IEEE Transactions on Very Large Scale Integration (VLSI) Systems, 2020, 28(12): 2540–2550. doi: 10.1109/TVLSI.2020.3015391. [15] HUANG Jianxin, WU Yuling, ZHUANG Mingyong, et al. High-precision and efficiency hardware implementation for GELU via its internal symmetry[J]. Electronics, 2025, 14(9): 1825. doi: 10.3390/electronics14091825. [16] SERHIIENKO P, SERGIYENKO A, TELENYK S, et al. Calculation of the sigmoid activation function in FPGA using rational fractions[C]. 24th International Conference on Computational Science (ICCS 2024), Malaga, Spain, 2024: 146–157. doi: 10.1007/978-3-031-63778-0_11. [17] XIANG Maoyang and WANG Bo. DAPA: Distribution aware piecewise activation functions for on-device transformer inference and training[C]. Proceedings of the 63rd ACM/IEEE Design Automation Conference, Long Beach, USA, 2026: 236. doi: 10.1145/3770743.3804274. [18] KARP A H and MARKSTEIN P. High-precision division and square root[J]. ACM Transactions on Mathematical Software, 1997, 23(4): 561–589. doi: 10.1145/279232.279237. [19] SAHA S and XU Lanyu. Vision transformers on the edge: A comprehensive survey of model compression and acceleration strategies[J]. Neurocomputing, 2025, 643: 130417. doi: 10.1016/j.neucom.2025.130417. [20] KANG Yiwen and WANG Dong. Hardware-oriented approximations of Softmax and RMSNorm for efficient Transformer inference[J]. Micromachines, 2026, 17(1): 84. doi: 10.3390/mi17010084. [21] 李天阳, 张帆, 王松, 等. 基于FPGA的卷积神经网络和视觉Transformer通用加速器[J]. 电子与信息学报, 2024, 46(6): 2663–2672. doi: 10.11999/JEIT230713.LI Tianyang, ZHANG Fan, WANG Song, et al. FPGA-based unified accelerator for convolutional neural network and vision transformer[J]. Journal of Electronics & Information Technology, 2024, 46(6): 2663–2672. doi: 10.11999/JEIT230713. [22] 贺煜凯, 谢童欣, 朱振华, 等. 面向商用存算一体架构矩阵乘算子协同优化策略研究[J]. 电子与信息学报, 2025, 47(9): 3187–3197. doi: 10.11999/JEIT250364.HE Yukai, XIE Tongxin, ZHU Zhenhua, et al. Collaborative optimization strategies for matrix multiplication-accumulation operators on commercial processing-in-memory architectures[J]. Journal of Electronics & Information Technology, 2025, 47(9): 3187–3197. doi: 10.11999/JEIT250364. -

 下载:

计量
- 文章访问数: 13
- HTML全文浏览量: 2
- PDF下载量: 0
- 被引次数: 0
