



Research on AI-Enabled Real-Time Audio Joint Source-Channel Coding
-
摘要: 目前,第3代合作伙伴计划(3rd Generation Partnership Project, 3GPP)的业务与系统技术规范组第4工作组(TSG SA working group 4, SA4) 已经开始研究基于人工智能(Artificial Intelligence, AI)的语音编解码器。该文首次以3GPP地球静止轨道(Geostationary Earth Orbit, GEO)语音典型的物理层参数配置与目前SA4正在研究的Descript音频编解码器(Descript Audio Codec, DAC)作为评估基线,保证了基线结果的公平性,并首次提出了总功率限制的DAC信源信道调制联合优化方案、恒模限制的DAC信源信道调制联合优化方案和DAC信源信道联合编解码方案。在语音质量可接受的前提下,所提方案相比于基线方案有2.5~4 dB的覆盖增益。以期为GEO语音的后续研究提供有益思路。
-
关键词:
- GEO语音 /
- 信源信道联合编码 /
- 联合信源信道编码调制 /
- AI
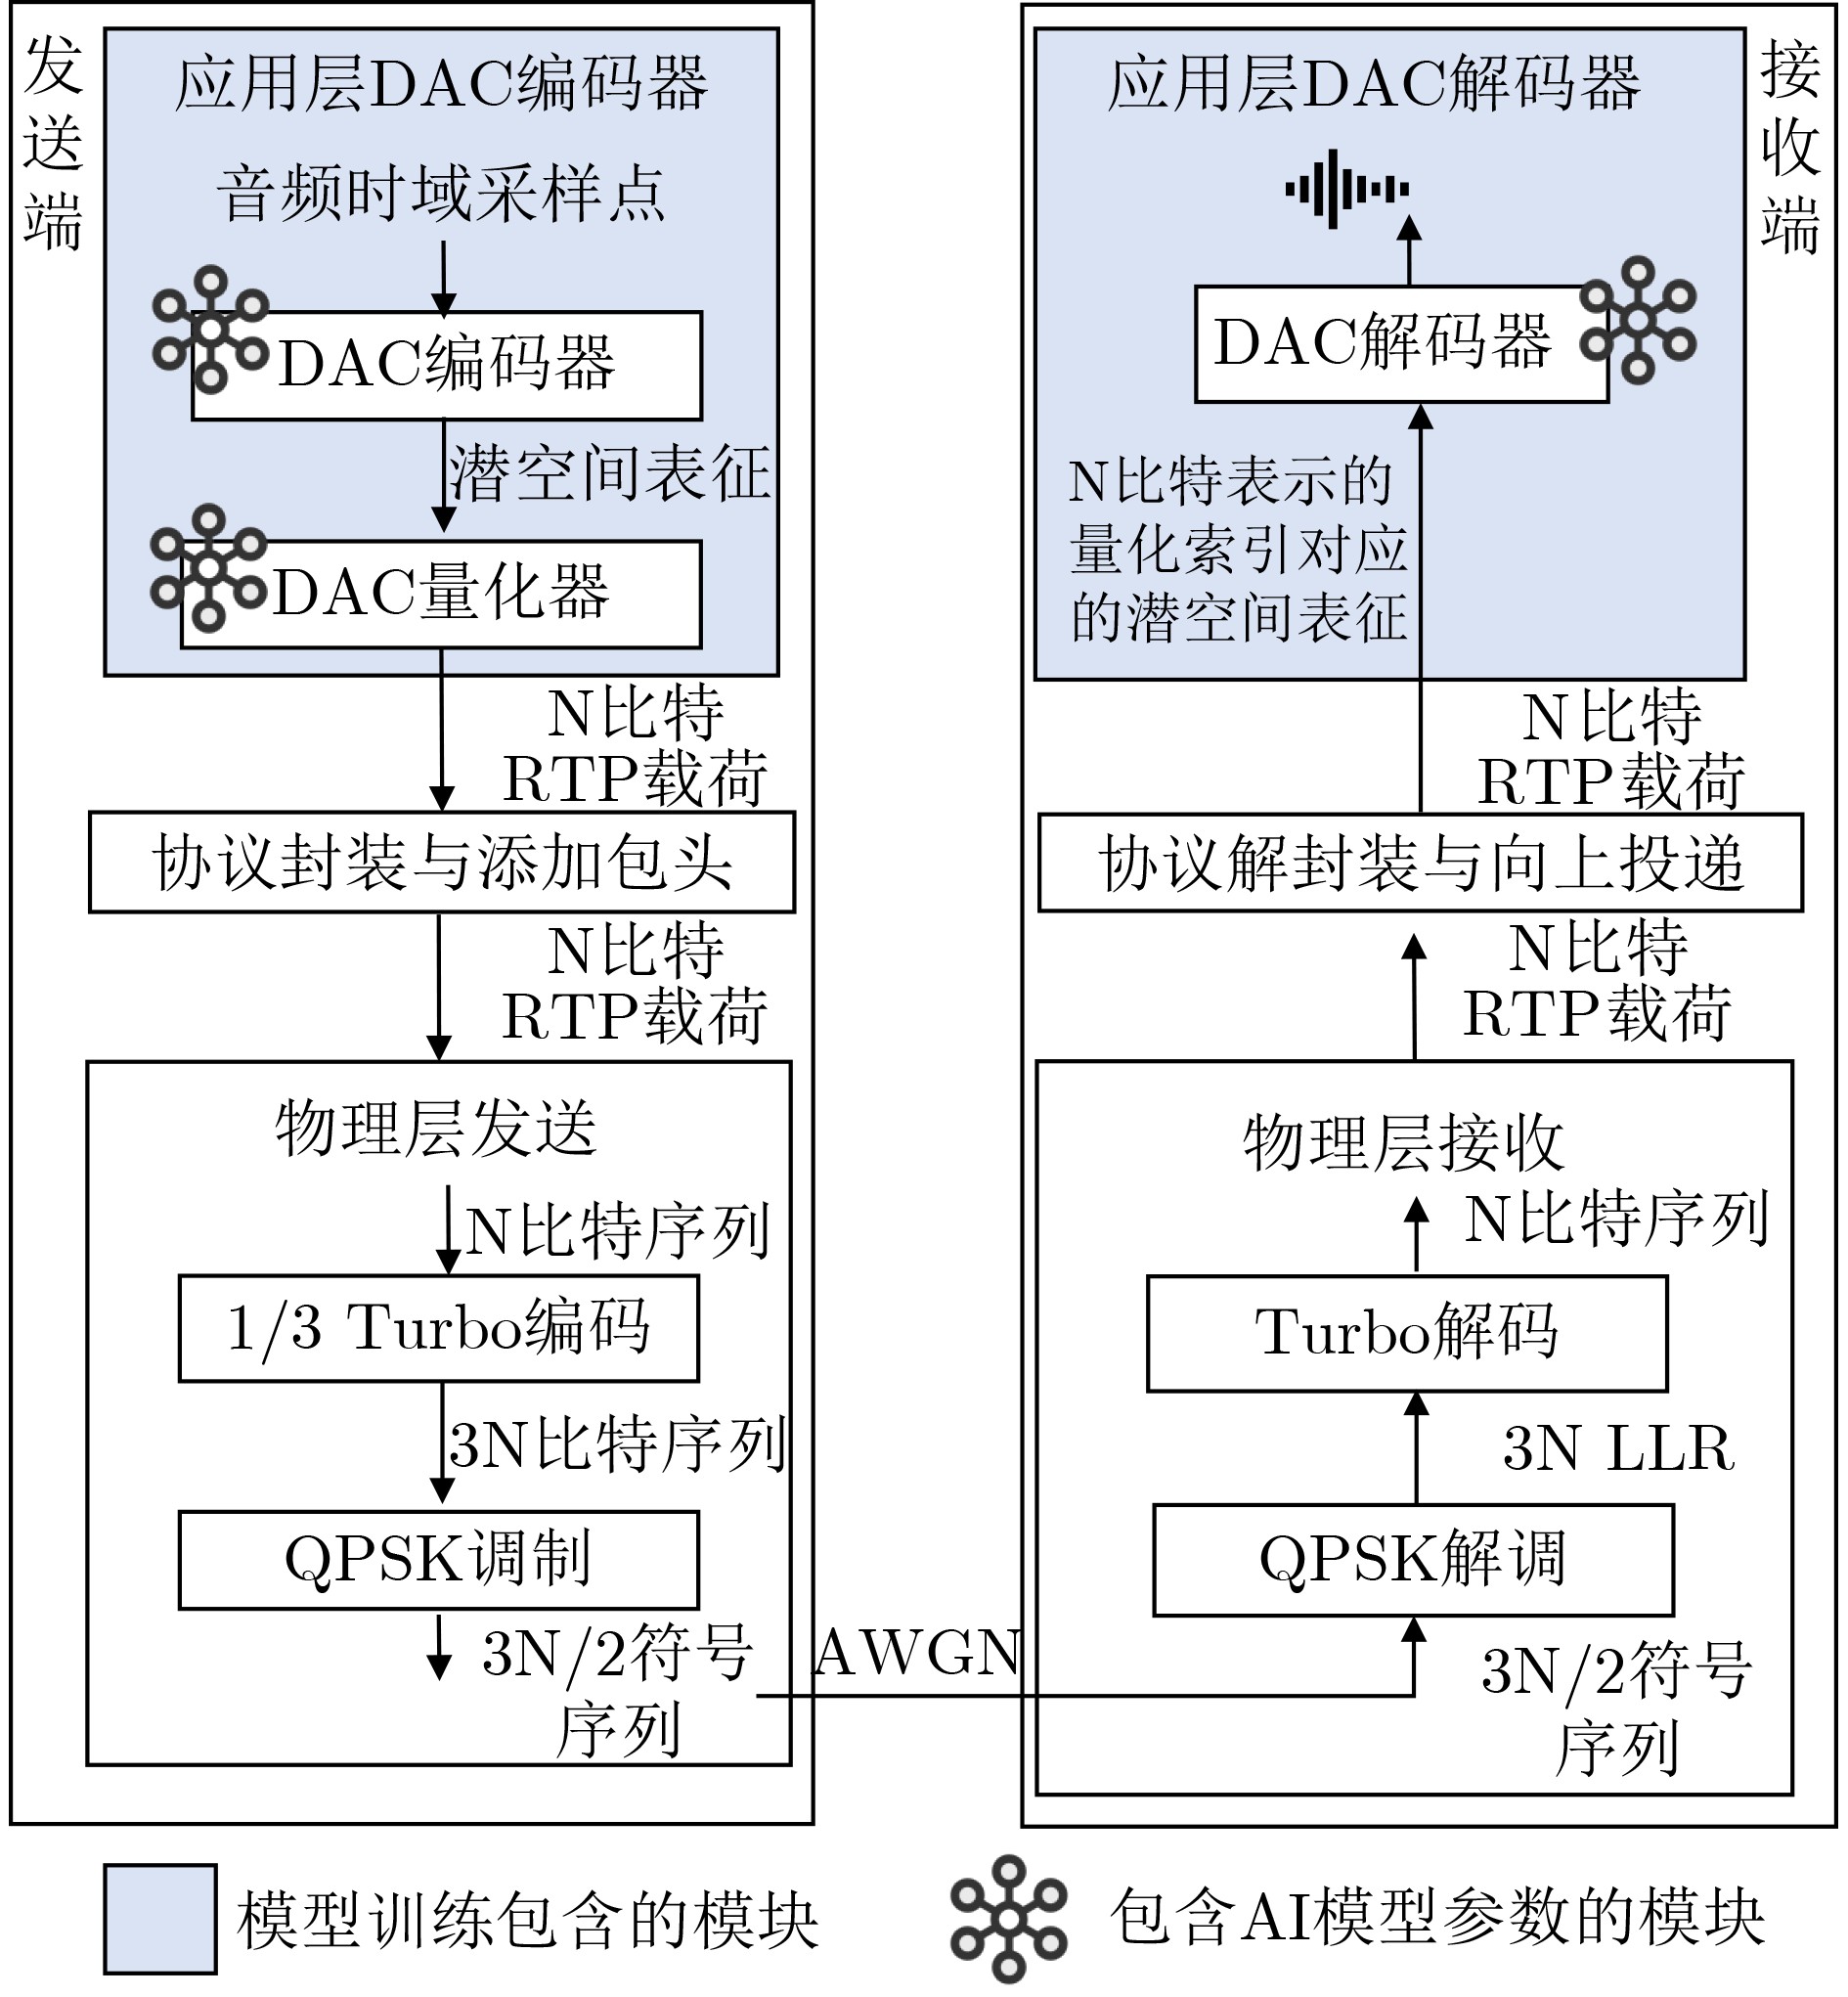
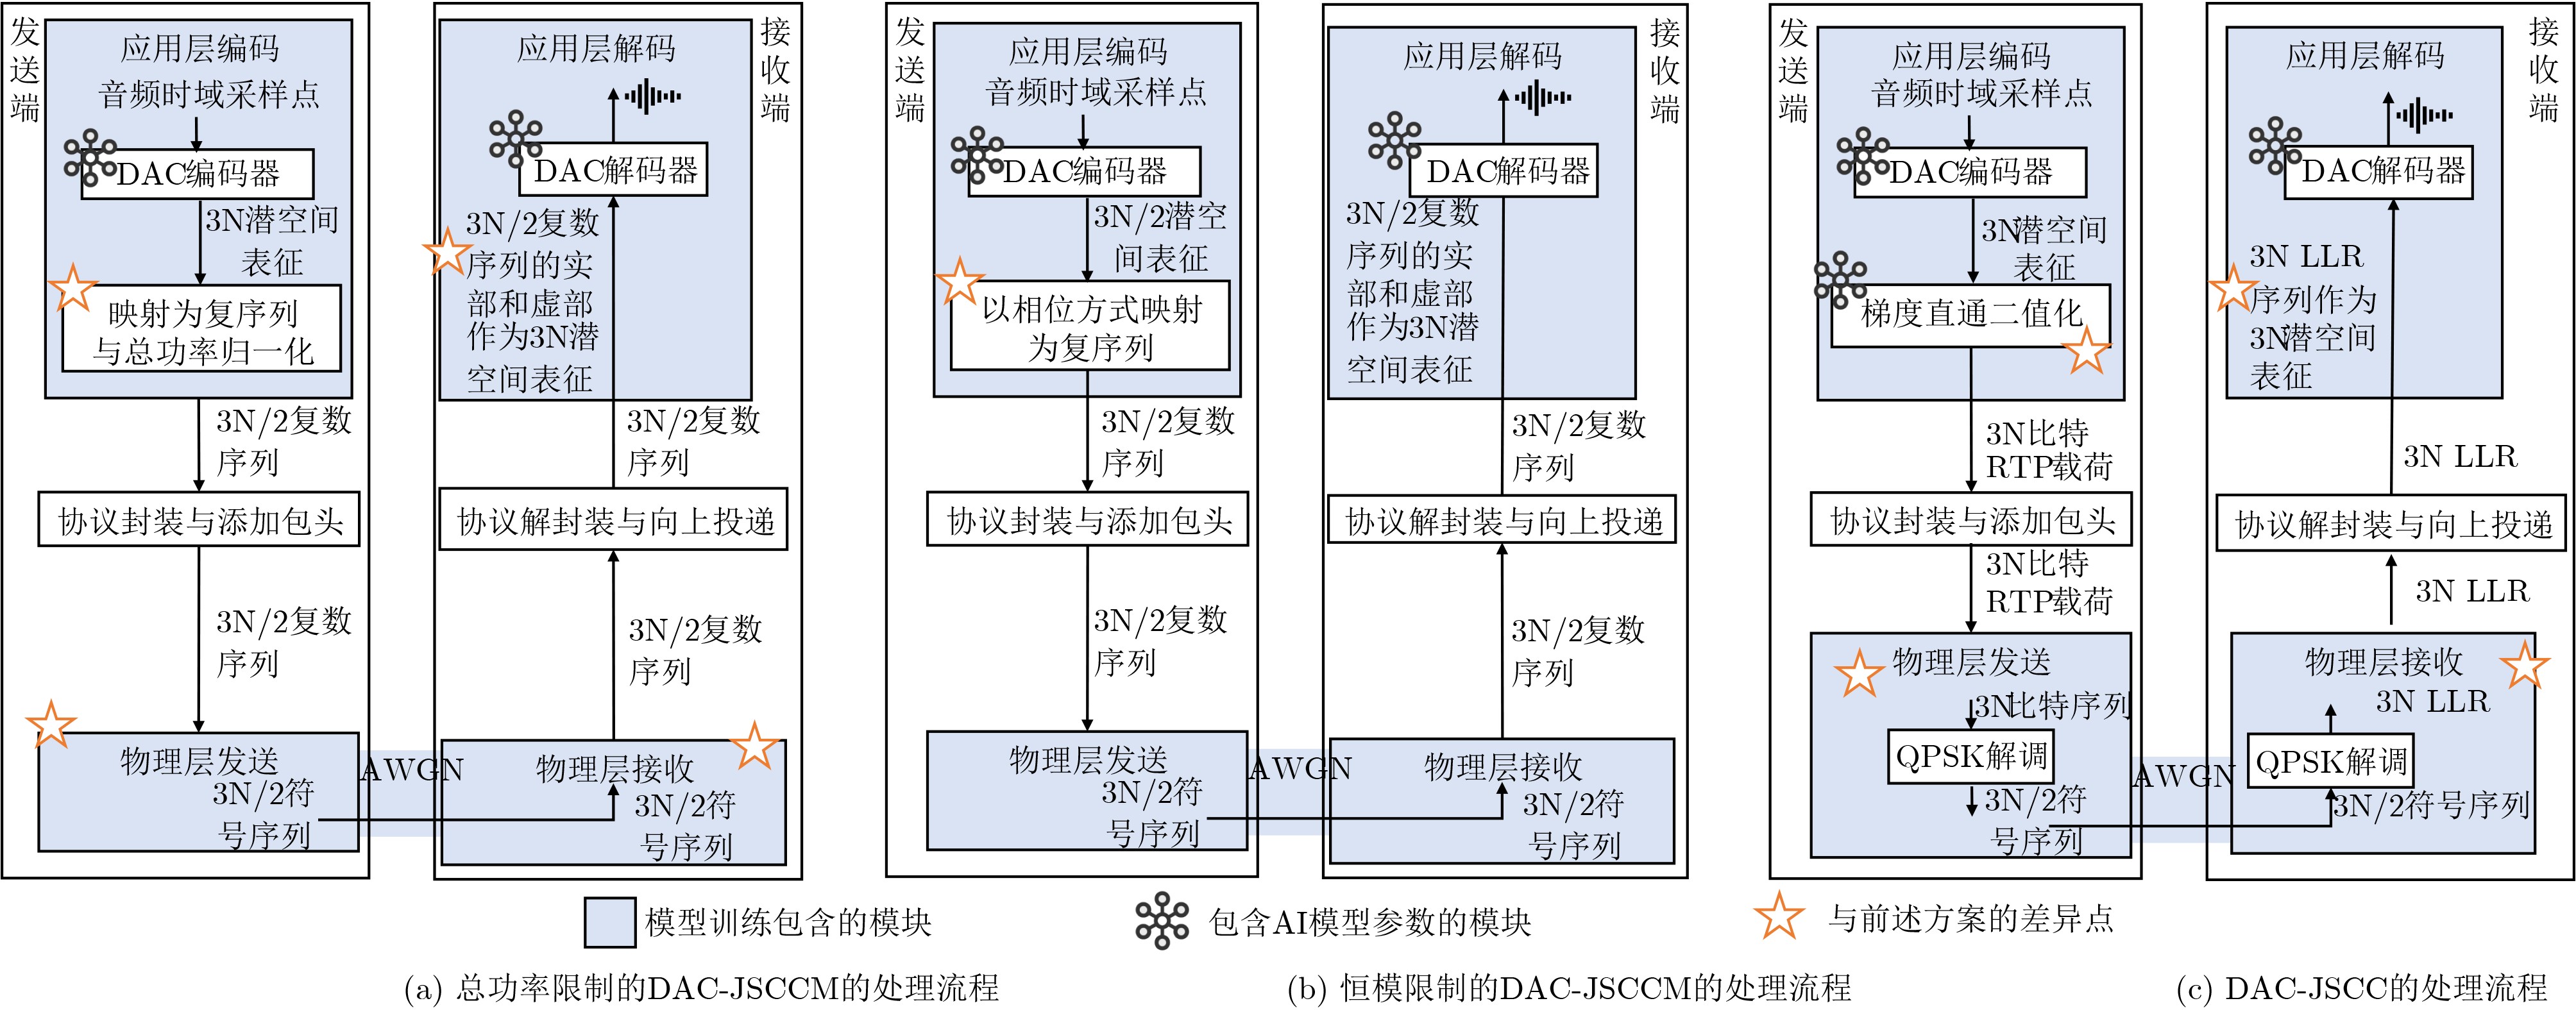
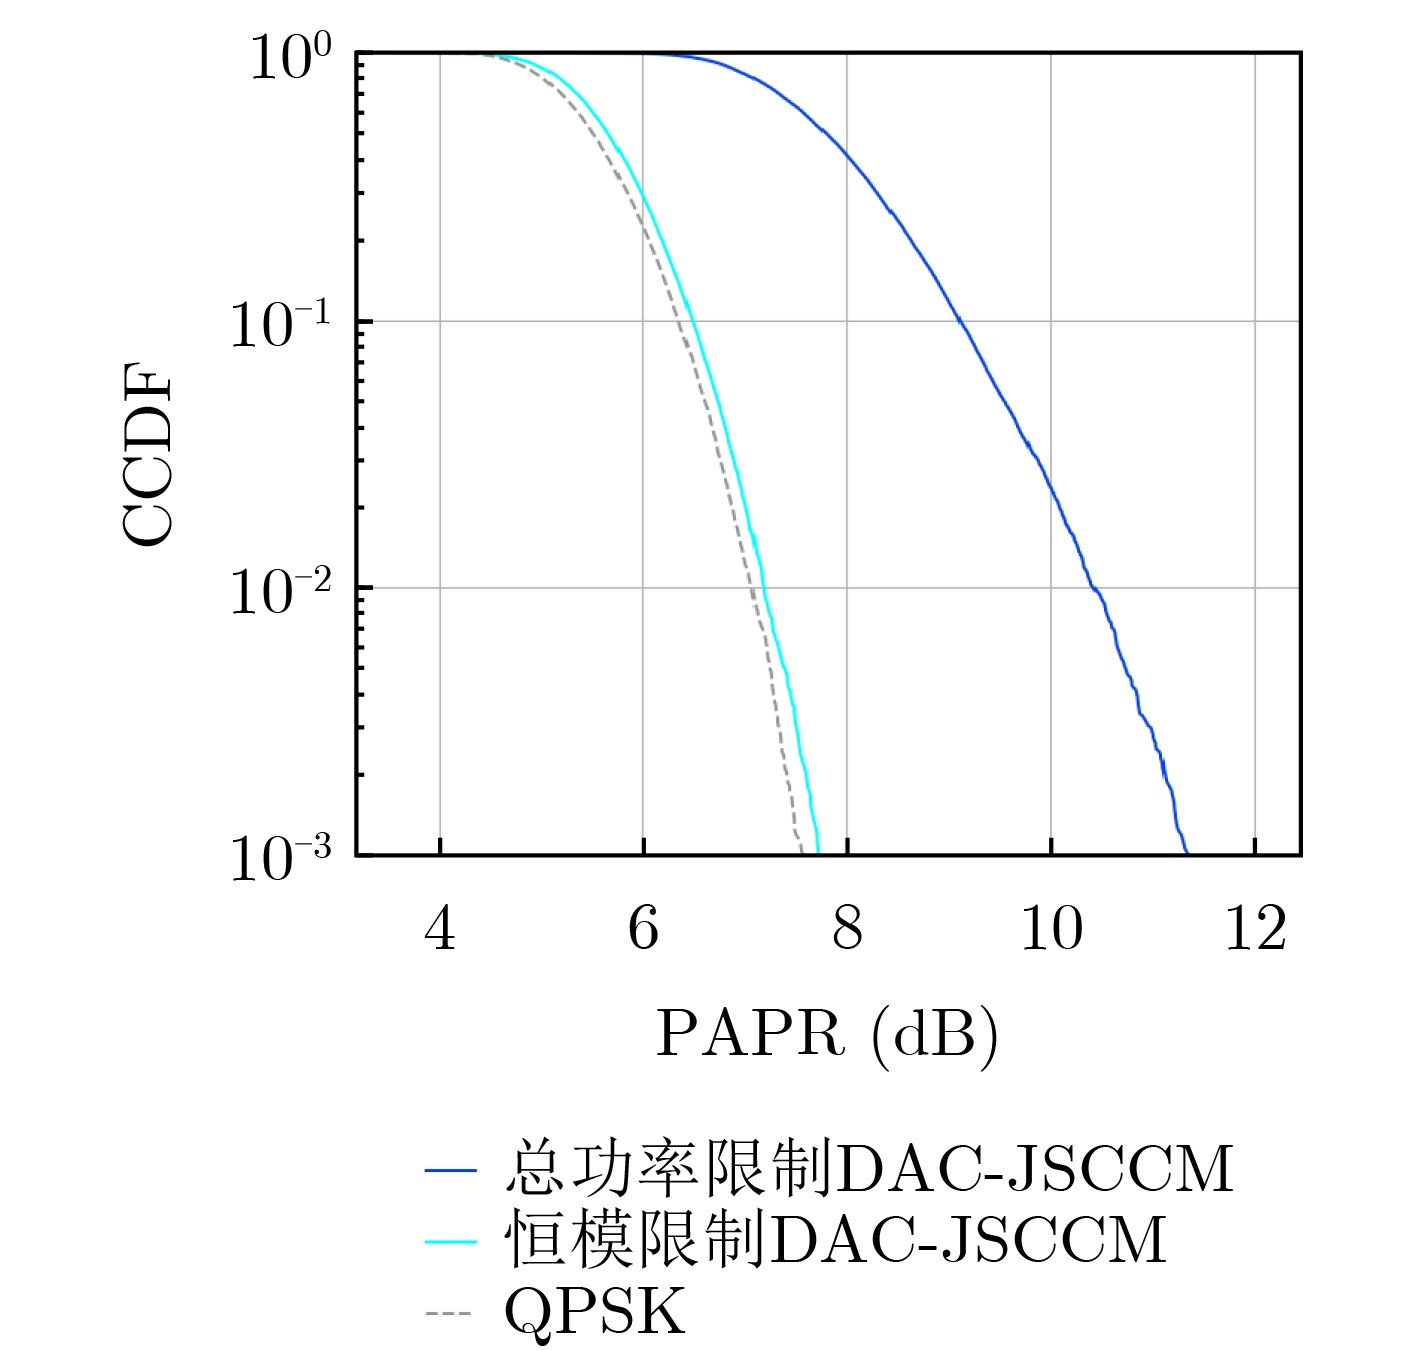
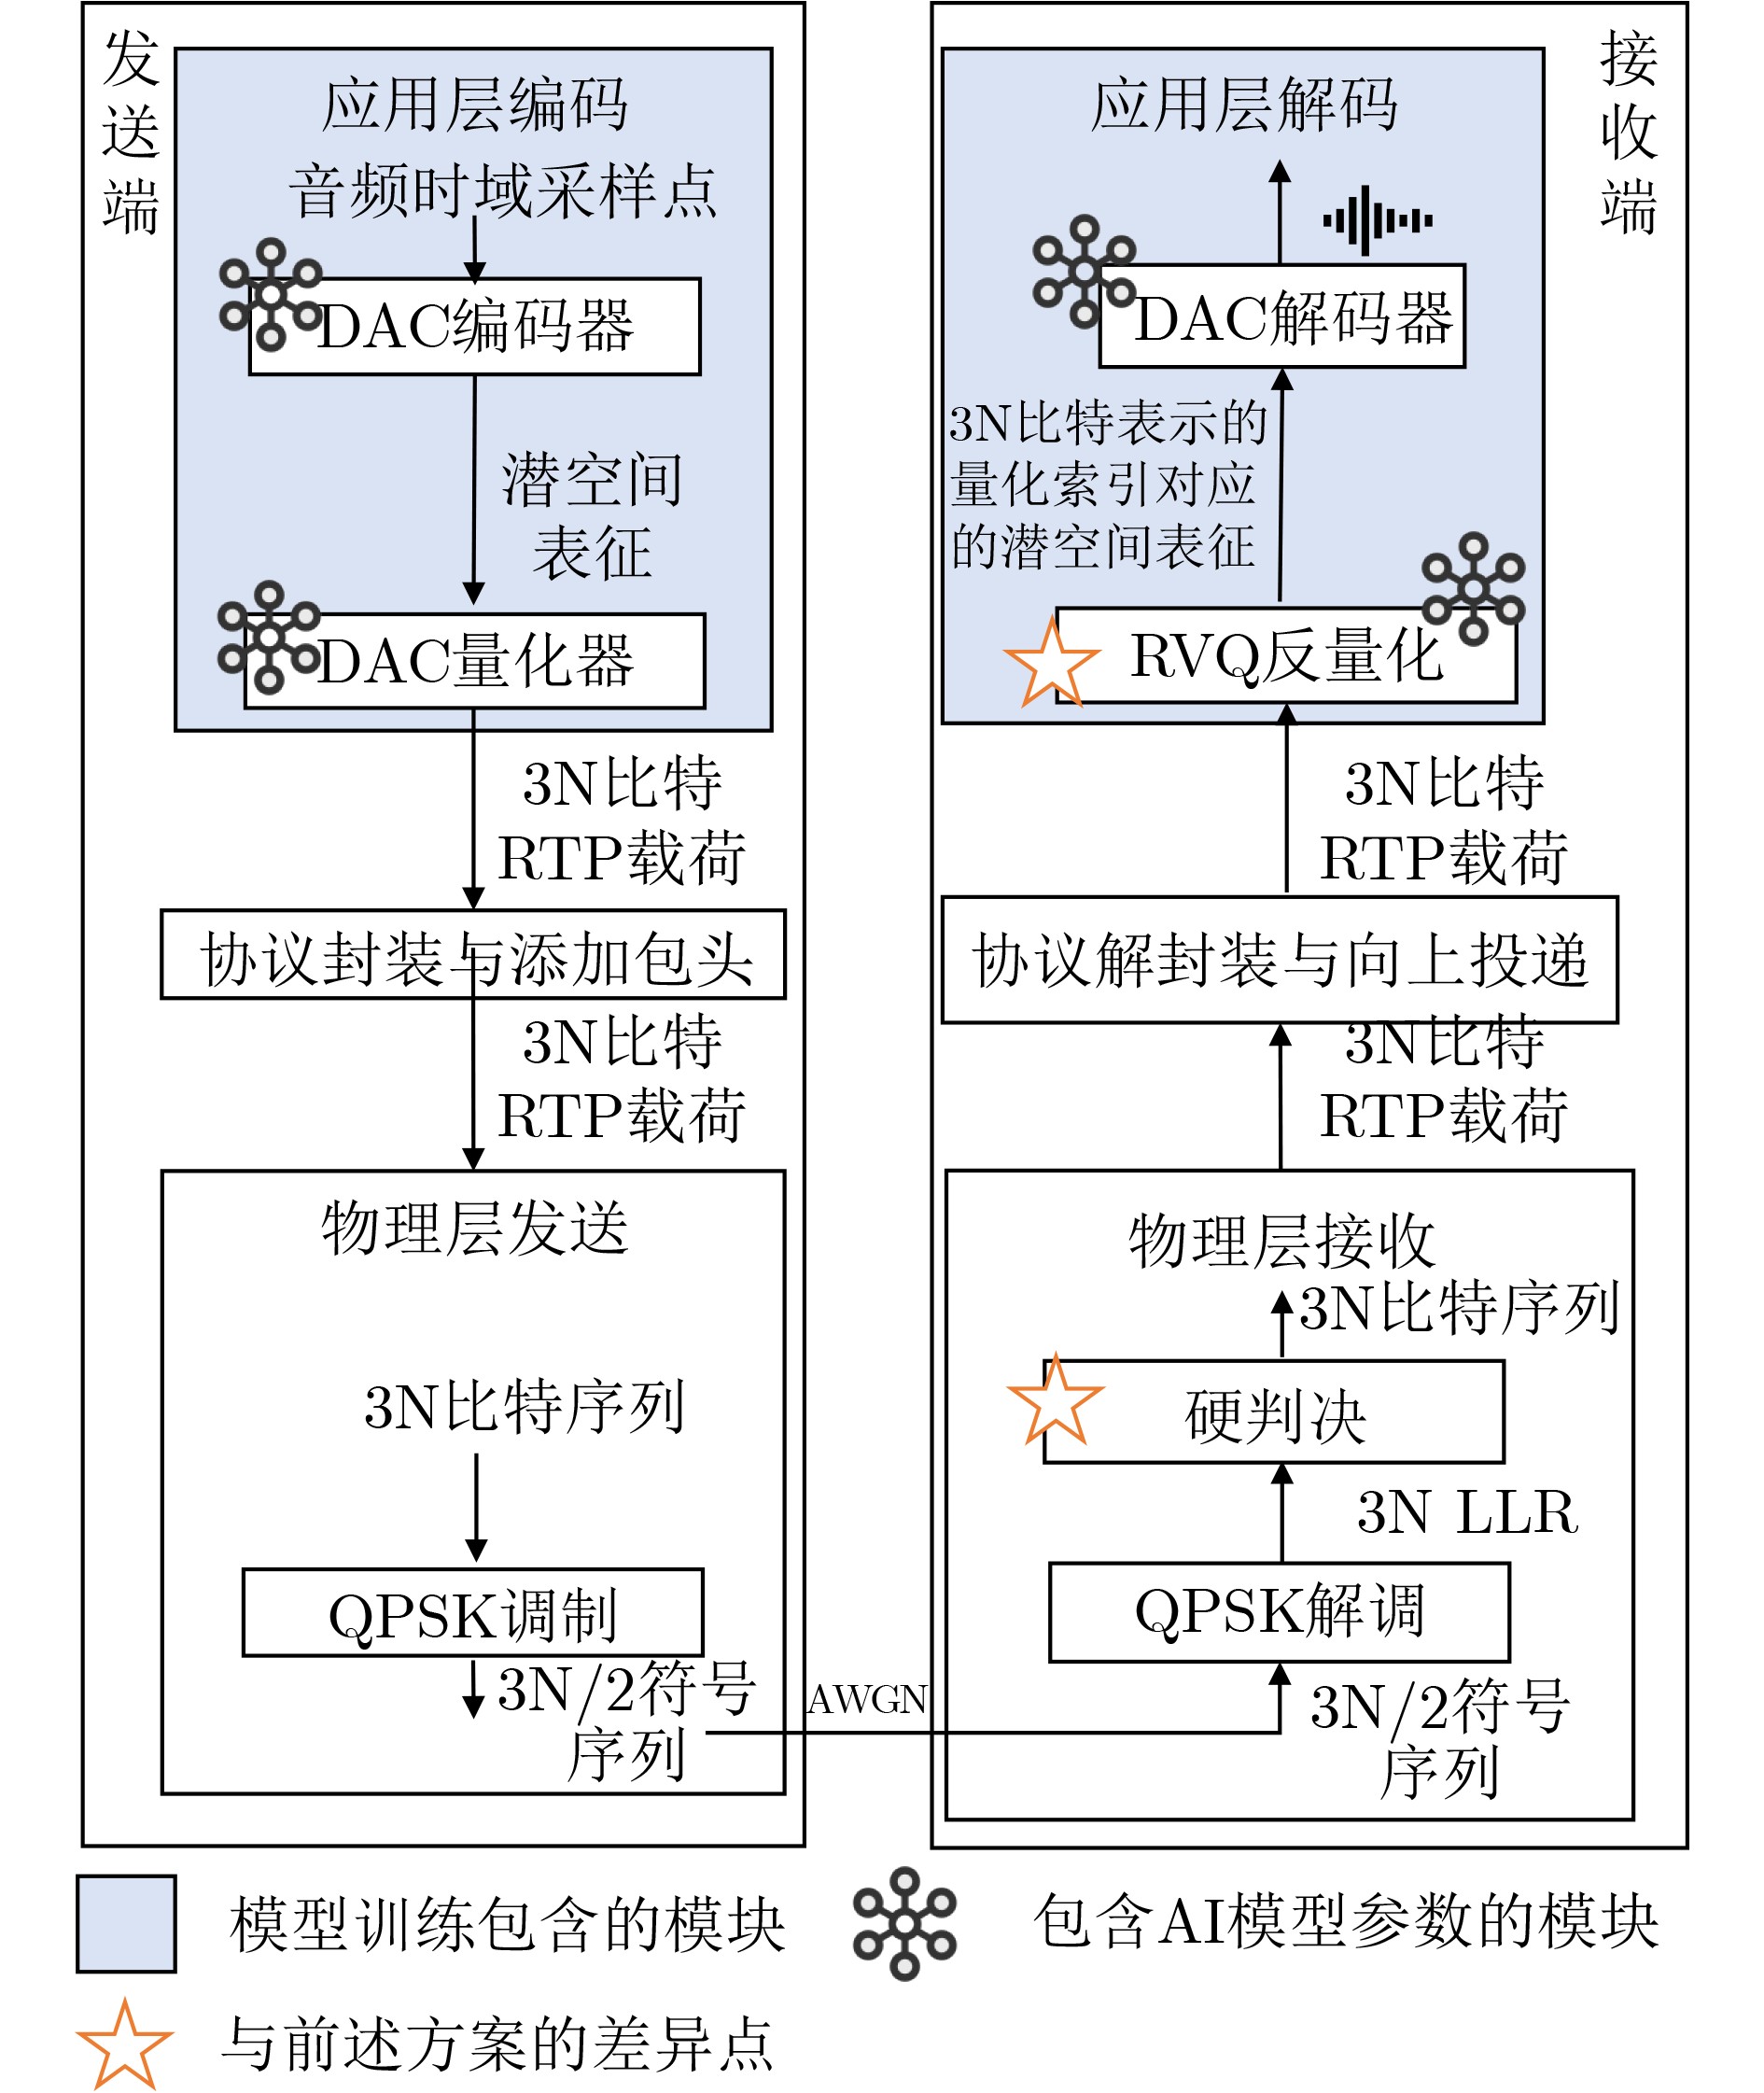
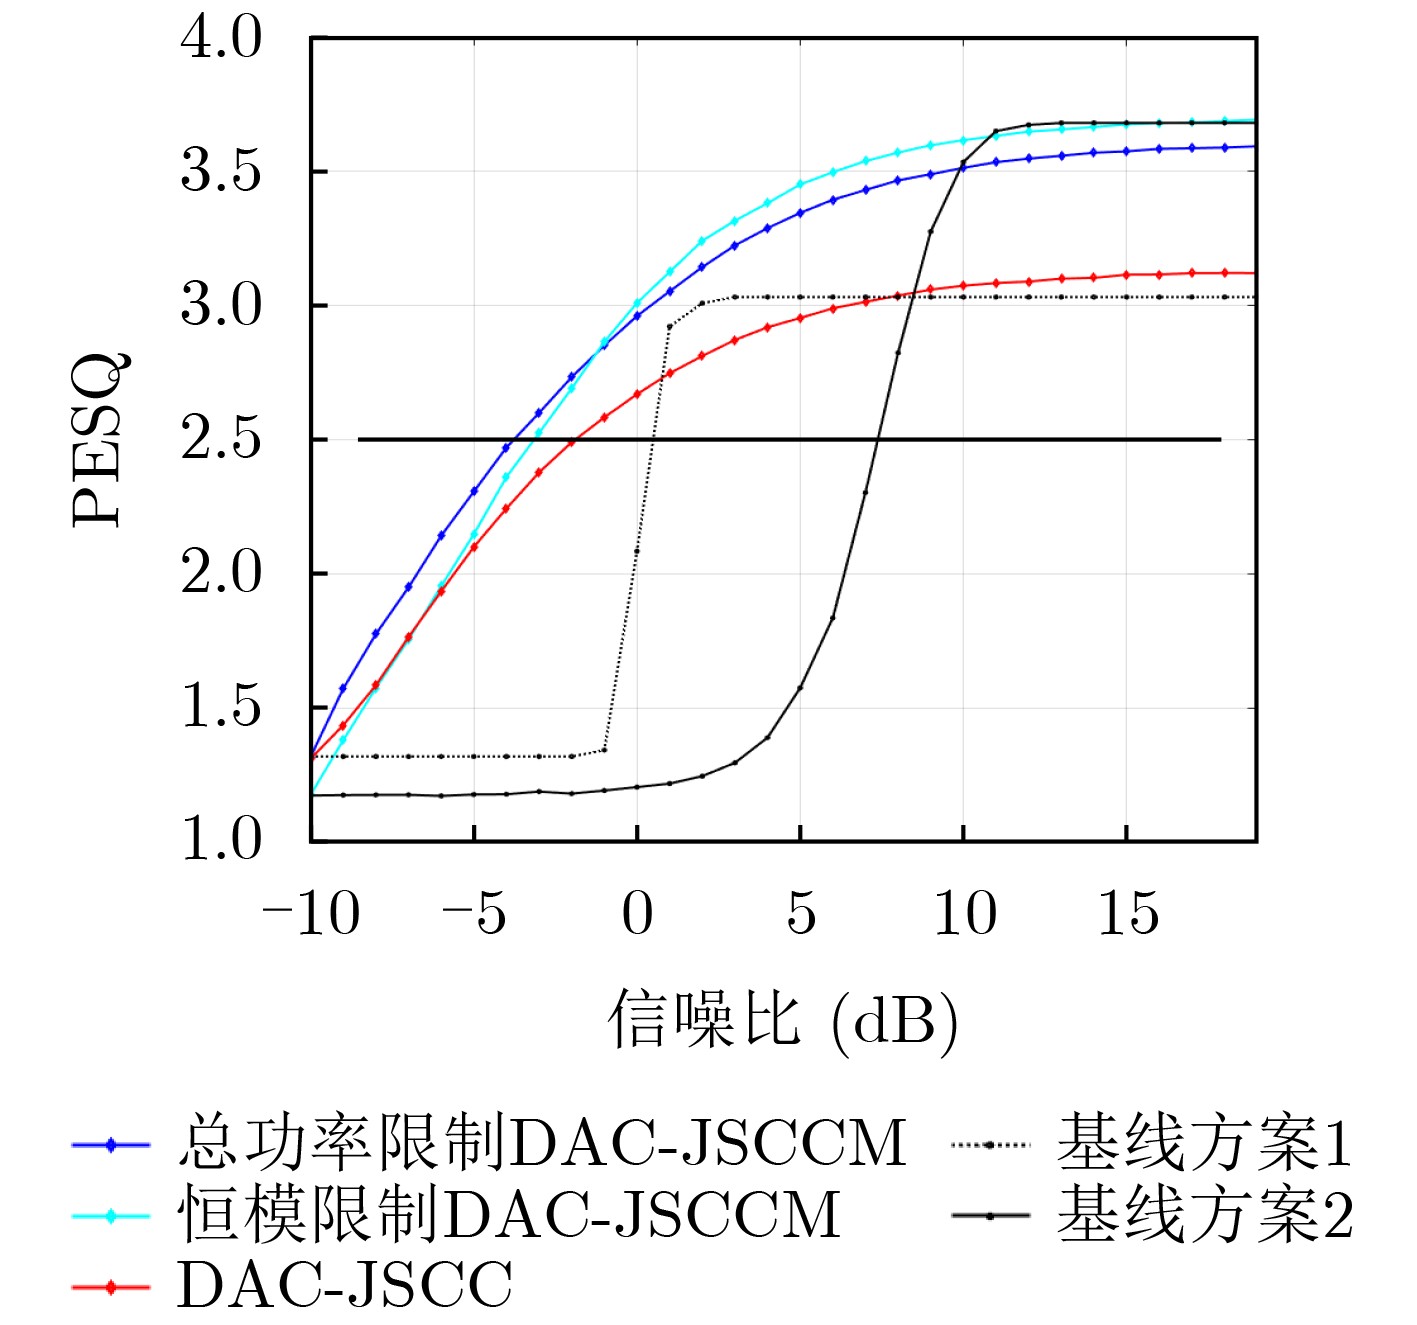
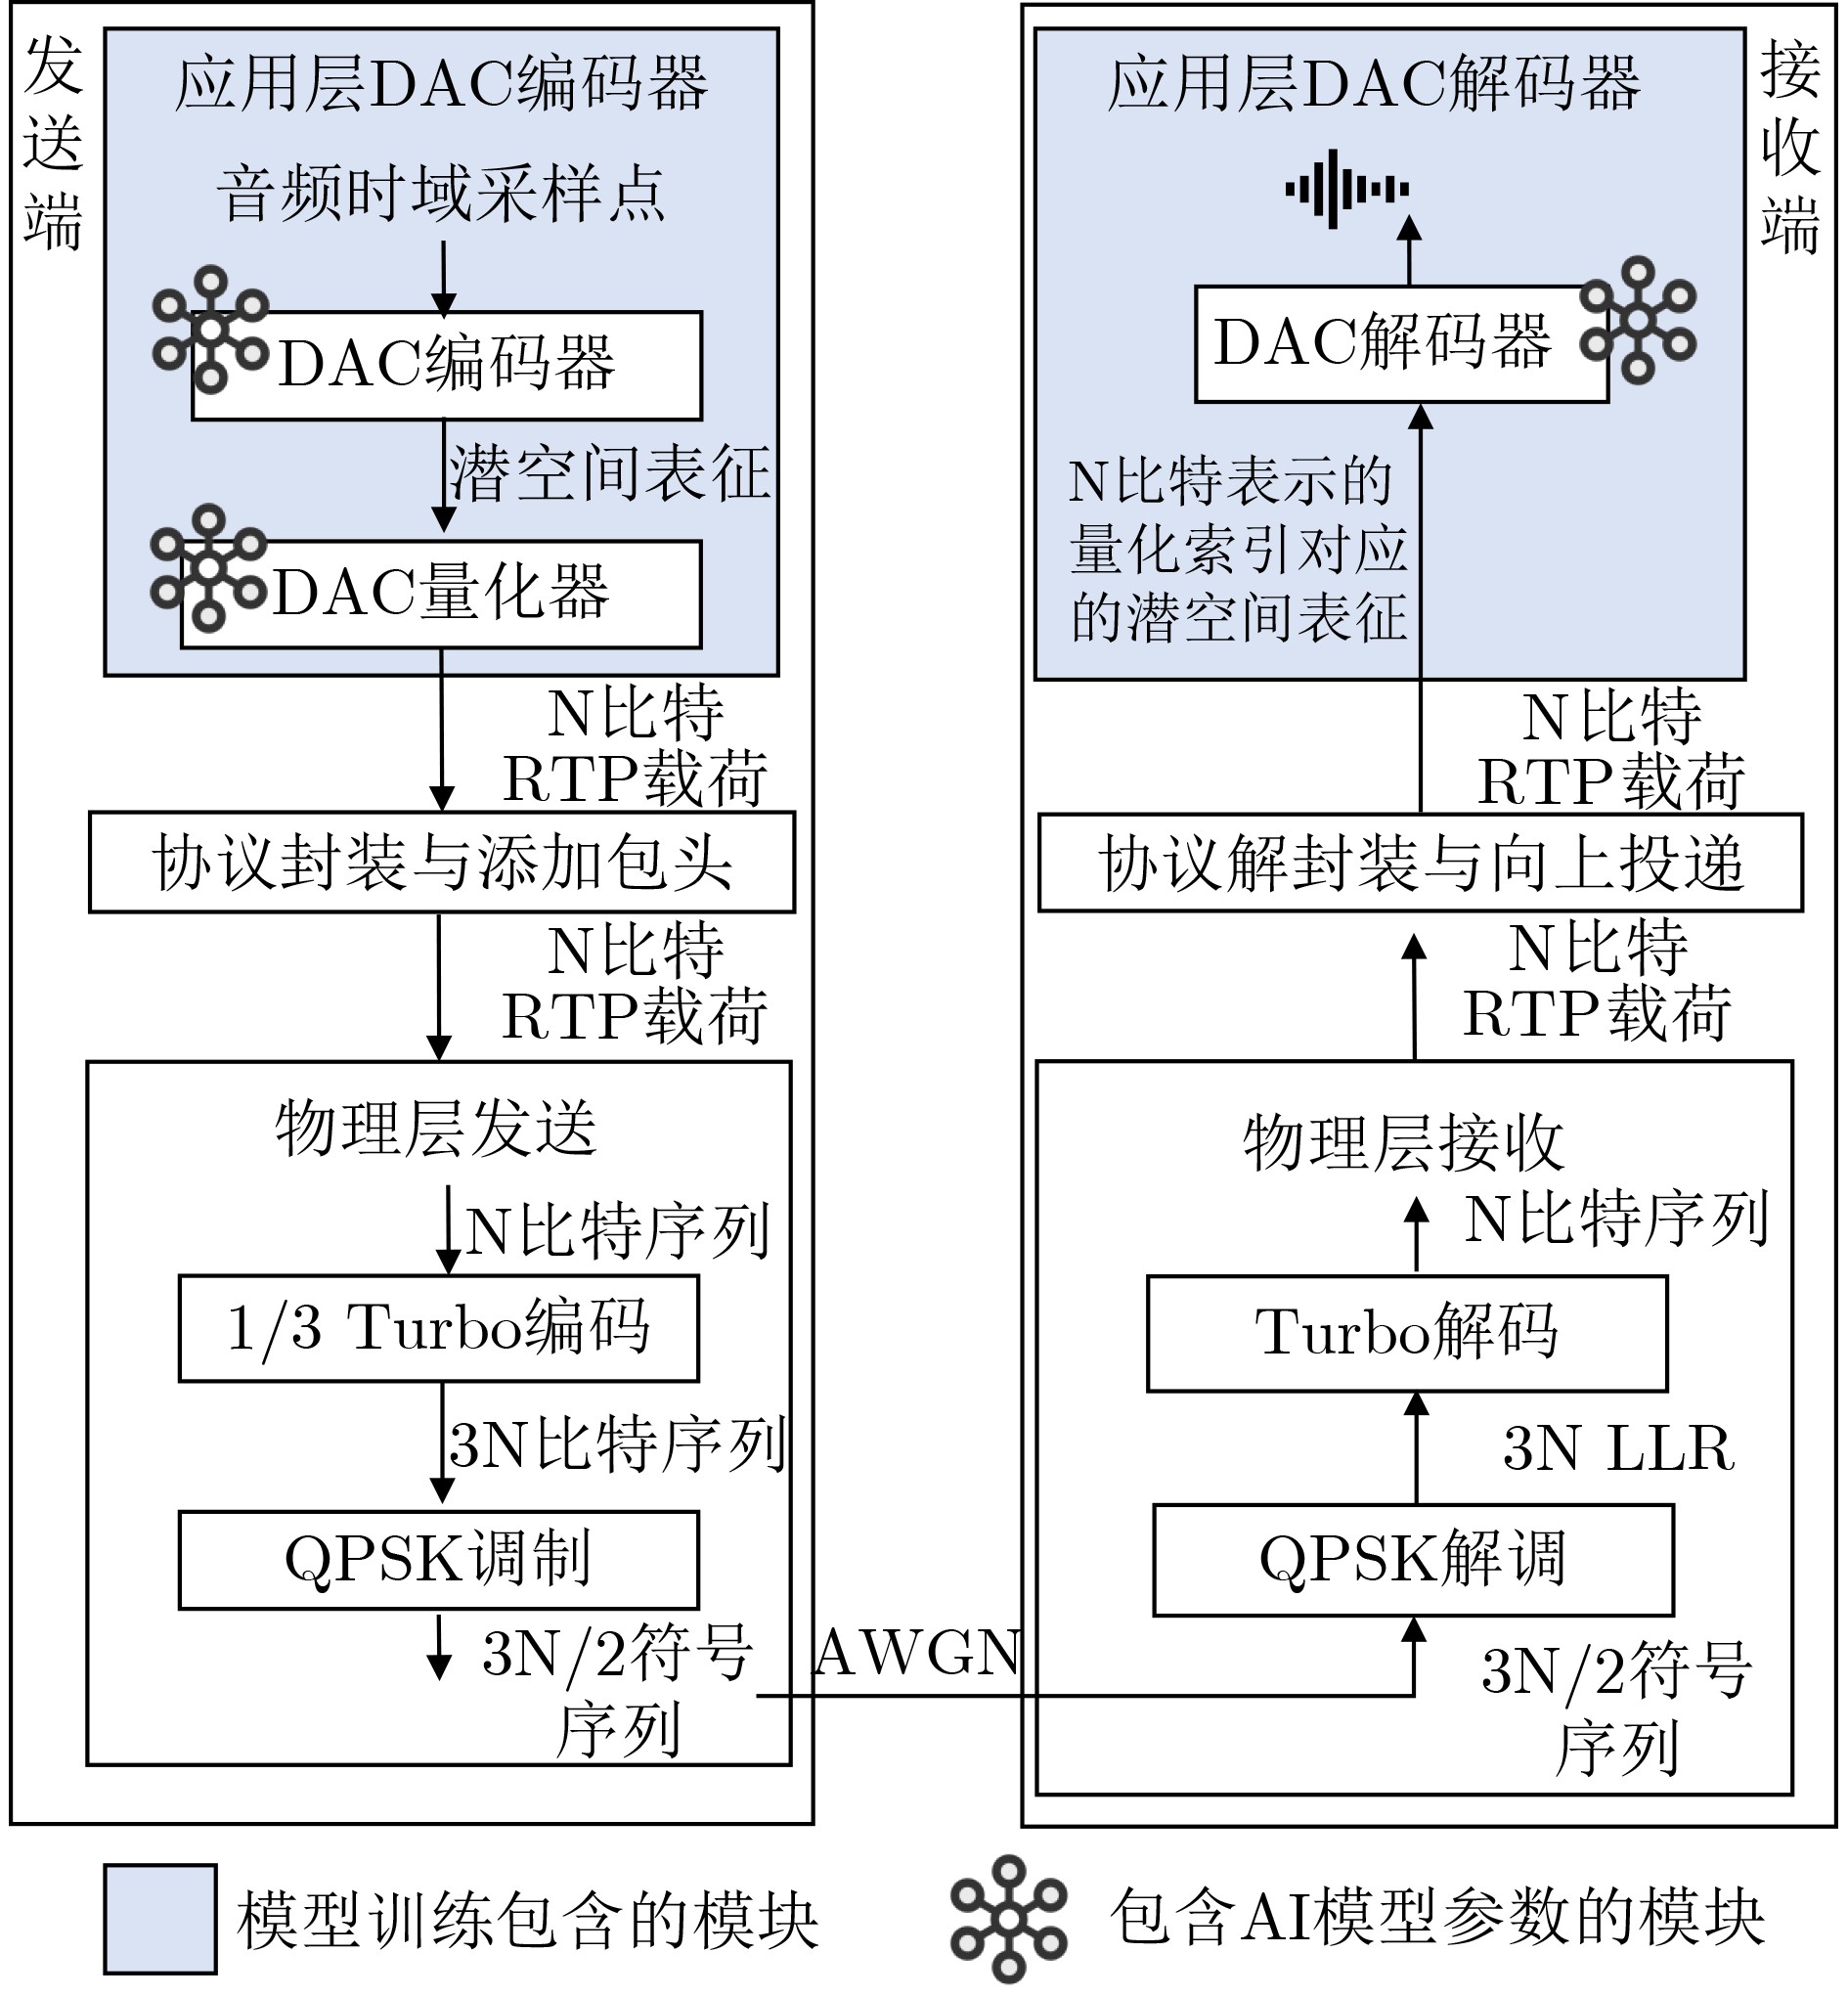
Abstract:The 3rd Generation Partnership Project (3GPP) Technical Specification Group Service and System Aspects Working Group 4 (TSG SA Working Group 4, SA4) is currently investigating Artificial Intelligence (AI)-based speech codecs. Based on the Descript Audio Codec (DAC) under investigation by SA4, this paper proposes three AI-enabled transmission schemes: a Total Power Constrained (TPC) DAC Joint Source-Channel Coding and Modulation (DAC-JSCCM) scheme, a Constant-Envelope Constrained (CEC) DAC-JSCCM scheme, and a DAC Joint Source-Channel Coding (DAC-JSCC) scheme. The proposed schemes are evaluated using the typical physical-layer parameter configuration for 3GPP Geostationary Earth Orbit (GEO) voice communications. The results provide useful guidance for future research on GEO voice communications. Objective Joint Source-Channel Coding (JSCC) has attracted increasing attention in both academia and industry. Academic research has primarily focused on video, image, and audio transmission, whereas industrial research has mainly considered Channel State Information (CSI) as the source. The limited industrial interest in JSCC for video and image transmission is mainly attributed to two factors. First, video and image coding standards are generally developed by external organizations, such as the Moving Picture Experts Group (MPEG) and the Joint Photographic Experts Group (JPEG), rather than by 3GPP. Second, application-layer JSCC is limited by architectural challenges because the channel information available at the application layer is often outdated, reducing its potential gain. Audio differs from video and images because speech coding is developed within 3GPP, and SA4 is currently investigating AI-based speech codecs. In GEO voice communications, satellites remain nearly stationary relative to ground stations, resulting in slowly varying channels. Therefore, physical-layer CSI can be reliably delivered to the application layer, avoiding outdated channel information. These characteristics make JSCC for audio a promising research direction within 3GPP. Methods The typical physical-layer parameter configuration for 3GPP GEO voice communications and the DAC under investigation by SA4 are first adopted as the evaluation baseline to ensure a fair performance comparison. Three AI-enabled transmission schemes are then proposed for low-bitrate audio communications. First, the TPC DAC-JSCCM scheme jointly optimizes source coding, channel coding, and modulation to maximize transmission gain. Second, to reduce the high Peak-to-Average Power Ratio (PAPR) associated with the TPC scheme, the CEC DAC-JSCCM scheme is proposed. Finally, because transmitting modulation symbols within the Real-time Transport Protocol (RTP) payload requires substantial modifications to the existing protocol, the DAC-JSCC scheme is proposed to retain bit-sequence transmission in the RTP payload while remaining compatible with the current protocol architecture. Results and Discussions Baseline scheme 1 is first evaluated through physical-layer link-level simulations to establish the relationship between Signal-to-Noise Ratio (SNR) and Block Error Rate (BLER) for 64-bit packets encoded with a rate-1/3 Turbo code. Assuming that the error rate of an audio frame is equal to the corresponding BLER, the transmission error rate of an RTP packet containing L audio frames is calculated. According to the existing transmission mechanism, an RTP packet is discarded if any audio frame within the packet is received incorrectly. In real-time communication, Voice over Internet Protocol (VoIP), and speech enhancement applications, a Perceptual Evaluation of Speech Quality (PESQ) score of 2.5 is generally regarded as the minimum acceptable speech quality threshold. Therefore, PESQ = 2.5 is selected as the reference point for GEO voice communications. At this threshold, both the TPC DAC-JSCCM and CEC DAC-JSCCM schemes achieve an approximately 4 dB coverage gain over baseline scheme 1 ( Fig. 4 ), whereas the DAC-JSCC scheme achieves a 2.5 dB coverage gain. These gains result from application-layer JSCC, which eliminates the cliff effect associated with Turbo coding at the physical layer. At a Complementary Cumulative Distribution Function (CCDF) of 10−3, the Peak-to-Average Power Ratio (PAPR) of the TPC DAC-JSCCM scheme is approximately 4 dB higher than that of Quadrature Phase Shift Keying (QPSK), resulting in sharper signal peaks, stricter linearity requirements for the power amplifier, and greater susceptibility to nonlinear distortion. By contrast, the CEC DAC-JSCCM scheme exhibits a PAPR comparable to that of QPSK.Conclusions Based on the DAC under investigation by SA4, three AI-enabled transmission schemes are proposed. Simulations are performed using the typical physical-layer parameter configuration for 3GPP GEO voice communications. At the minimum acceptable speech quality threshold (PESQ = 2.5), the proposed TPC DAC-JSCCM and CEC DAC-JSCCM schemes each provide an approximately 4 dB coverage gain over the conventional DAC-based transmission scheme, whereas the DAC-JSCC scheme provides a 2.5 dB coverage gain. As SA4 continues to investigate more advanced GEO speech codecs, future work will extend the proposed framework to these next-generation codecs. -
表 1 仿真参数设置
参数 基线
方案1基线
方案2总功率限制
DAC-
JSCCM恒模
限制
DAC-
JSCCMDAC-
JSCC应用层输出
(N=64)N bit 3N
bit3N /2
复数3N /2
复数3N bit 物理层调制方式 QPSK QPSK 无 无 QPSK 物理层信道编码 1/3
Turbo1/3
无无 无 无 训练信噪比
(dB)无 无 [–5,10) [–5,10) [–5,10) DAC下采样输出维度 1024 1024 192 96 192 RVQ码本数 8 24 无 无 无 码本大小 256 256 无 无 无  下载: 导出CSV
表 2 信噪比与误块率表(64 bit长度,1/3 Turbo编码)
信噪比(dB) 误块率 –6 1 –5 1 –4 1 –3 0.925 –2 0.665 –1 0.236 0 0.0464 1 0.0039 2 0.0004 3 0 4 0 5 0 6 0 7 0
下载: 导出CSV
-
[1] 周通, 姜大洁, 谭俊杰, 等. 语义通信的用例、挑战与标准化影响浅析[J]. 移动通信, 2025, 49(7): 2–11. doi: 10.3969/j.issn.1006-1010.20250522-0001.ZHOU Tong, JIANG Dajie, TAN Junjie, et al. A survey of semantic communication: Use cases, open challenges, and standardization trends[J]. Mobile Communications, 2025, 49(7): 2–11. doi: 10.3969/j.issn.1006-1010.20250522-0001. [2] OPPO. 基于信源信道联合编码的CSI反馈[R]. IMT-2030-Semantic_2024004, 2024. [3] OPPO. 信道与无线环境语义通信_基于联合信源信道编码的CSI反馈[R]. IMT-2030-Semantic_2024036, 2024. [4] 小米. 面向CSI反馈的信道估计与联合信源信道编码的联合设计[R]. IMT-2030-Semantic_2024056, 2024. [5] YANG Ke, WANG Sixian, DAI Jincheng, et al. SwinJSCC: Taming swin transformer for deep joint source-channel coding[J]. IEEE Transactions on Cognitive Communications and Networking, 2025, 11(1): 90–104. doi: 10.1109/TCCN.2024.3424842. [6] GUO Jiangyuan, CHEN Wei, SUN Yuxuan, et al. VideoQA-SC: Adaptive semantic communication for video question answering[J]. IEEE Journal on Selected Areas in Communications, 2025, 43(7): 2462–2477. doi: 10.1109/JSAC.2025.3559160. [7] TUNG T Y and GÜNDÜZ D. DeepWiVe: Deep-learning-aided wireless video transmission[J]. IEEE Journal on Selected Areas in Communications, 2022, 40(9): 2570–2583. doi: 10.1109/JSAC.2022.3191354. [8] BOURTSOULATZE E, KURKA D B, and GÜNDÜZ D. Deep joint source-channel coding for wireless image transmission[J]. IEEE Transactions on Cognitive Communications and Networking, 2019, 5(3): 567–579. doi: 10.1109/TCCN.2019.2919300. [9] YILMAZ S F, NIU Xueyan, BAI Bo, et al. High perceptual quality wireless image delivery with denoising diffusion models[C]. IEEE Conference on Computer Communications Workshops, Vancouver, Canada, 2024: 1–5. doi: 10.1109/INFOCOMWKSHPS61880.2024.10620904. [10] DAI Jincheng, WANG Sixian, TAN Kailin, et al. Nonlinear transform source-channel coding for semantic communications[J]. IEEE Journal on Selected Areas in Communications, 2022, 40(8): 2300–2316. doi: 10.1109/JSAC.2022.3180802. [11] WENG Zhenzi, QIN Zhijin, and LI G Y. Robust semantic communications for speech transmission[C]. 2025 IEEE International Conference on Acoustics, Speech and Signal Processing, Hyderabad, India, 2025: 1–5. doi: 10.1109/ICASSP49660.2025.10889160. [12] HAN Tianxiao, YANG Qianqian, SHI Zhiguo, et al. Semantic-preserved communication system for highly efficient speech transmission[J]. IEEE Journal on Selected Areas in Communications, 2023, 41(1): 245–259. doi: 10.1109/JSAC.2022.3221952. [13] WENG Zhenzi, QIN Zhijin, TAO Xiaoming, et al. Deep learning enabled semantic communications with speech recognition and synthesis[J]. IEEE Transactions on Wireless Communications, 2023, 22(9): 6227–6240. doi: 10.1109/TWC.2023.3240969. [14] CHEN Xiaojiao, WANG Jing, XU Liang, et al. A perceptually motivated approach for low-complexity speech semantic communication[J]. IEEE Internet of Things Journal, 2024, 11(12): 22054–22065. doi: 10.1109/JIOT.2024.3378779. [15] 3GPP. 3GPP TS 23.501 System architecture for the 5G System (5GS)[S]. 2025. [16] 3GPP. 3GPP TS 38.323 Packet data convergence protocol (PDCP) specification[S]. 2025. [17] IMT-2030(6G)推进组. 面向6G的语义通信技术研究报告[M]. 北京: IMT-2030(6G)推进组, 2025. [18] Descript. Descript-audio-codec[EB/OL]. https://github.com/descriptinc/descript-audio-codec, 2026. [19] 3GPP. 3GPP TR 26.940 Study on ultra low bit rate speech codecs[S]. 2026. [20] 3GPP. 3GPP TS 36. 212 Multiplexing and channel coding[S]. 2025. [21] ETSI. ETSI TS 136 213 V19.1. 0 (2025-10) Physical layer procedures[S]. 2025. [22] OpenDataLab. VCTK[EB/OL]. https://opendatalab.com/OpenDataLab/VCTK, 2026. [23] Common voice[EB/OL]. https://commonvoice.mozilla.org/zh-CN, 2026. [24] Librispeech[EB/OL]. https://huggingface.co/datasets/openslr/librispeech_asr, 2026. [25] ITU. ITU-T P. 863-2018 Perceptual objective listening quality prediction[S]. 2018. -

 下载:

图(5) / 表(2)
计量
- 文章访问数: 514
- HTML全文浏览量: 319
- PDF下载量: 23
- 被引次数: 0
